arXiv update · P2 · 2026-05-29
Beyond Interpretability:它和通用视觉自监督的关系在于:在 CLIP image encoder 激活上训练 SAE 并做 label-free steering,连接可解释性与可操作视觉表征
中相关;详见方法、贡献和实验边界。
Beyond Interpretability: When, Why, and How Sparse Autoencoders Enable Label-Free Visual Steering arXiv update 原文链接
编号2506.01247
优先级P2
类别arXiv update
会议arXiv update
方法在 CLIP image encoder 激活上训练 SAE 并做 label-free steering,连接可解释性与可操作视觉表征
来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:在 CLIP image encoder 激活上训练 SAE 并做 label-free steering,连接可解释性与可操作视觉表征。 中相关;详见方法、贡献和实验边界。
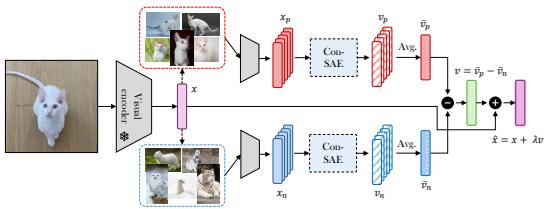 (b) ${ \mathrm { V } } { \mathrm { S } } 2 ^ { + + }$ : Selective Visual Sparse Steering F(b) ${ \mathrm { V } } { \mathrm { S } } 2 ^ { + + }$ : Selective Visual Sparse Steering Figure 1: Overview of VS2 and ${ \mathrm { V } } { \mathrm { S } } 2 ^ { + + }$ : VS2 constructs a steering vector by uniformly amplifying active sparse features, while ${ \mathrm { V } } { \mathrm { S } } 2 ^ { + + }$ selectively amplifies sparse features given external corpus.这张图概括 Beyond Interpretability 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
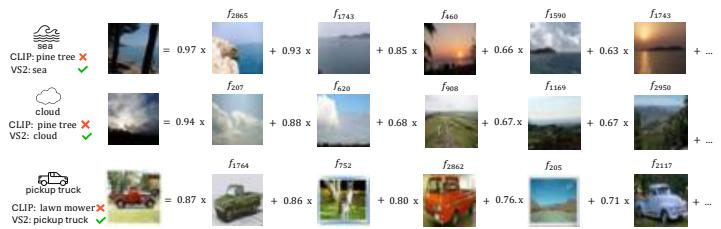 (b) VS2-corrected examples using weighted interpretable features(b) VS2-corrected examples using weighted interpretable features. Figure 2: Qualitative evidence for SAE-based steering. (a) Some SAE features group coherent visual concepts. (b) In CIFAR-100 errors corrected by VS2, top active latents often align with the recovered class, illustrating coarse semantic alignment rather than perfect monosemanticity.这张图/表用于判断 Beyond Interpretability 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:在 CLIP image encoder 激活上训练 SAE 并做 label-free steering,连接可解释性与可操作视觉表征。
方法拆解
在 CLIP image encoder 激活上训练 SAE 并做 label-free steering,连接可解释性与可操作视觉表征
主要贡献
中相关;详见方法、贡献和实验边界。
实验看点
实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。
局限与读法
这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。