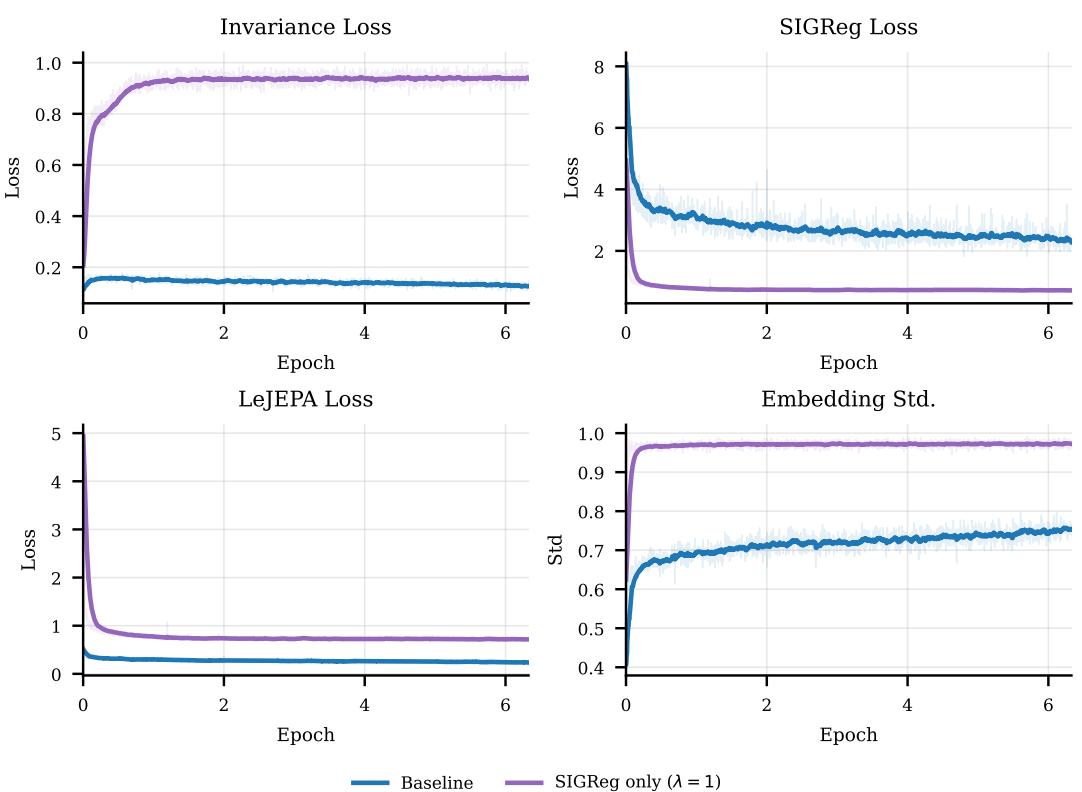
AV-JEPA: Extending LeJEPA to Audio-Visual Self-Supervised Learning
高相关;详见方法、贡献和实验边界。
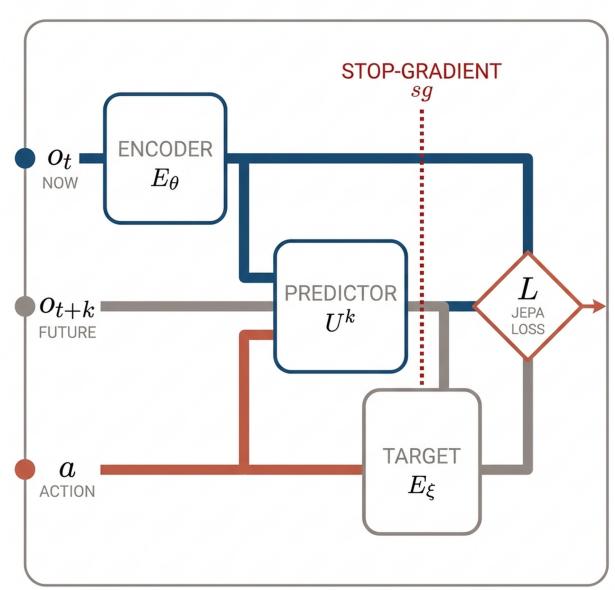
方法:用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本的简洁自监督结构
收录近期通用视觉自监督、视觉基础模型与多模态表征学习论文,按日期、优先级与主题归档。
高相关;详见方法、贡献和实验边界。
方法:用 early-fusion ViT、modality dropout masking 和 SIGReg,把 JEPA 扩展到音视频 latent 对齐,同时保持无 decoder/无负样本的简洁自监督结构
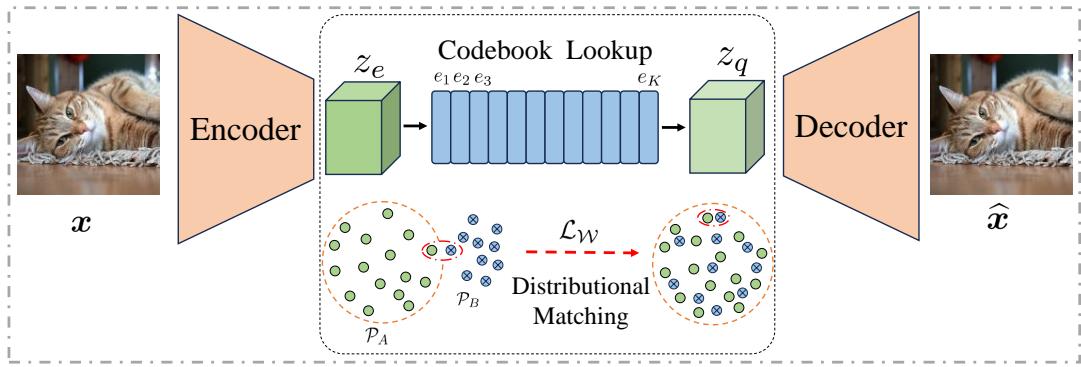
高相关;详见方法、贡献和实验边界。
方法:把 VQ 训练不稳定与 codebook collapse 归因于 feature/code distribution mismatch,对视觉 tokenizer、AR 图像模型和离散表征学习都有底层价值
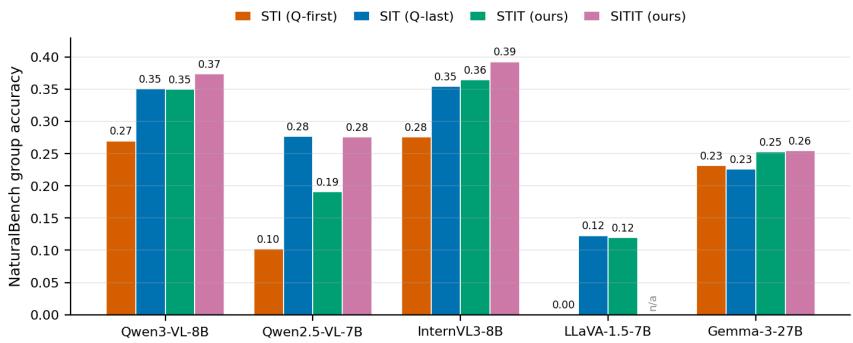
中高相关;详见方法、贡献和实验边界。
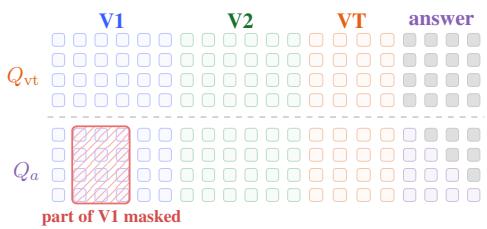
方法:解释 question-first prompt 为什么会损伤 VLM:问题能引导图像 patch 表征,却在 answer token 处被读不到;echoing 是训练无关修复
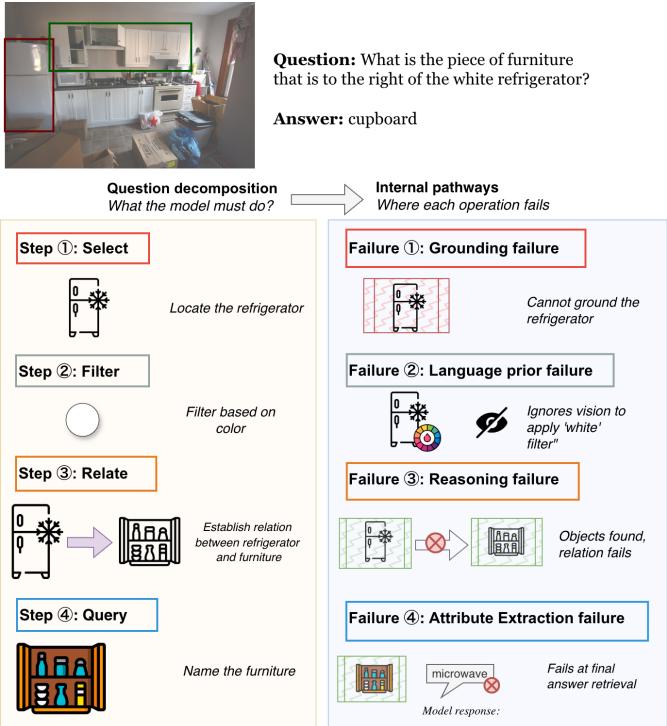
中高相关;详见方法、贡献和实验边界。
方法:把 compositional VQA 失败拆成 grounding、reasoning、attribute extraction、language prior 四类,并定位到不同 transformer pathway
中高相关;详见方法、贡献和实验边界。
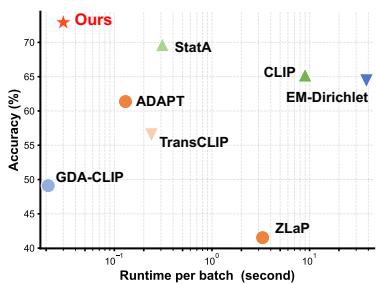
方法:把 CLIP/VLM 单位球特征建模为 vMF mixture,用动态 shrinkage 处理长尾/不均衡测试集,属于训练无关表征校准
中高相关;详见方法、贡献和实验边界。
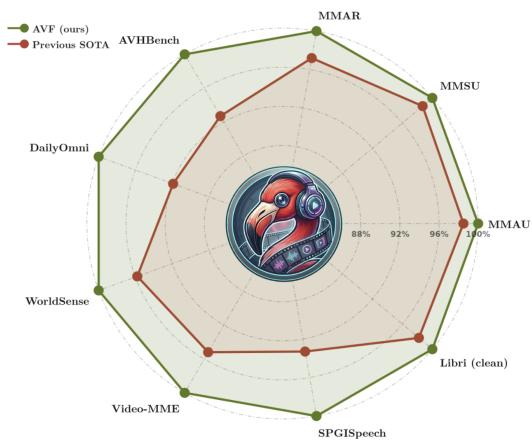
方法:开放长音视频数据、三阶段课程和时间戳 grounding CoT,适合看视频/音频/图像联合表征的工程化路线
中高相关;详见方法、贡献和实验边界。
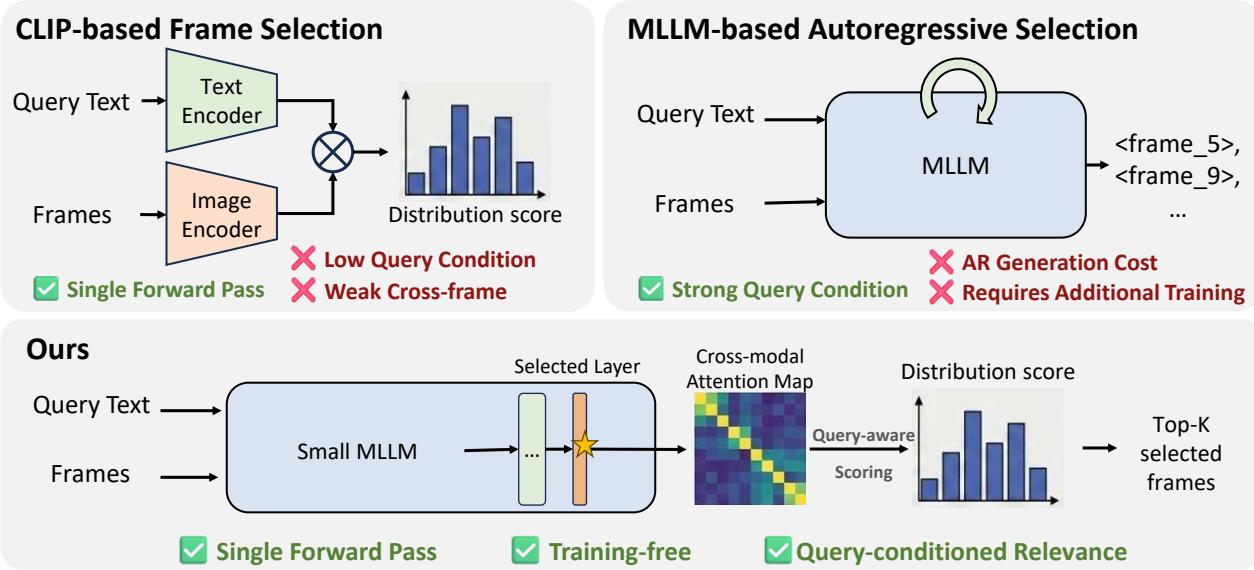
方法:直接利用 MLLM 中间层 cross-modal attention 做 query-relevant frame evidence,不经生成即可压缩长视频 token
中高相关;详见方法、贡献和实验边界。
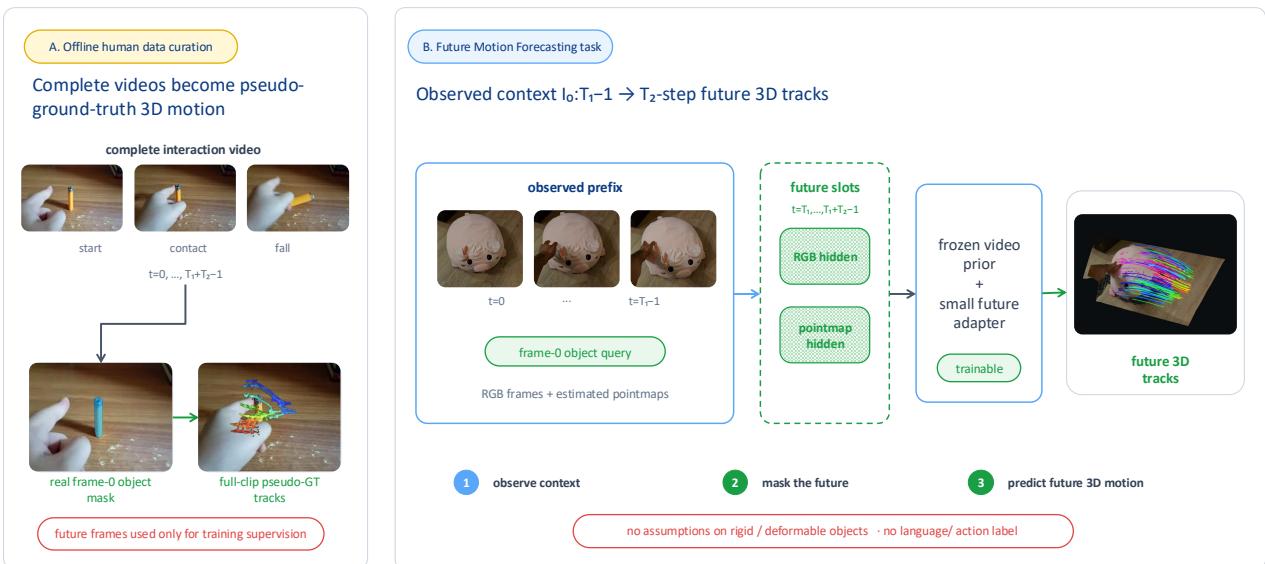
方法:冻结大型视频/跟踪组件,只训练轻量 adapter,把视频预测模型中的物理运动先验迁移到未来 3D scene flow
中相关;详见方法、贡献和实验边界。
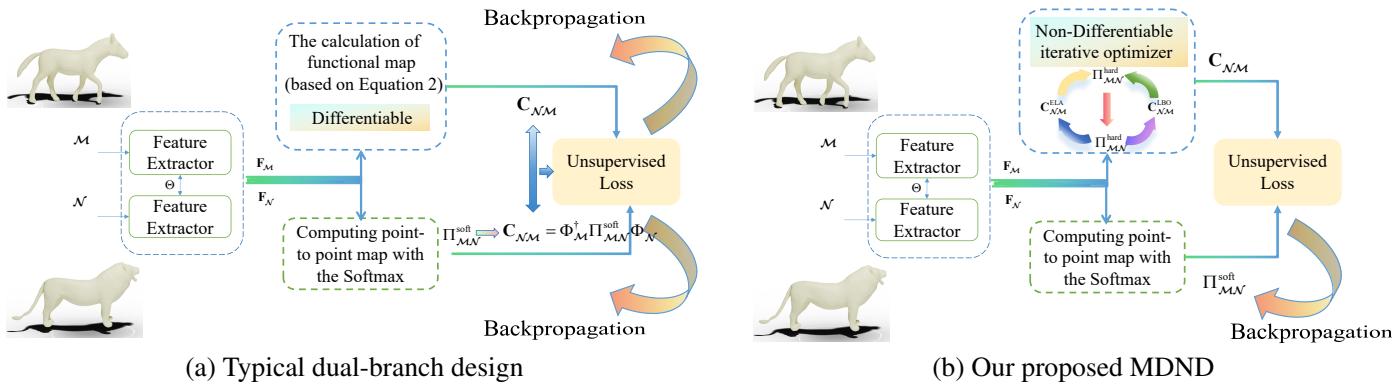
方法:用非可微 refinement branch 生成高质量内部目标,再监督可微 branch,无监督学习形状 correspondence
中相关;详见方法、贡献和实验边界。
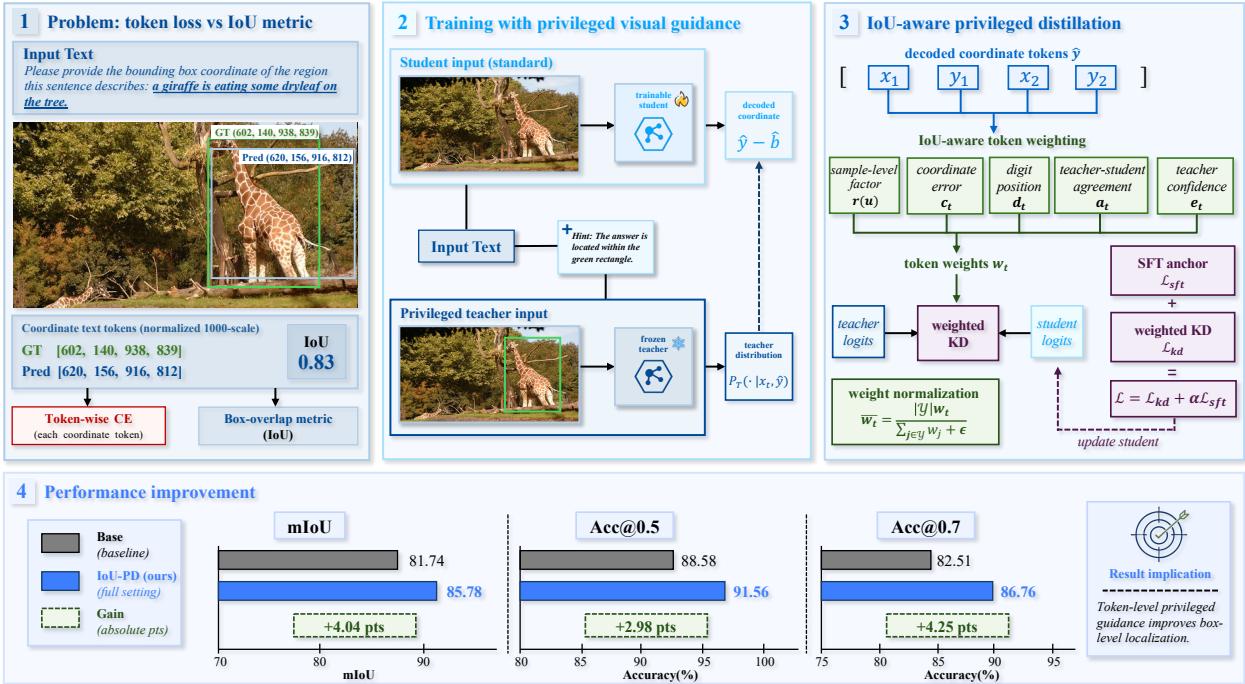
方法:用带 box 标注的教师分支提供训练时 privileged guidance,把 token-level 坐标生成和 IoU 几何质量对齐
中相关;详见方法、贡献和实验边界。
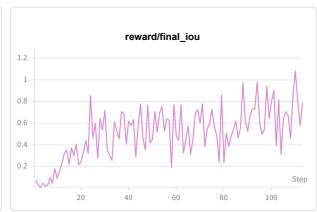
方法:用 object-part hierarchy、self-check crop re-encoding 和 part-aware GRPO 改善 MLLM 细粒度 grounding,偏任务但可迁移到局部视觉表征
中相关;详见方法、贡献和实验边界。
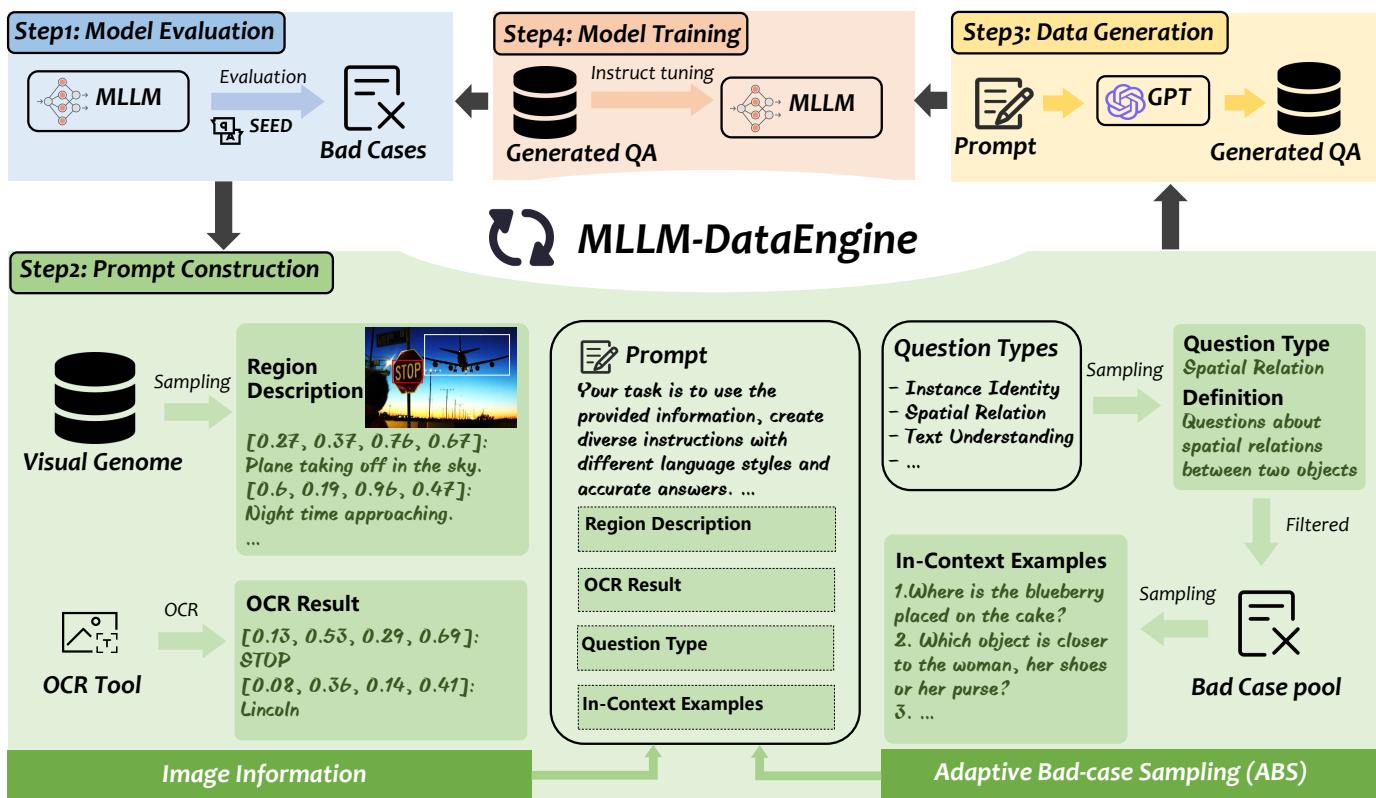
方法:让评测 bad cases 反向驱动增量多模态指令数据生成,是 VLM 训练数据闭环的一种工程模板
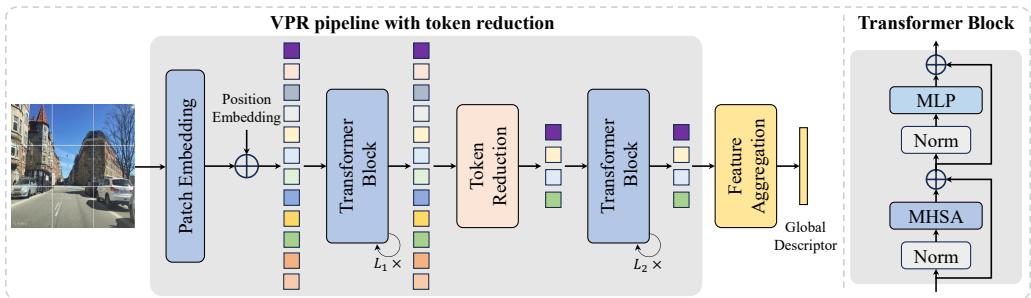
中相关;详见方法、贡献和实验边界。
方法:任务是 VPR,但系统评测 token pruning/merging 对 ViT/VFM 检索性能和吞吐的影响,可作视觉 token 效率背景
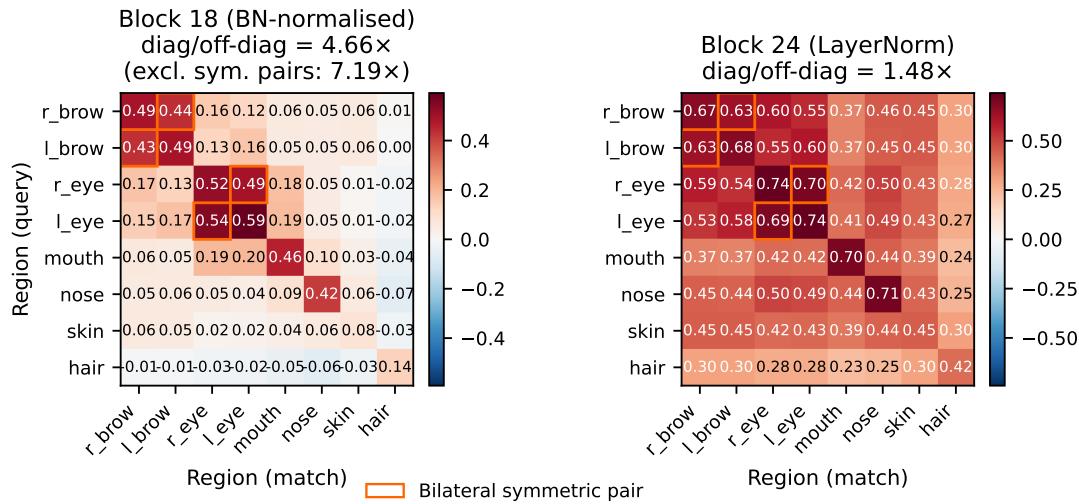
高相关;详见方法、贡献和实验边界。
方法:官方页未推进,今天不重复计新增;仍是冻结 DINOv3 dense correspondence 的本周主线
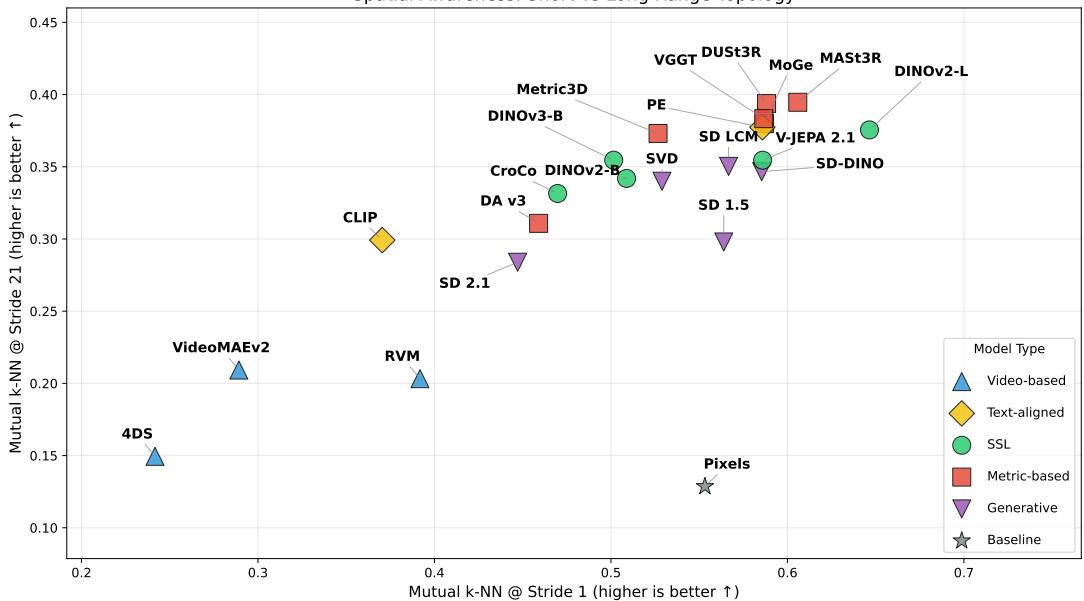
高相关;详见方法、贡献和实验边界。
方法:官方页未推进,今天只保留精读提醒;它仍是 VFM latent space 几何诊断的核心读物
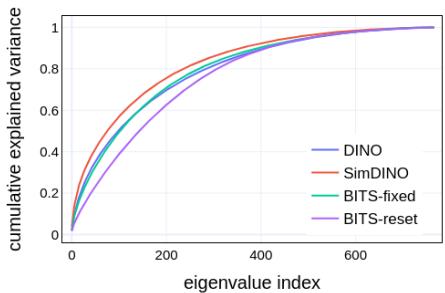
高相关;详见方法、贡献和实验边界。
方法:OpenReview/搜索核查仍只指向旧 ICML 2026 Poster 记录;可作为视觉 SSL 目标函数背景补读
高相关;详见方法、贡献和实验边界。
方法:官方页未推进,今天不重复计新增;仍是本周最值得精读的冻结自监督 VFM dense correspondence 证据
高相关;详见方法、贡献和实验边界。
方法:官方页未推进,今天只保留读法提醒;它提供 VFM latent space 与 SE(3) 拓扑/几何的诊断范式
高相关;详见方法、贡献和实验边界。
方法:OpenReview 搜索结果今天再次命中,但去重库已在 2026-06-01 记录;适合作为视觉 SSL 离散通信目标的背景
高相关;详见方法、贡献和实验边界。
方法:用冻结 DINOv3 特征验证跨身份、跨时间的局部区域对应,核心问题是自监督 ViT 是否形成 dense semantic coordinate system
高相关;详见方法、贡献和实验边界。
方法:直接探测 VFM 表征空间与三维欧氏变换 SE(3) 的拓扑/几何关系,比只回归 depth/normal 更基础
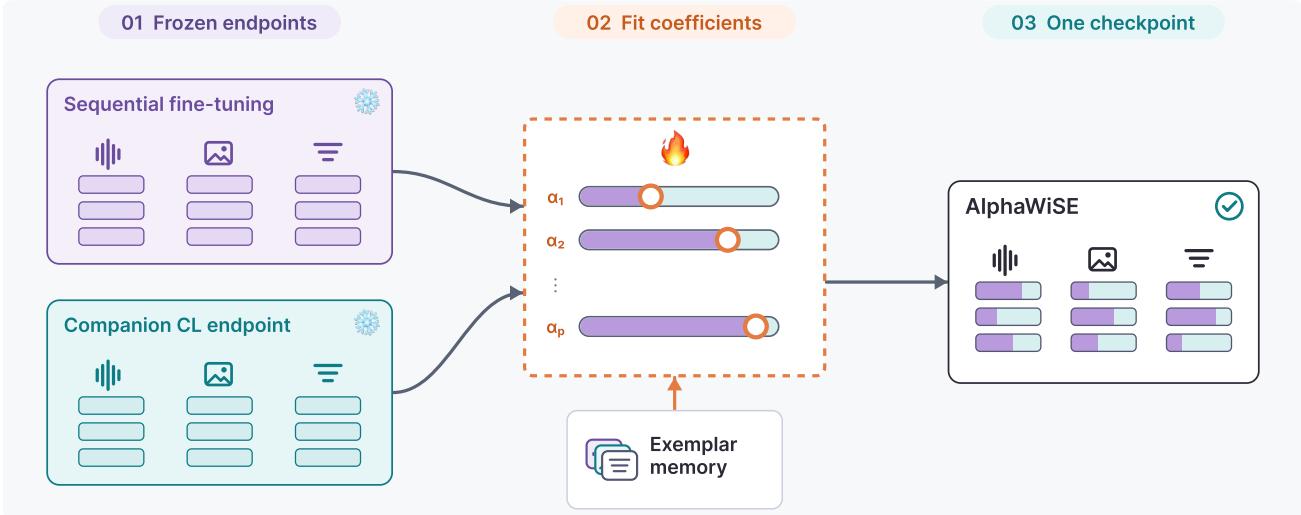
中高相关;详见方法、贡献和实验边界。
方法:用 post-hoc weight interpolation 维护 CLIP 类共享嵌入空间,关注 sequential adaptation 下的 alignment 遗忘
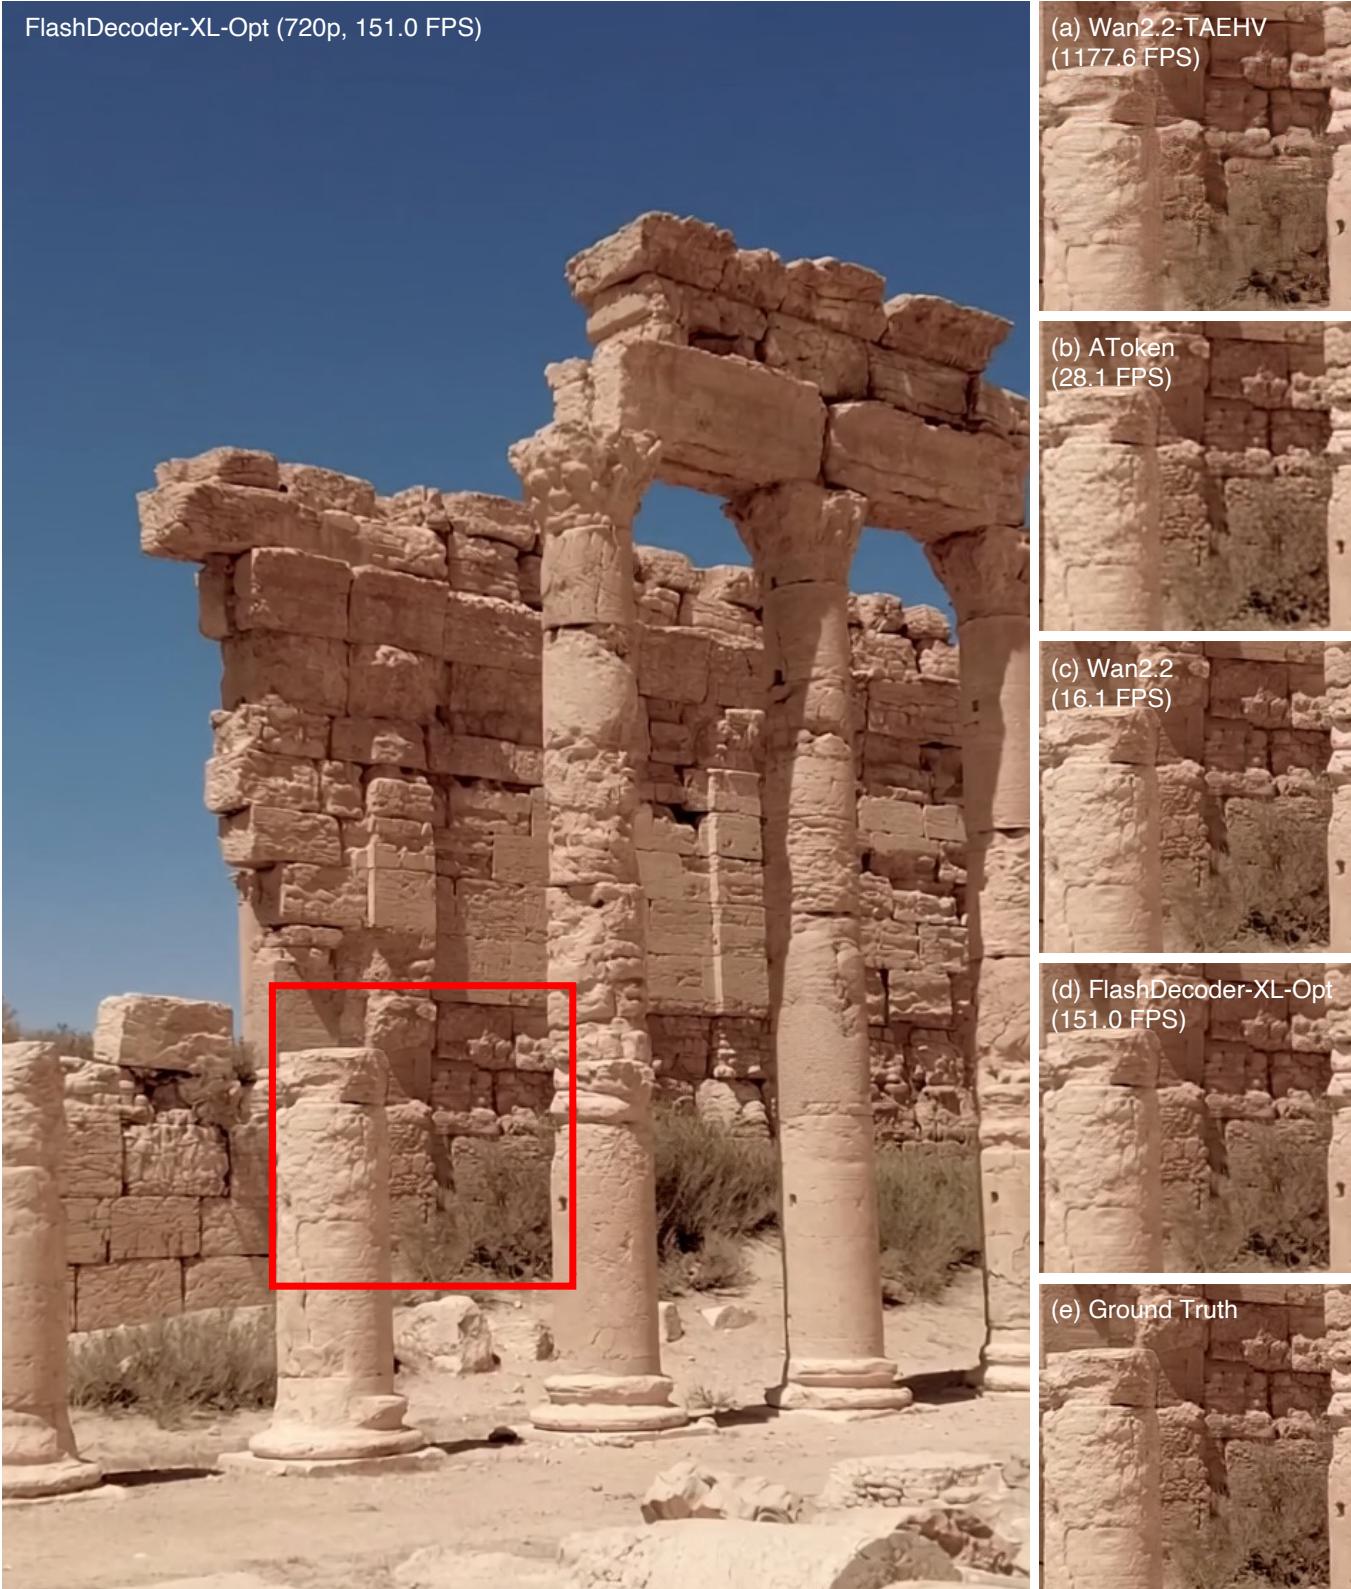
中高相关;详见方法、贡献和实验边界。
方法:不是预训练目标,但对 RAE/video diffusion latent 体系很关键:实时把 latent 解回像素,决定生成式表征是否可部署
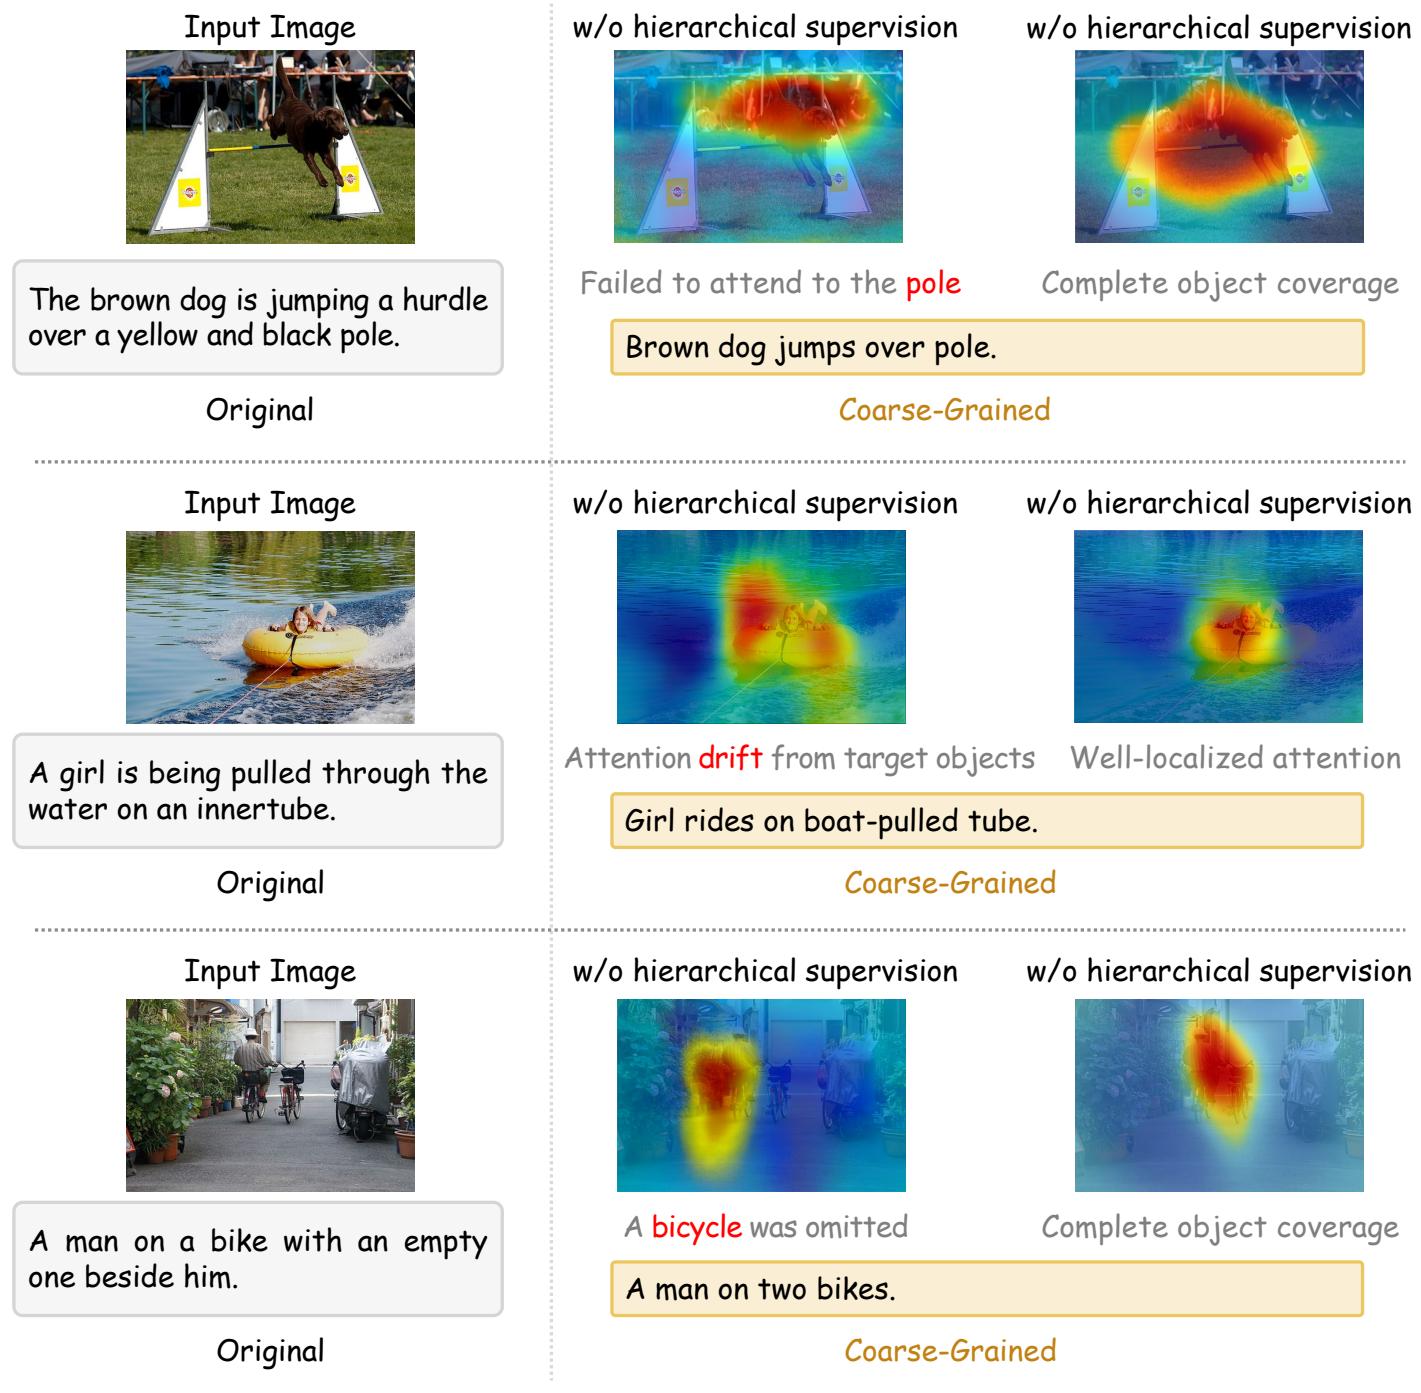
中高相关;详见方法、贡献和实验边界。
方法:同时构造视觉和文本的粗到细多粒度提示表征,适合与 CLIP dense/local alignment 工作连读
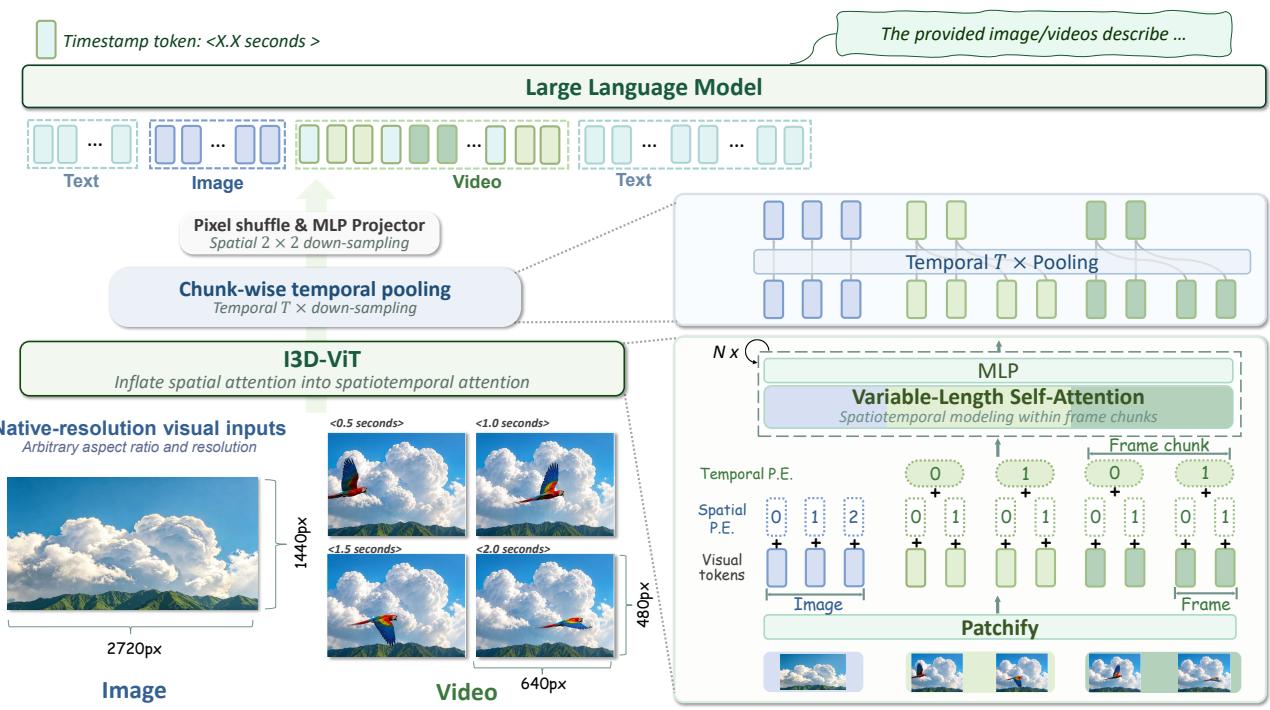
中高相关;详见方法、贡献和实验边界。
方法:开放训练策略与数据流水线,提出 I3D-ViT 和自适应帧分辨率,适合看视频表征工程化路线
中高相关;详见方法、贡献和实验边界。
方法:在视频生成 latent 中加入树状层级 denoising,让模型先做全局规划再流式输出
中高相关;详见方法、贡献和实验边界。
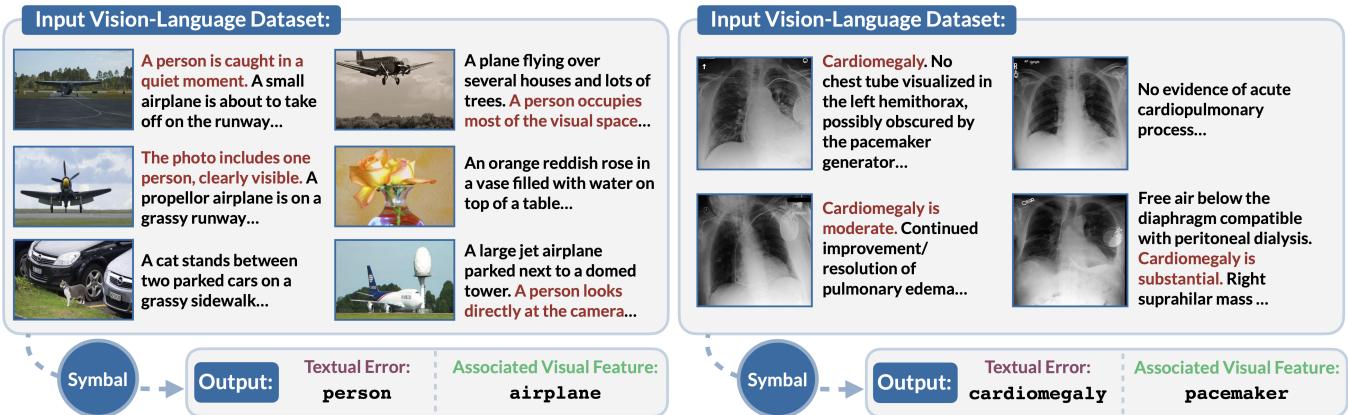
方法:针对 MLLM 生成 caption 中和视觉特征绑定的系统性错配,适合做图文预训练数据清洗工具
中高相关;详见方法、贡献和实验边界。
方法:从 VLP embedding anisotropy 出发做 adversarial detection,给 CLIP/VLP 表征流形诊断提供几何视角
中相关;详见方法、贡献和实验边界。
方法:动态融合多个视觉 foundation model 先验,说明不同 VFM 对空间/3D 任务的互补性
中相关;详见方法、贡献和实验边界。
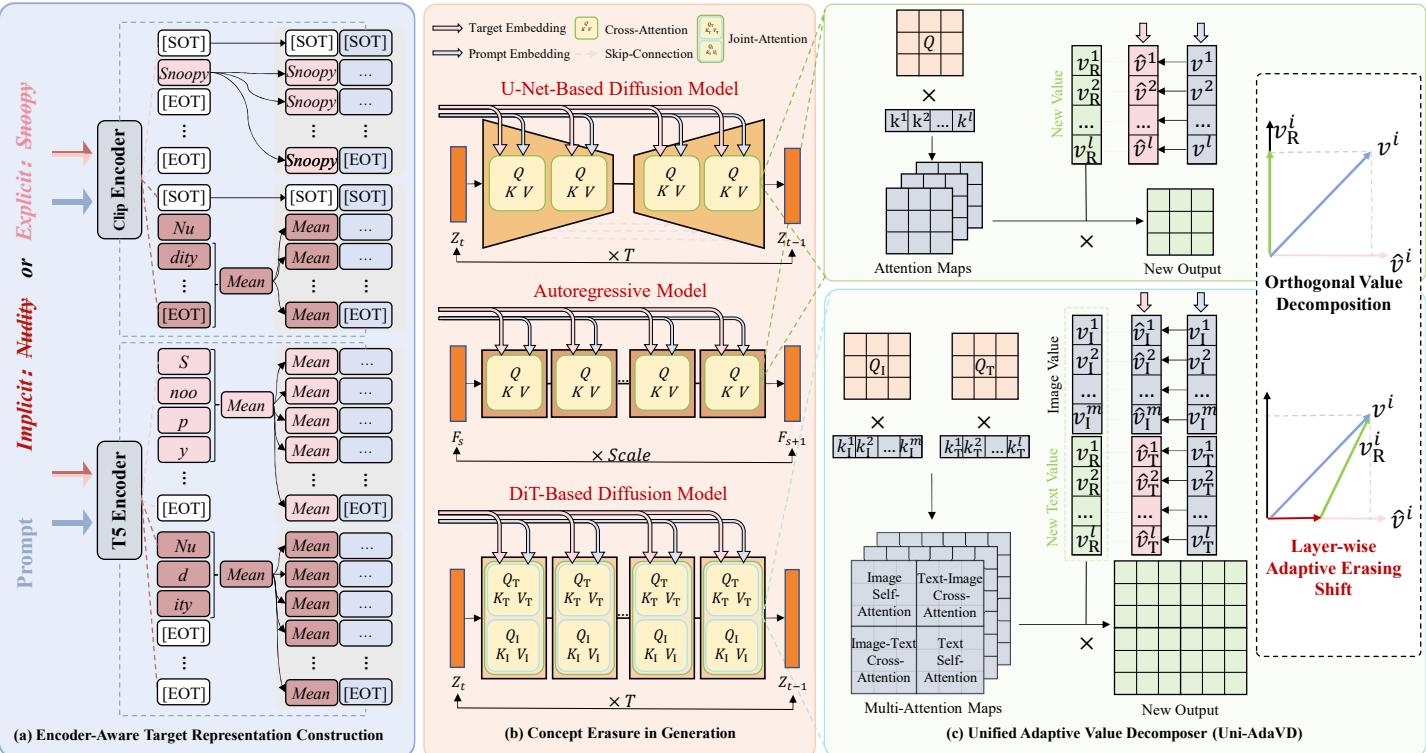
方法:把多模态 attention value space 当作统一干预空间,和视觉生成模型安全及语义方向控制相关
中相关;详见方法、贡献和实验边界。
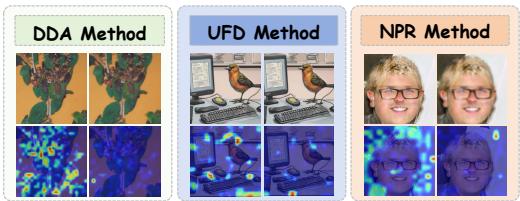
方法:用 local bottleneck + global structural reasoning + contrastive structural loss,把检测信号从局部 artifact 转向全局结构
中相关;详见方法、贡献和实验边界。
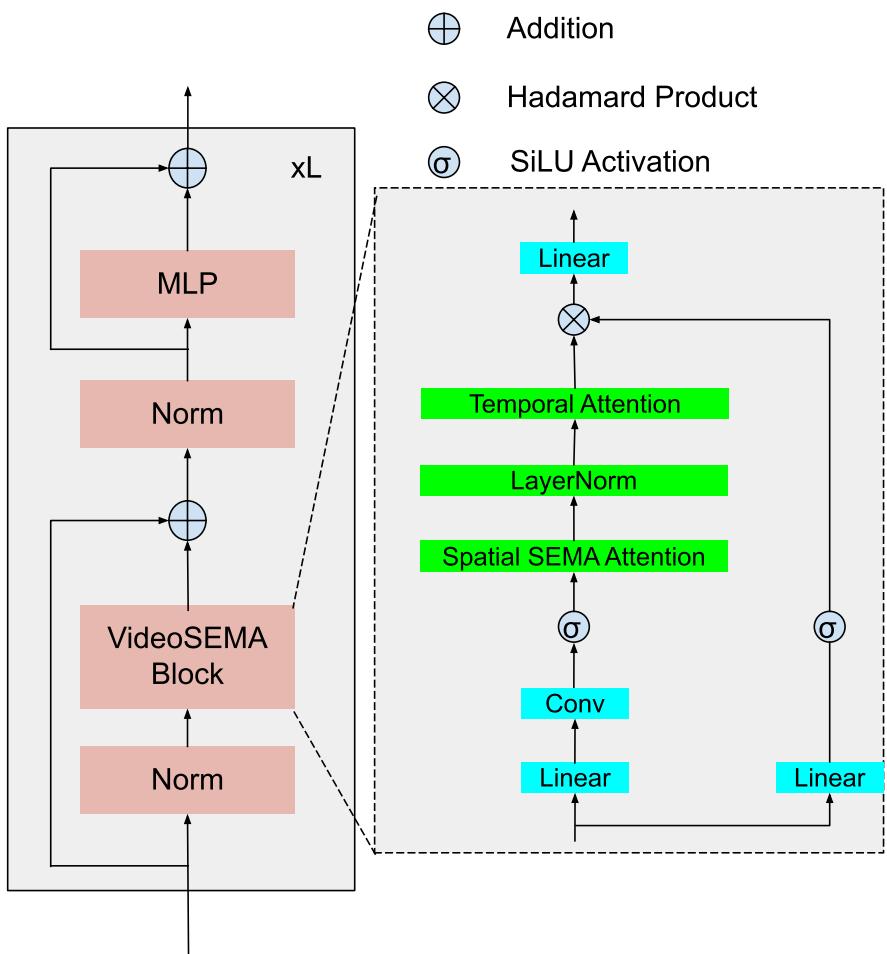
方法:主要是监督视频理解架构,但高分辨率/长视频 token 计算方式可作为视频预训练工程背景
高相关;详见方法、贡献和实验边界。
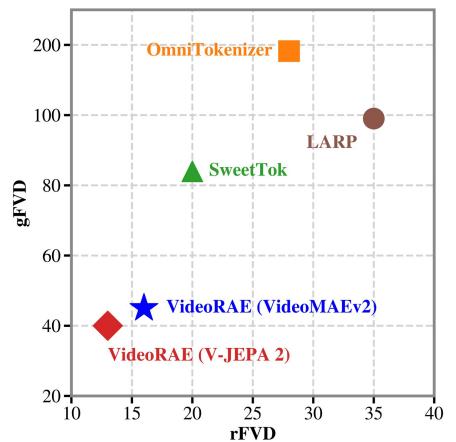
方法:把冻结视频基础模型的多尺度表征压成可重建、可生成的视频 latent,直接连接视频 SSL backbone 与生成模型 latent
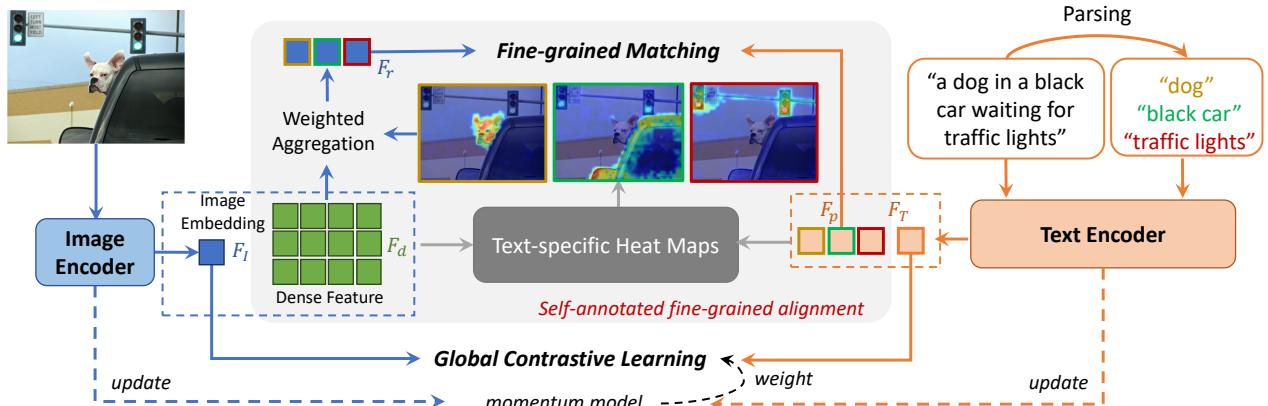
高相关;详见方法、贡献和实验边界。
方法:只用 image-text pairs 给 CLIP 做 region-phrase 自标注对齐,目标是补足 CLIP 的细粒度 dense representation
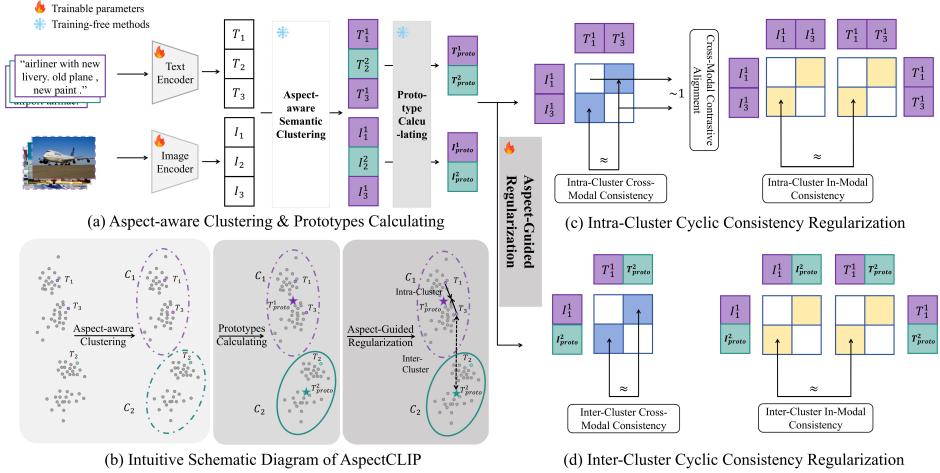
高相关;详见方法、贡献和实验边界。
方法:从 caption 只描述图像某一 aspect 的事实出发,重写 CLIP 表征空间的 consistency regularization
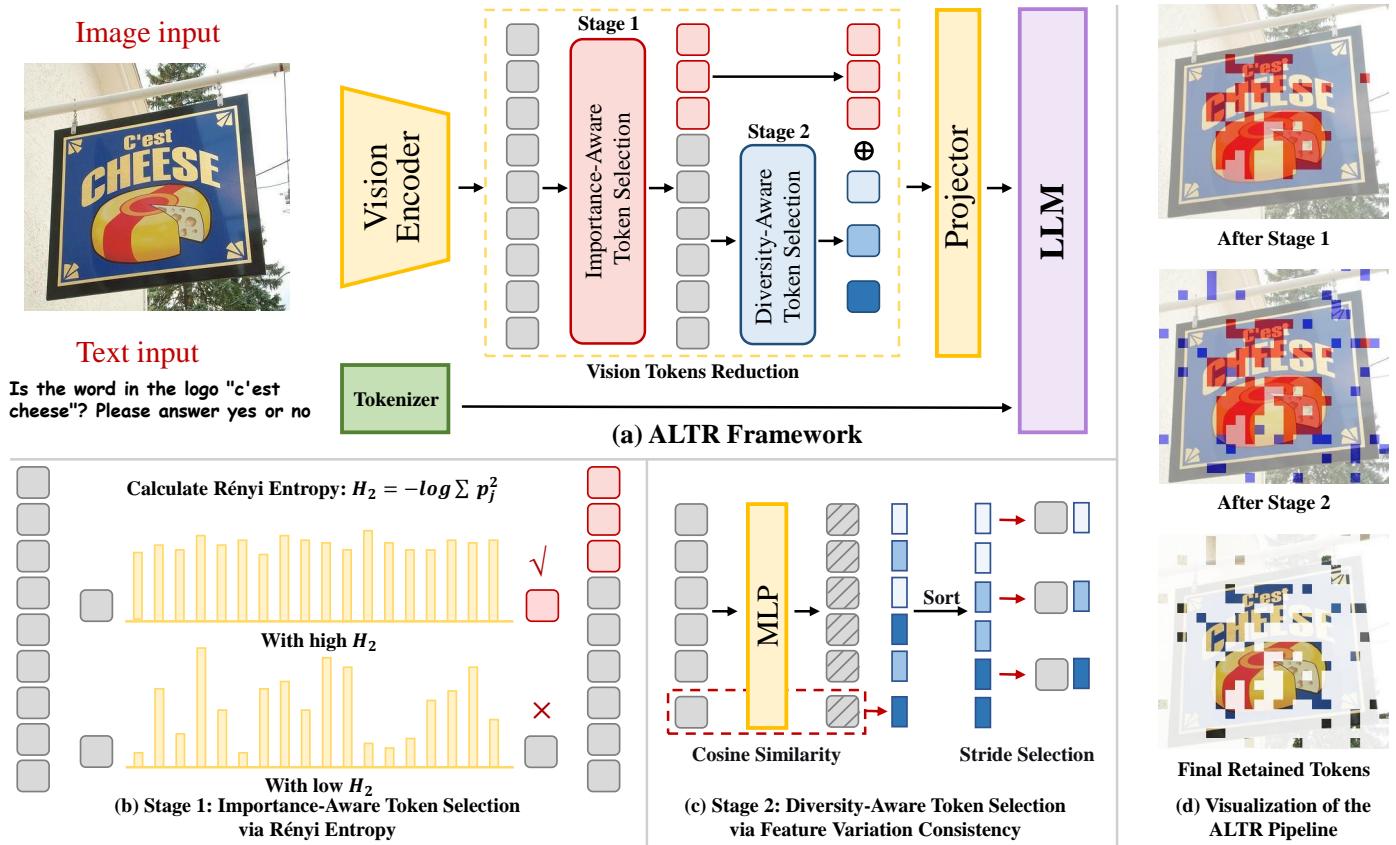
高相关;详见方法、贡献和实验边界。
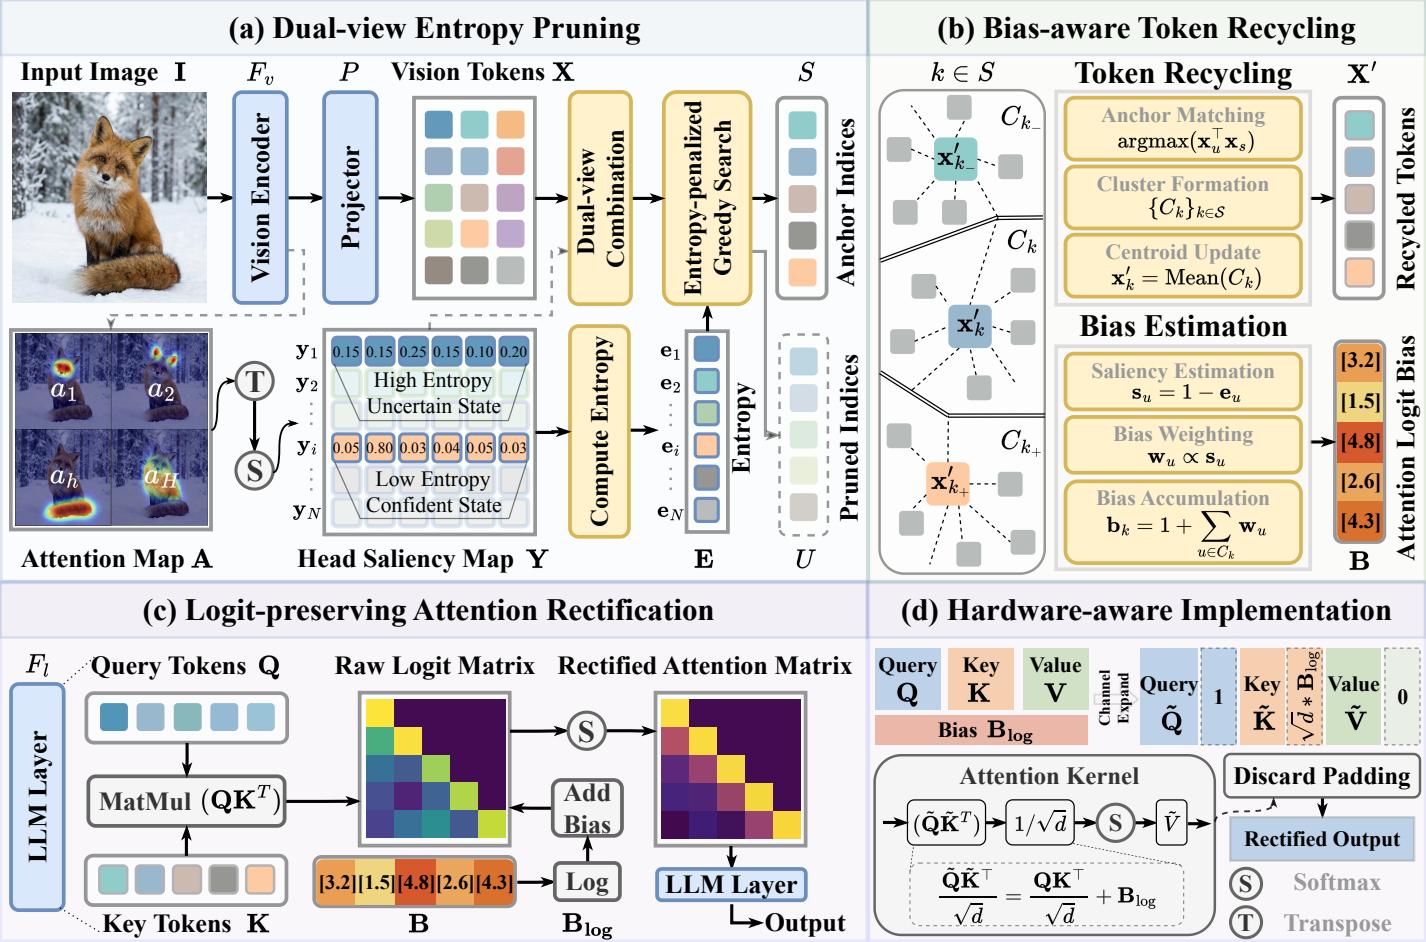
方法:不依赖 attention map,用 entropy 与一致性信号保留重要且多样的 visual tokens
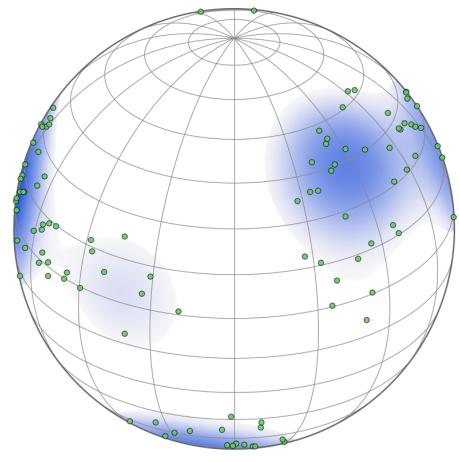
高相关;详见方法、贡献和实验边界。
方法:把 CLIP embedding space 解释为 hyperspherical semantic mixture,而不是高斯空间
中高相关;详见方法、贡献和实验边界。
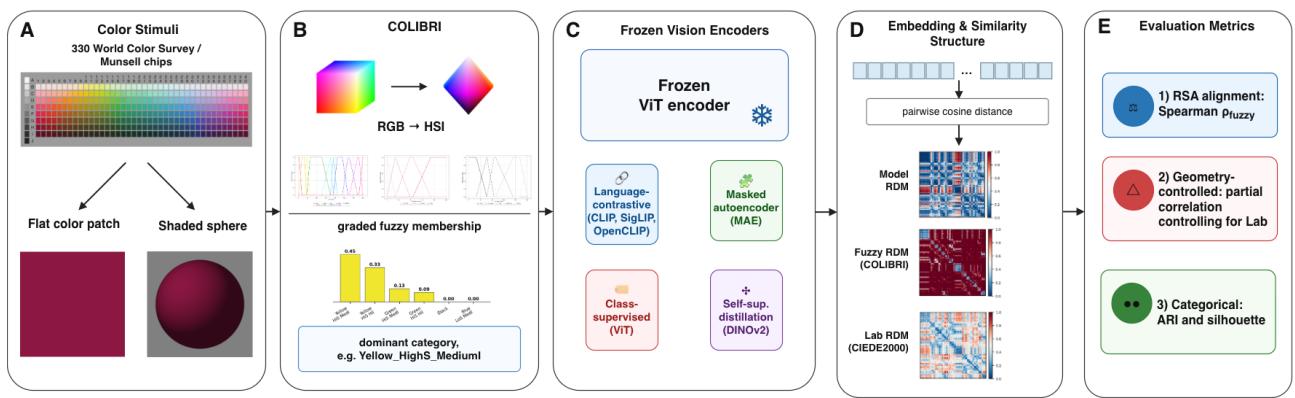
方法:用人类 fuzzy color categories 检查 ViT/MAE/语言监督模型如何编码颜色
中高相关;详见方法、贡献和实验边界。
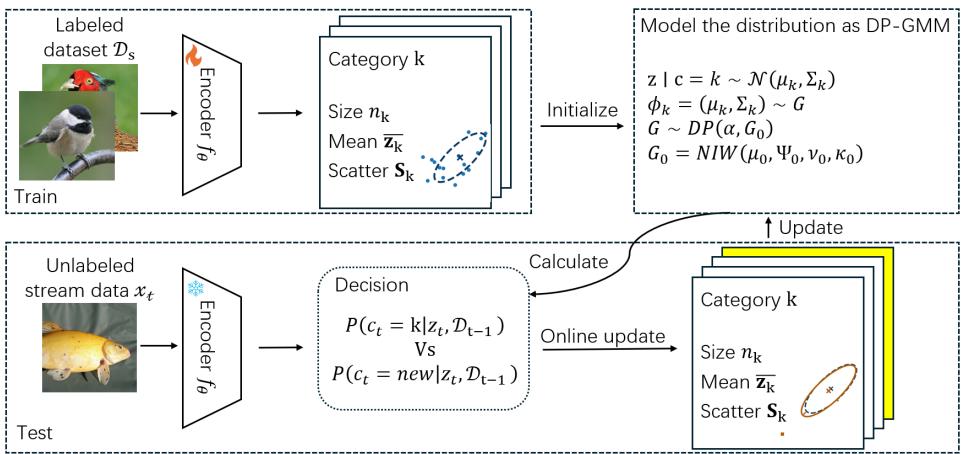
方法:在线判断新样本属于已知类还是应生成新类,和开放世界表征聚类/novel class discovery 相关
中高相关;详见方法、贡献和实验边界。
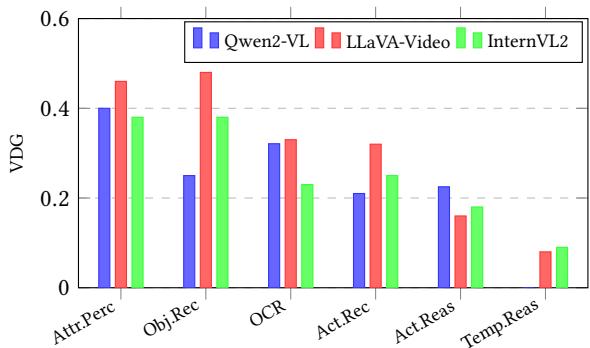
方法:证明视频 LLM benchmark accuracy 与真实视觉依赖可以分离,提出 Visual Dependency Gap
中高相关;详见方法、贡献和实验边界。
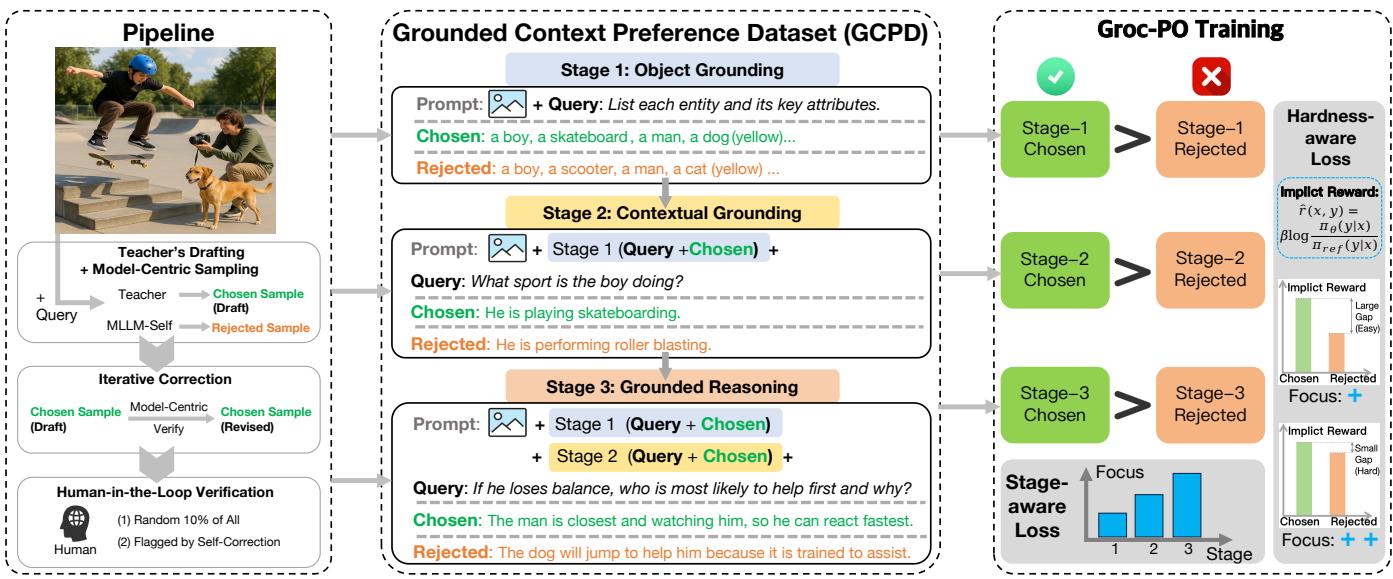
方法:把偏好优化的监督粒度前移到 grounding/context 阶段,减少多模态推理中的视觉幻觉传播
中相关;详见方法、贡献和实验边界。
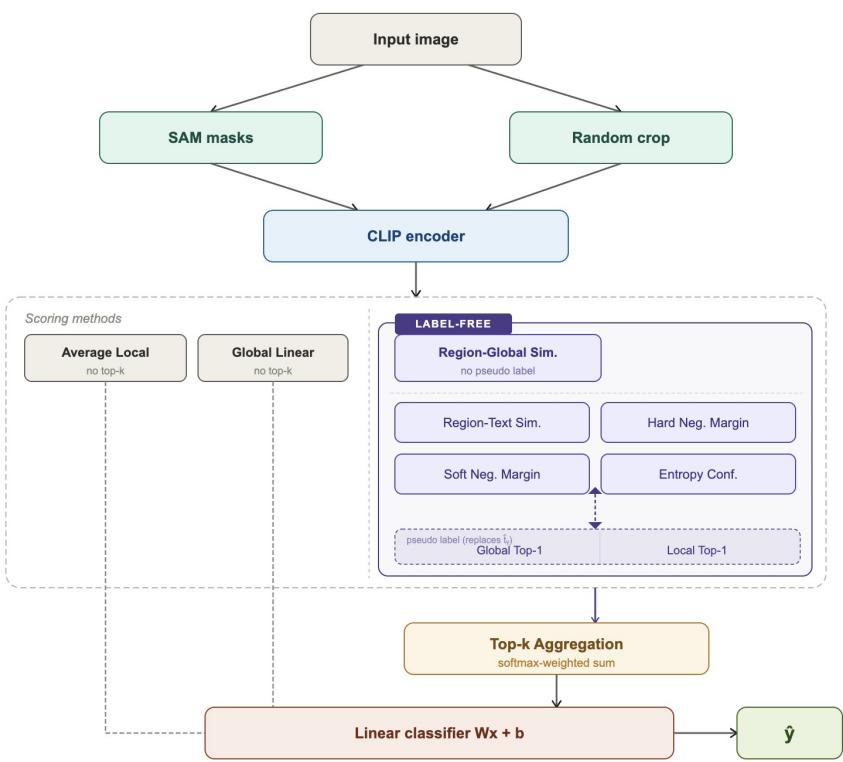
方法:用 CLIP 与 SAM 做无标签细粒度 region scoring,适合看训练免费局部证据选择
中相关;详见方法、贡献和实验边界。
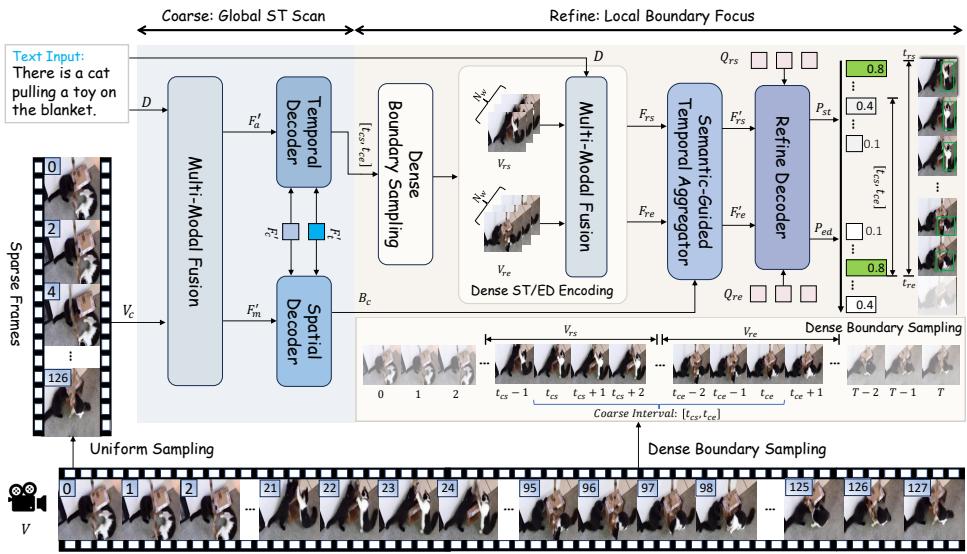
方法:面向长视频 grounding 的 coarse-to-fine 视觉语言融合和边界细化
中相关;详见方法、贡献和实验边界。
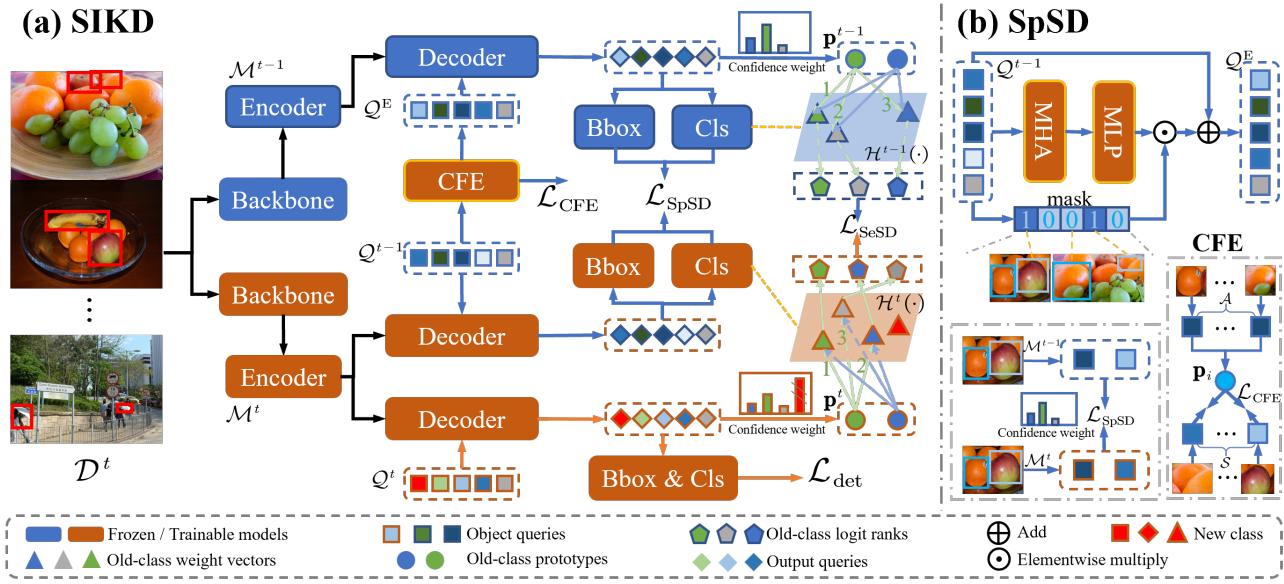
方法:用 spatial/semantic symbiosis 做增量目标检测蒸馏,关注旧知识如何以共享表征保留
中相关;详见方法、贡献和实验边界。
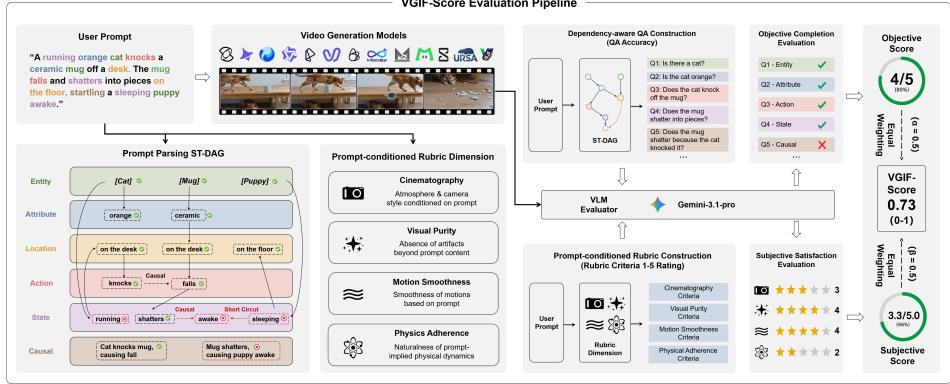
方法:提出自动化可解释的 video generation instruction-following 诊断
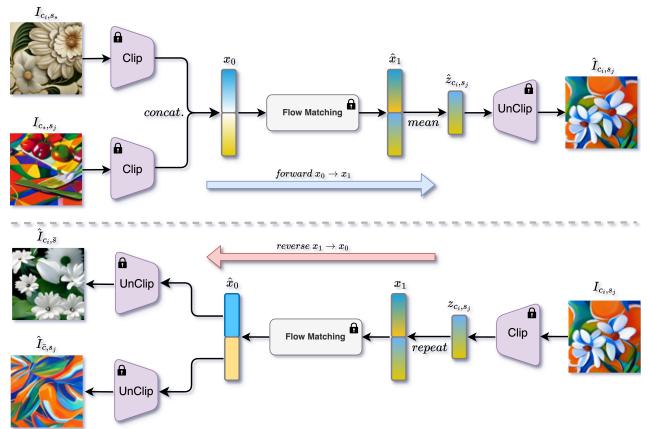
高相关;详见方法、贡献和实验边界。
方法:把 contrastive regularization 接进 flow matching,在 CLIP/DINO/ALIGN embedding space 做 content-style 表征解耦
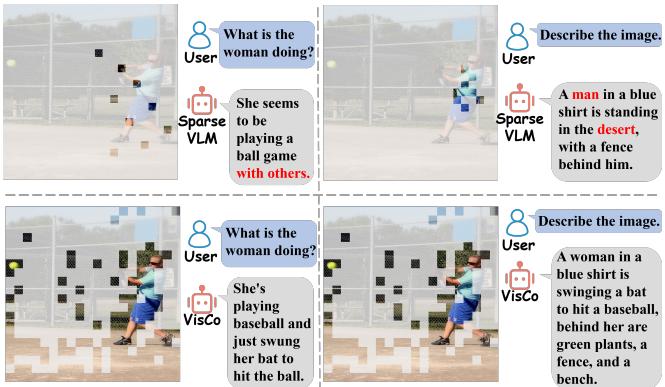
高相关;详见方法、贡献和实验边界。
方法:复用预训练 VLM 自身作为 intrinsic compressor,用少量 memory tokens 压缩视觉信息,直接影响视觉 token 表征保真
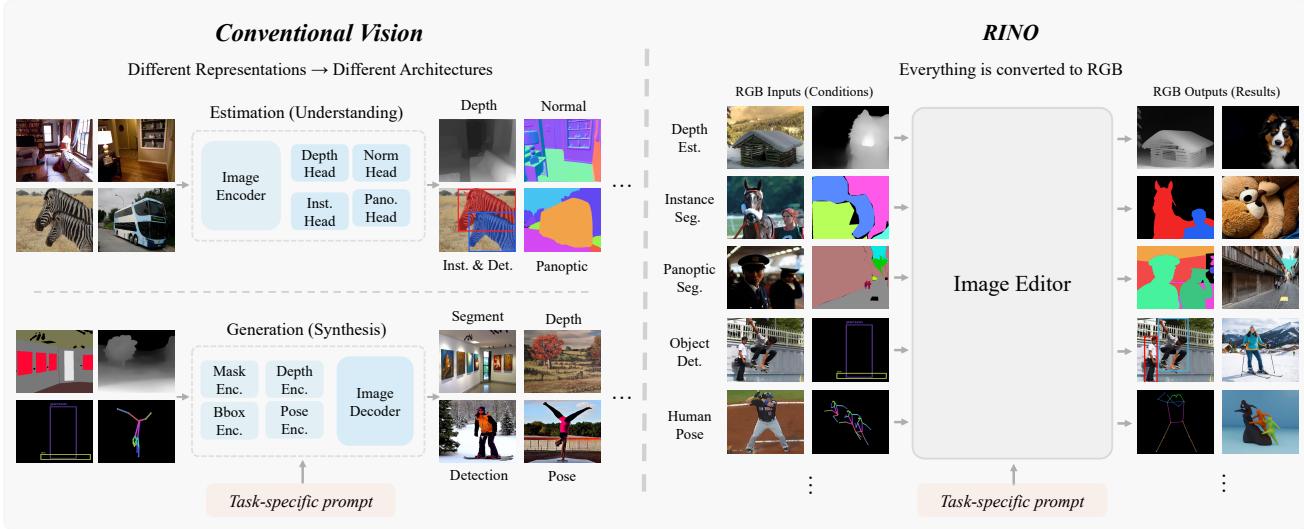
高相关;详见方法、贡献和实验边界。
方法:把 mask、depth 等结构化视觉信号统一成 RGB in/RGB out,有机会成为视觉任务统一接口
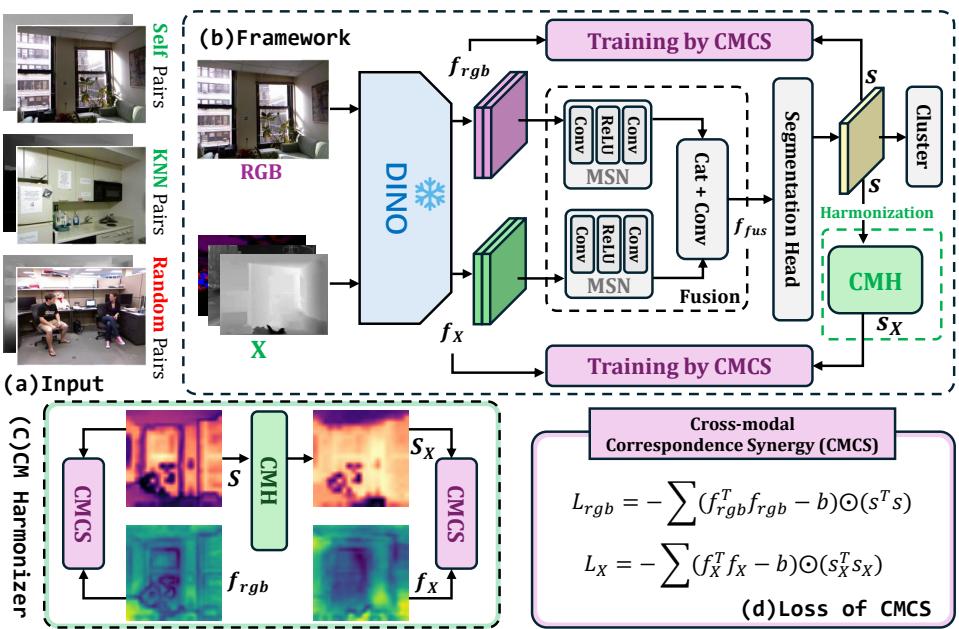
高相关;详见方法、贡献和实验边界。
方法:基于 DINOv3 做 label-free multimodal segmentation,直接检验 VFM 特征能否统一 RGB 与其他传感器结构
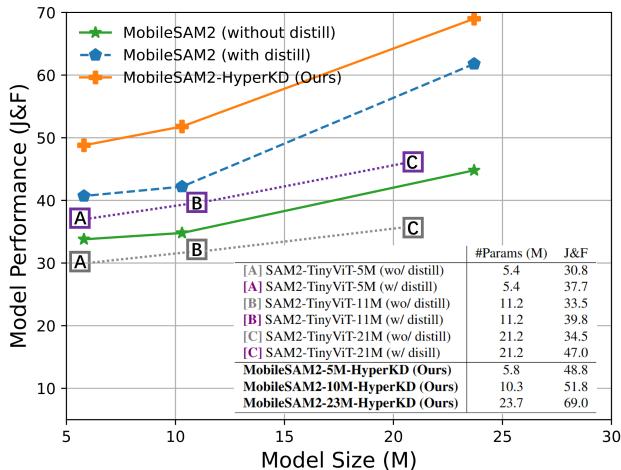
中高相关;详见方法、贡献和实验边界。
方法:把 SAM2 的图像/视频分割知识蒸馏到轻量模型,关注 VFM 知识如何跨时序和粒度迁移
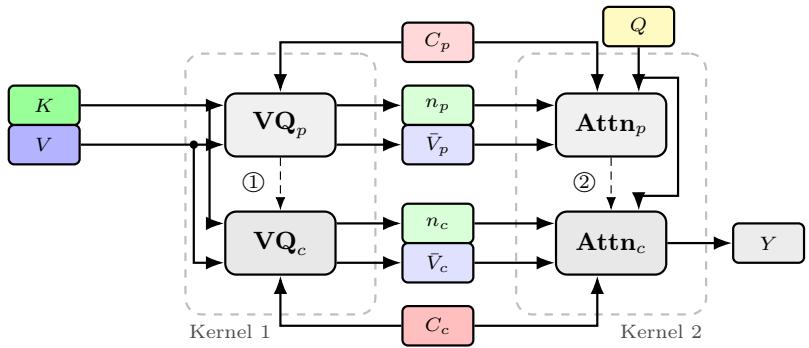
中高相关;详见方法、贡献和实验边界。
方法:AVQ-Attention 根据注意力重要性自适应分配 VQ codebook capacity,影响视觉 token 表征效率
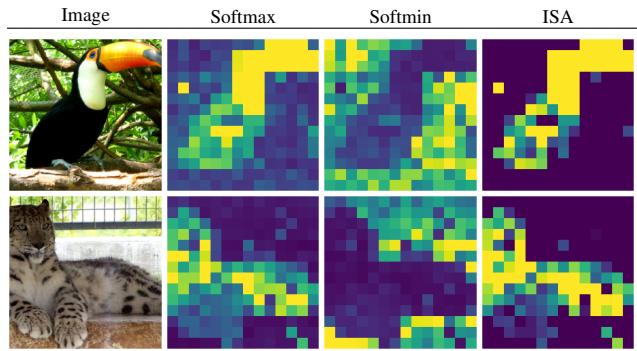
中高相关;详见方法、贡献和实验边界。
方法:利用负注意力抑制背景响应,提升 ViT object-centric selectivity 与 OOD robustness
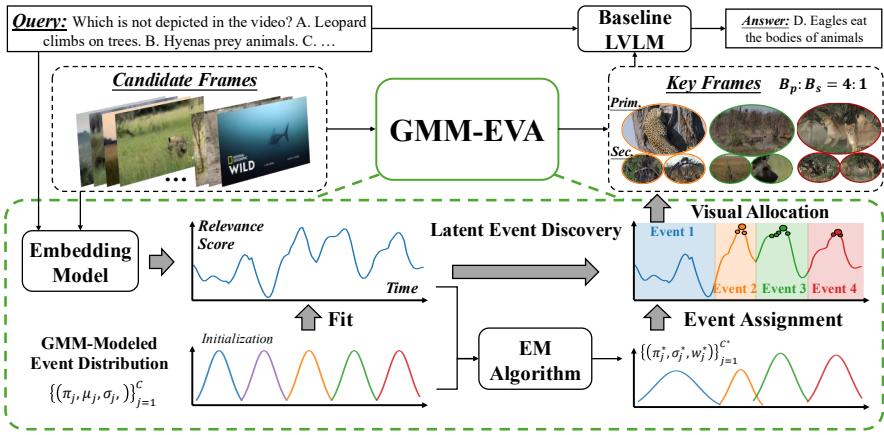
中高相关;详见方法、贡献和实验边界。
方法:用 event-level structure 分配长视频 visual token budget,和视频 VLM/视频预训练的 token selection 直接相关
中高相关;详见方法、贡献和实验边界。
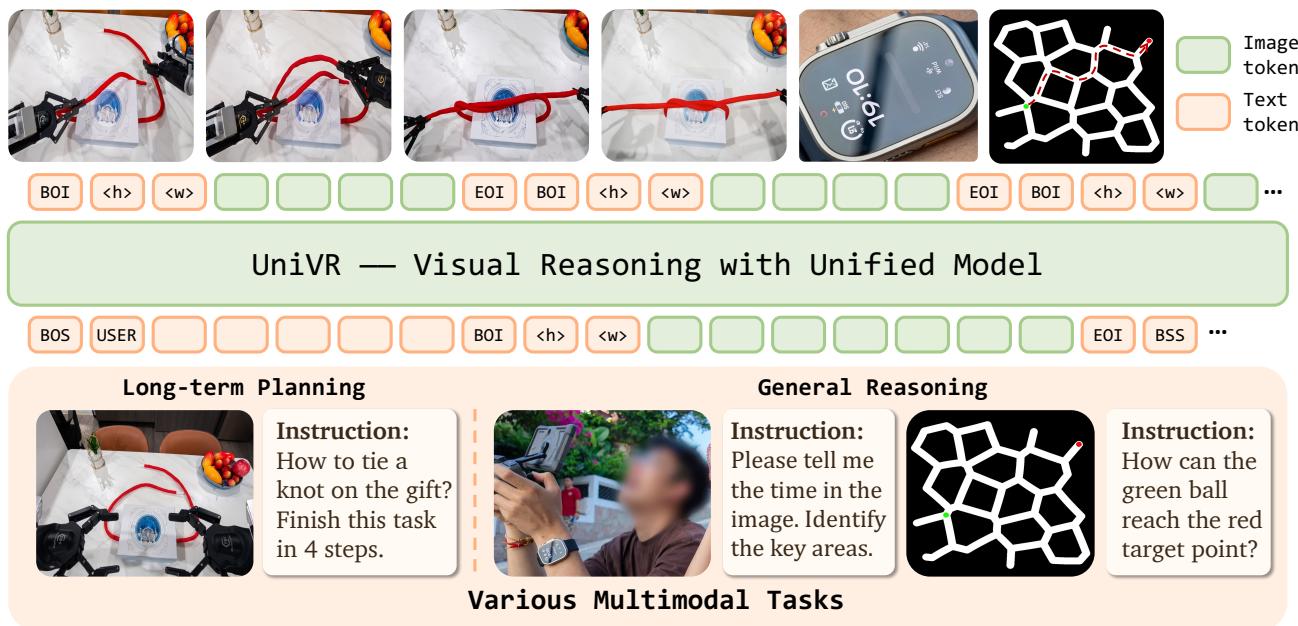
方法:从纯视觉 demonstrations 学复杂推理、物理动态和长期规划,不依赖 image-text pairs
中高相关;详见方法、贡献和实验边界。
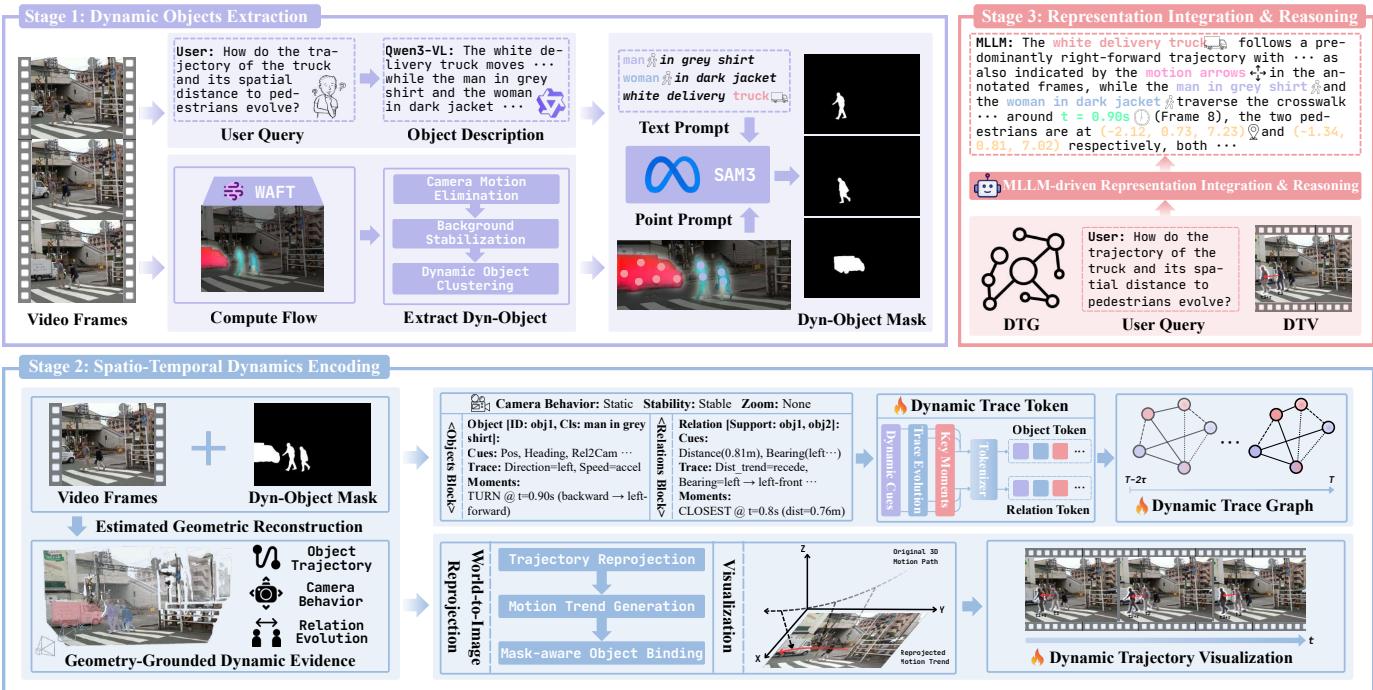
方法:用 trace tokens 和 geometry-informed priors 让 MLLM 连续跟踪动态对象证据,补视频表征的 4D readout
中相关;详见方法、贡献和实验边界。
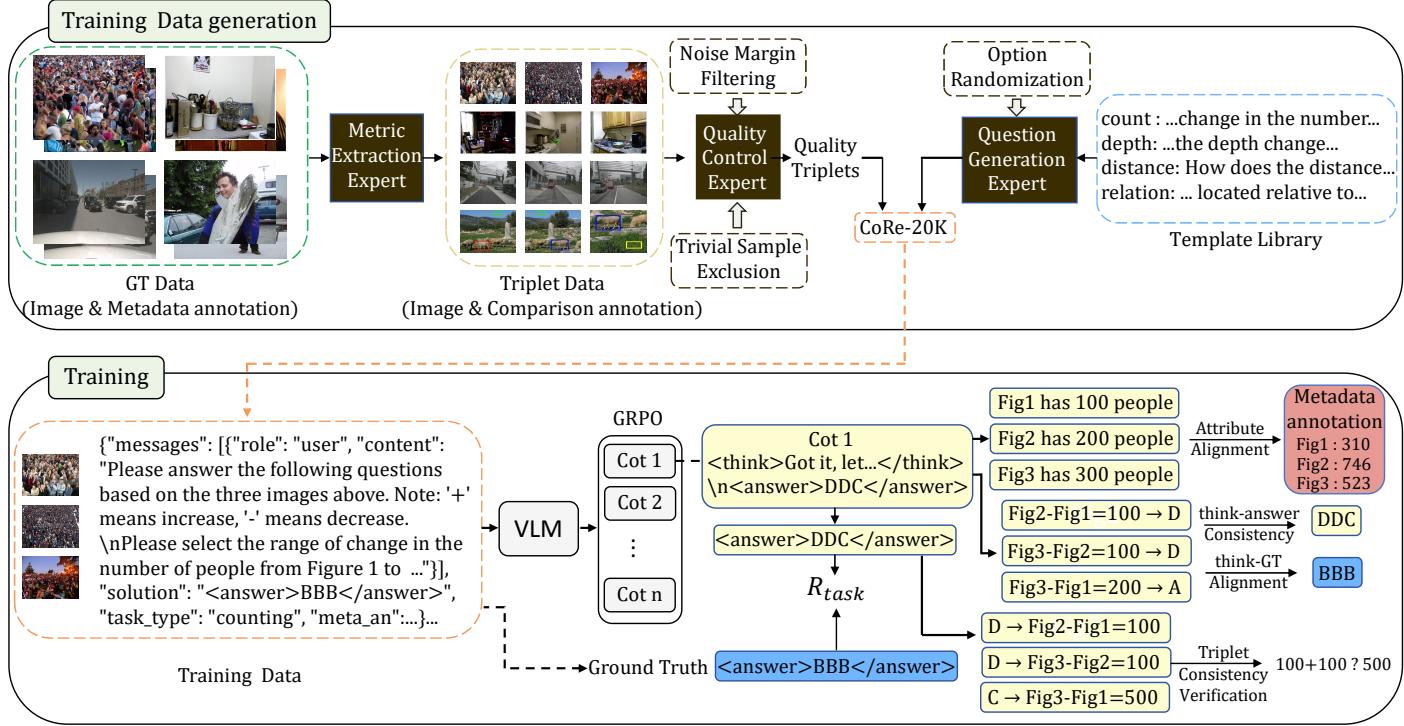
方法:构造 cross-image comparative reasoning 数据和 reward,关注 fine-grained attribute grounding
中相关;详见方法、贡献和实验边界。
方法:分析 video diffusion 在长串因果事件上的 seriality gap,有助判断生成式视频模型能否当通用视觉 learner
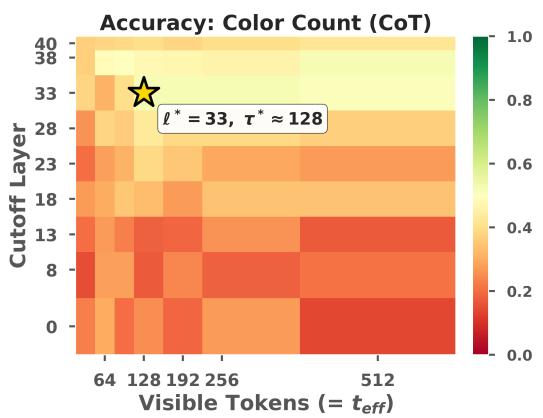
中相关;详见方法、贡献和实验边界。
方法:用 causal masking 定义 Visual Access Boundary,诊断 CoT 是否真的延长了图像 token 访问
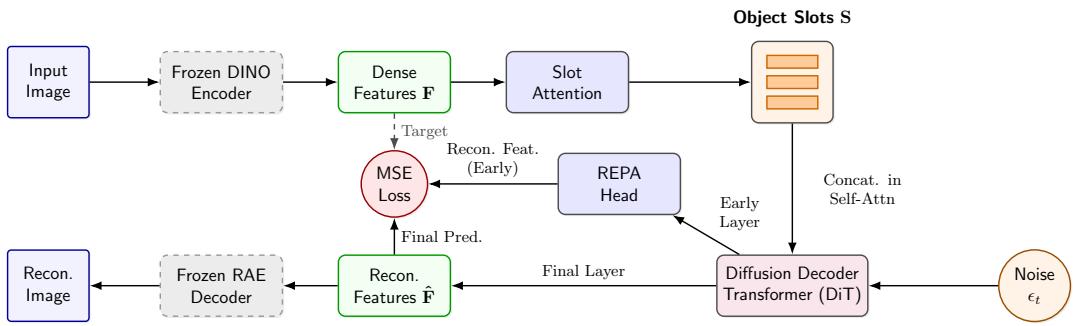
高相关;详见方法、贡献和实验边界。
方法:把 object-centric learning 直接放到冻结 VFM 语义特征空间和 DiT 解码里,贴近 DINO/RAE/无监督对象发现主线
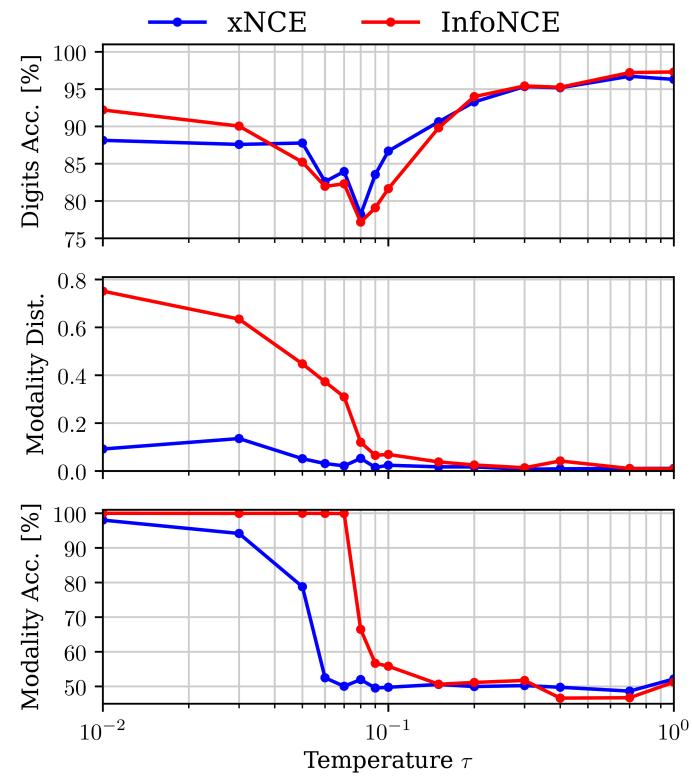
高相关;详见方法、贡献和实验边界。
方法:直接解释 CLIP-style dual encoder 的 modality gap,并给出 xNCE 这种 contrastive objective 改法
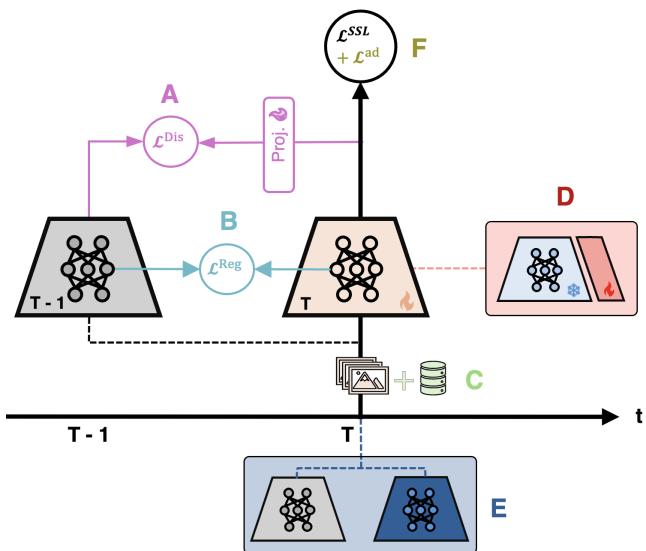
高相关;详见方法、贡献和实验边界。
方法:系统梳理 continual self-supervised learning for vision,适合作为长期预训练/持续学习路线图
高相关;详见方法、贡献和实验边界。
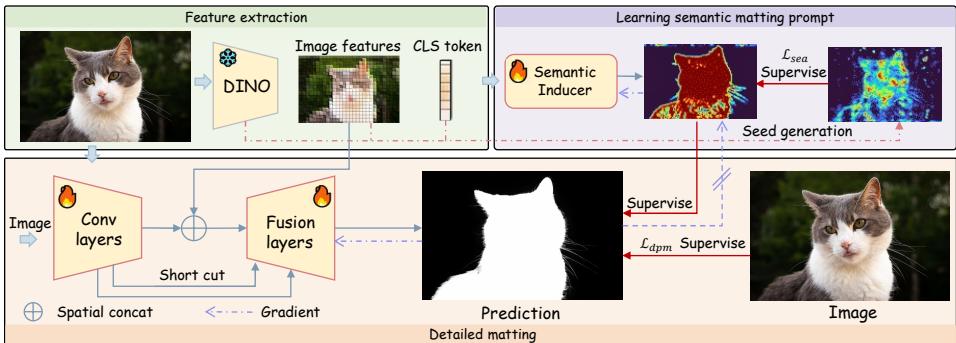
方法:用冻结 self-supervised ViT 特征生成语义 matting prompt,展示 SSL 表征可承担 annotation-free dense task
中高相关;详见方法、贡献和实验边界。
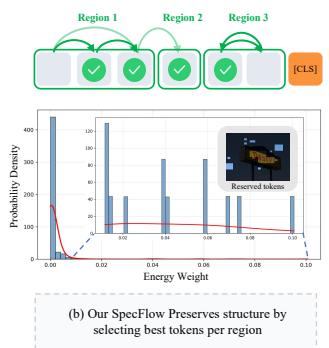
方法:训练-free visual token condensation 直接影响 VLM 视觉 token 的保真压缩,和视觉表征读出效率强相关
中高相关;详见方法、贡献和实验边界。
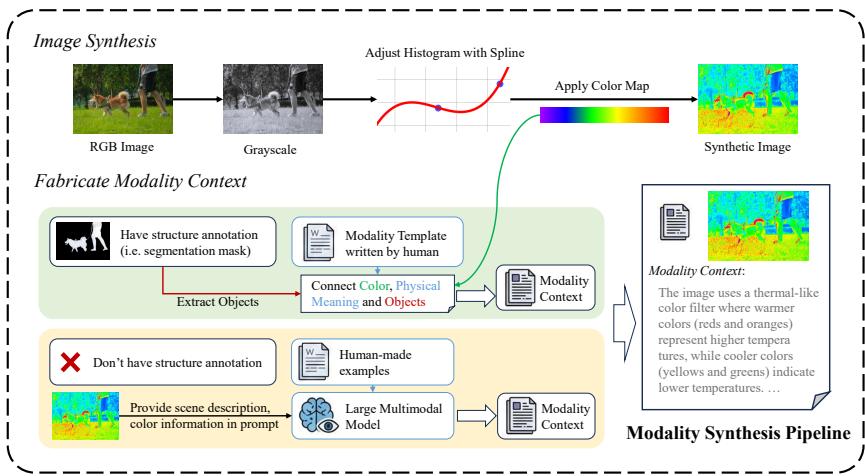
方法:用 fabricated modality synthesis 训练 LMM 泛化到未见视觉模态,和 modality-agnostic visual representation 直接相关
中高相关;详见方法、贡献和实验边界。
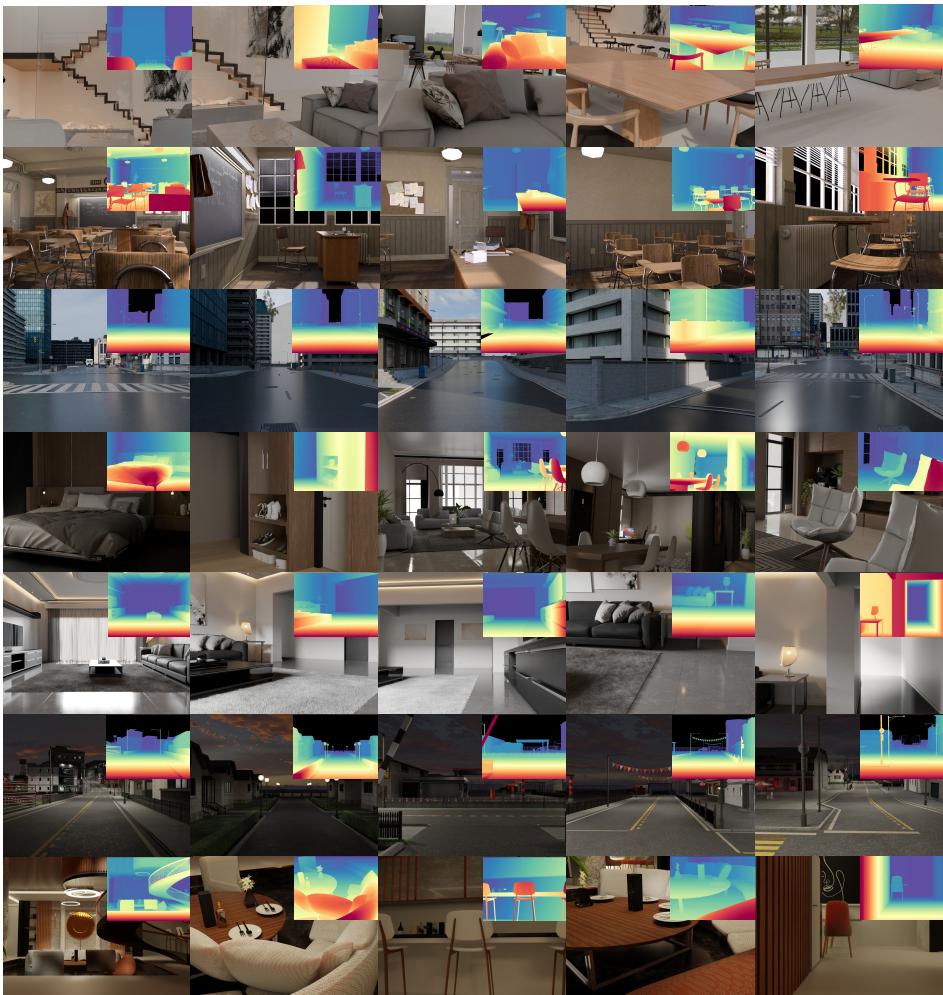
方法:以 DINOv3 初始化几何 foundation model,关注跨域 metric geometry 和 pixel-wise field
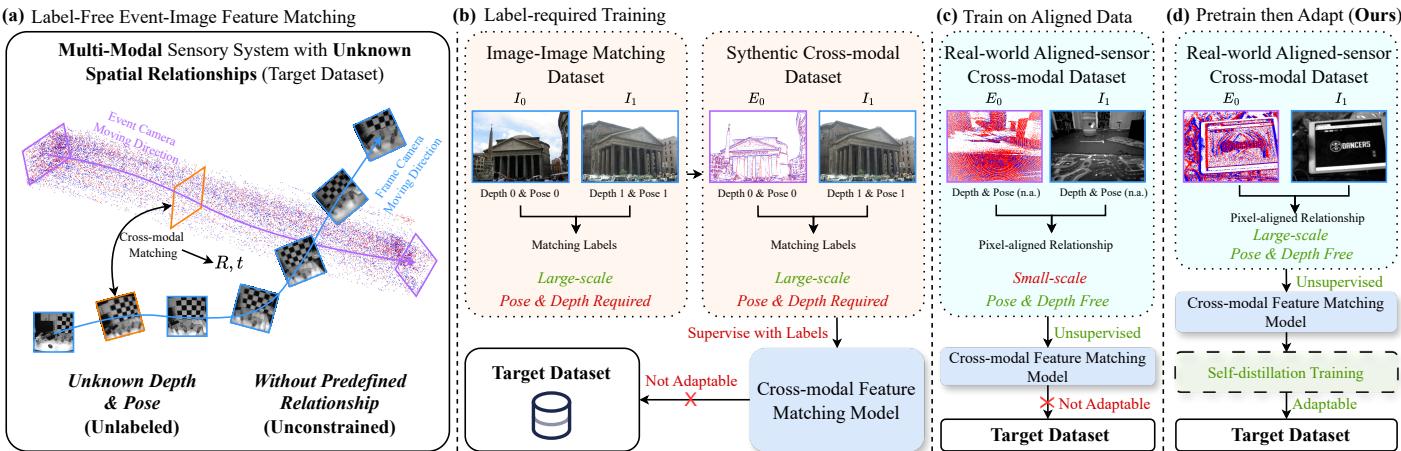
中高相关;详见方法、贡献和实验边界。
方法:事件-图像 feature matching 虽偏传感器融合,但 label-agnostic distillation pretraining + contrastive objective 有迁移价值
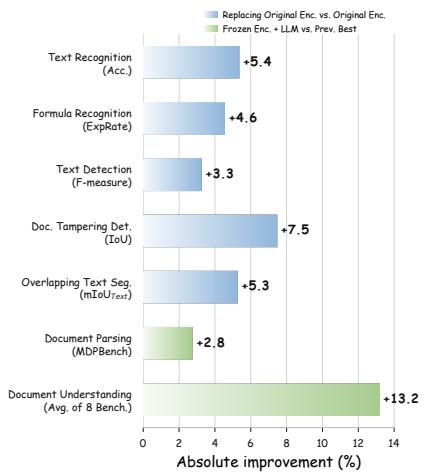
中相关;详见方法、贡献和实验边界。
方法:文档视觉-文本预训练不等同自然图像 SSL,但能补视觉 token 对文字、公式和版式的表征短板
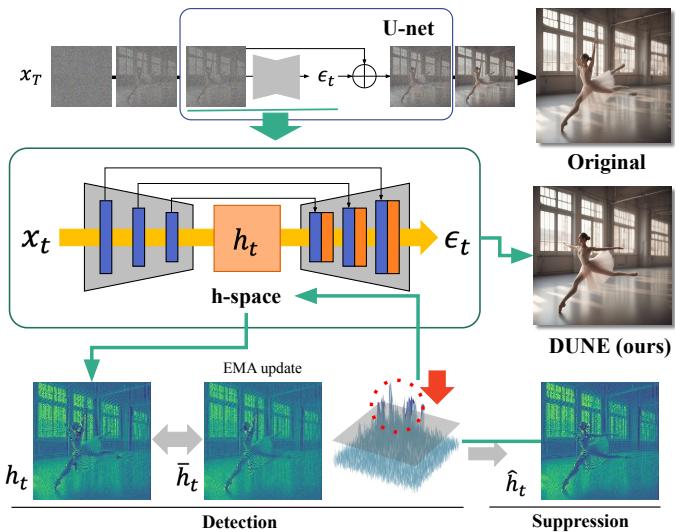
中相关;详见方法、贡献和实验边界。
方法:DUNE 主要是 diffusion generation refinement,但其 internal-latent analysis 有助理解生成 backbone 的视觉表征控制点
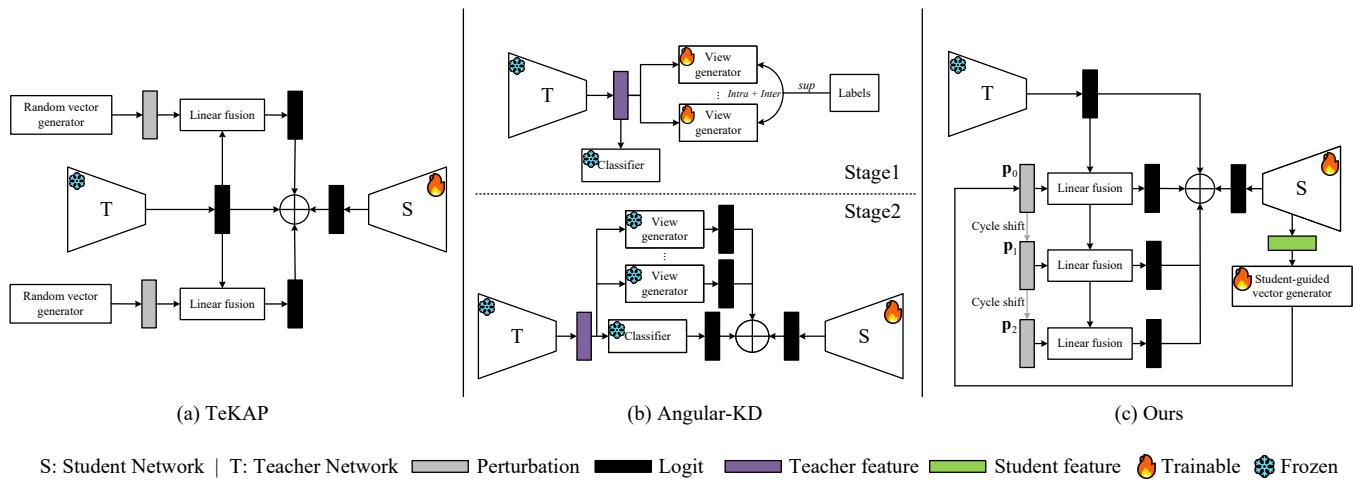
中相关;详见方法、贡献和实验边界。
方法:学生引导的 single-teacher view augmentation 对蒸馏式自监督/压缩有参考,但不是视觉 foundation 预训练本身
高相关;详见方法、贡献和实验边界。
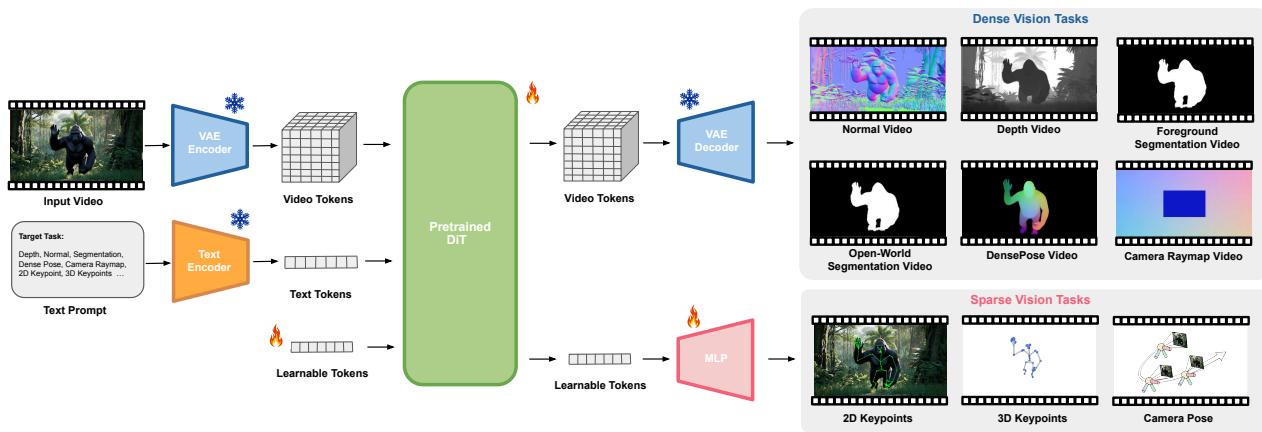
方法:把大规模视频生成 backbone 当作通用视觉预训练信号,并直接和 V-JEPA/VideoMAE 等范式比较
高相关;详见方法、贡献和实验边界。
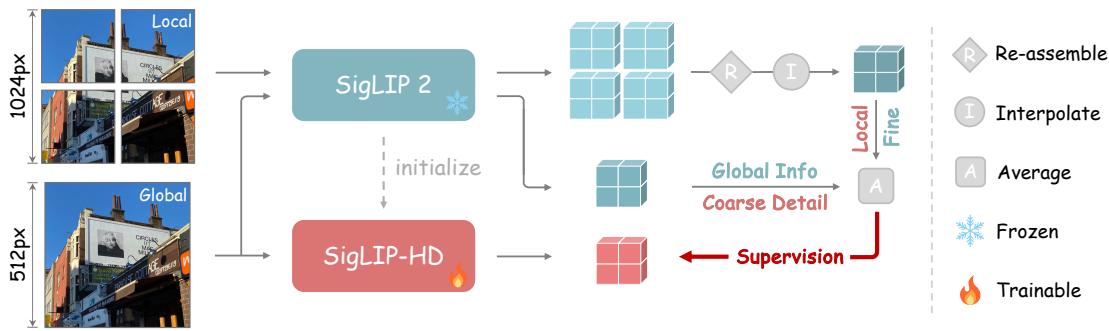
方法:在 SigLIP 2 上用 fine-to-coarse supervision 提升同等推理预算下的视觉 token 质量
高相关;详见方法、贡献和实验边界。
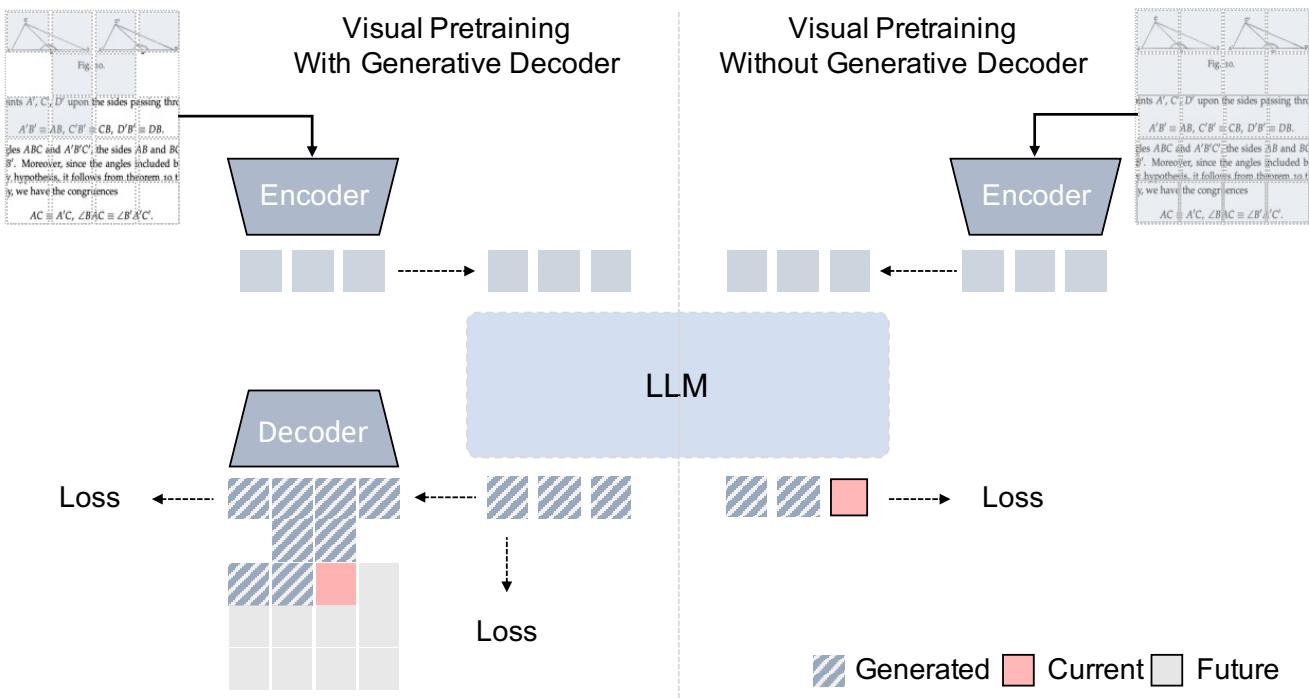
方法:系统研究 unsupervised visual pretraining 对语言智能的贡献,强调文档/网页的视觉结构不应被纯文本化丢弃
高相关;详见方法、贡献和实验边界。
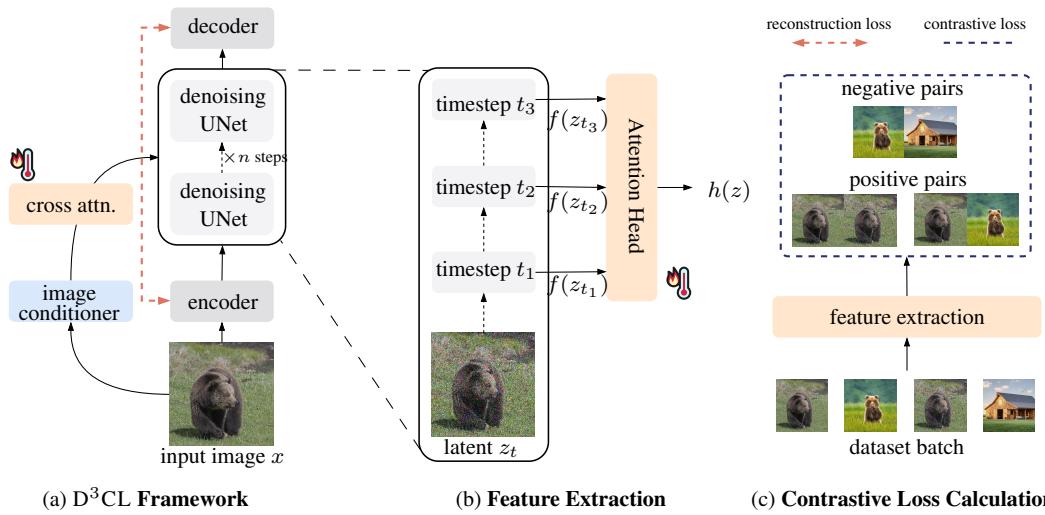
方法:把 diffusion denoising timestep 当作随机视图,加入 contrastive objective 来学习判别表征
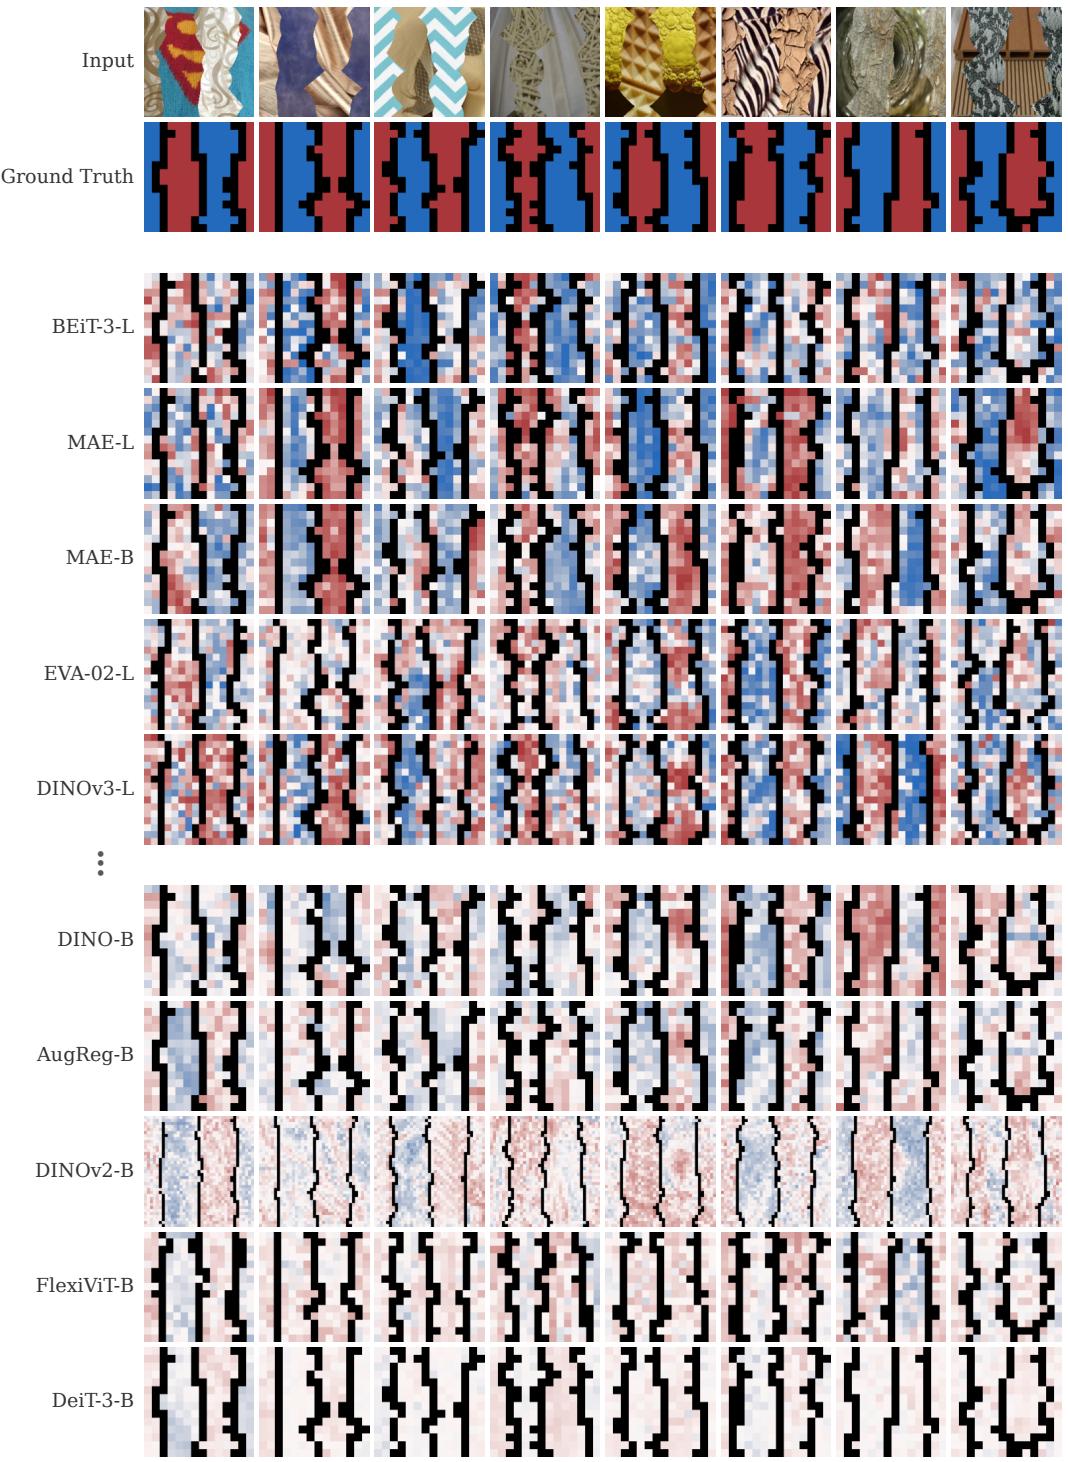
高相关;详见方法、贡献和实验边界。
方法:分析 supervised/self-supervised ViT 是否从自然图像统计中学到 Gestalt-like figure-ground cues
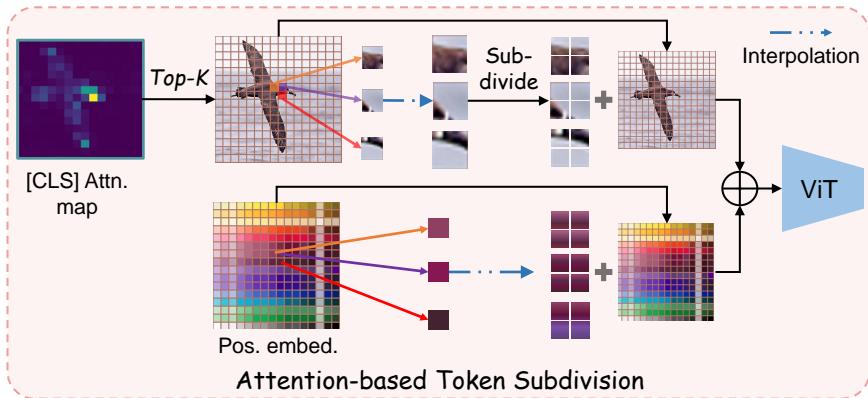
中高相关;详见方法、贡献和实验边界。
方法:选择性把关键 patch 细分成 subtokens,可改善 DINOv2 在 GCD/fine-grained novel category 上的表现
中高相关;详见方法、贡献和实验边界。
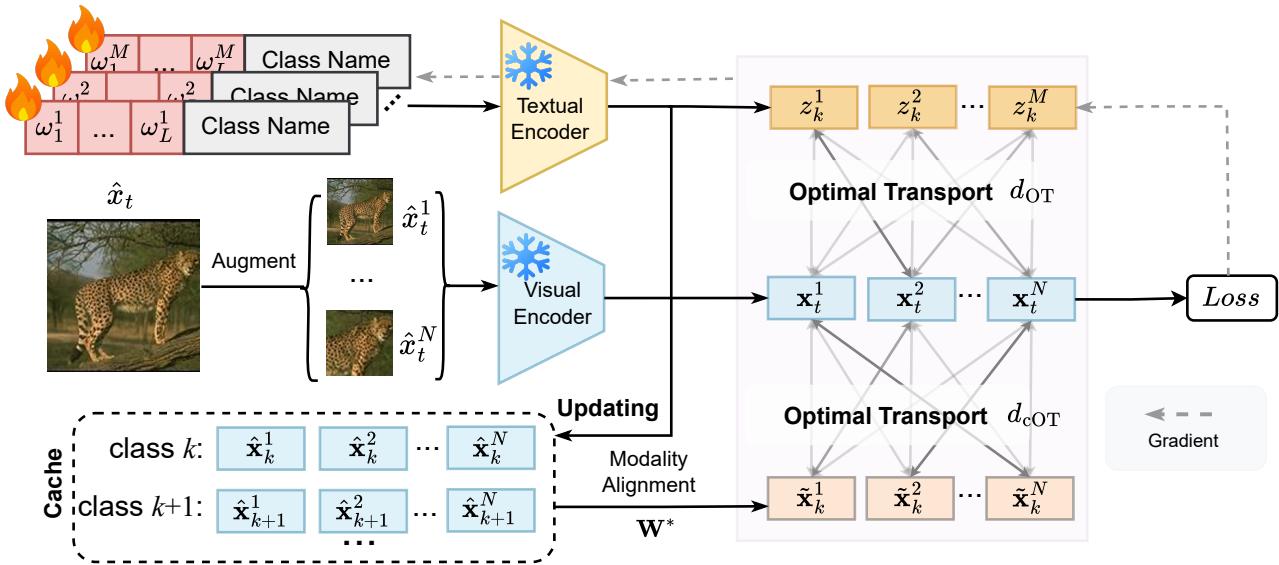
方法:从 similarity search generalization 角度重解释 InfoNCE,而不只停留在 MI/alignment-uniformity
中高相关;详见方法、贡献和实验边界。
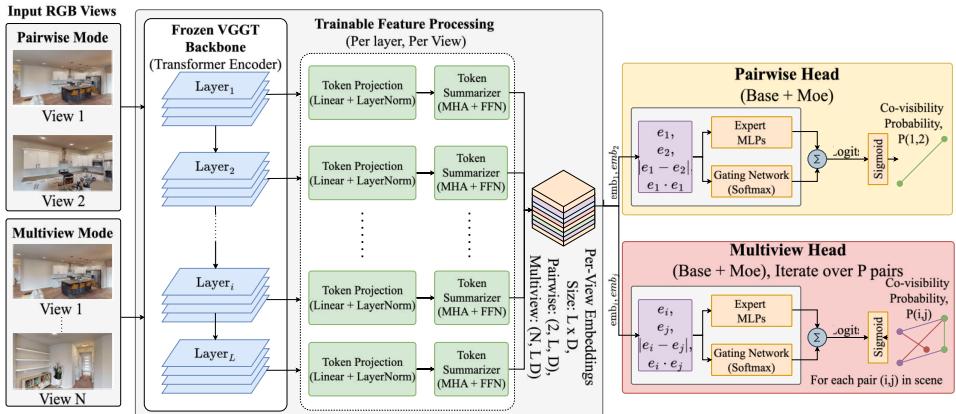
方法:冻结 VGGT 后探测其几何 foundation representation 是否隐式编码 co-visibility
中高相关;详见方法、贡献和实验边界。
方法:测试时用分布级 alignment 强化 CLIP/VLM adversarial robustness,关注预训练视觉-语言表征的脆弱性
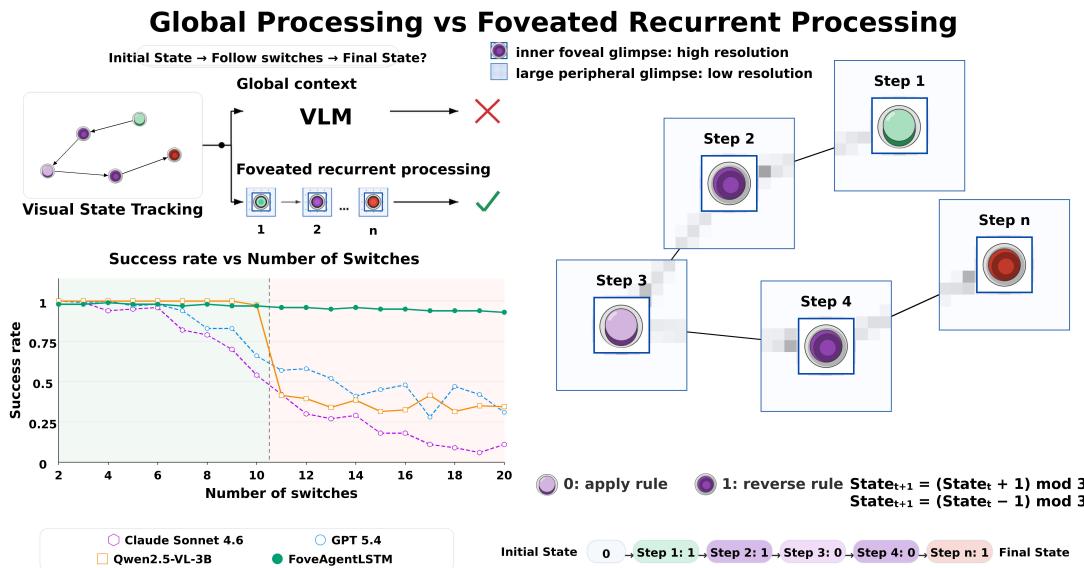
中相关;详见方法、贡献和实验边界。
方法:用局部/顺序视觉策略研究 visual reasoning 的 length generalization,与全局一次性 ViT 的 shortcut 问题相关
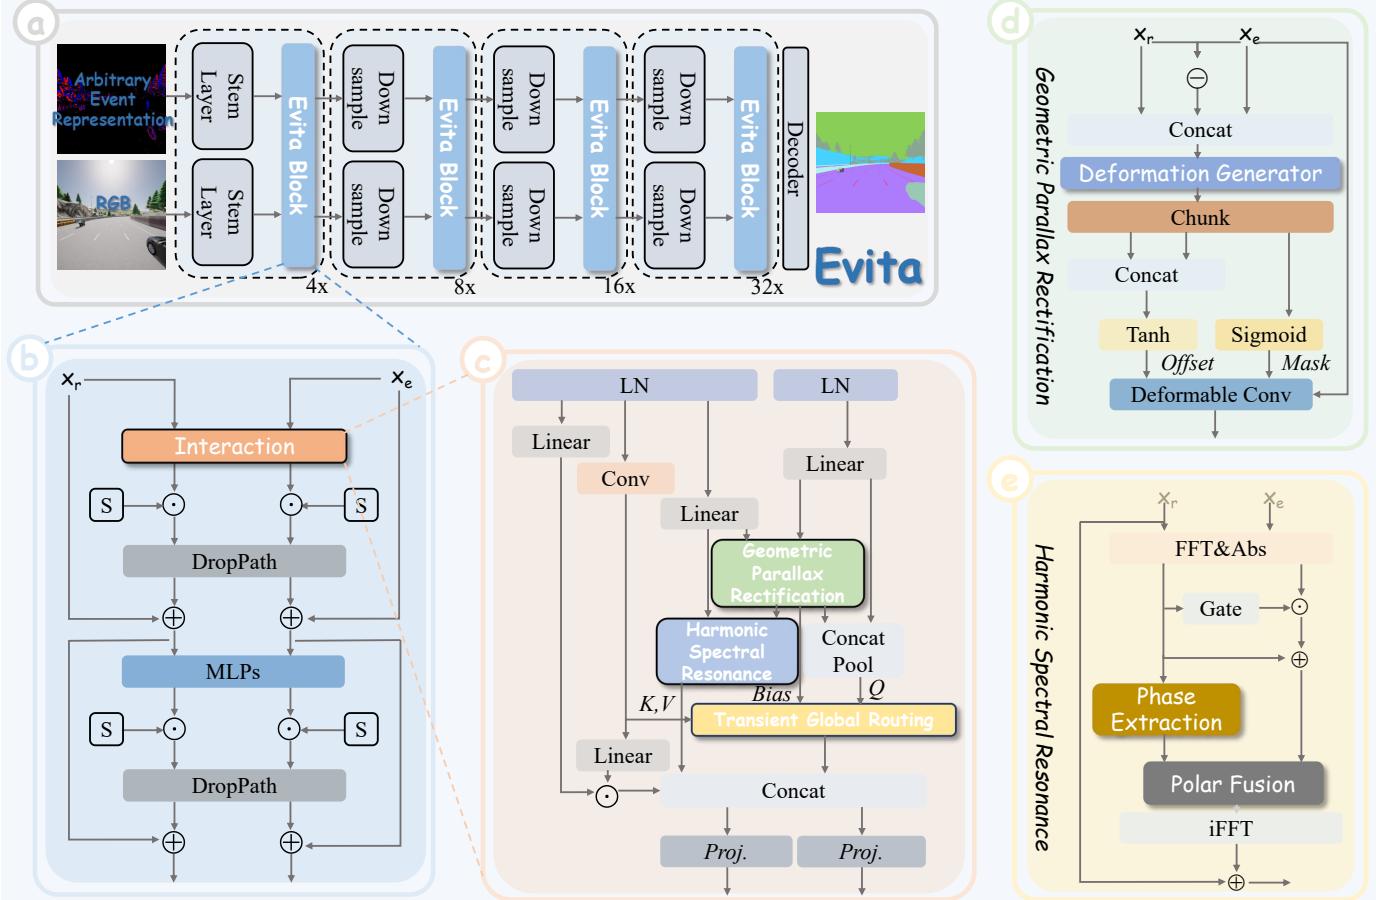
中相关;详见方法、贡献和实验边界。
方法:多模态 RGB-event dense parsing 的统一 backbone 与 stochastic event representation mixing pretraining 有方法迁移价值
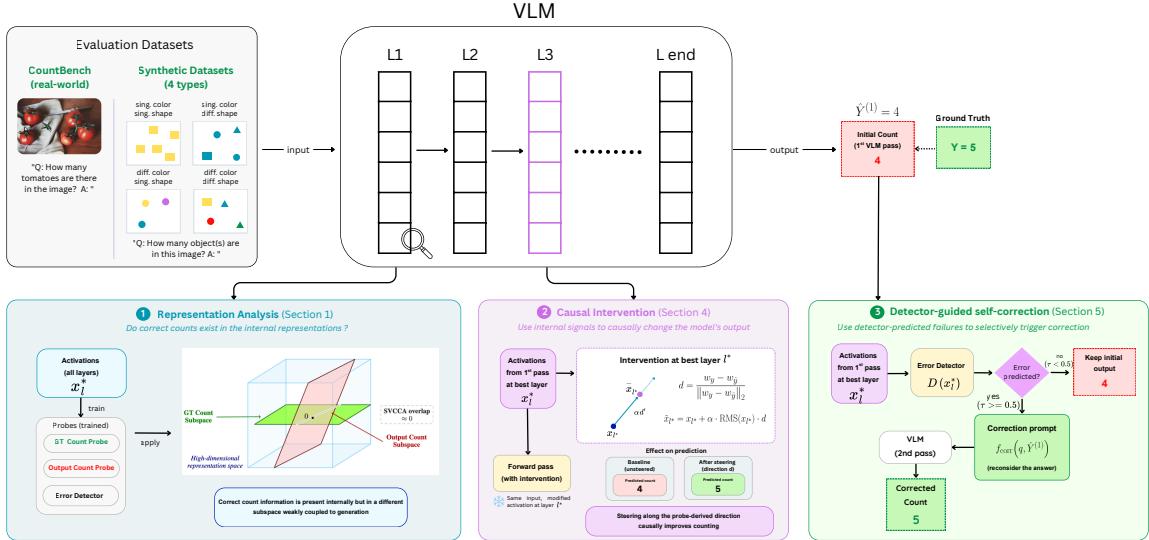
中相关;详见方法、贡献和实验边界。
方法:用 activation probe 证明 VLM 可能内部知道 object count 但输出方向错位
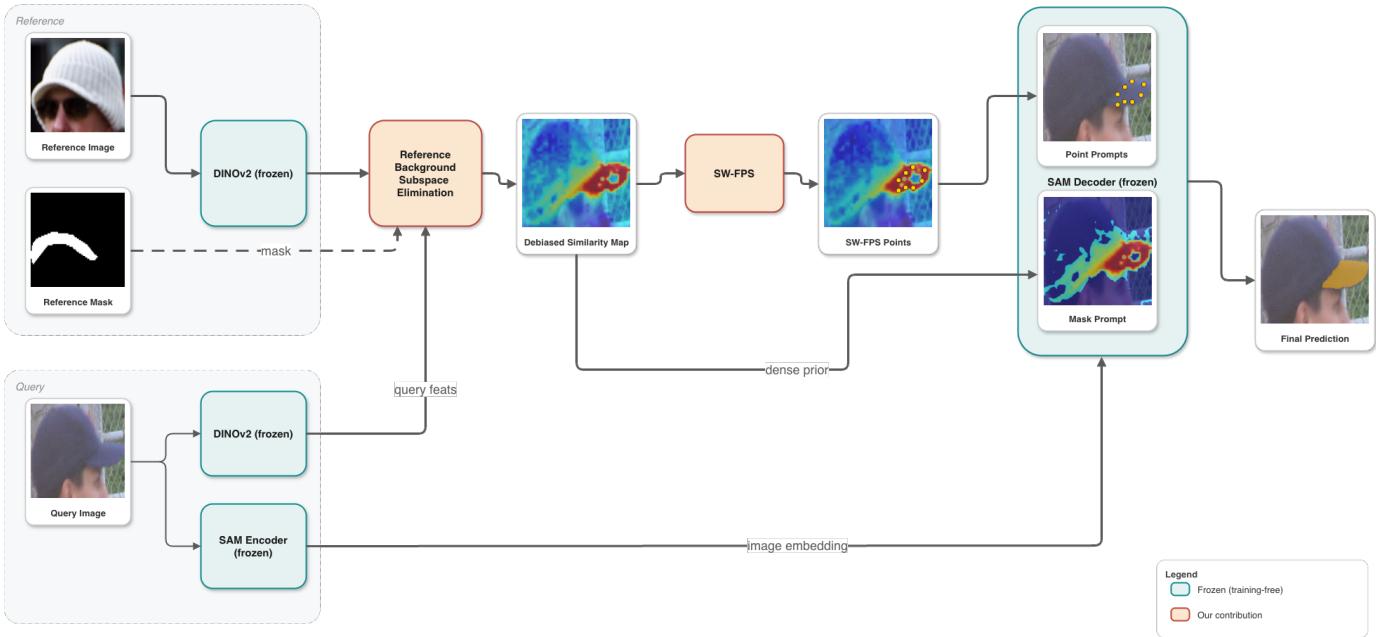
中相关;详见方法、贡献和实验边界。
方法:用 reference-background subspace elimination 清理 VFM cross-image similarity map,偏下游但对特征匹配有启发
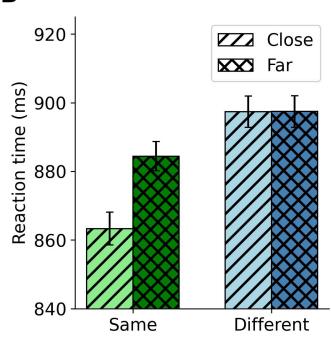
高相关;详见方法、贡献和实验边界。
方法:DINO/self-supervised ViT 的 object-centric patch similarity 能预测人类 object grouping 行为,是今天最贴近通用视觉 SSL 表征机制的复核项
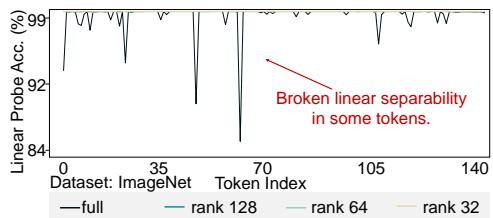
中高相关;详见方法、贡献和实验边界。
方法:低秩 alignment 被用于解释视觉 token 线性可分性如何在 VLM 对齐中保真
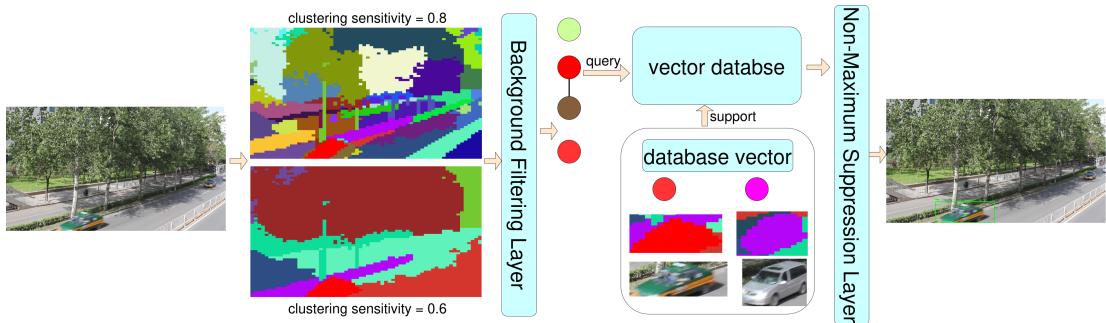
中相关;详见方法、贡献和实验边界。
方法:用 DINOv3 特征聚类成 visual vocabulary,适合作为“冻结表征 + 可扩展记忆”的工程参考
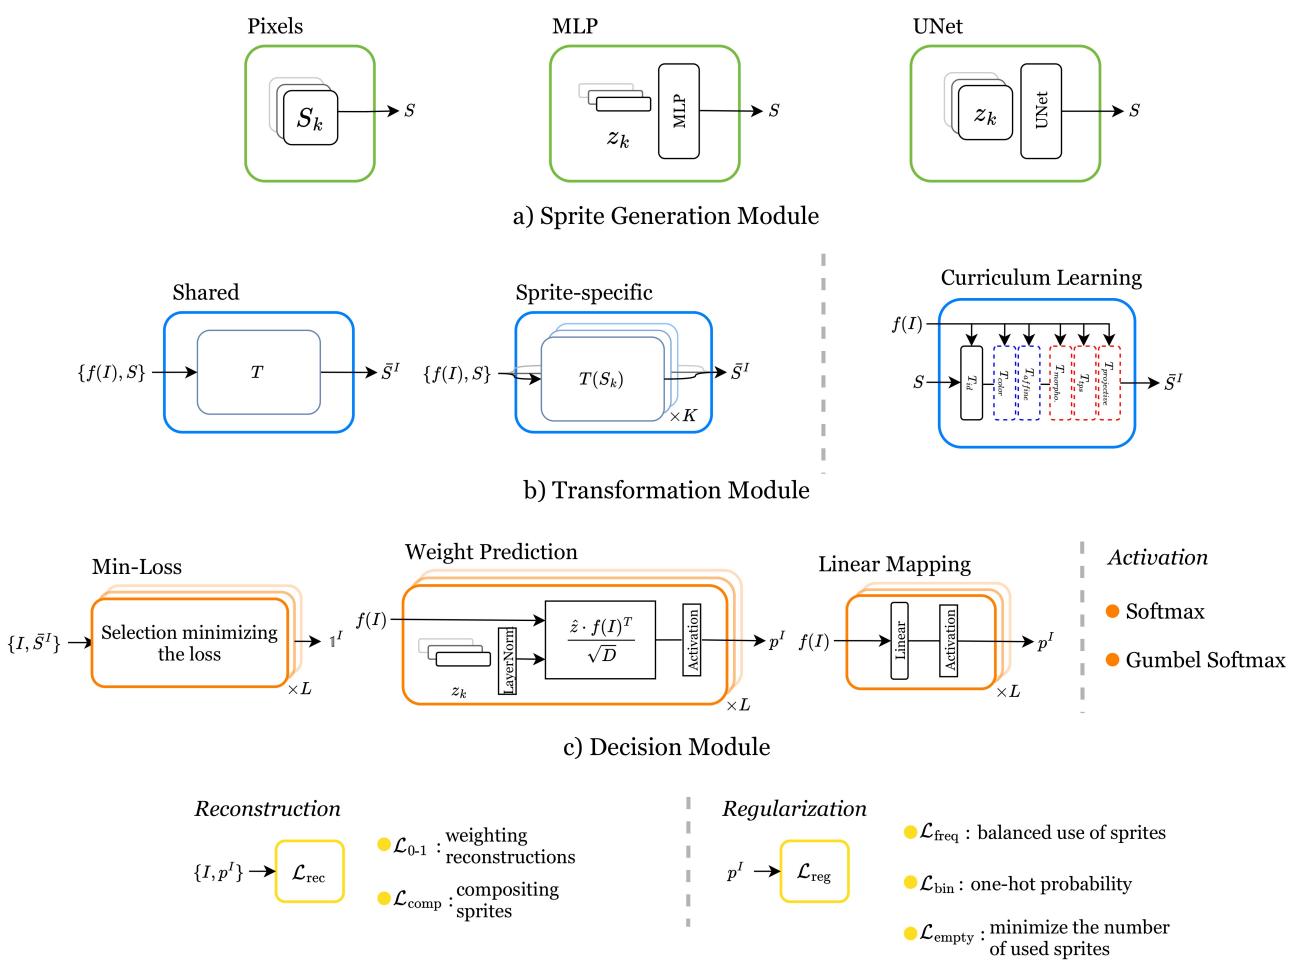
中相关;详见方法、贡献和实验边界。
方法:分析 sprite-based decomposition 并提出可扩展 object-centric 无监督分解,和通用视觉表征可解释性相关
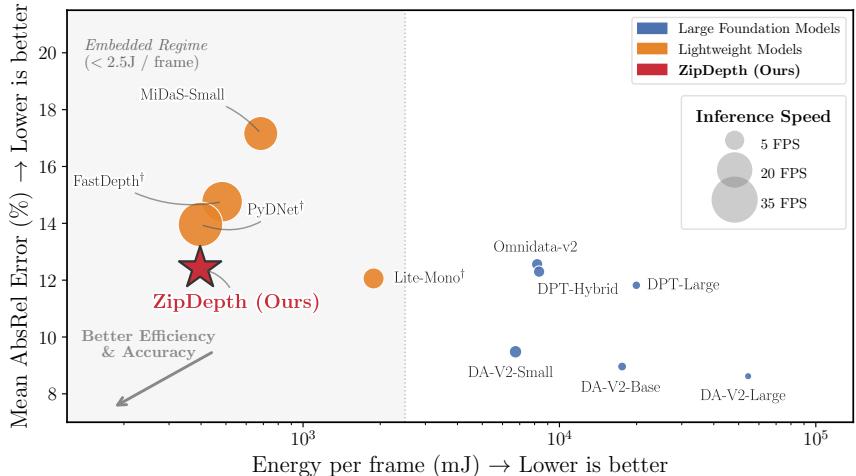
中相关;详见方法、贡献和实验边界。
方法:不是 SSL 主方法,但把大 VFM depth 能力蒸馏到 6.1M 参数模型,适合关注表征压缩与迁移的人扫读
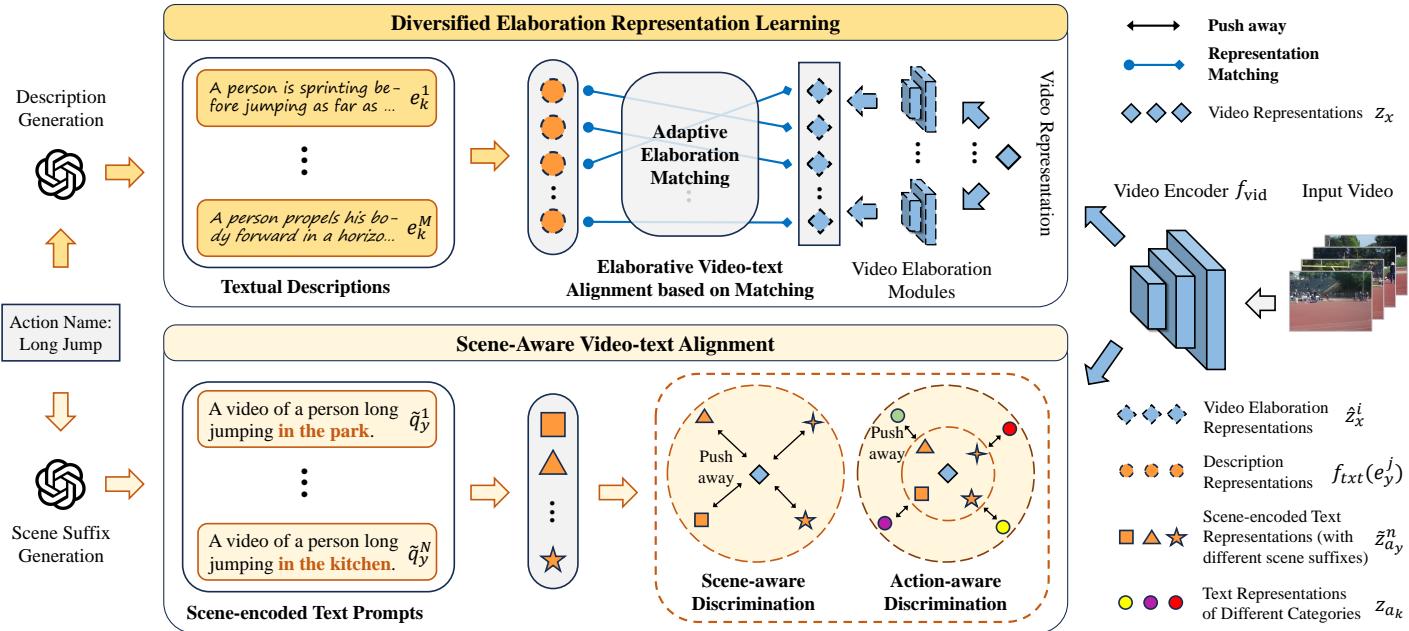
中低相关;详见方法、贡献和实验边界。
方法:旧文状态更新为 TPAMI,关注图文基础模型迁移到跨域视频动作识别的人可扫
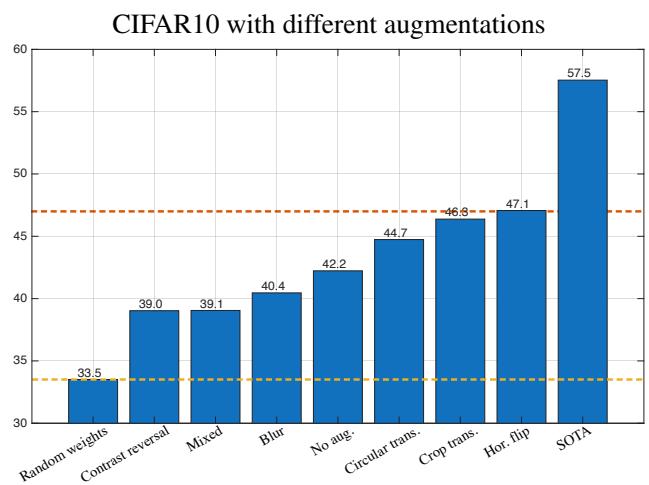
高相关;详见方法、贡献和实验边界。
方法:从自然图像平稳统计和 augmentation 出发解析 contrastive optimum,是今天最基础的视觉 SSL 理论文
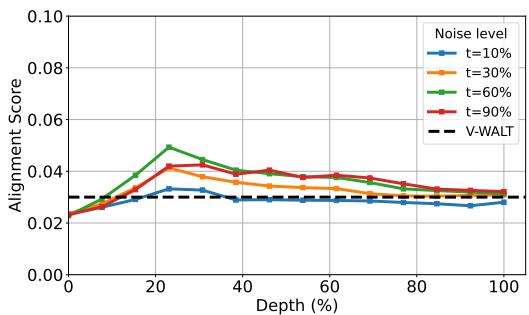
高相关;详见方法、贡献和实验边界。
方法:系统探测视频 diffusion 中间层,并证明单次前向可作为跨任务视频 encoder
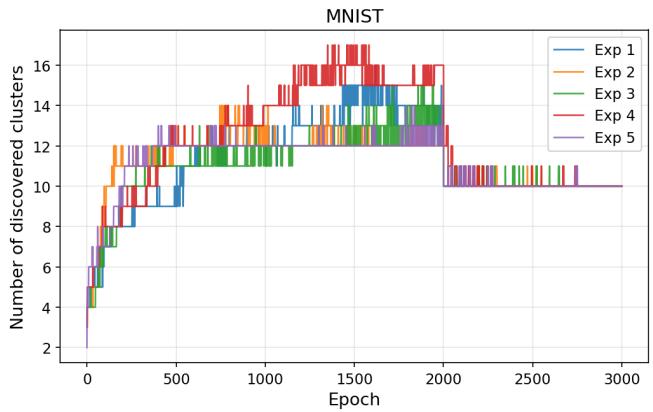
高相关;详见方法、贡献和实验边界。
方法:用 surprise score + evolution strategy 替代常规 per-step SSL loss,直接瞄准无类别数先验的图像聚类
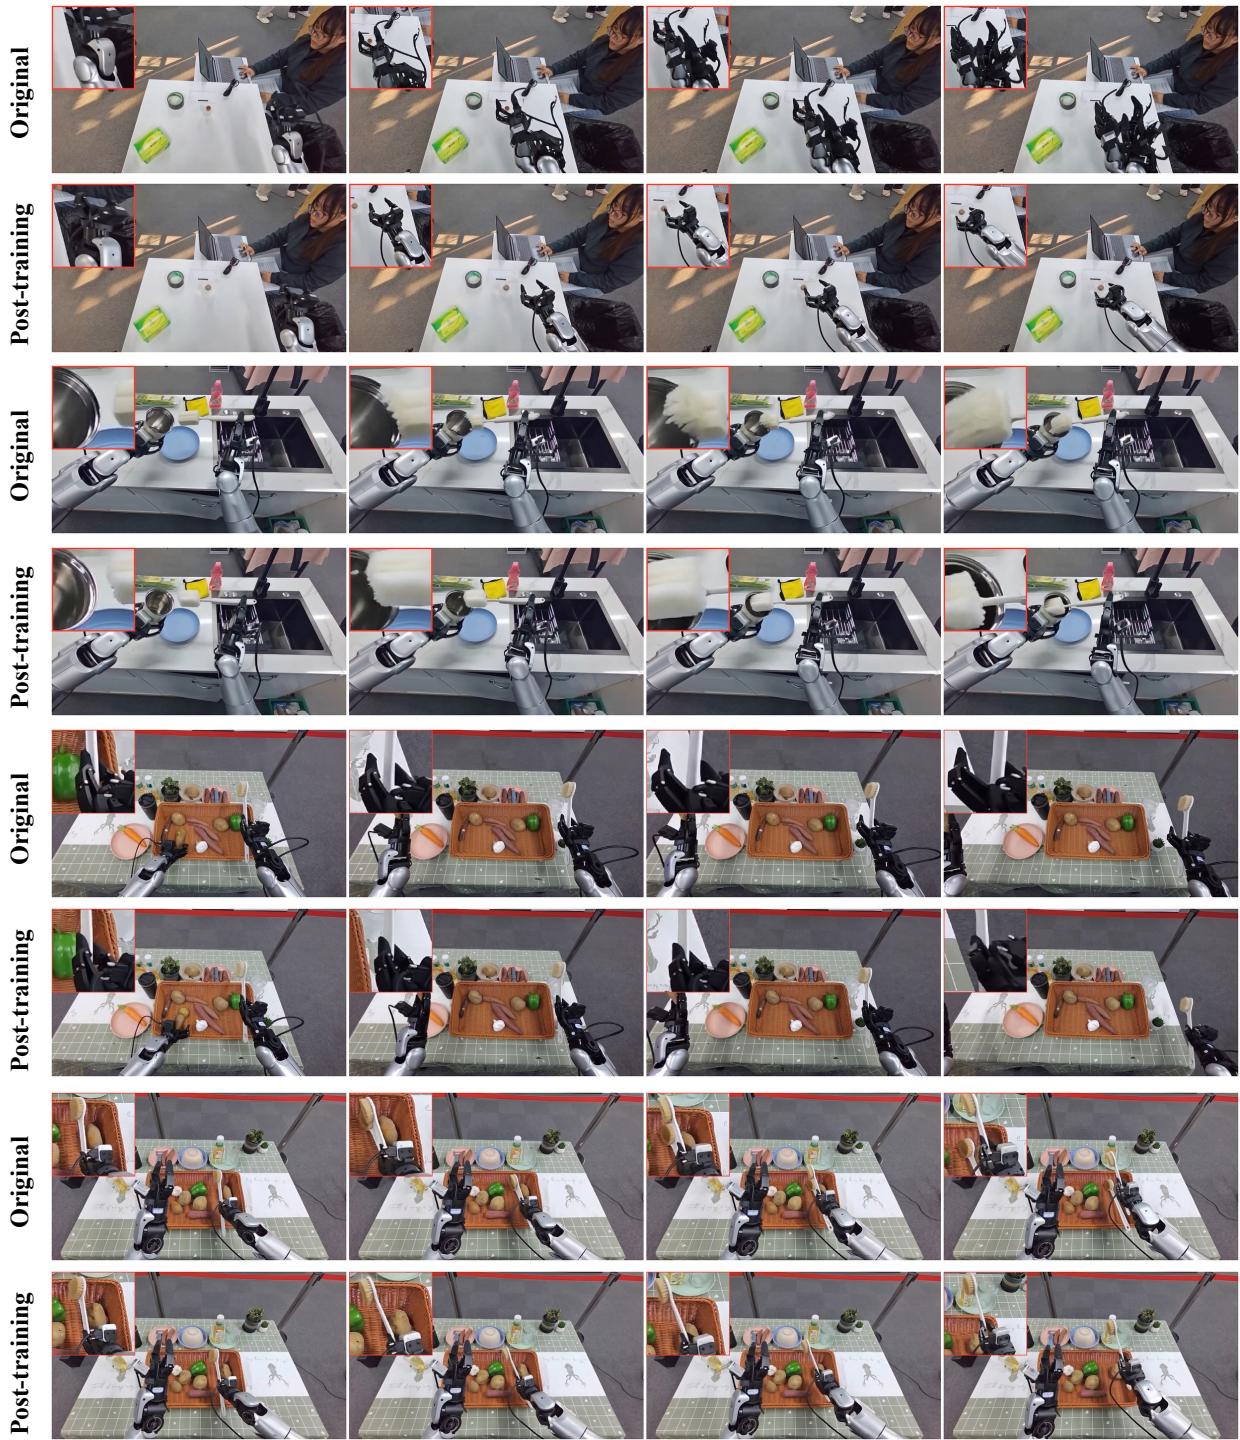
中高相关;详见方法、贡献和实验边界。
方法:虽然面向 embodied intelligence,但训练的是开源 MoE 视频基础模型,数据和架构对通用视频预训练有参考价值
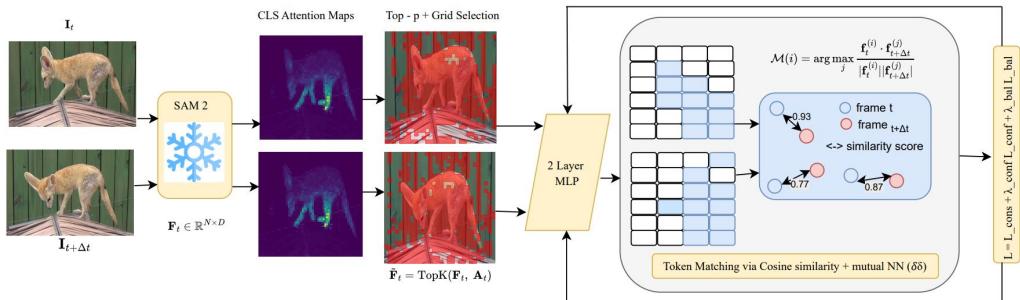
中高相关;详见方法、贡献和实验边界。
方法:用 attention-guided token selection 与 cross-temporal clustering 学 part-aware video representations
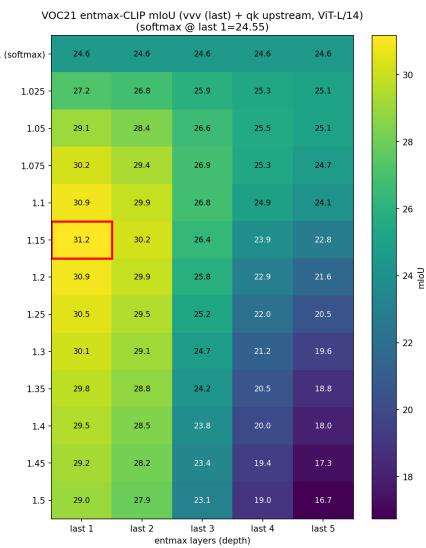
中高相关;详见方法、贡献和实验边界。
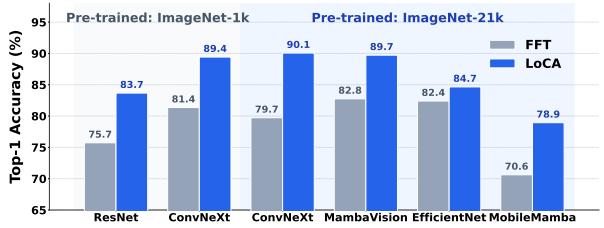
方法:训练后替换 CLIP final attention 为 sparse entmax,直接改善 dense open-vocabulary prediction 的空间证据
中高相关;详见方法、贡献和实验边界。
方法:关注 VFM adaptation 时如何保留预训练空间先验,对 frozen/self-supervised backbone 下游使用很实用
中高相关;详见方法、贡献和实验边界。
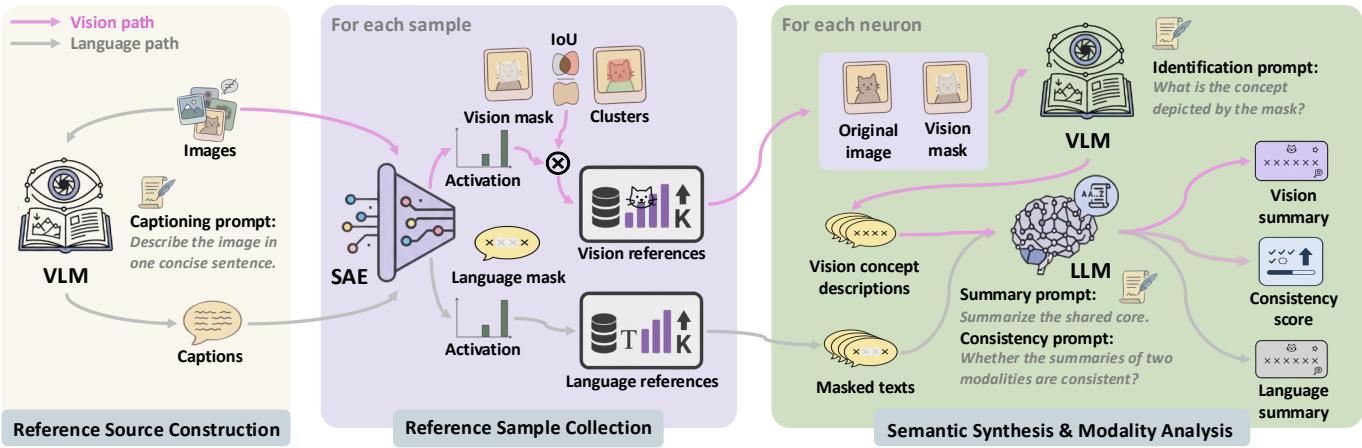
方法:说明低秩 alignment 能保留视觉 token 线性可分性,适合理解 VLM 对视觉表征的破坏/保真
中相关;详见方法、贡献和实验边界。
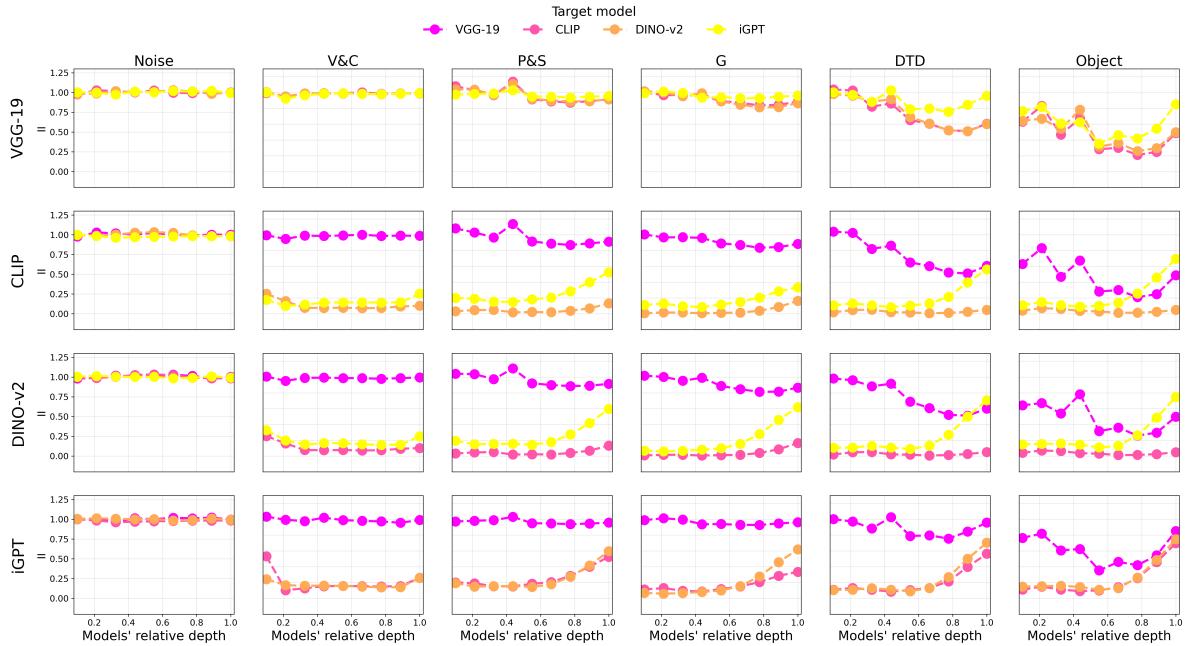
方法:用结构稀疏约束让 SAE 在视觉-语言模态间学更一致的概念,偏诊断但表征相关
中相关;详见方法、贡献和实验边界。
方法:比较 CNN、ViT 和人类纹理表征,对“通用视觉表征到底捕获什么”有解释价值
中相关;详见方法、贡献和实验边界。
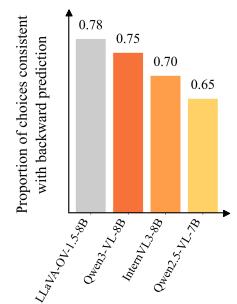
方法:通过无标签 backward prediction 增强 VLM reasoning,属于视觉-语言自监督式训练信号
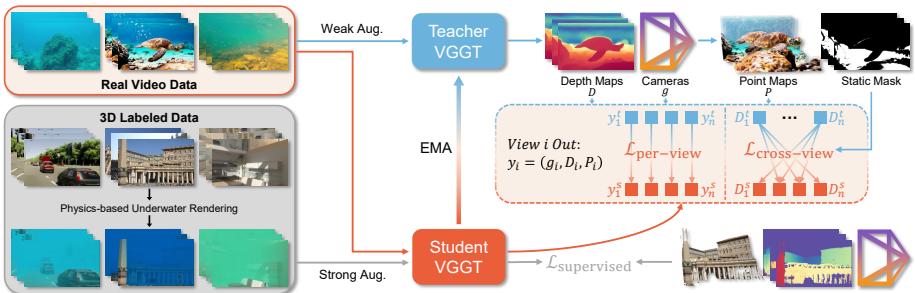
中相关;详见方法、贡献和实验边界。
方法:任务垂直但方法是无标注视频 + teacher-student + cross-view consistency,可迁移到 3D geometry SSL
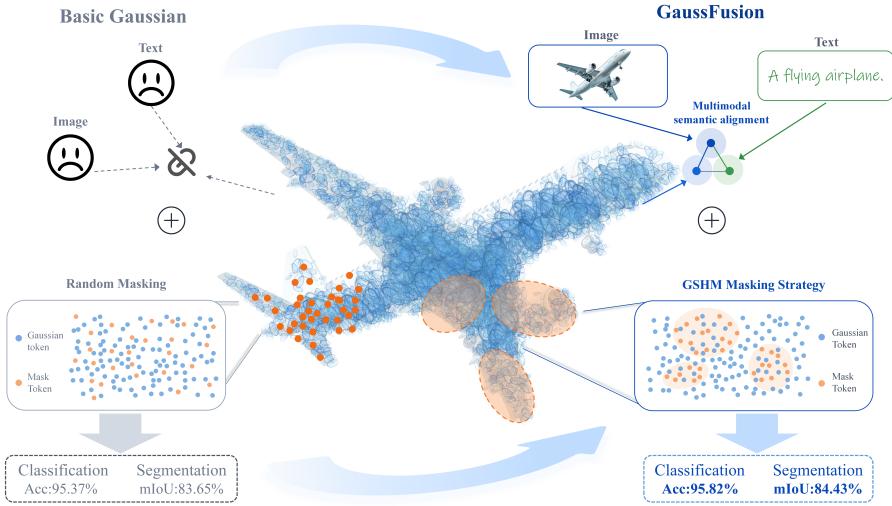
高相关;详见方法、贡献和实验边界。
方法:把 masked Gaussian modeling 与图文语义对齐合并,是今天最直接的通用 3D/视觉表征预训练论文
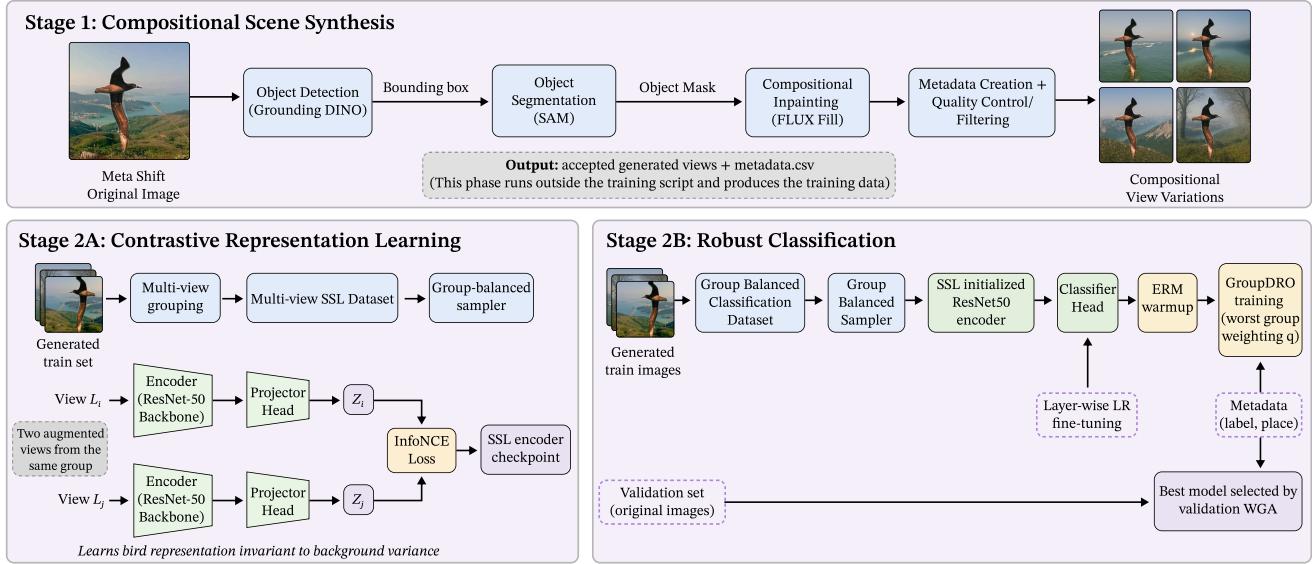
高相关;详见方法、贡献和实验边界。
方法:把生成式 counterfactual 当作正样本构造,直接训练背景不变的 object-centric 表征
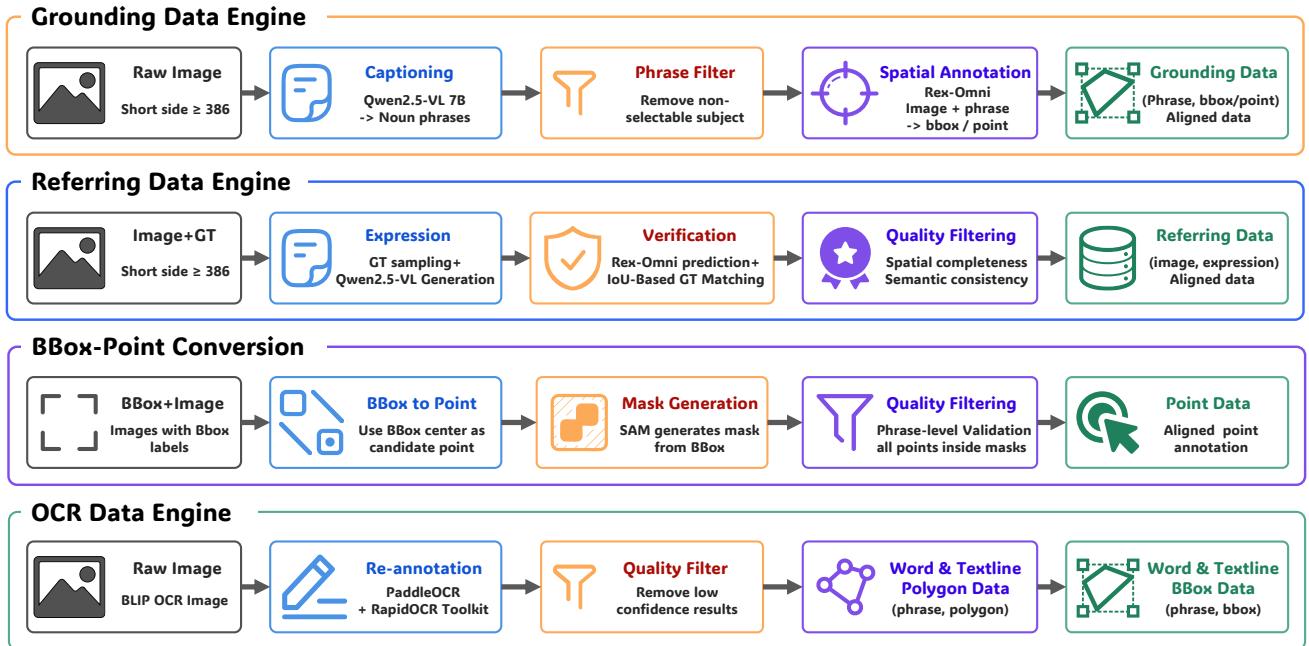
中高相关;详见方法、贡献和实验边界。
方法:把多种视觉任务统一成文本/图像生成接口,展示通用 VFM 可以不靠专用 head 覆盖 dense 与 symbolic tasks
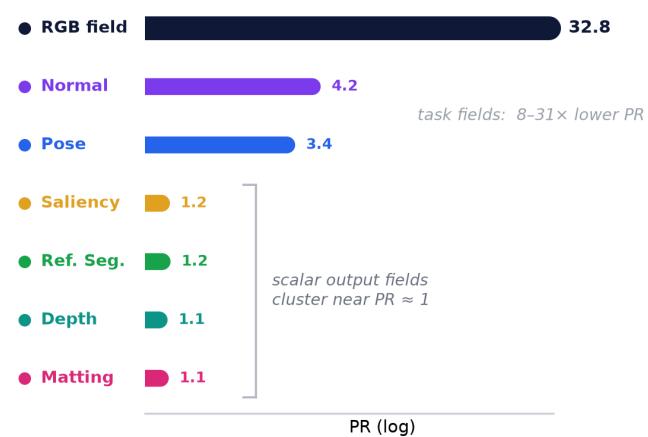
中高相关;详见方法、贡献和实验边界。
方法:直接讨论如何从文本到图像生成预训练中读出 dense fields,关系到生成式 VFM 的空间表征可用性
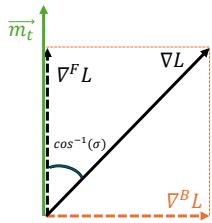
中高相关;详见方法、贡献和实验边界。
方法:不是 SSL 目标,但直接影响 CLIP/VLM prompt tuning 的泛化,且 comments 标注 ECCV 主会
中高相关;详见方法、贡献和实验边界。
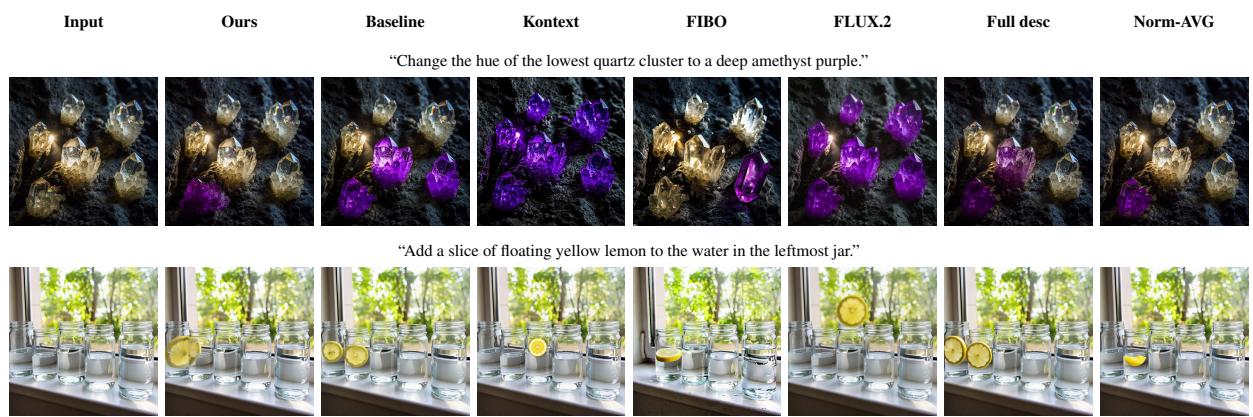
方法:诊断 VLM 作为 condition encoder 时空间信号是否真正被读出,有助于理解视觉表征在生成编辑管线中的丢失
中高相关;详见方法、贡献和实验边界。
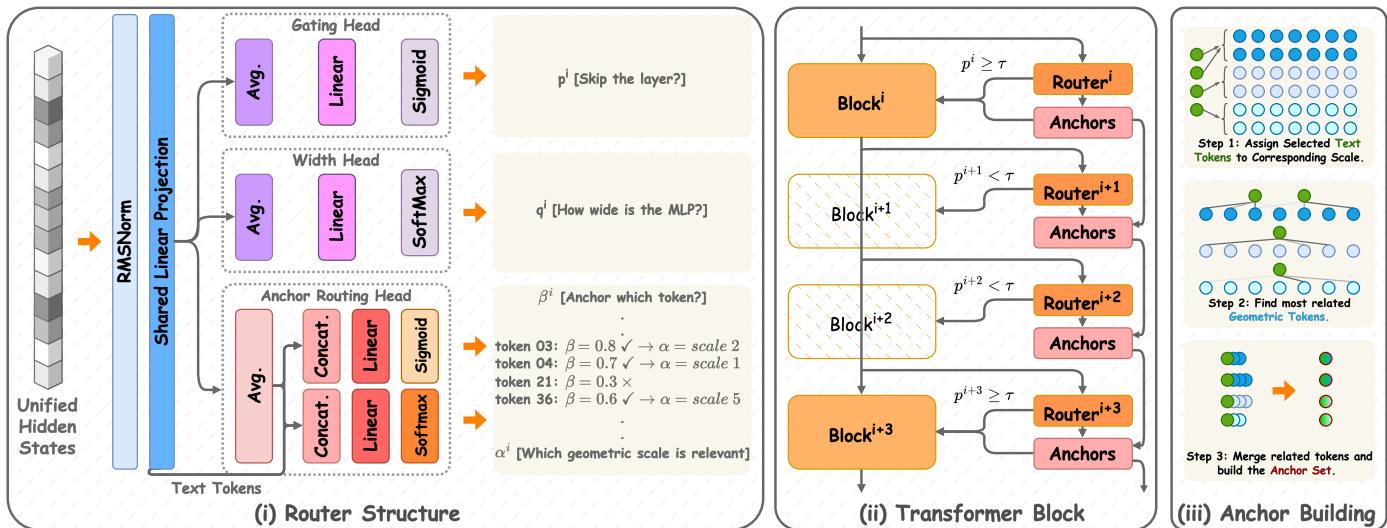
方法:通过 scale-aware 3D tokenizer 和 anchor tokens 组织文本-3D 对齐,适合作为 3D VFM/VLM 接口参考
中相关;详见方法、贡献和实验边界。
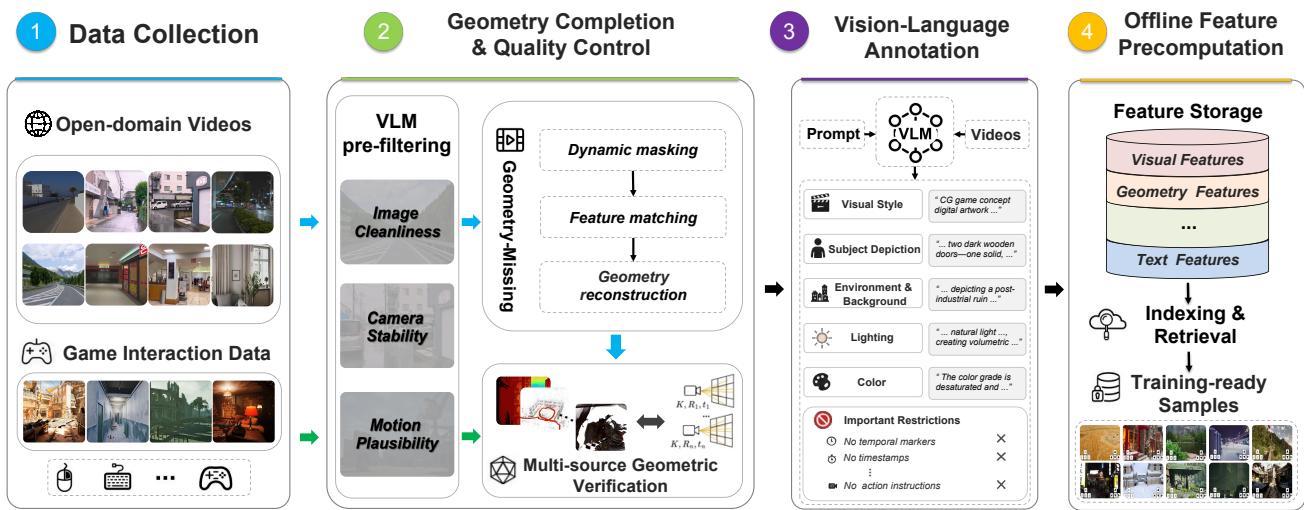
方法:强调 world model 的数据引擎、cross-frame pretraining 和 distillation,方法可迁移但应用偏生成/交互
中相关;详见方法、贡献和实验边界。
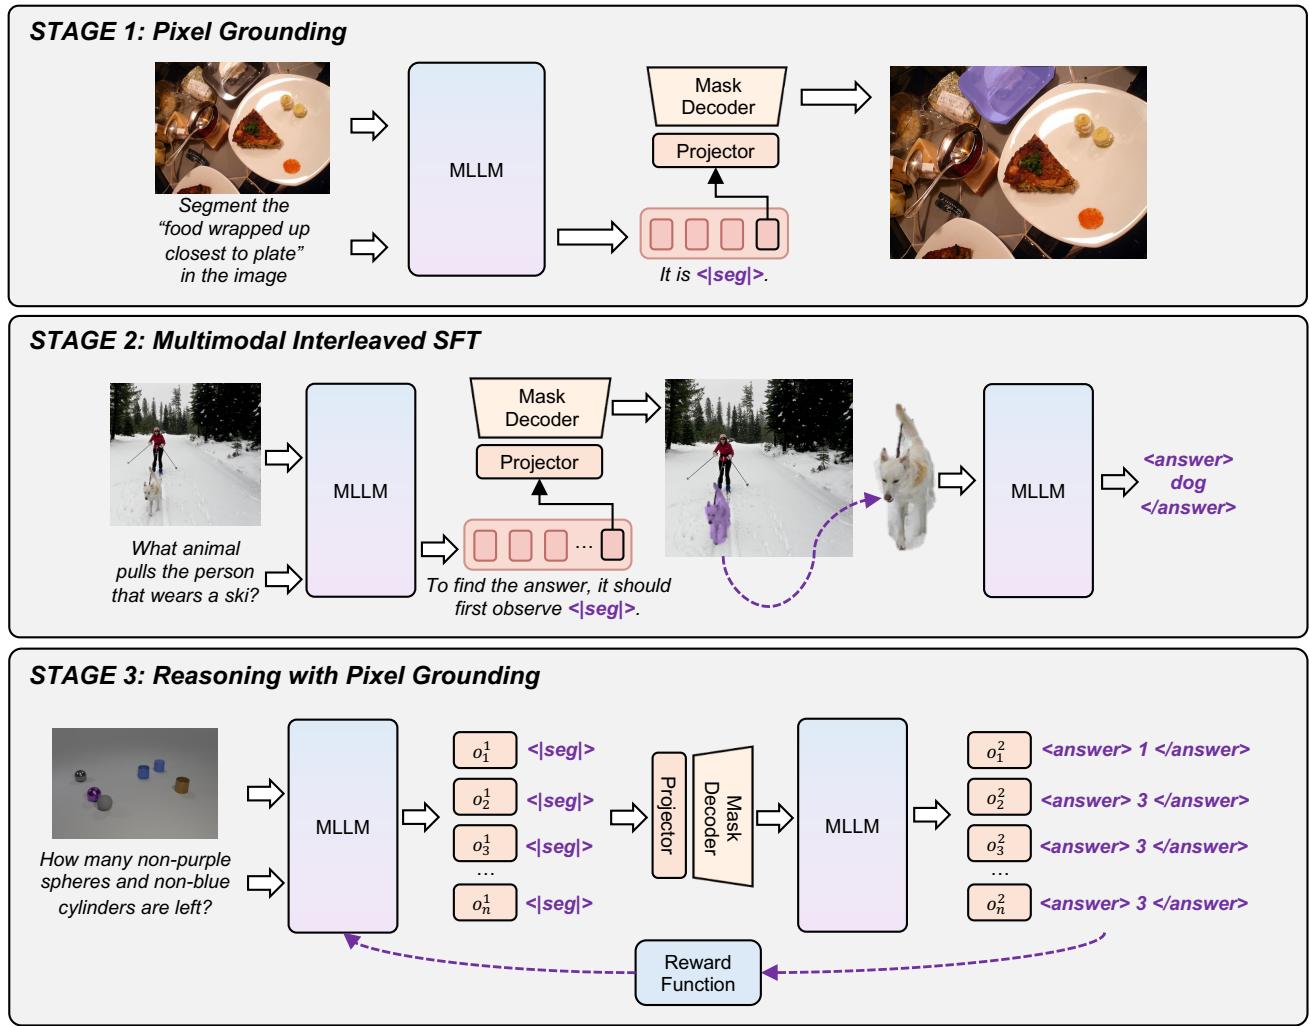
方法:把 MLLM 的 zoom-in 单位从 box 换成 mask,并讨论 segmentation patches 与 visual tokens 的对齐
中相关;详见方法、贡献和实验边界。
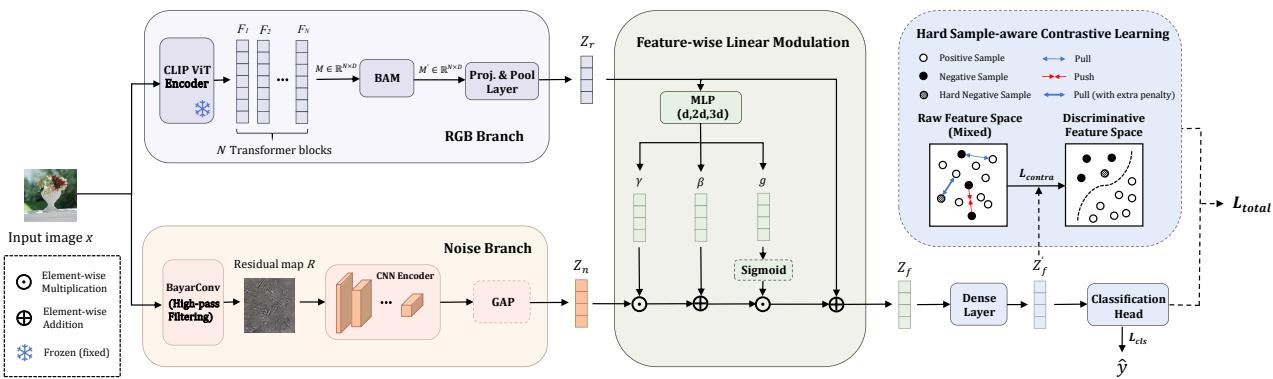
方法:任务是生成图像取证,但 RGB-Noise 双分支和 hard-sample contrastive 对鲁棒表征有参考价值
中低相关;详见方法、贡献和实验边界。
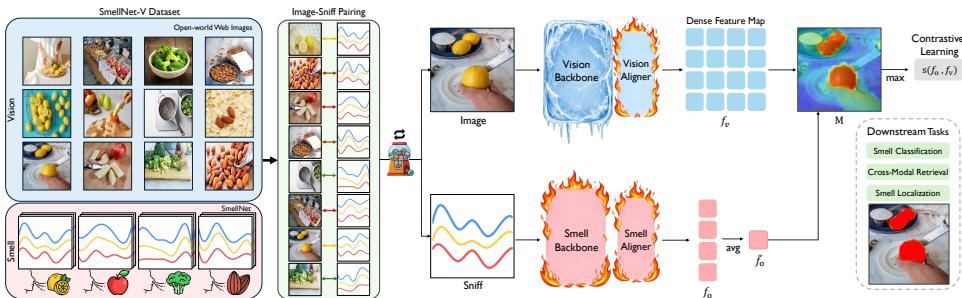
方法:ECCV 状态明确,但核心是气味/电子鼻跨模态学习,和通用视觉自监督只弱相关
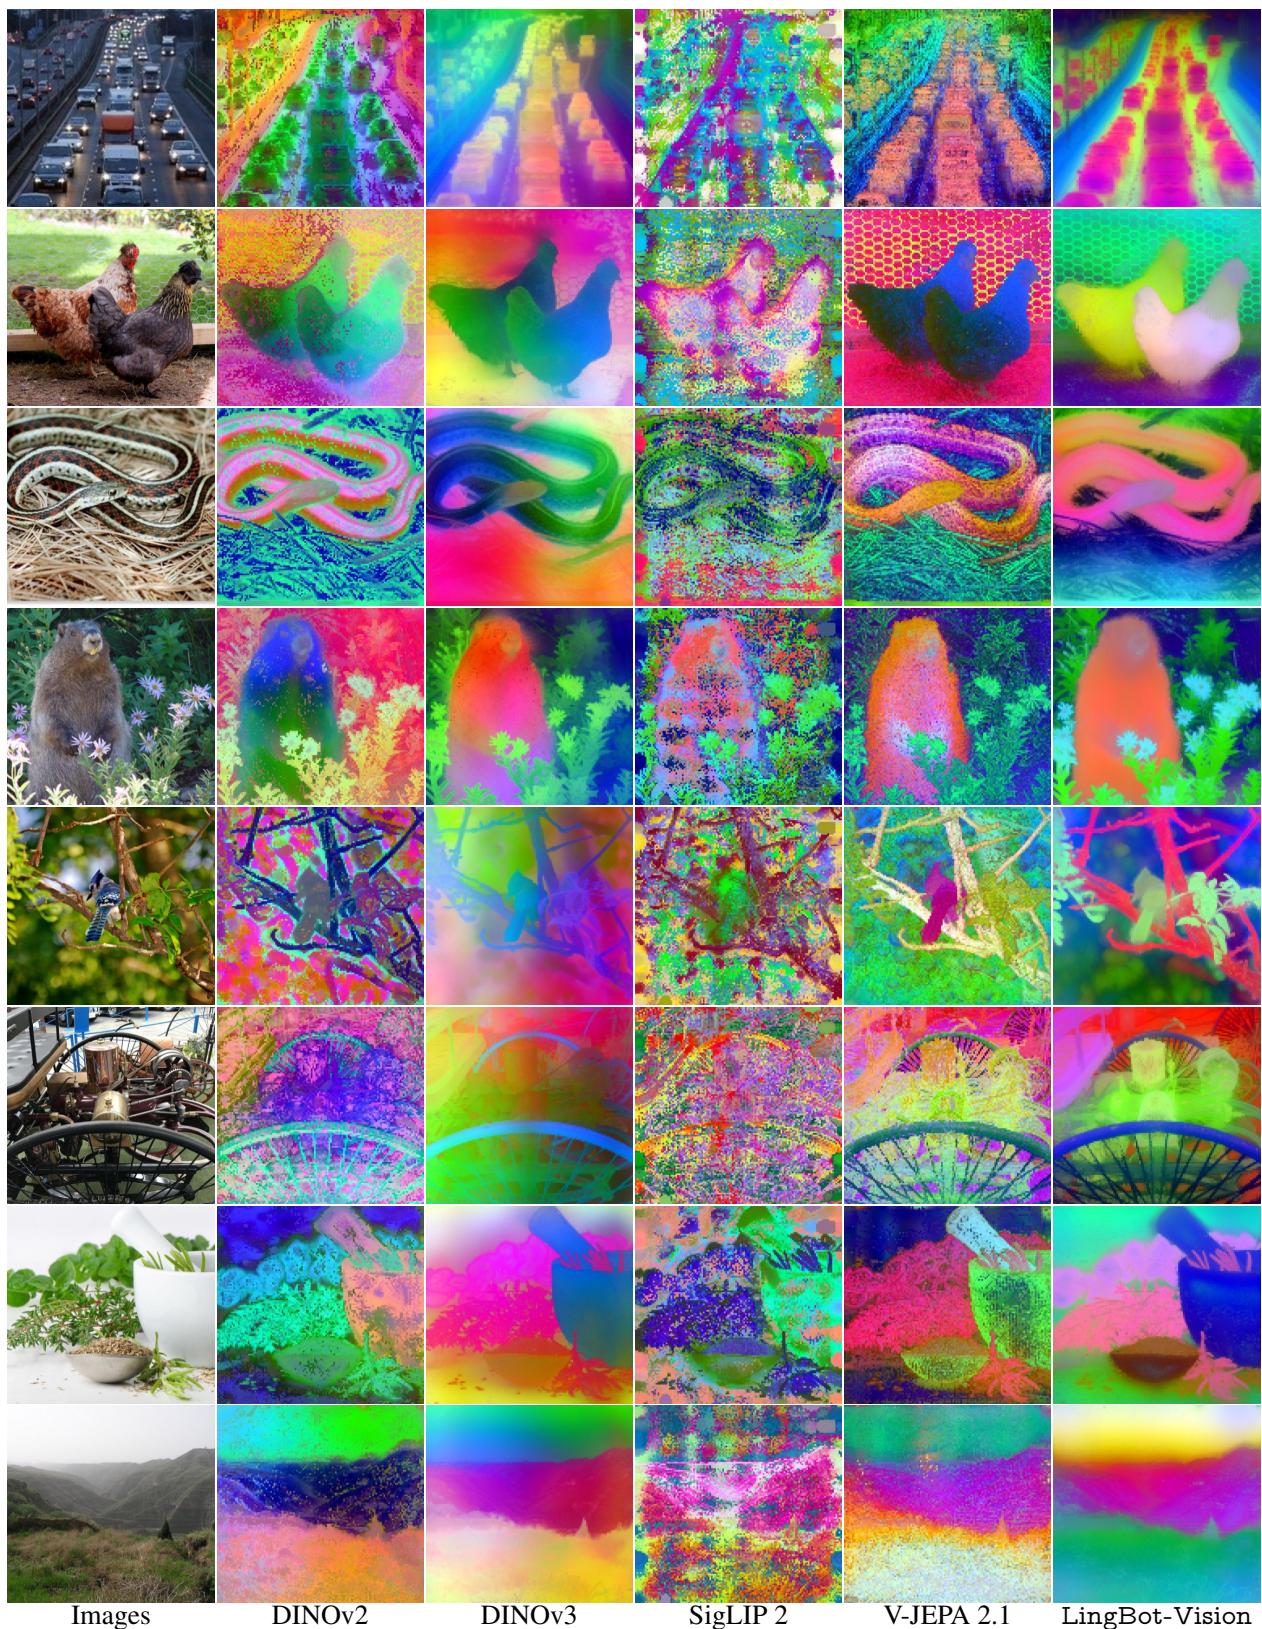
高相关;详见方法、贡献和实验边界。
方法:直接提出面向 dense geometry 的自监督预训练目标,弥补语义 VFM 对边界/形状结构不敏感的问题
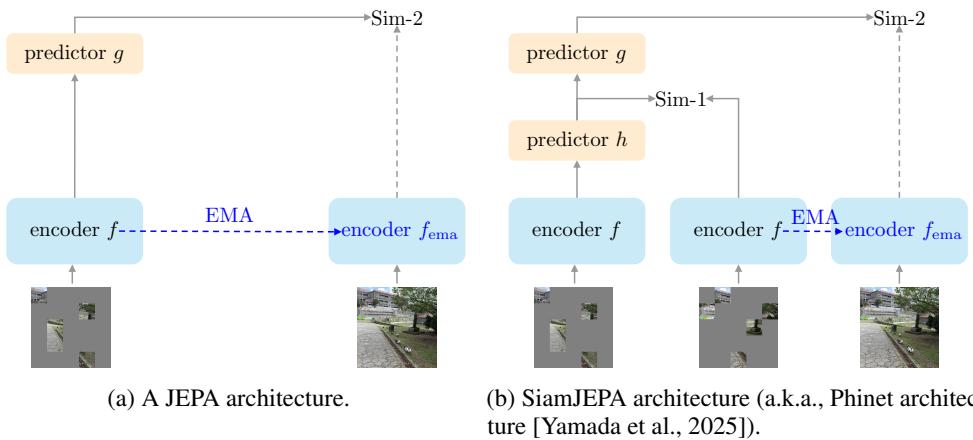
高相关;详见方法、贡献和实验边界。
方法:研究 Siamese student encoder 对 JEPA 的正则化和早期学习收益,是今天最直接的 JEPA 目标改造论文
高相关;详见方法、贡献和实验边界。
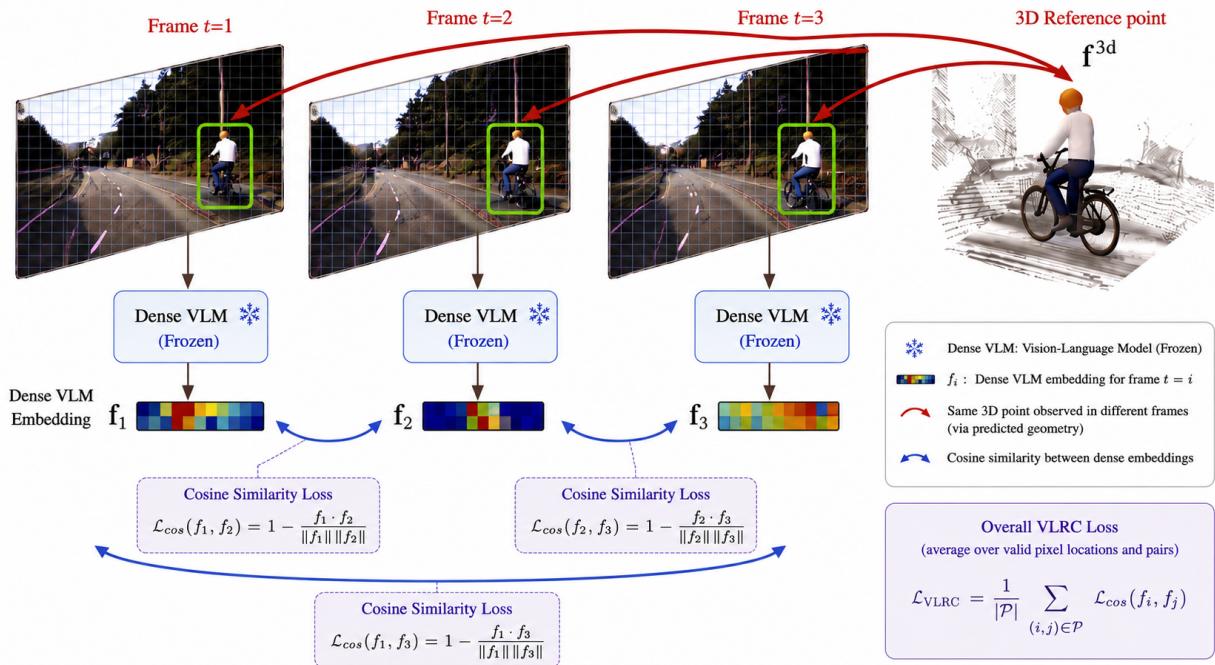
方法:用 frozen vision-language representations 作为多视角一致性信号,为无 3D 标注的 feed-forward 3D 预训练提供可扩展监督
高相关;详见方法、贡献和实验边界。
方法:把 caption 视为不完备约束,显式分离 consensus semantic core 和 unsaid residual,改进 CLIP 式对齐鲁棒性
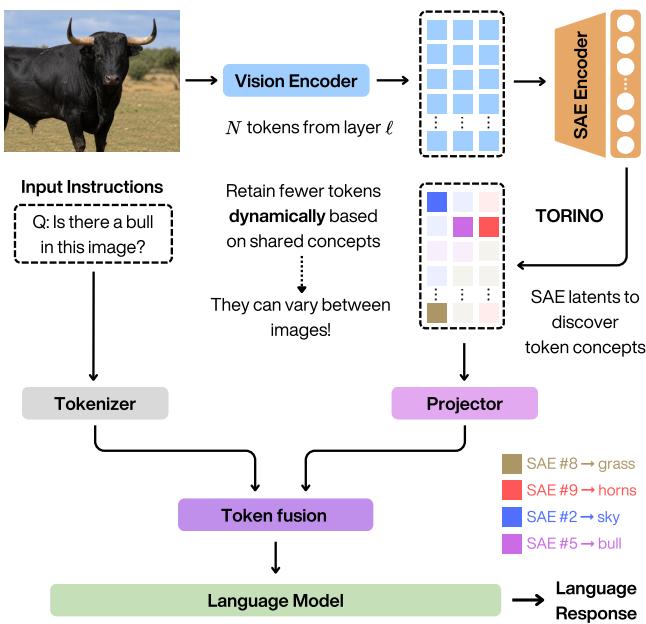
中高相关;详见方法、贡献和实验边界。
方法:用 sparse autoencoder concept overlap 做可解释 token pruning/merging,关注减少 token 同时保留语义证据
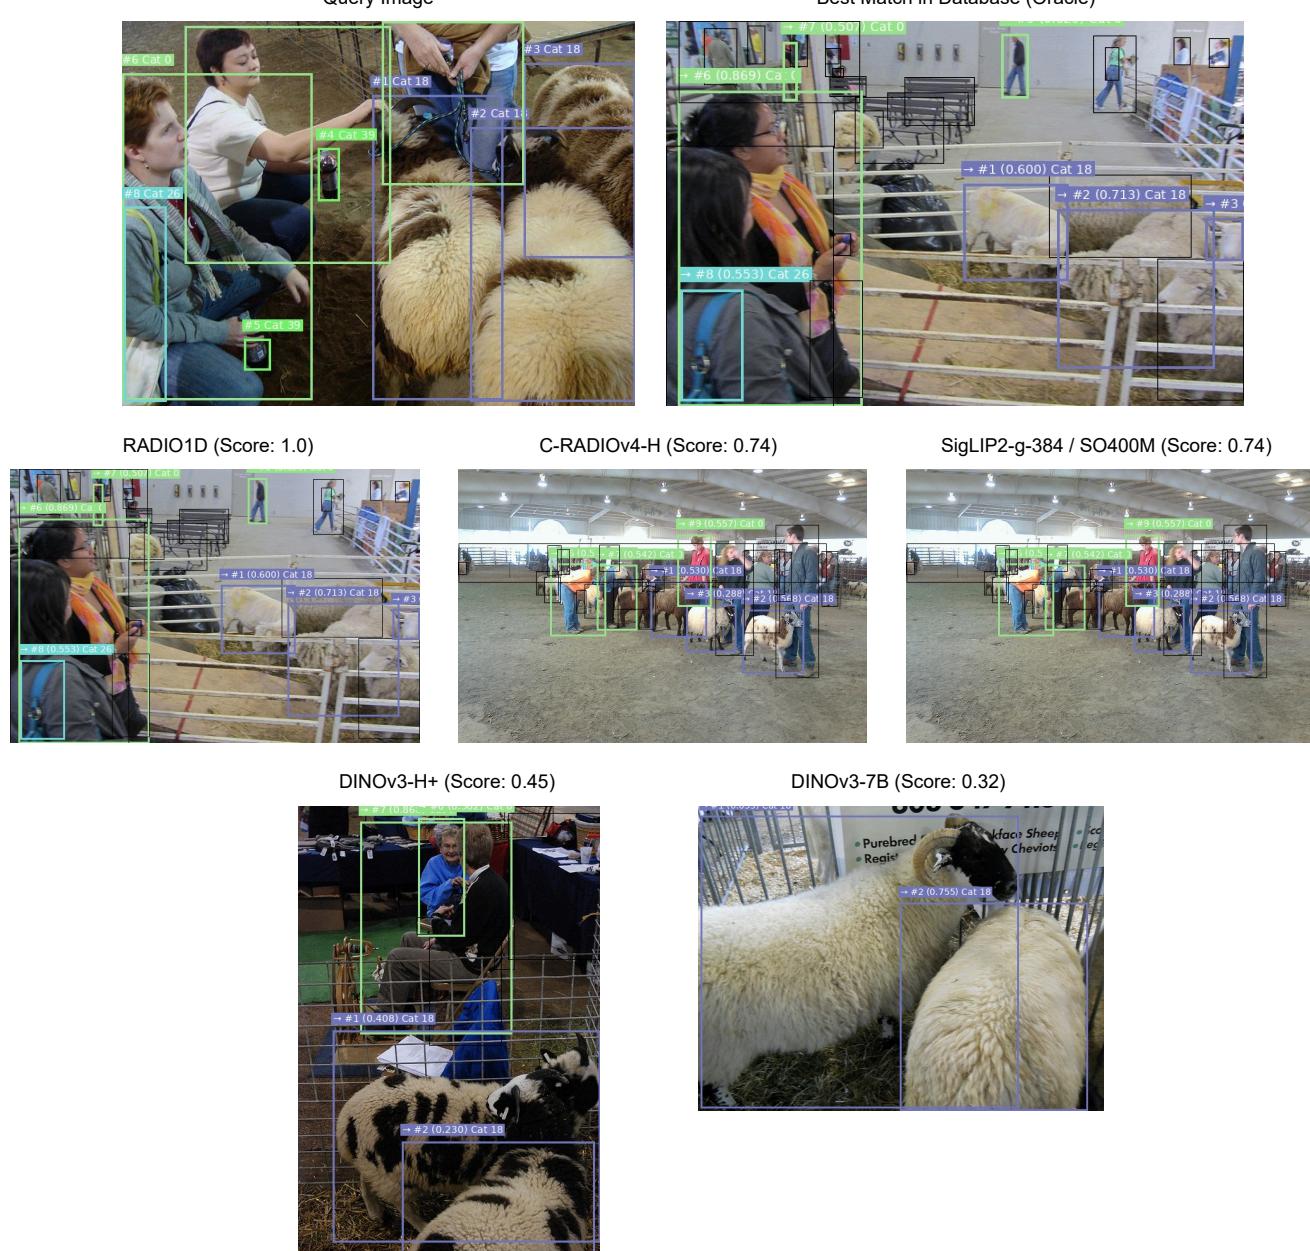
中高相关;详见方法、贡献和实验边界。
方法:挑战固定 2D patch feature 假设,用多教师蒸馏和 autoencoder 生成可变长度 1D 视觉表示
中高相关;详见方法、贡献和实验边界。
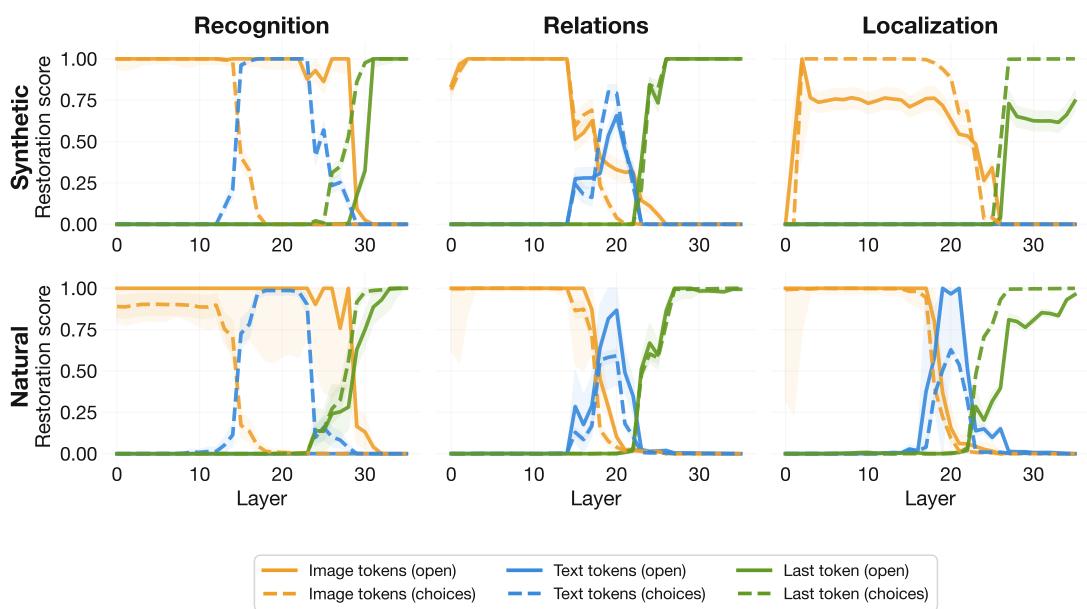
方法:通过 causal patching 区分 direct visual pathway 与 text-mediated pathway,有助于判断 VLM 是否真正读出视觉 token
中高相关;详见方法、贡献和实验边界。
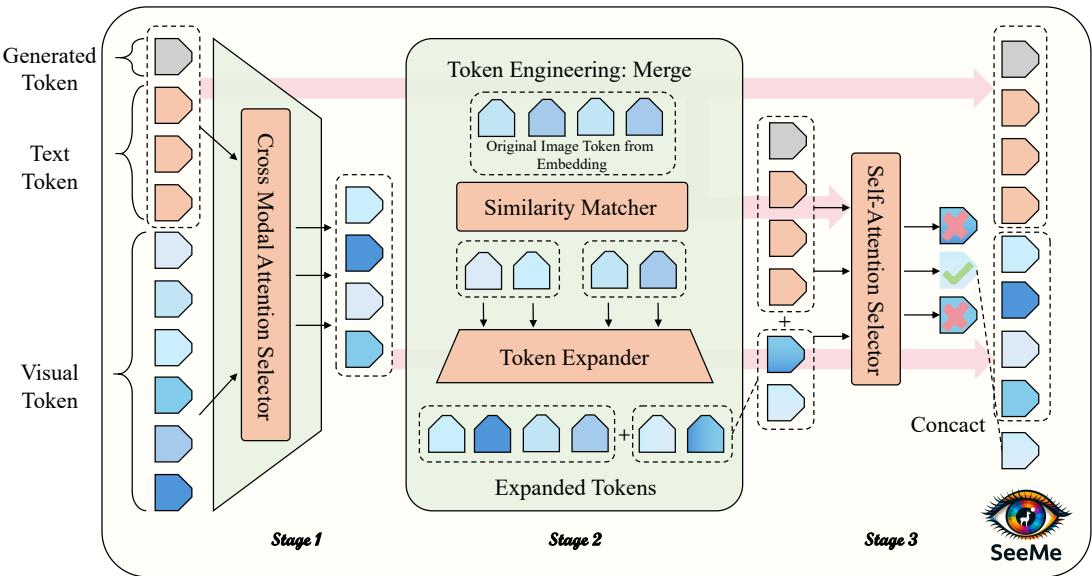
方法:把 hallucination 根源部分定位到 irrelevant/noisy visual tokens,并提出无需训练的三阶段 token 重构
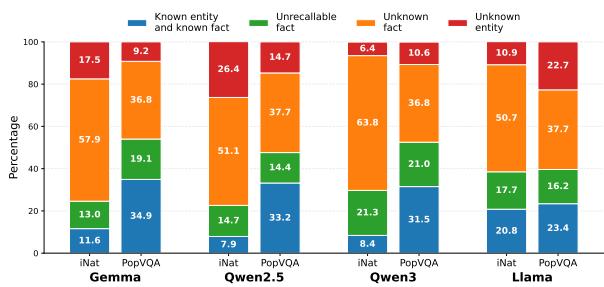
中高相关;详见方法、贡献和实验边界。
方法:用 pre-generation visual-token/hidden-state signals 区分视觉识别失败和知识检索失败,适合做 VLM 诊断工具
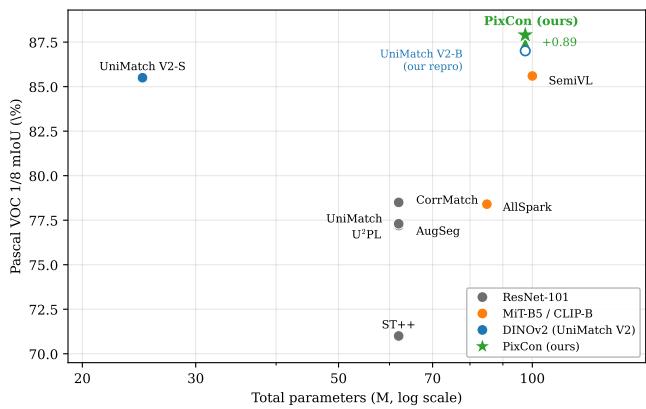
中相关;详见方法、贡献和实验边界。
方法:不是预训练论文,但给出 DINOv2 teacher 下 clean-positive pixel contrast 的低成本表征塑形方案
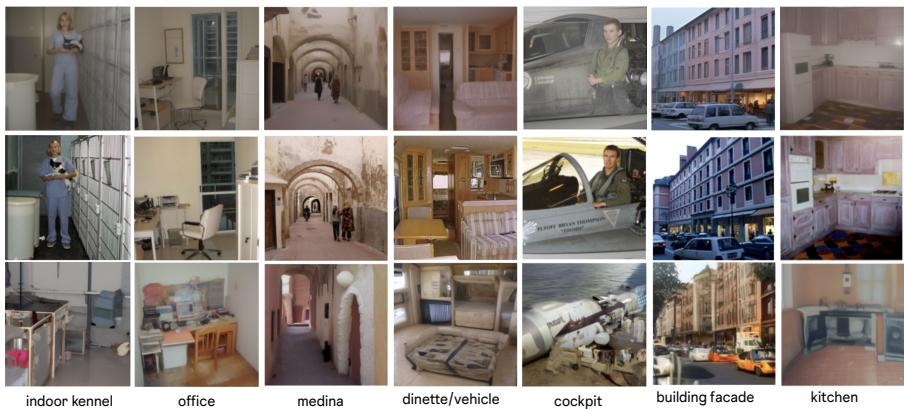
中相关;详见方法、贡献和实验边界。
方法:从生成式反演攻击角度约束 CLIP/视觉特征,提醒通用表征要同时考虑可用性和隐私泄漏
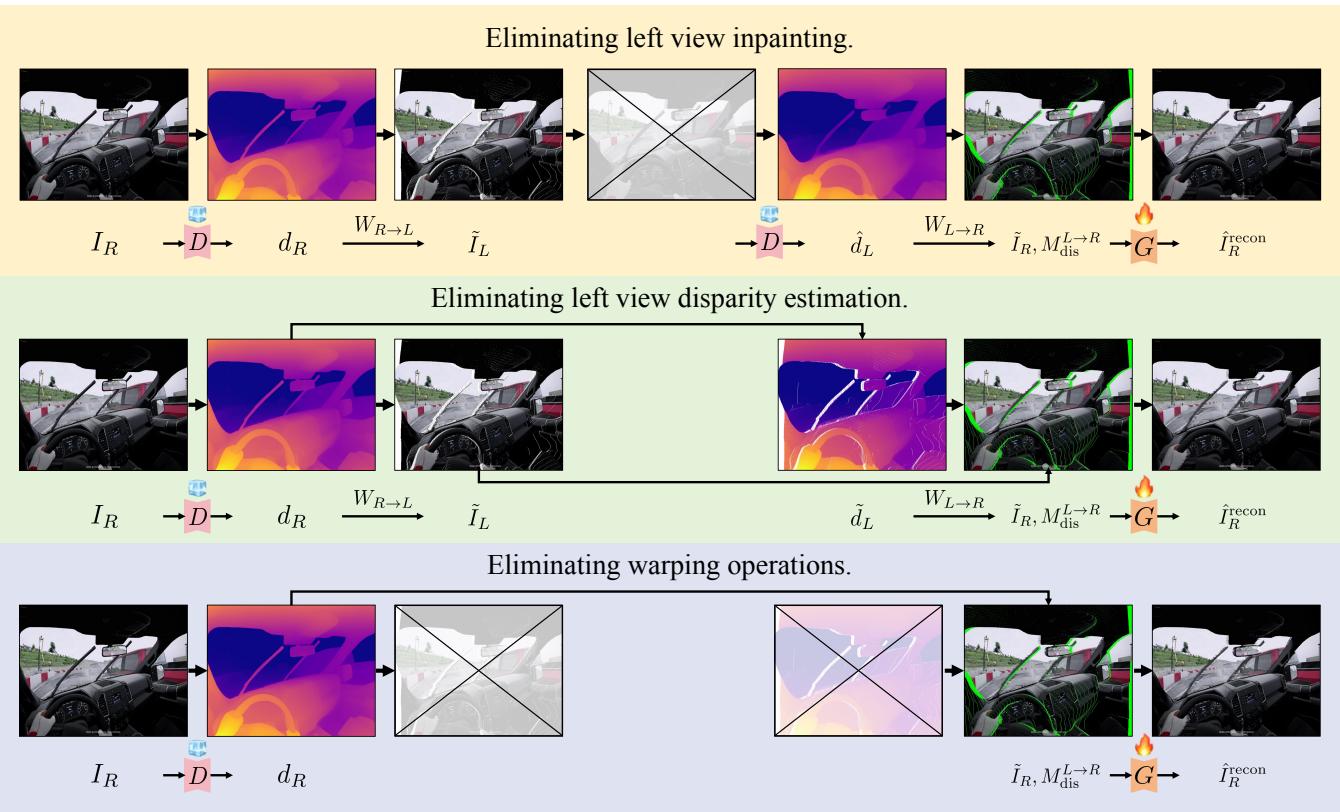
中相关;详见方法、贡献和实验边界。
方法:任务是 monocular-to-stereo generation,但 cycle/geometric reciprocity 可作为视频几何自监督信号参考
中相关;详见方法、贡献和实验边界。
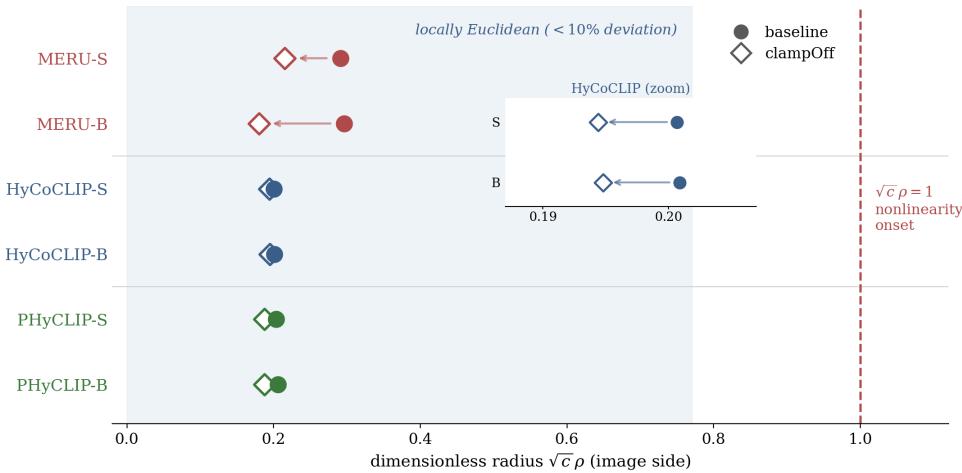
方法:审计 MERU/HyCoCLIP/PHyCLIP 是否真正使用 hyperbolic geometry,适合作为层级 V-L 表征评估反例
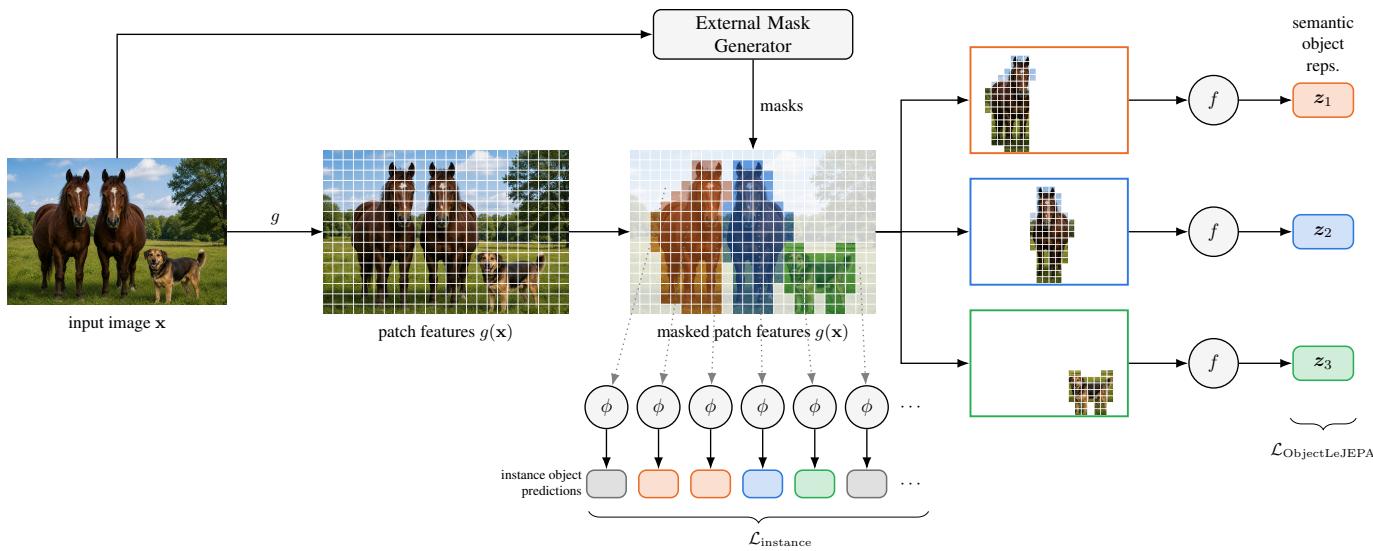
高相关;详见方法、贡献和实验边界。
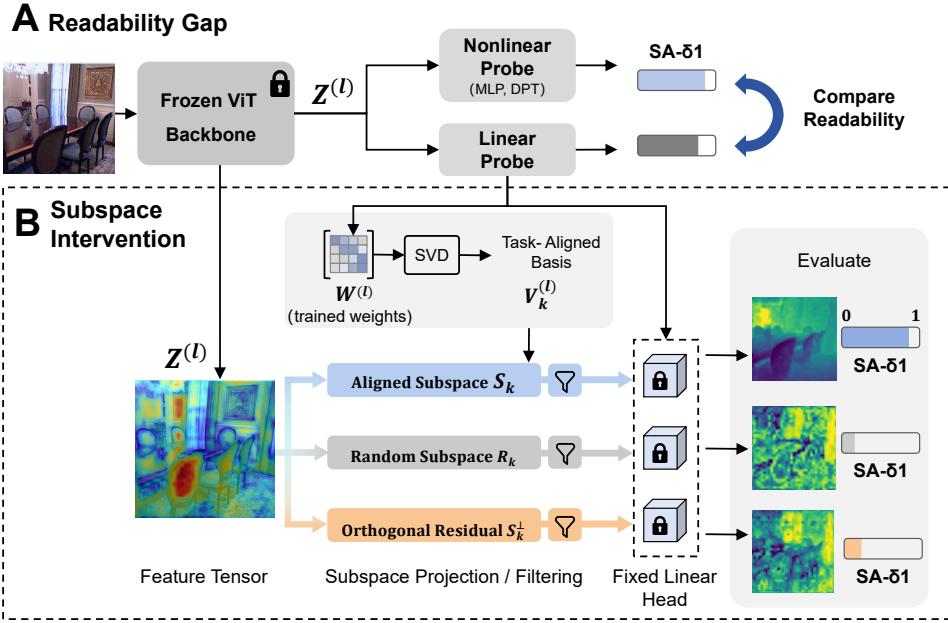
方法:用子空间干预解释 DINOv2、MAE 等 SSL ViT 如何编码 dense geometry,直接服务 backbone/decoder 设计
高相关;详见方法、贡献和实验边界。
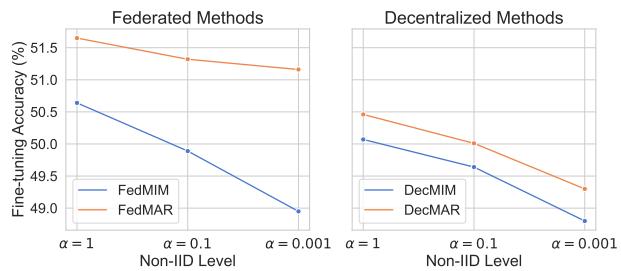
方法:理论上比较 MIM 与 contrastive learning 在非 IID 分布式自监督中的稳健性,并提出 MAR loss
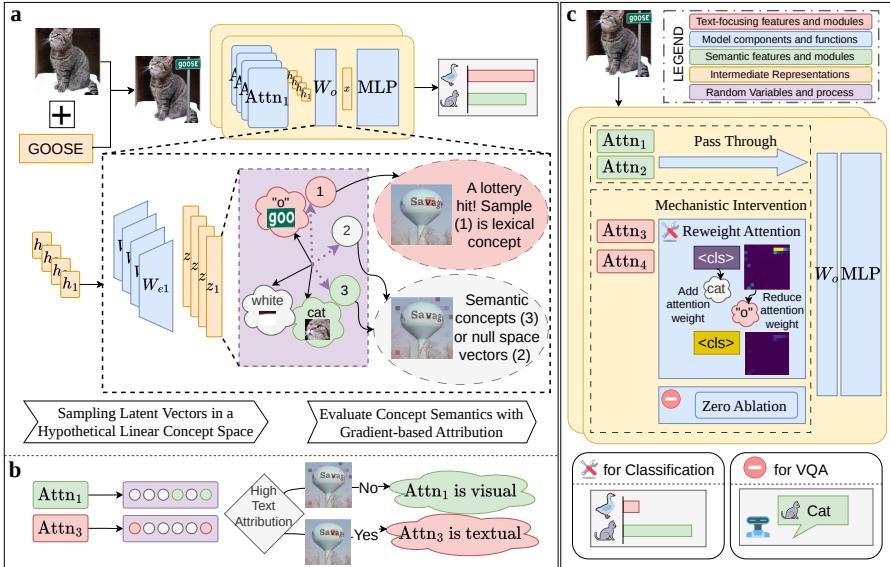
中高相关;详见方法、贡献和实验边界。
方法:定位 CLIP/LVLM 视觉编码器被图中文字劫持的注意力/电路机制,对通用视觉-语言表征可靠性重要
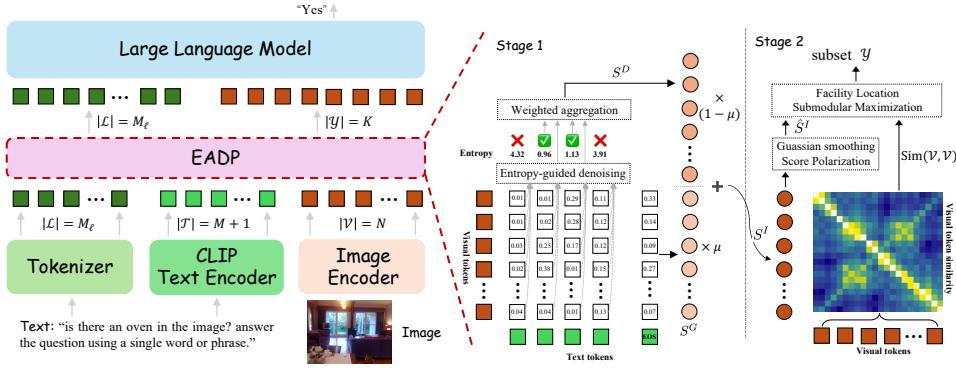
中高相关;详见方法、贡献和实验边界。
方法:把 VLM token pruning 从 top-k 选择改为抗文本噪声的结构化压缩,关注细粒度视觉证据保留
中高相关;详见方法、贡献和实验边界。
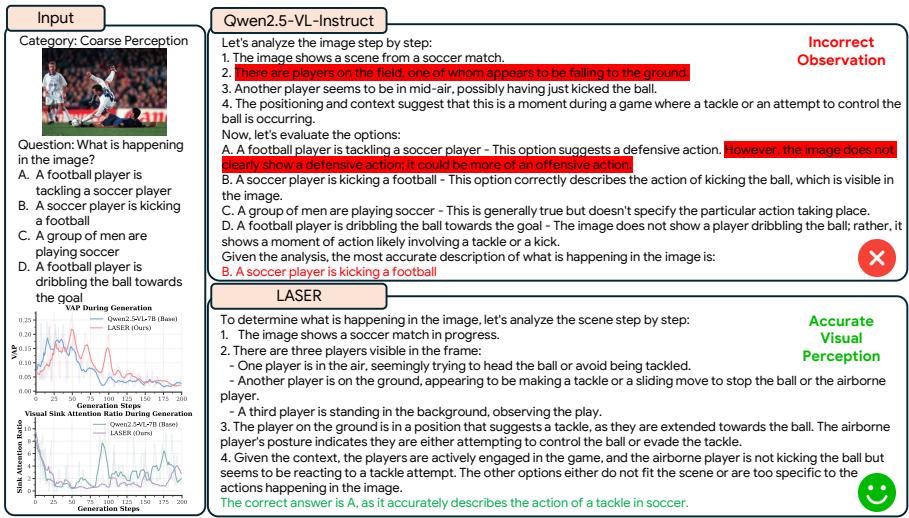
方法:处理长推理中视觉注意力衰减和 visual sink token,适合作为 LVLM 表征保真诊断材料
中相关;详见方法、贡献和实验边界。
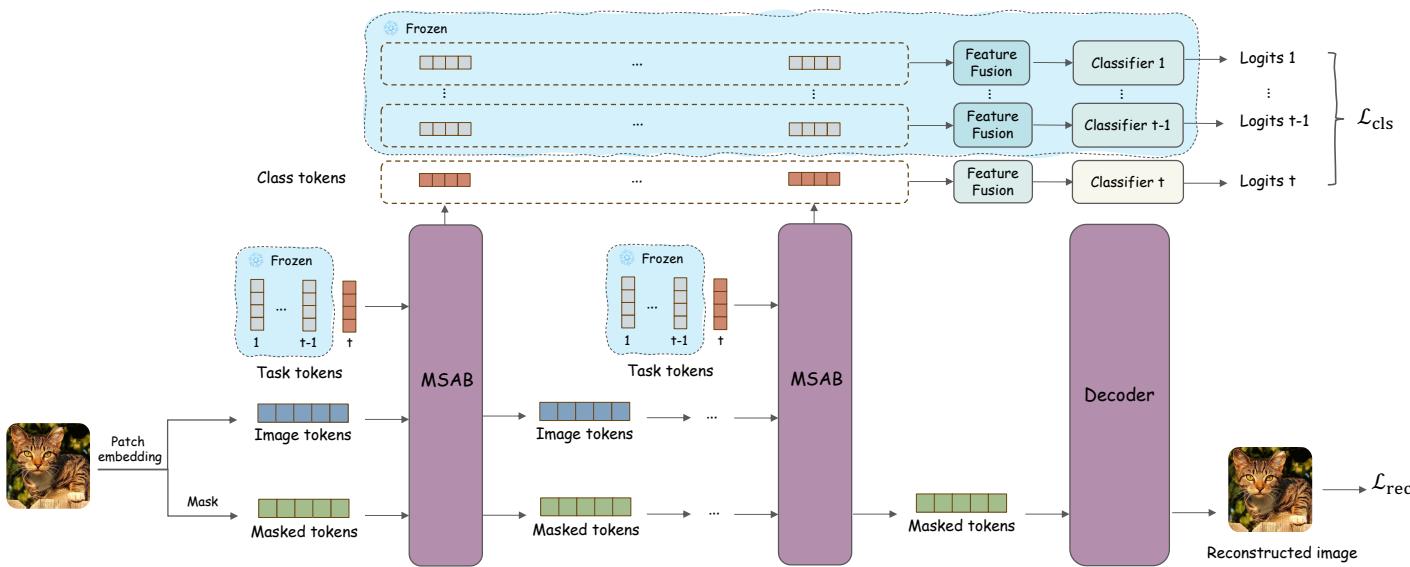
方法:虽然是 class-incremental learning,但持续 MIM 保护任务无关视觉结构的设计可迁移
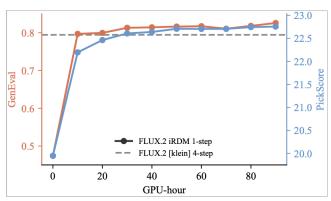
中相关;详见方法、贡献和实验边界。
方法:用多编码器特征分布约束 one-step generator,反映 frozen visual representations 如何作为生成训练信号
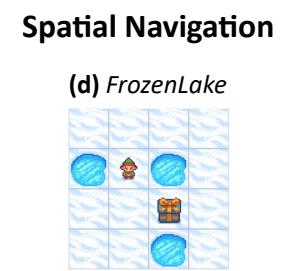
中相关;详见方法、贡献和实验边界。
方法:强调 self-reflection 必须回看视觉证据,适合作为 VLM 视觉 grounding 训练信号参考
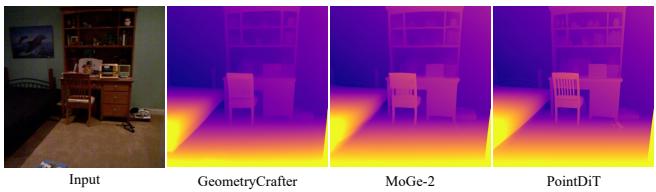
中相关;详见方法、贡献和实验边界。
方法:不是预训练方法,但给出 DINOv2/OpenCLIP/小型 VLM 在低显存 fine-tuning 下的部署对比
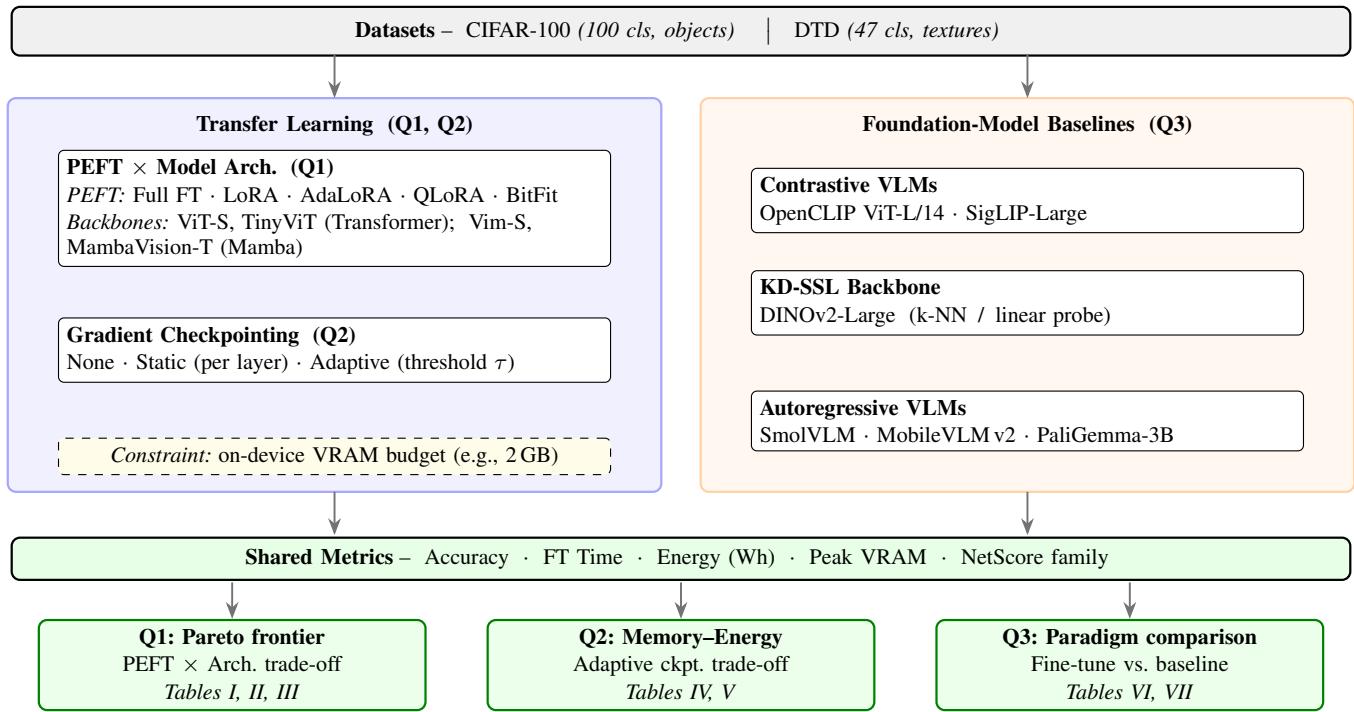
中相关;详见方法、贡献和实验边界。
方法:不是 SSL 训练,但直接使用 DINOv3 image tokens 作为几何扩散条件,能观察 DINO 表征的 dense transfer
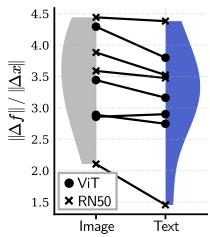
中相关;详见方法、贡献和实验边界。
方法:用语言 embedding 作为信息瓶颈抑制环境伪相关,和视觉-语言表征的 domain invariance 相关
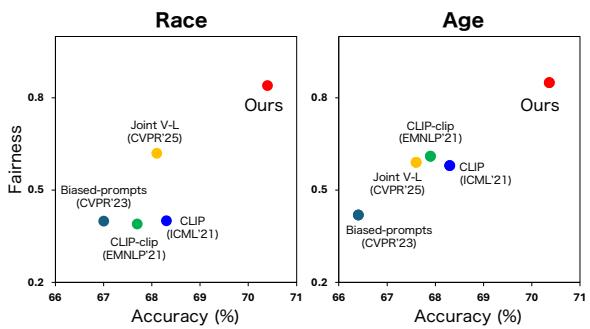
中相关;详见方法、贡献和实验边界。
方法:虽然目标是公平性,但核心机制是在不损坏通用 cross-modal alignment 的前提下选择性调节 CLIP/VLM 输出
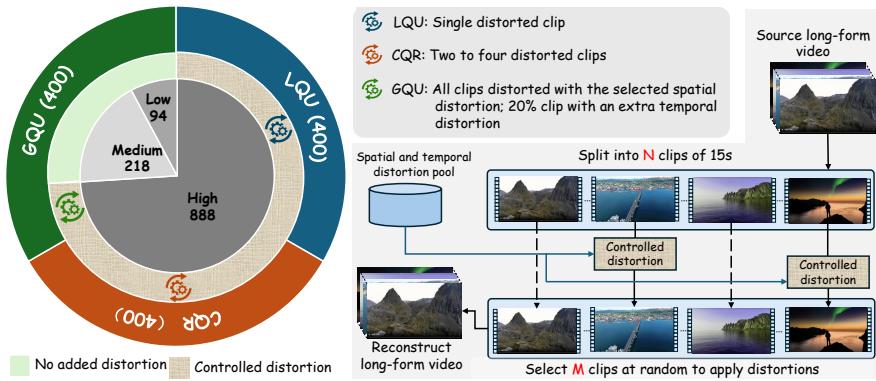
中相关;详见方法、贡献和实验边界。
方法:不训练 backbone,但提供长视频质量理解、时间聚合和细粒度视觉证据归因的诊断集
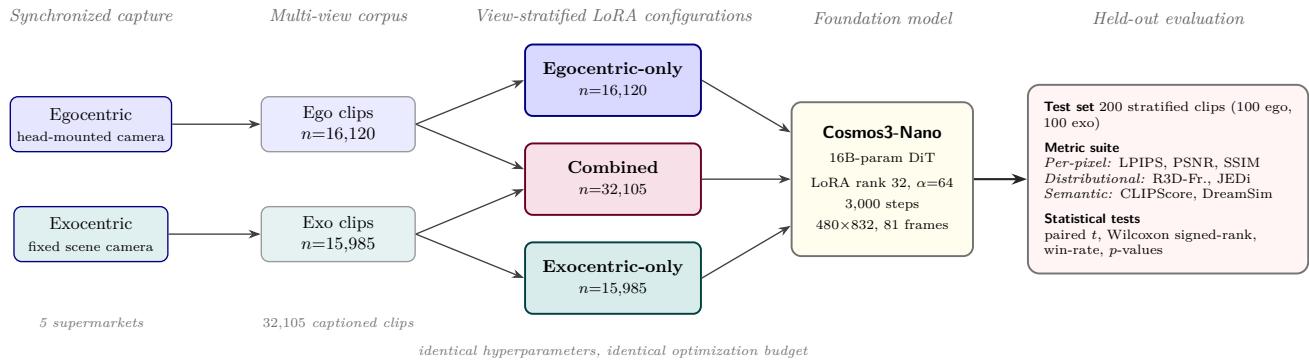
中相关;详见方法、贡献和实验边界。
方法:零售场景偏垂直,但比较 ego/exo 视角对 Cosmos3-Nano 视频 world model 适配的贡献,值得借鉴数据视角
中低相关;详见方法、贡献和实验边界。
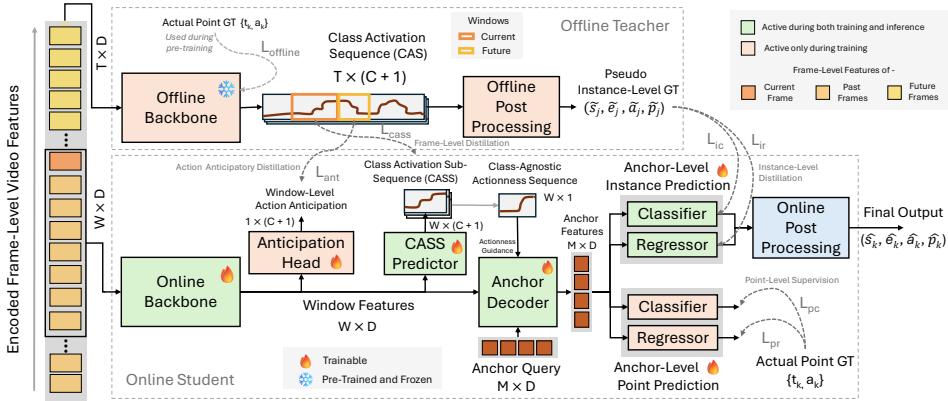
方法:是弱监督视频 TAL,不是通用 SSL;但 offline teacher 到 online student 的多层蒸馏结构可作为视频表征压缩参考
中低相关;详见方法、贡献和实验边界。
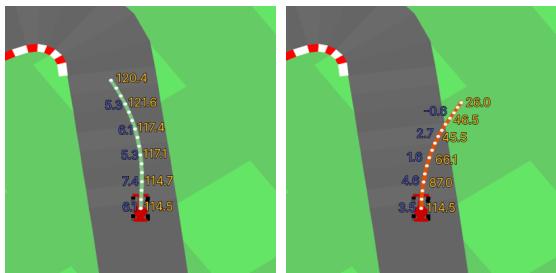
方法:偏 RL/CarRacing,但 latent diffusion dynamics + MPC 的低延迟 trade-off 对视频 world-model 表征路线有背景价值
高相关;详见方法、贡献和实验边界。
方法:把 JEPA 式非对比学习直接推到端到端图文预训练,目标是更好的 dense visual tokens
高相关;详见方法、贡献和实验边界。
方法:针对 visual autoregressive 模型的多尺度表征冲突,用自监督特征对齐和 MoE 路由修补早期语义
高相关;详见方法、贡献和实验边界。
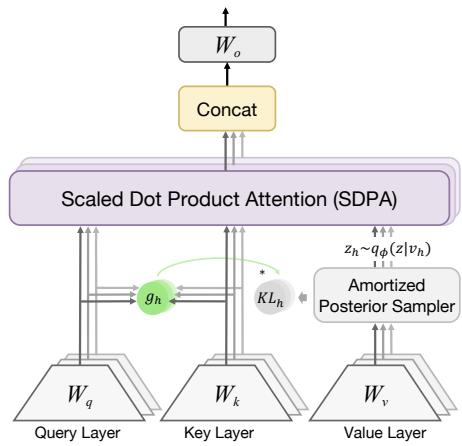
方法:把 VLM hallucination/grounding 失败追到视觉信息注入失控,并给出 attention-level 表征正则
高相关;详见方法、贡献和实验边界。
方法:把“输入 token 怎么切”提升为资源自适应第三杠杆,尤其指出 self-supervised foundation backbones 最受益
中高相关;详见方法、贡献和实验边界。
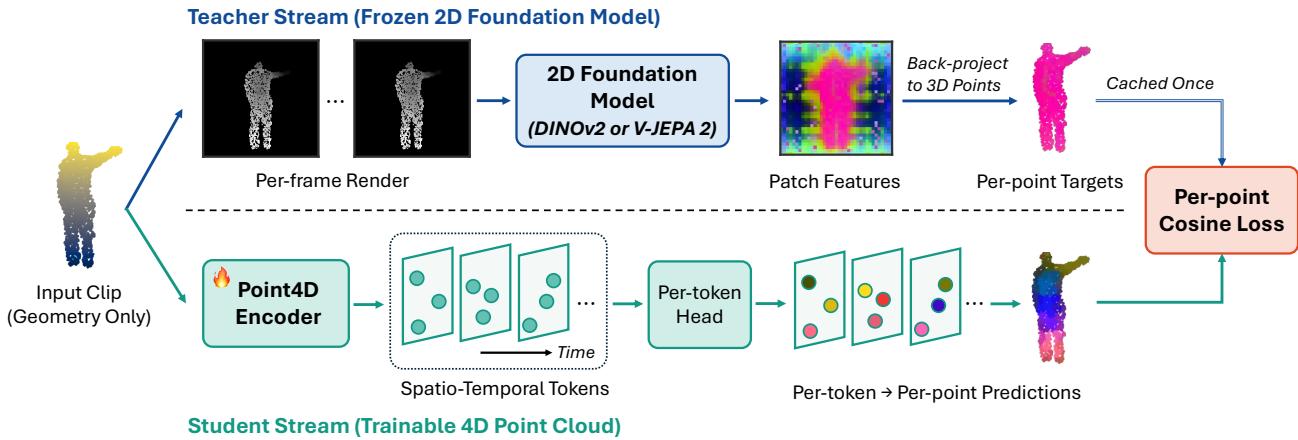
方法:虽然是 4D point cloud,但核心是把 DINOv2/V-JEPA dense patch semantics 蒸馏到动态几何编码器
中高相关;详见方法、贡献和实验边界。
方法:从 CLIP 式视频文本对比预训练的 entanglement 入手,处理长视频和长 caption 的局部相关性
中高相关;详见方法、贡献和实验边界。
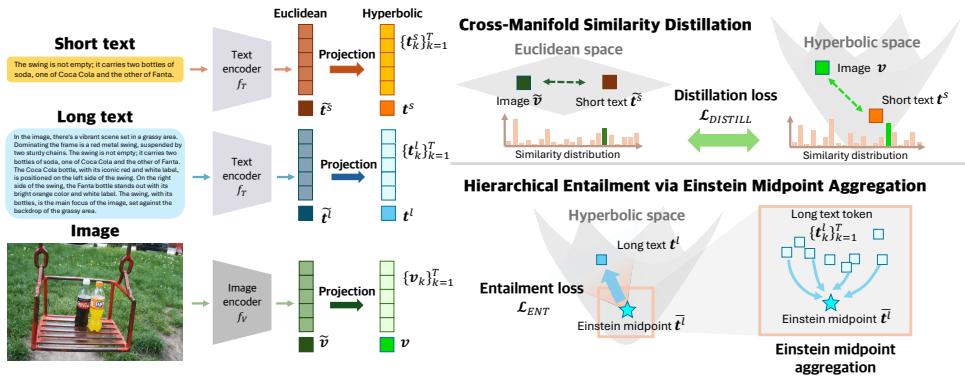
方法:用 hyperbolic geometry 处理 CLIP 长文本上下文和层级语义,对图文表征鲁棒性有直接参考
中高相关;详见方法、贡献和实验边界。
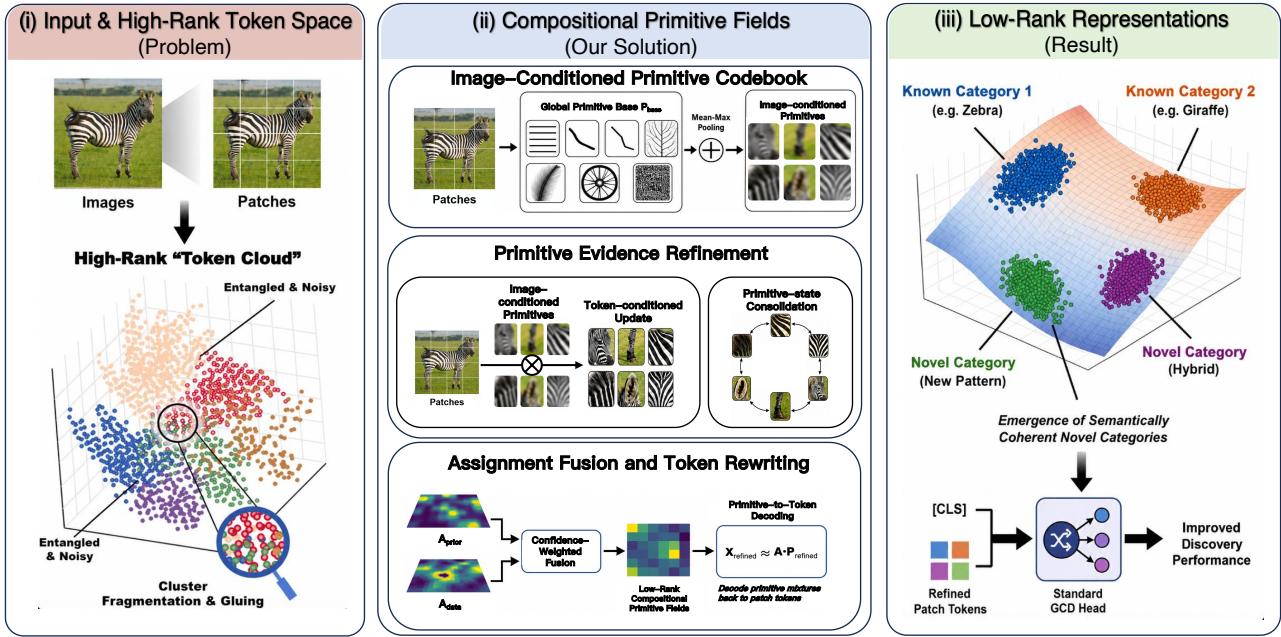
方法:把 open-world category discovery 的瓶颈定位为高秩、纠缠的 patch-token 表征,并显式构造 compositional primitive field
中高相关;详见方法、贡献和实验边界。
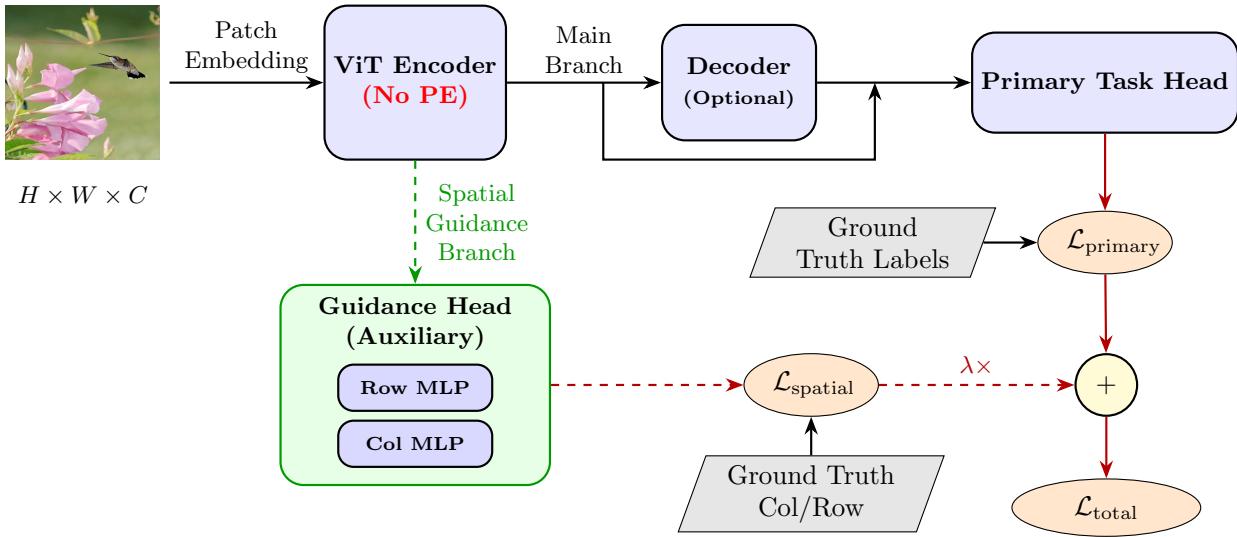
方法:讨论 ViT 是否必须注入 positional mechanism,直接关系到自监督 backbone 的空间归纳偏置
中高相关;详见方法、贡献和实验边界。
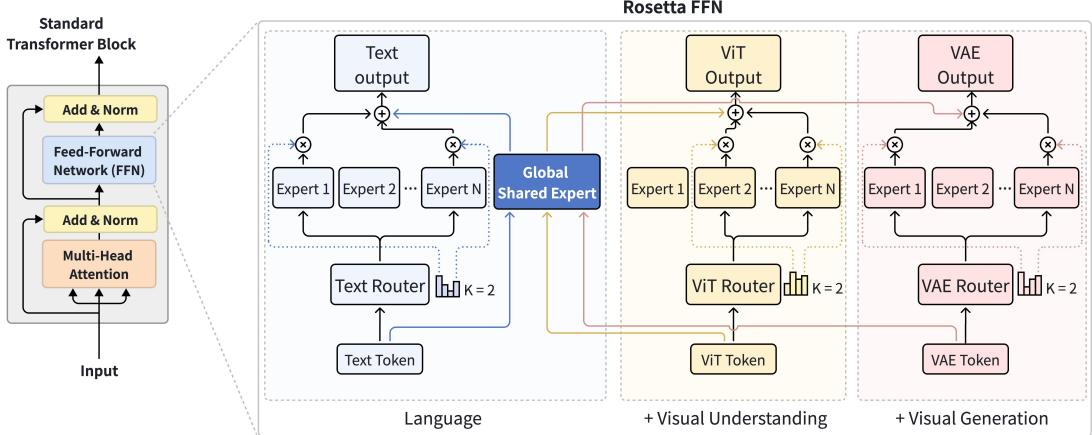
方法:聚焦新模态接入时的 representation overwriting,适合放进 multimodal foundation model 训练路线
中相关;详见方法、贡献和实验边界。
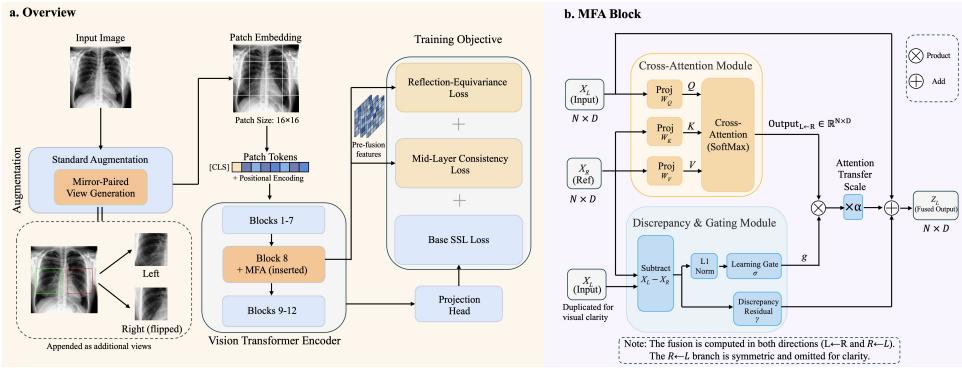
方法:用 mirror-paired views 和 token-level mirror fusion 修补过强 flip invariance,方法可迁移但数据有明显垂直属性
中相关;详见方法、贡献和实验边界。
方法:从 action-free internet videos 学表示,虽然落点是 RL,但核心是视频自监督如何避免只保留静态像素
中相关;详见方法、贡献和实验边界。
方法:不是 SSL 方法本身,但直接服务大规模视觉预训练/下游训练的数据效率和合成数据保真
中相关;详见方法、贡献和实验边界。
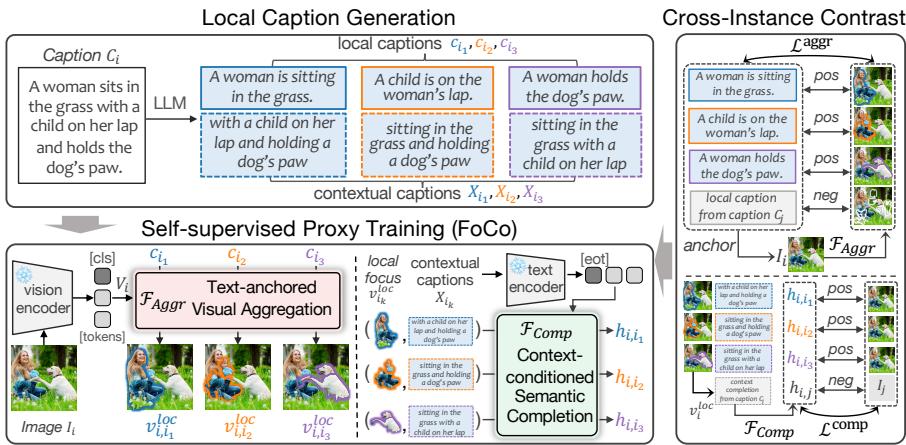
方法:偏检索任务,但 proxy-task 设计能参考到图文表征组合能力
中相关;详见方法、贡献和实验边界。
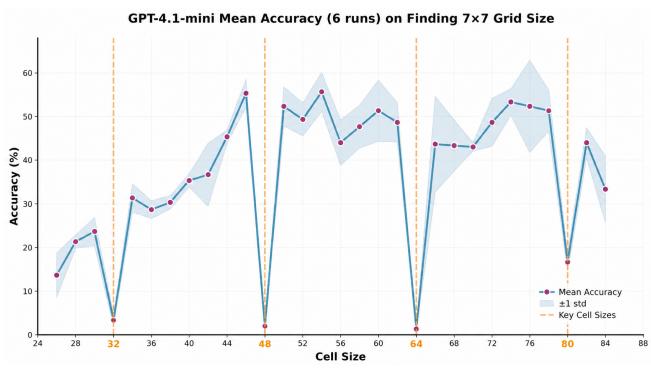
方法:安全论文,但黑盒恢复 VLM patch size / preprocessing 的 side channel 很能说明 tokenizer 接口的可见性
高相关;详见方法、贡献和实验边界。
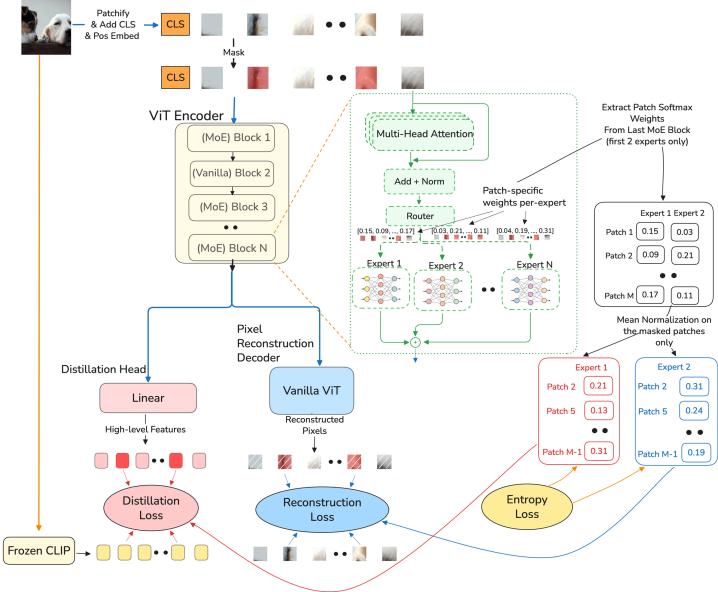
方法:把 token distillation、CLS alignment、pixel reconstruction 变成按 patch 自适应路由的 MIM 训练信号
高相关;详见方法、贡献和实验边界。
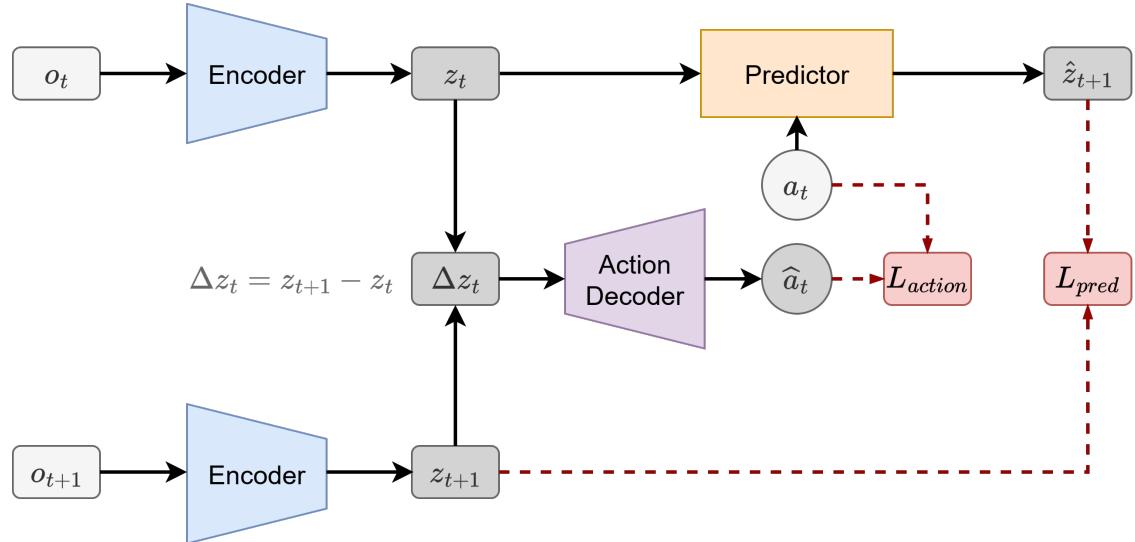
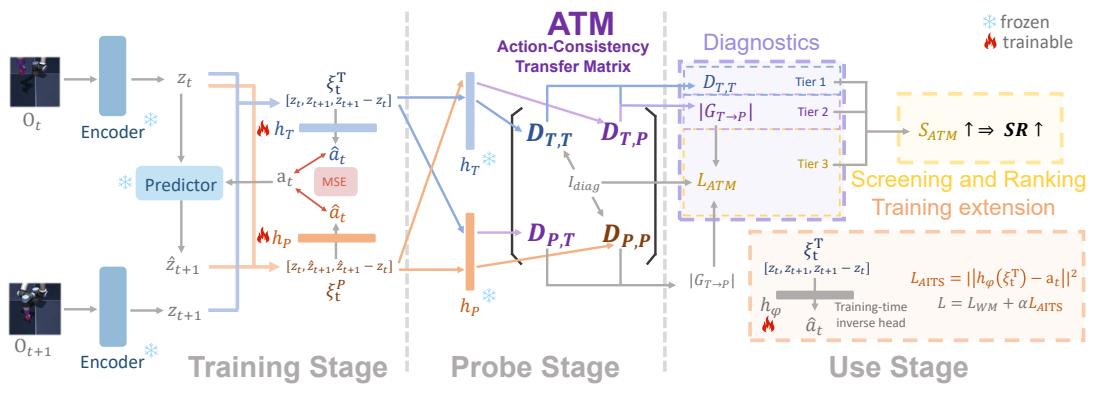
方法:针对 JEPA 式 world model 的 action-insensitive collapse,直接在 latent displacement 上加动作监督
高相关;详见方法、贡献和实验边界。
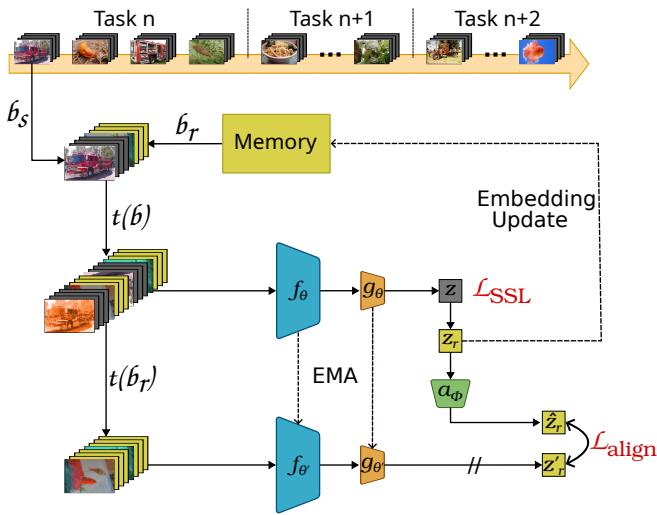
方法:在线 continual self-supervised learning 直接服务无标签图像流中的表征保持与漂移控制
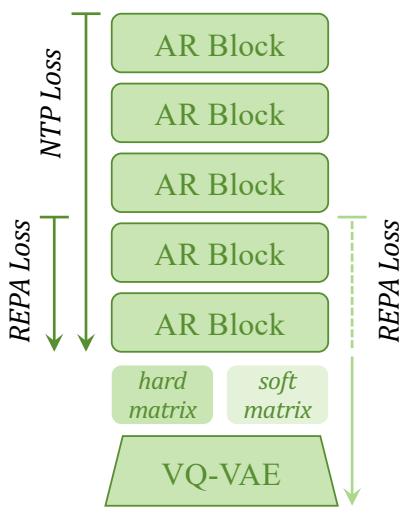
高相关;详见方法、贡献和实验边界。
方法:把 VQ tokenizer 与 AR generator 端到端联合训练,并用 representation alignment 让生成器反向塑造视觉 token
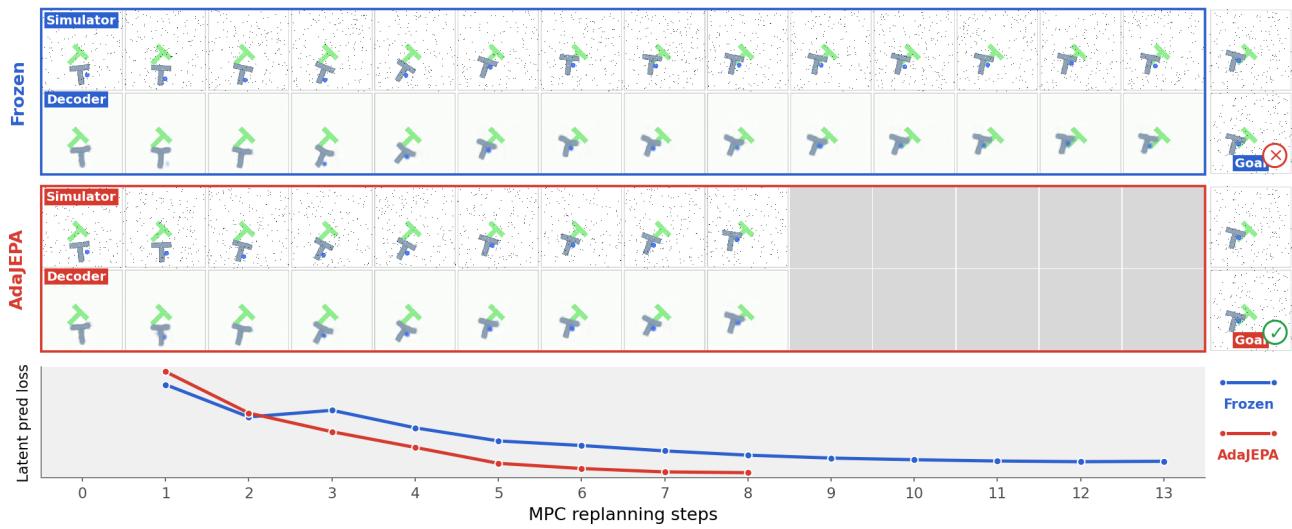
中高相关;详见方法、贡献和实验边界。
方法:AdaJEPA 用闭环自监督 transition 做 test-time adaptation,补上 frozen latent world model 的分布偏移问题
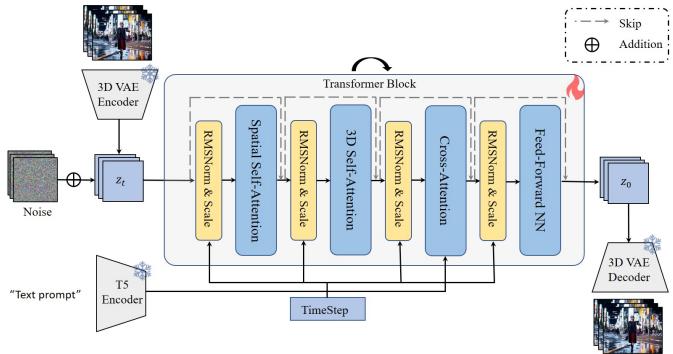
中高相关;详见方法、贡献和实验边界。
方法:视频 world model 的长期一致性不只靠更长 context,MemLearner 学习如何查询 context memory
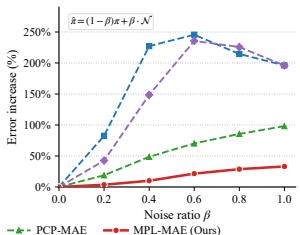
中高相关;详见方法、贡献和实验边界。
方法:3D MAE 的 positional leakage 诊断对所有 masked reconstruction 类 SSL 都有警示价值
中高相关;详见方法、贡献和实验边界。
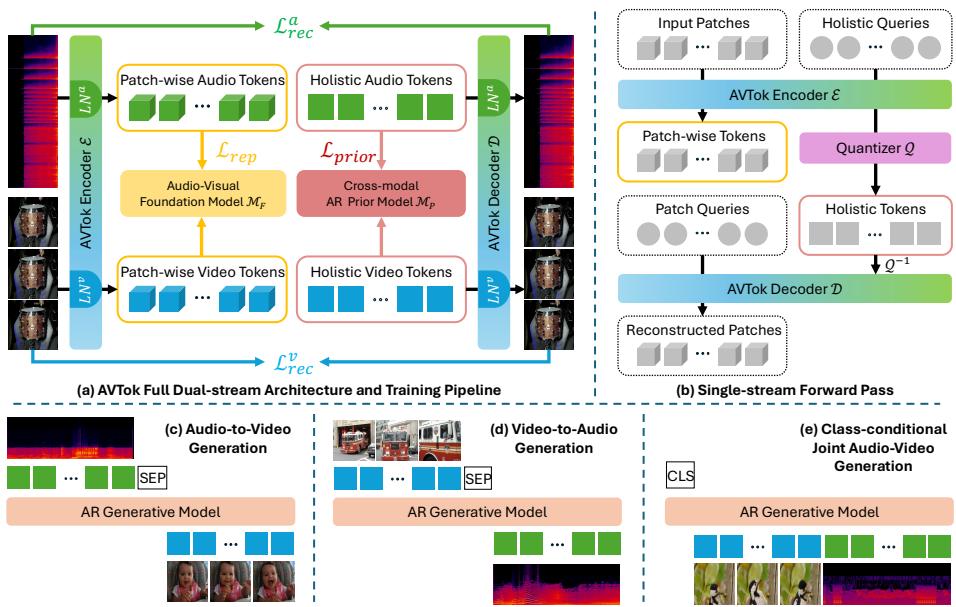
方法:AVTok 把 audio/video 编到统一 1D latent codebook,和视觉 token 化、多模态预训练接口高度相关
中高相关;详见方法、贡献和实验边界。
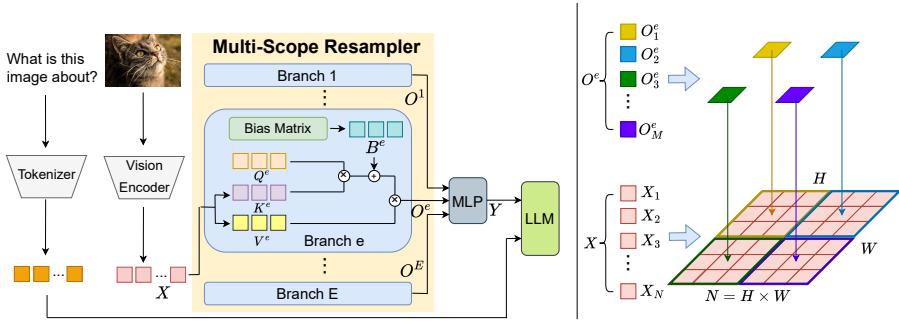
方法:MS-Resampler 直接处理 dense visual features 到短 visual token sequence 的信息保留问题
中高相关;详见方法、贡献和实验边界。
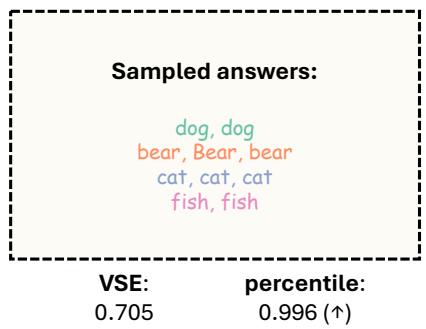
方法:用只扰动图像、不扰动文本的 Visual Semantic Entropy 测 VLM 是否识别视觉歧义
中高相关;详见方法、贡献和实验边界。
方法:它用 blank-image arbiter 反驳“probe 能线性读出就代表视觉 grounded”的常见误判
中相关;详见方法、贡献和实验边界。
方法:ERA 讨论 aggressive visual token pruning 后的 attention logit collapse,和高效 MLLM 视觉证据保留相关
中相关;详见方法、贡献和实验边界。
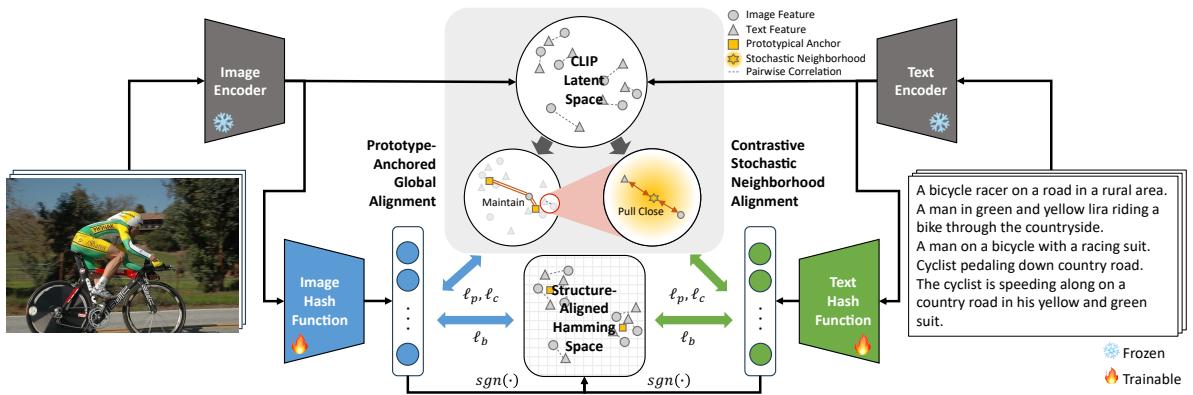
方法:少量 image-text pair 下,把 VLM 连续 latent 结构转成二值 Hamming 空间,适合看数据效率与跨模态对齐
中相关;详见方法、贡献和实验边界。
方法:Cross-Space Distillation 解决 teacher/student latent space 不同的问题,可借鉴到异构视觉基础模型蒸馏
中相关;详见方法、贡献和实验边界。
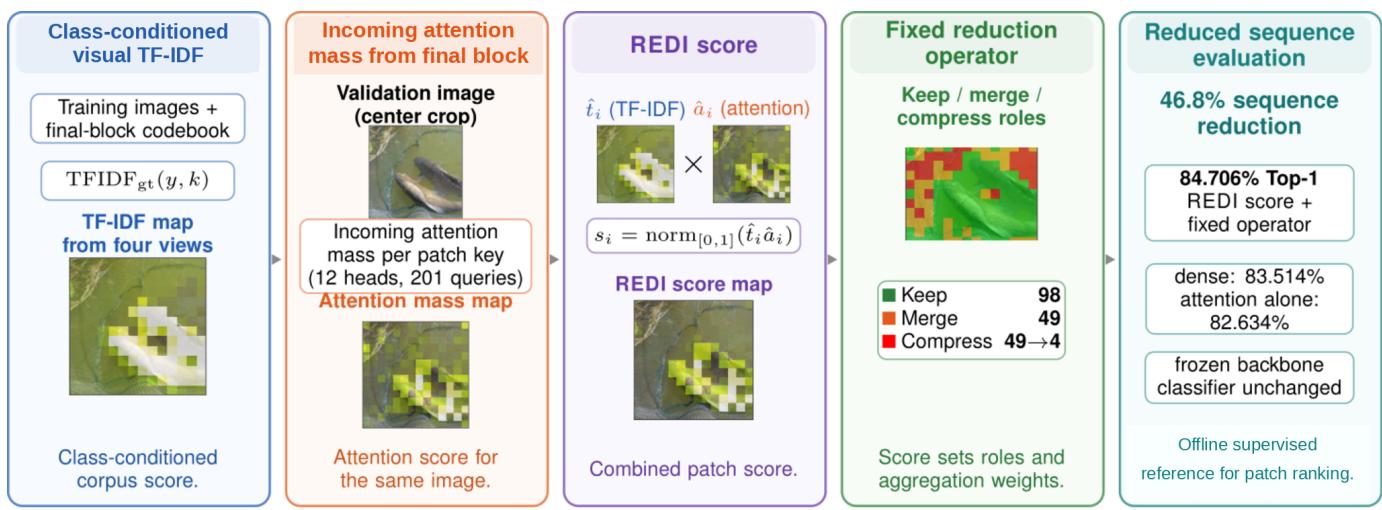
方法:REDI 用 corpus-aware visual vocabulary + attention 给 DINOv3 patch ranking,适合扫 token ranking 机制
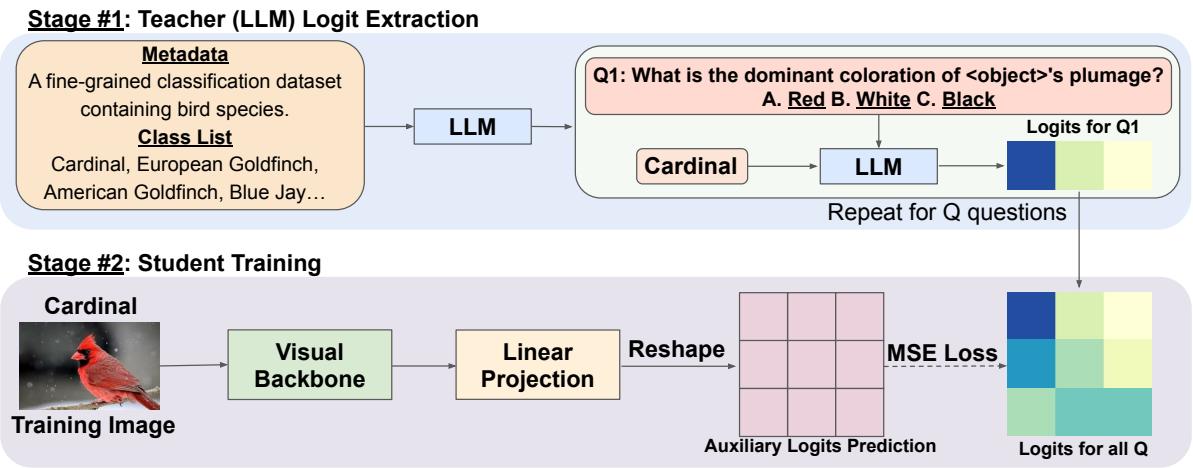
高相关;详见方法、贡献和实验边界。
方法:用语言-only LLM 产生细粒度概念监督来蒸馏 vision-only student,直接对应视觉表征蒸馏与弱多模态监督
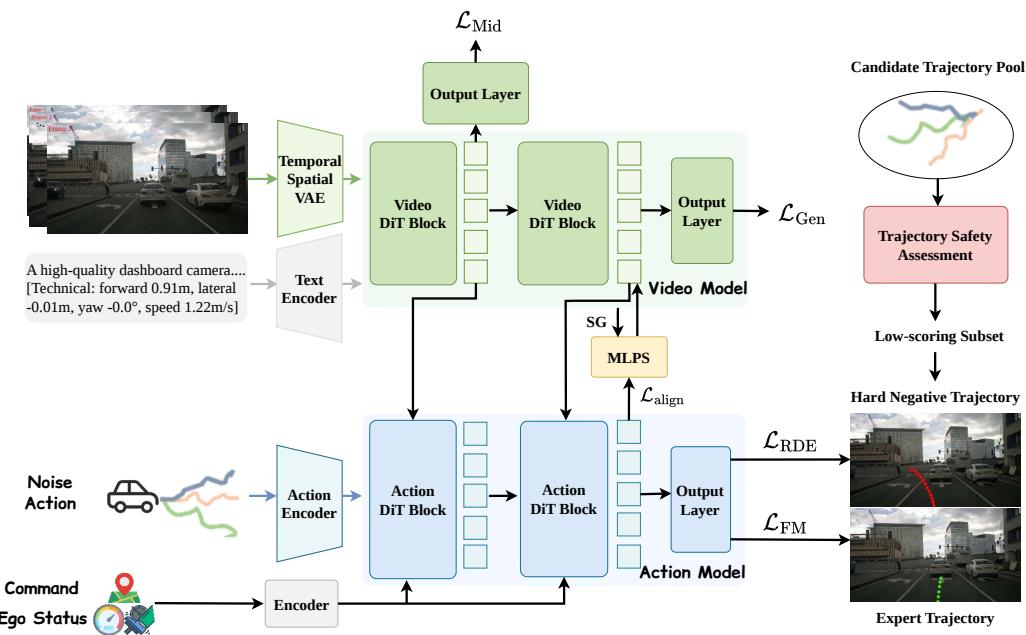
高相关;详见方法、贡献和实验边界。
方法:ReWorld 直接优化 world action model 的中间表征,和视频预训练、JEPA/world-model 线高度相关
高相关;详见方法、贡献和实验边界。
方法:PRA 不依赖离散 tokenizer,直接在 pixel-space AR 中学习中间状态,并报告 probing accuracy 提升
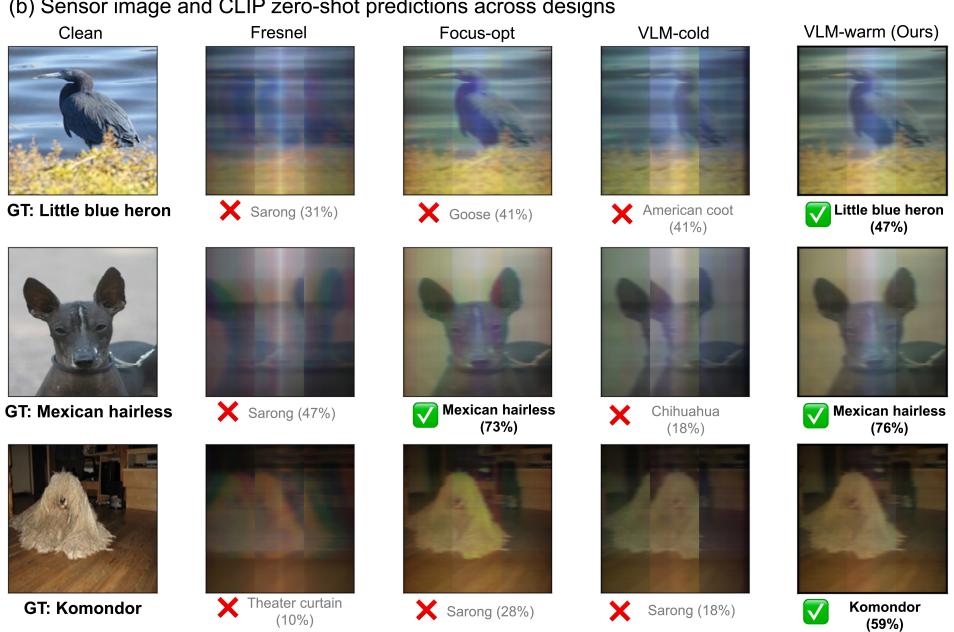
中高相关;详见方法、贡献和实验边界。
方法:CODA 直接用 frozen CLIP 目标优化光学前端,并迁移到 SigLIP/DINOv2,说明视觉基础模型目标可反向塑造输入成像
中高相关;详见方法、贡献和实验边界。
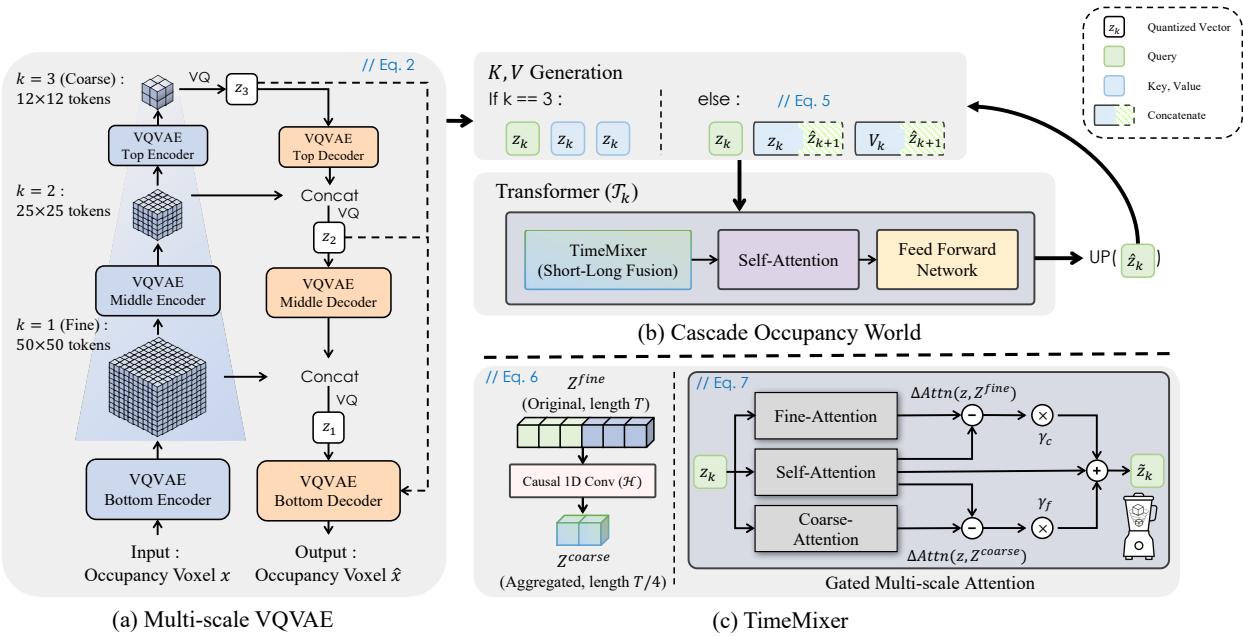
方法:CascadeOcc 用 cascaded VQ 表示建模 3D occupancy world dynamics,适合跟踪离散视觉 token/world representation
中高相关;详见方法、贡献和实验边界。
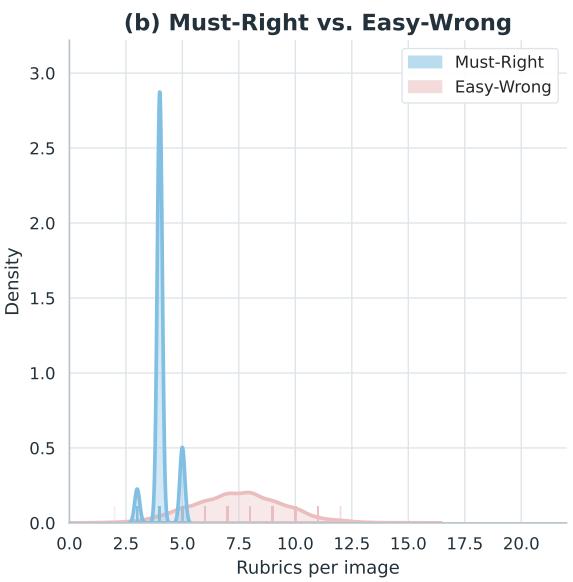
方法:PerceptionRubrics 把 VLM 视觉感知评测拆成原子 rubrics,可用于判断视觉表征是否真正保留细节
中高相关;详见方法、贡献和实验边界。
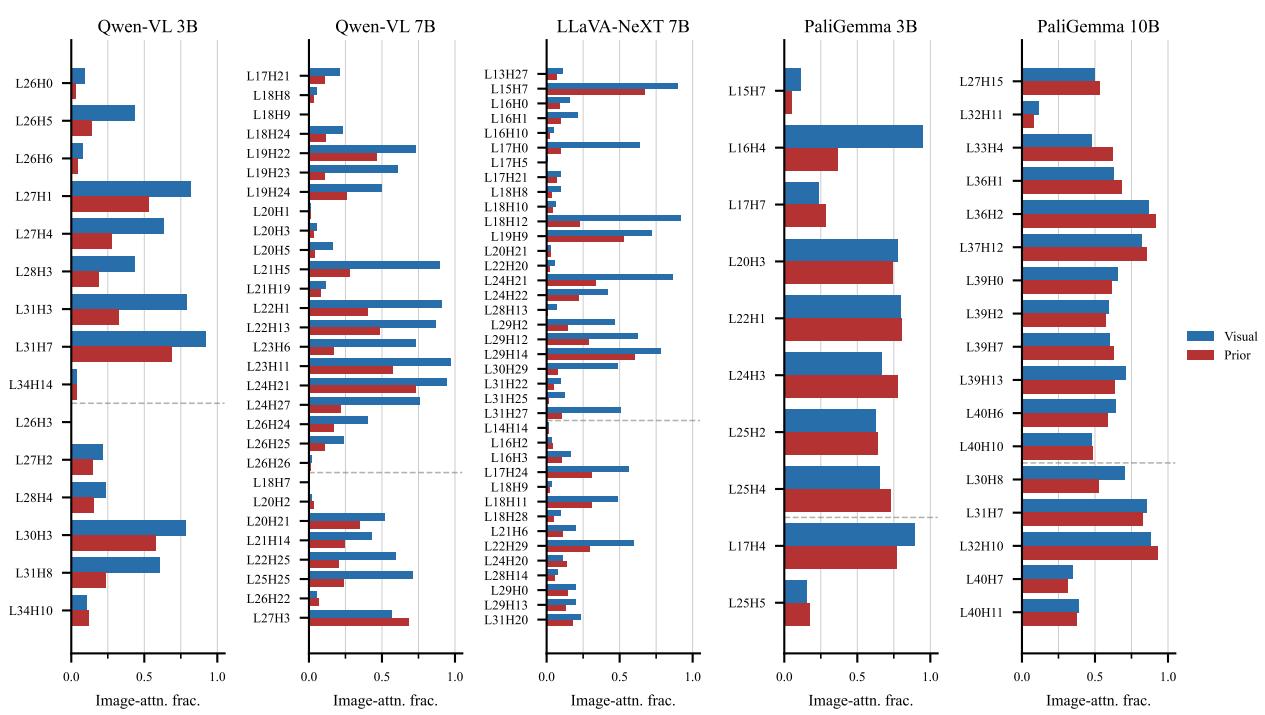
方法:论文定位 VLM 中视觉证据与世界知识冲突的因果注意力头,有助于理解视觉 grounding 是否被语言先验覆盖
中高相关;详见方法、贡献和实验边界。
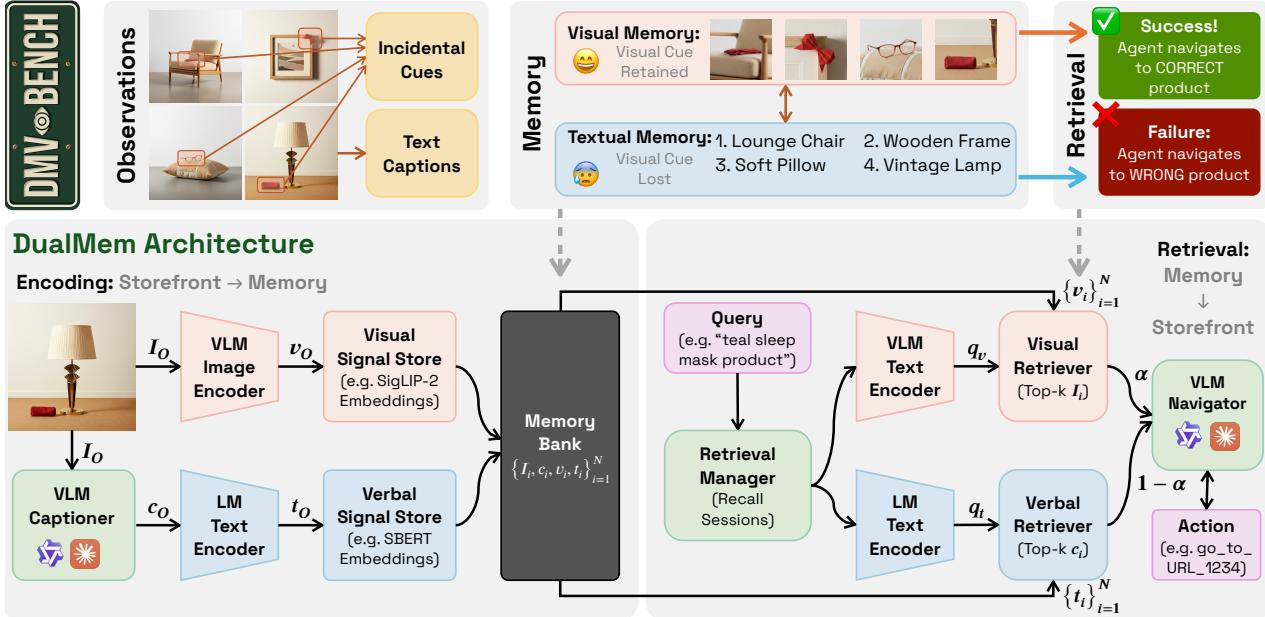
方法:DMV-Bench 把长期记忆信号限制在像素 cue 中,可测试模型是否真的保留视觉表征而非文本泄漏
中高相关;详见方法、贡献和实验边界。
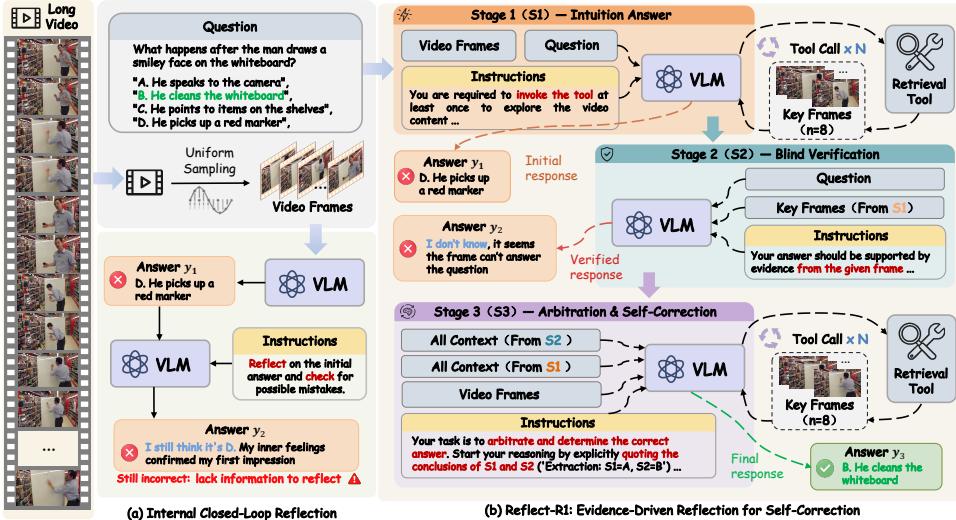
方法:Reflect-R1 通过检索客观视觉证据做自校正,和视频 VLM 的 grounding/post-training 相关
中相关;详见方法、贡献和实验边界。
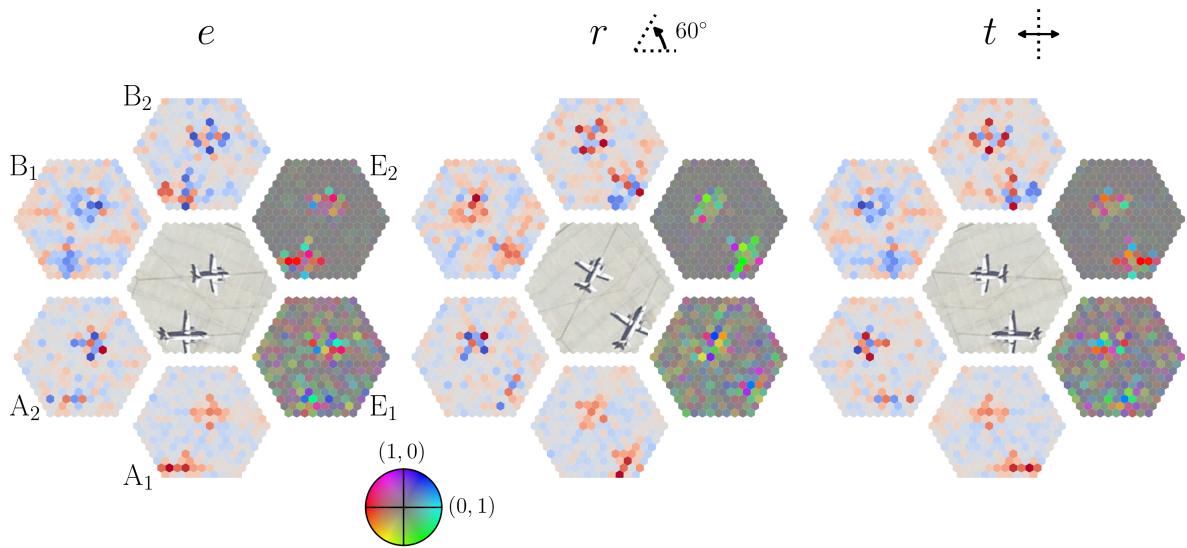
方法:给 ViT 加 O(2) 离散子群等变性,在数据稀缺视觉表征学习中可能减少对数据增强的依赖
中相关;详见方法、贡献和实验边界。
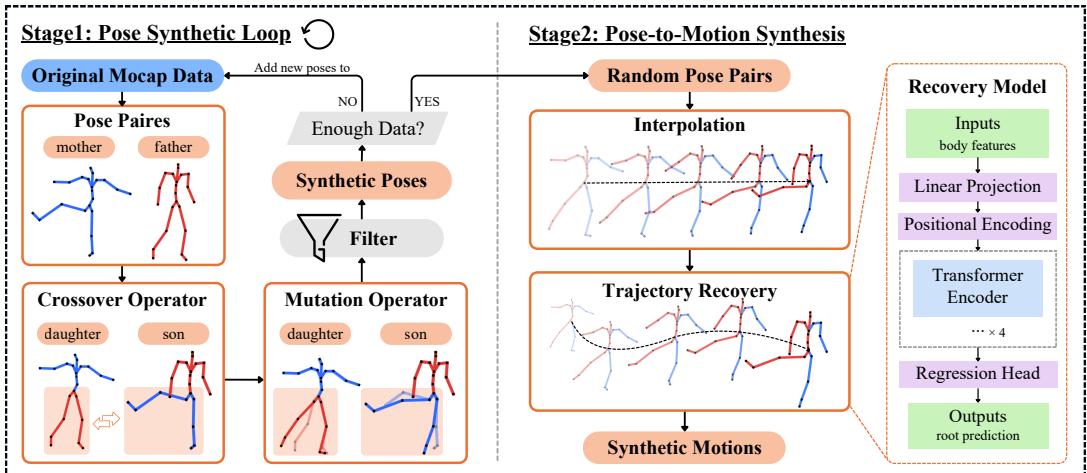
方法:Motion tokenizer 与合成运动扩展 codebook 的想法,可迁移到视频 tokenization/动作表征
中相关;详见方法、贡献和实验边界。
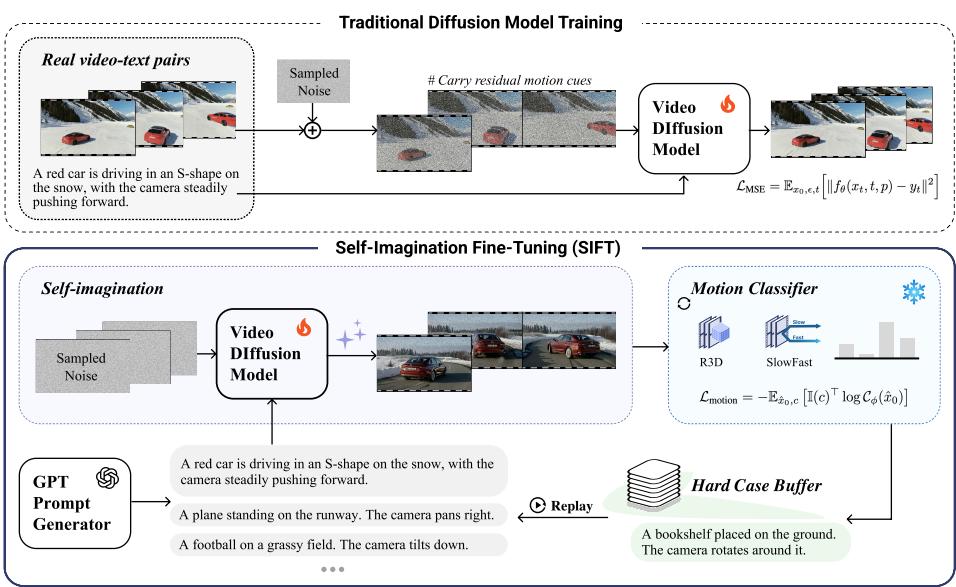
方法:SIFT 让视频 diffusion 从自身生成样本中学习物理运动,属于自生成数据驱动的 video model 后训练
中相关;详见方法、贡献和实验边界。
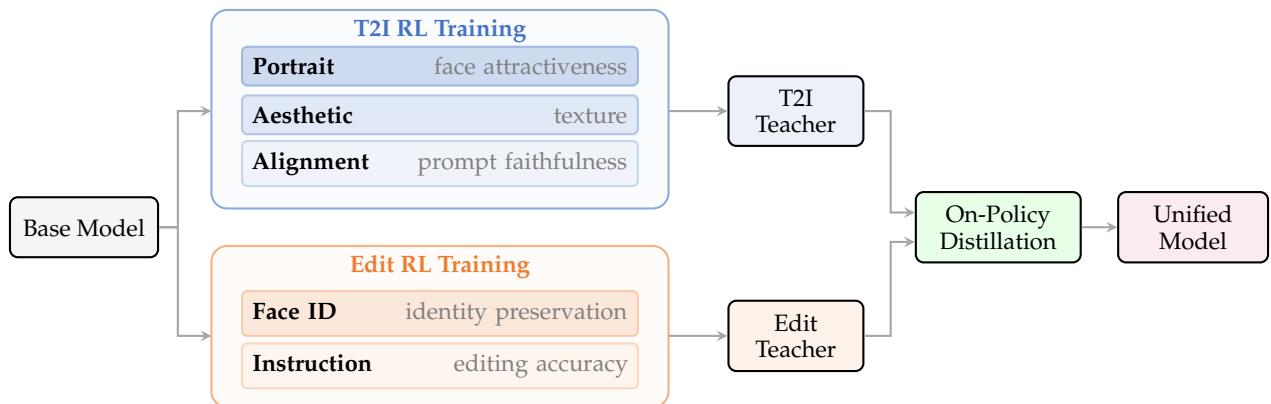
方法:Qwen-Image-2.0-RL 是视觉生成 post-training 技术报告,包含 VLM reward 与 on-policy distillation,可扫其视觉奖励信号设计
中相关;详见方法、贡献和实验边界。
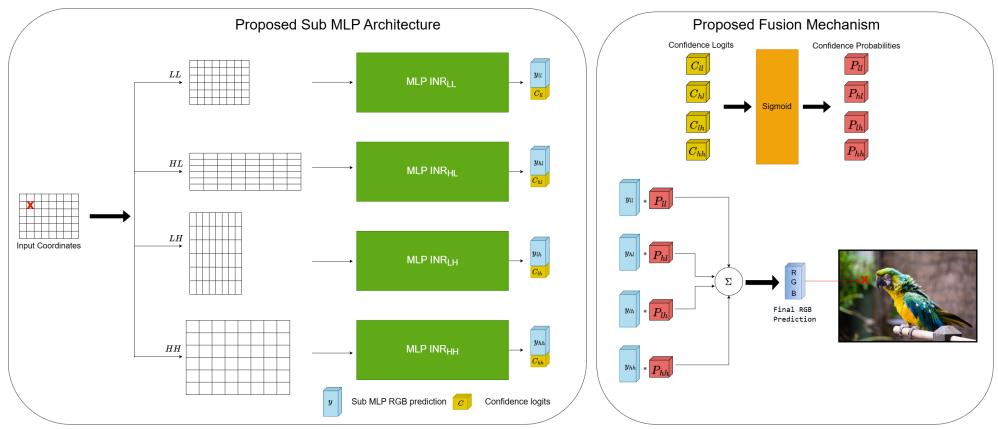
方法:ScaLe-INR 关注连续信号表示的频谱分解,对图像/3D INR 表征有方法参考,但不是 SSL 主线
高相关;详见方法、贡献和实验边界。
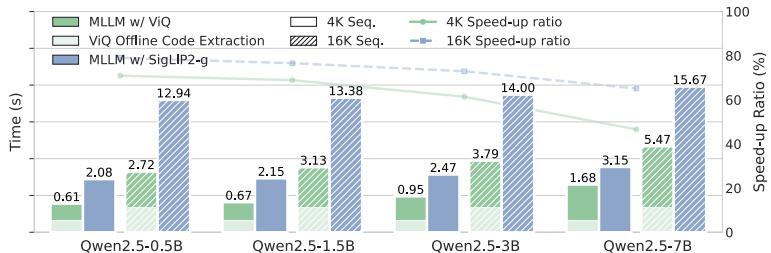
方法:任意分辨率视觉输入被压成 text-aligned discrete representation,直接影响统一多模态模型的视觉 token 接口
高相关;详见方法、贡献和实验边界。
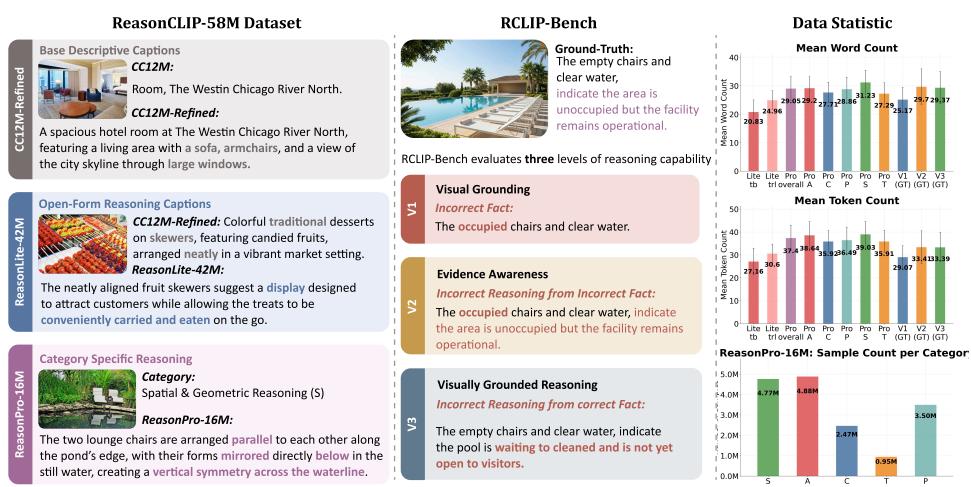
方法:在 CLIP-style encoder 上加入视觉可验证 reasoning supervision,同时保持 descriptive alignment
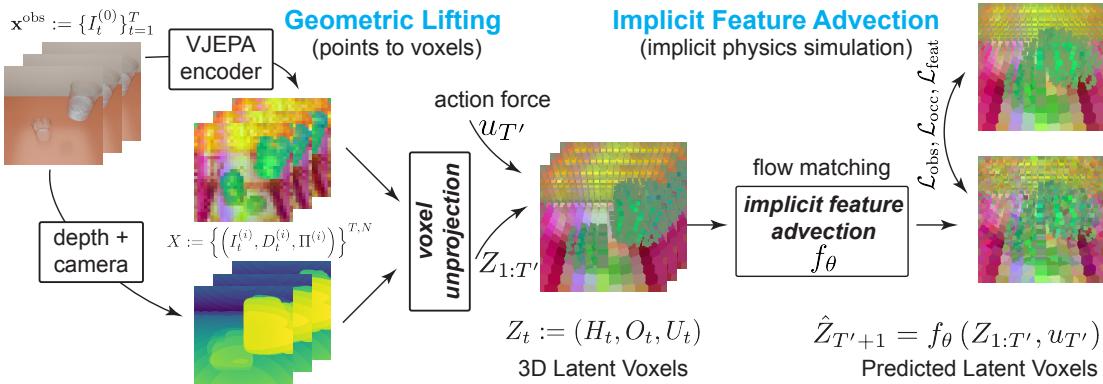
高相关;详见方法、贡献和实验边界。
方法:用 V-JEPA semantic features 构建 3D latent dynamics,是视频 SSL 与 world model 的强交叉
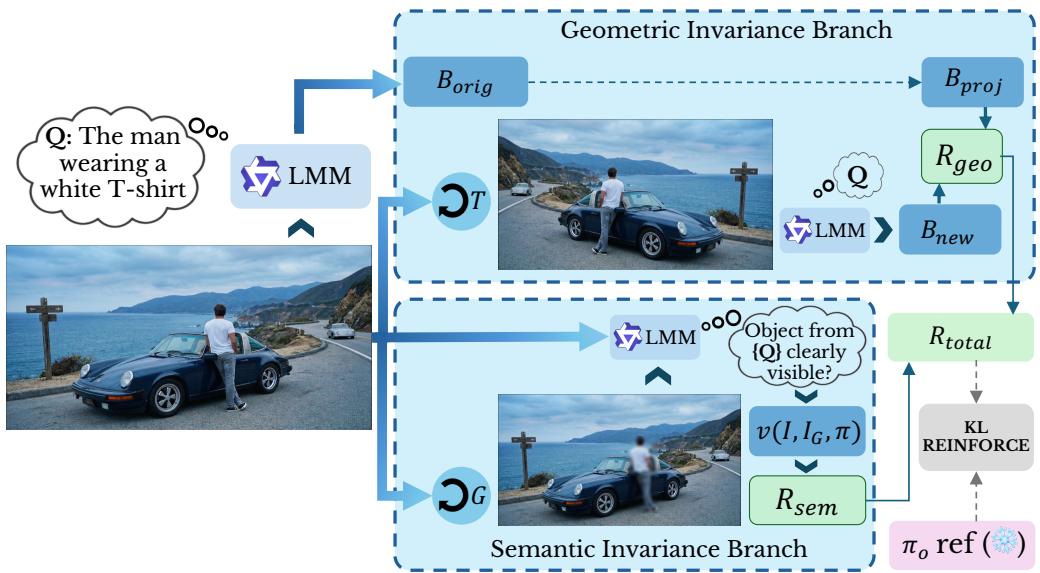
高相关;详见方法、贡献和实验边界。
方法:指出 self-consistency 自训练会走语言捷径,提出显式压住视觉 token attention 的奖励
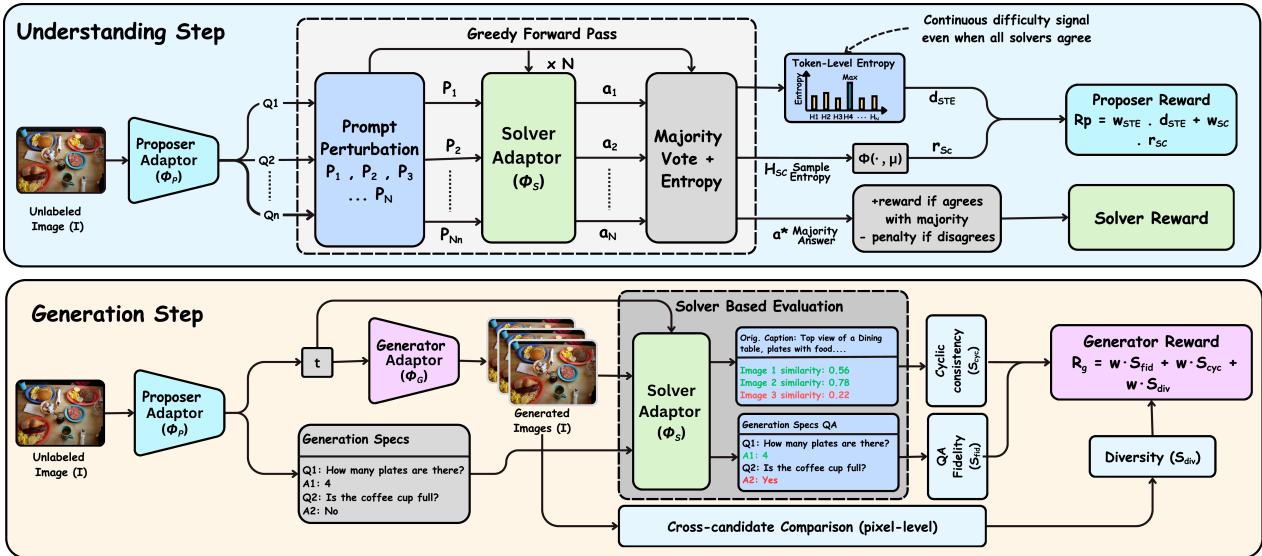
高相关;详见方法、贡献和实验边界。
方法:用未标注图像让统一 LMM 自己提问、回答和生成图像,接近无人工标注的 VLM 自监督训练
中高相关;详见方法、贡献和实验边界。
方法:dense local alignment + masked visual modeling 的跨模态自监督框架可迁移
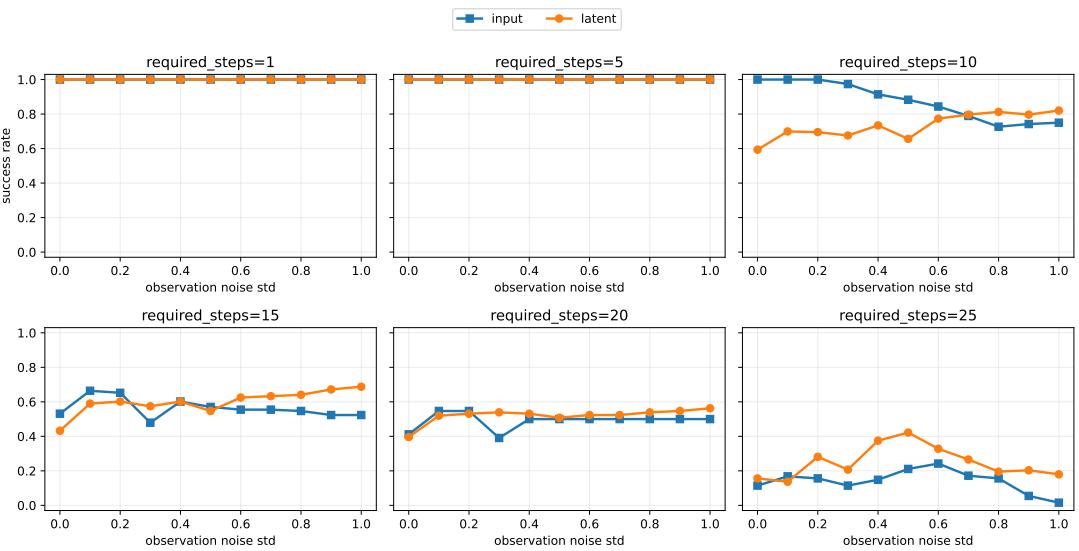
中高相关;详见方法、贡献和实验边界。
方法:给 JEPA 目标作 conditional spectral graph learning 解释,帮助理解 JEPA dynamics 泛化
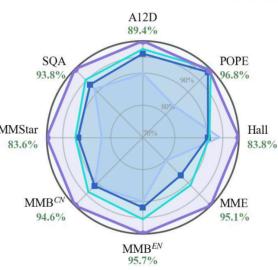
中高相关;详见方法、贡献和实验边界。
方法:从信息论重写视觉 token 保留目标,适合关注 VLM 视觉 token 预算
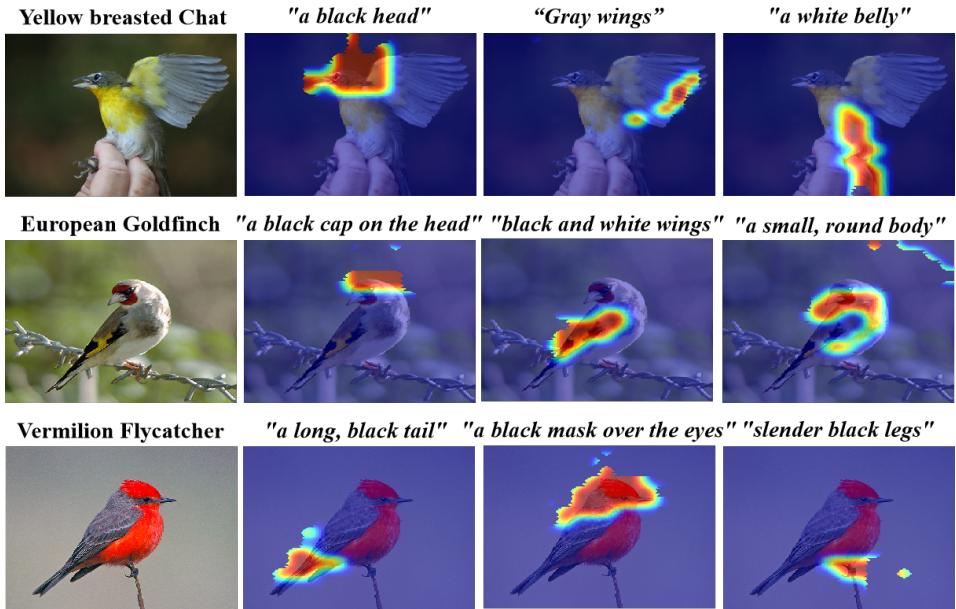
中高相关;详见方法、贡献和实验边界。
方法:把概念对齐从全局 cosine 改成 OT semantic flow,更适合分析细粒度视觉语义几何
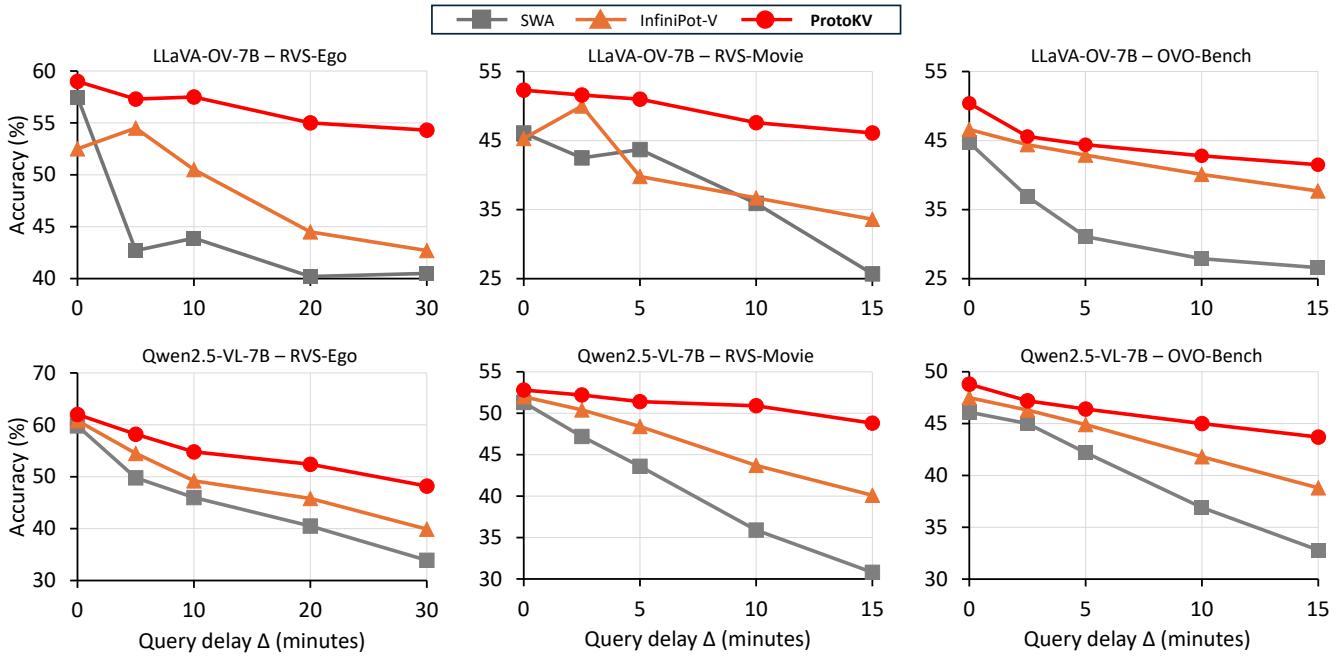
中高相关;详见方法、贡献和实验边界。
方法:用 prototype bank 维护长视频语义-空间记忆,对视频 token 压缩和长期表征有参考价值
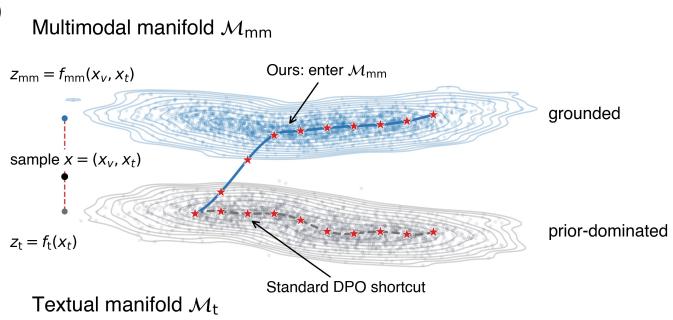
中高相关;详见方法、贡献和实验边界。
方法:把 MLLM hallucination 归因到 visual laziness,并用反事实视觉对齐纠正语言捷径
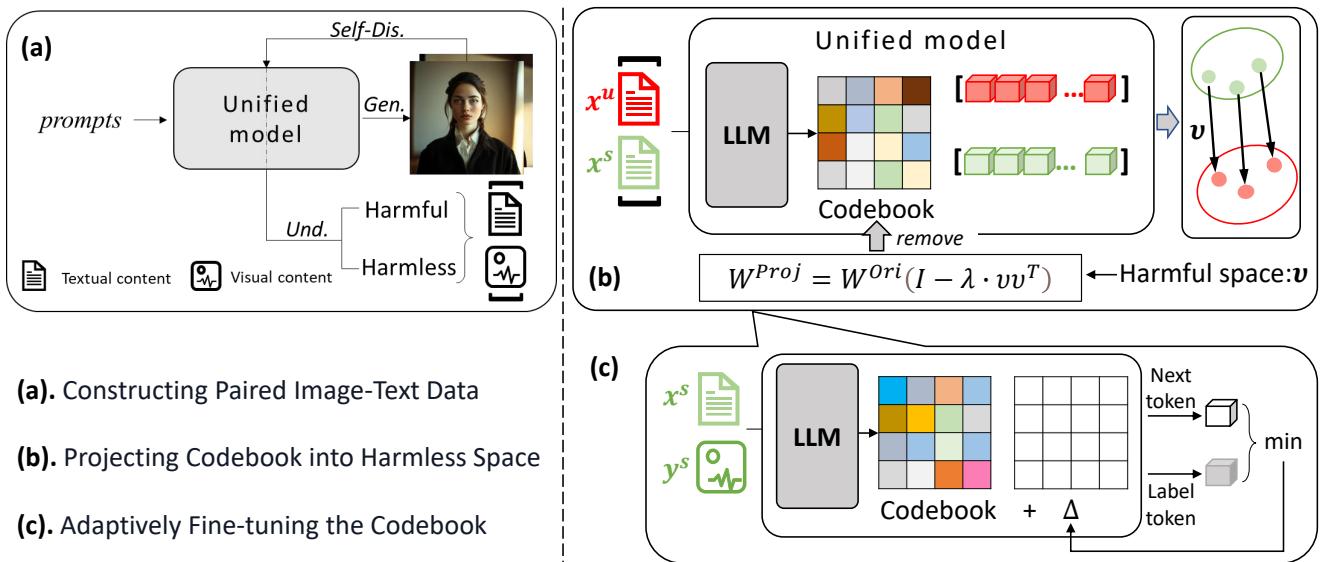
中相关;详见方法、贡献和实验边界。
方法:主要是安全生成,但自改进 codebook 直接操作离散视觉 token 表征
中相关;详见方法、贡献和实验边界。
方法:目标是解释 vision foundation model activations,适合作为 VFM 表征诊断工具背景
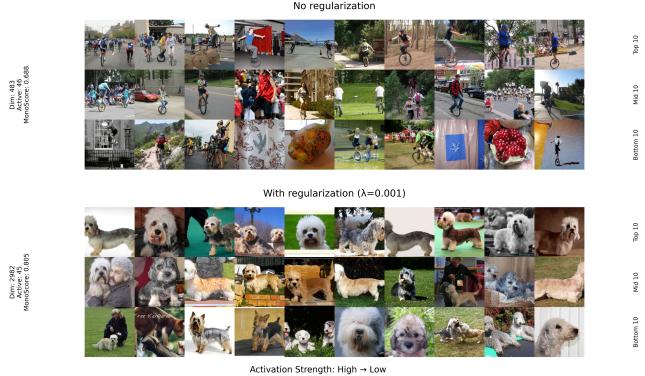
高相关;详见方法、贡献和实验边界。
方法:把 JEPA 从单模态推进到共享音视频 encoder,直接服务大规模视频自监督表征
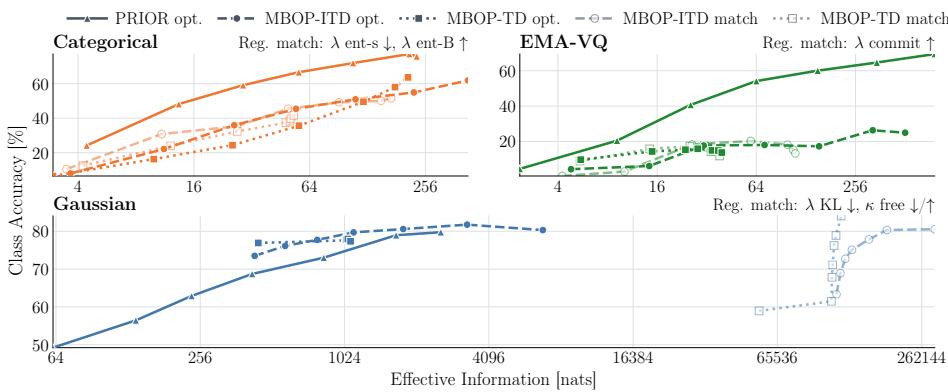
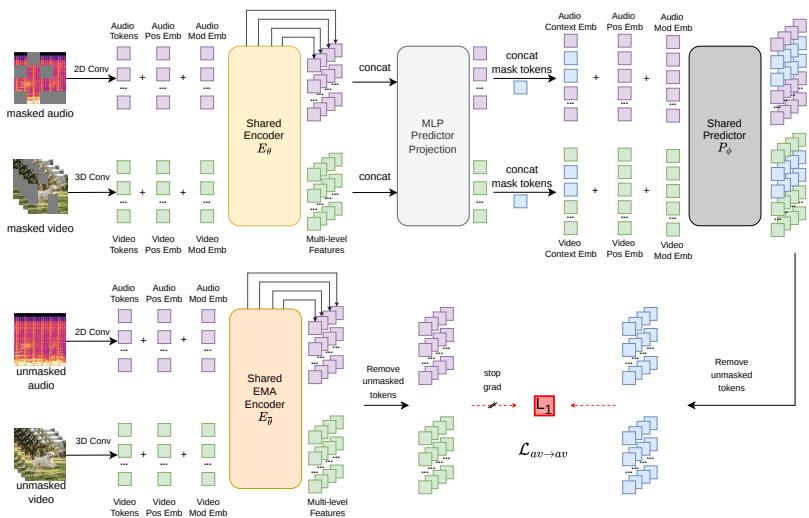
高相关;详见方法、贡献和实验边界。
方法:用 residual predictors 让 token budget 从粗到细承载信息,可直接启发可压缩视觉表征
高相关;详见方法、贡献和实验边界。
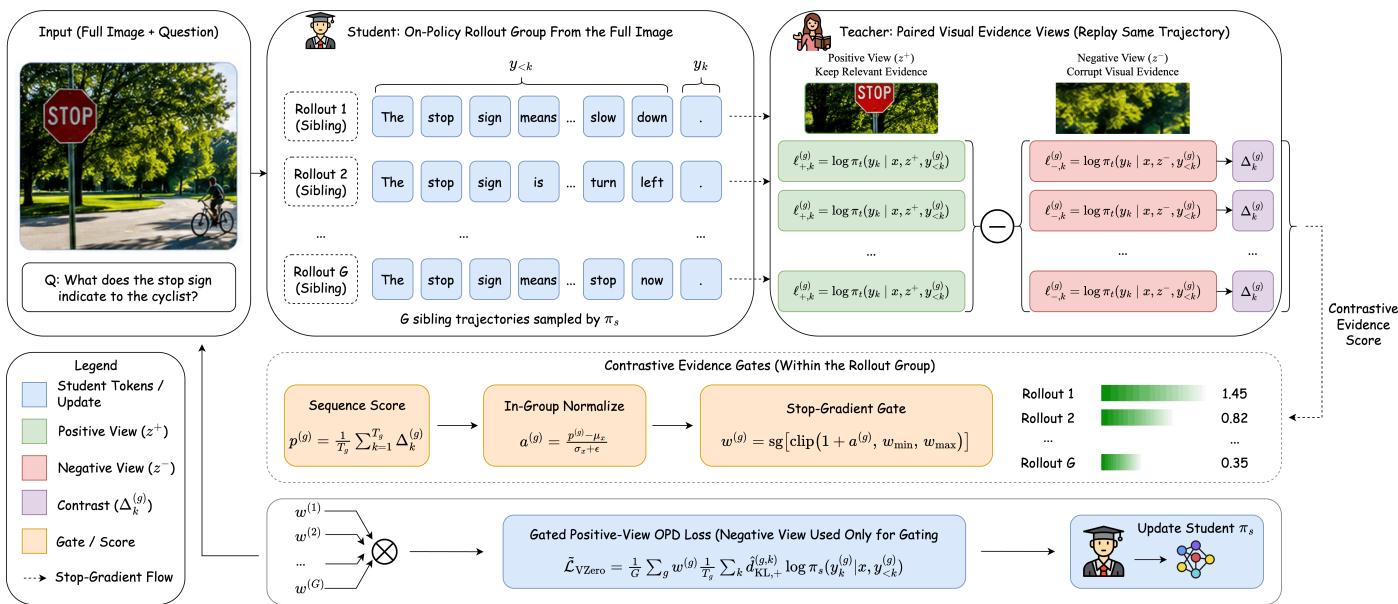
方法:把 on-policy distillation 和负视觉视图 gating 结合,减少对答案标注的依赖
高相关;详见方法、贡献和实验边界。
方法:关注 CLIP 视频适配时表征几何偏移,OpenReview 旧状态为 ICLR 2026 withdrawn
中高相关;详见方法、贡献和实验边界。
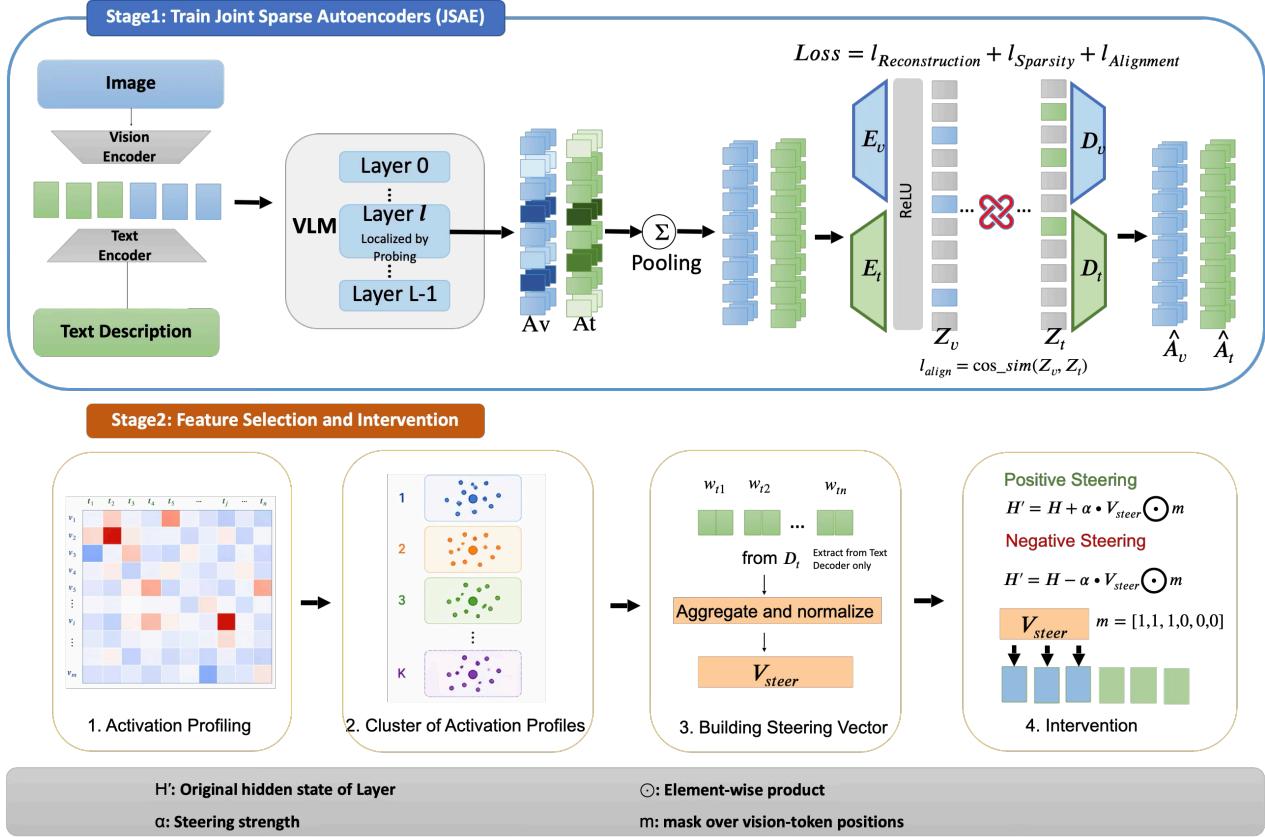
方法:把 SAE 做成显式跨模态对齐的 steerable features,适合诊断视觉语言表征
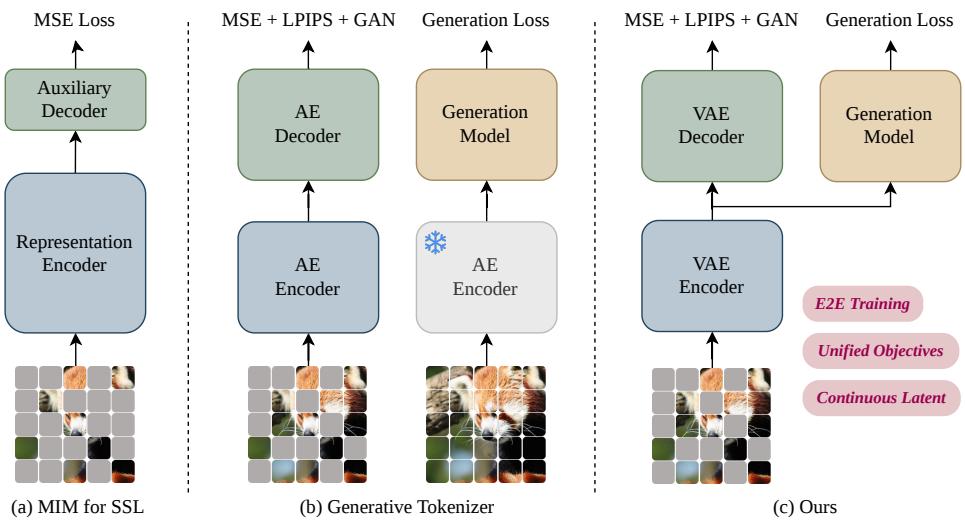
中高相关;详见方法、贡献和实验边界。
方法:把 MIM latent semantics 接入 normalizing flows,线性 probe 与生成指标都有报告
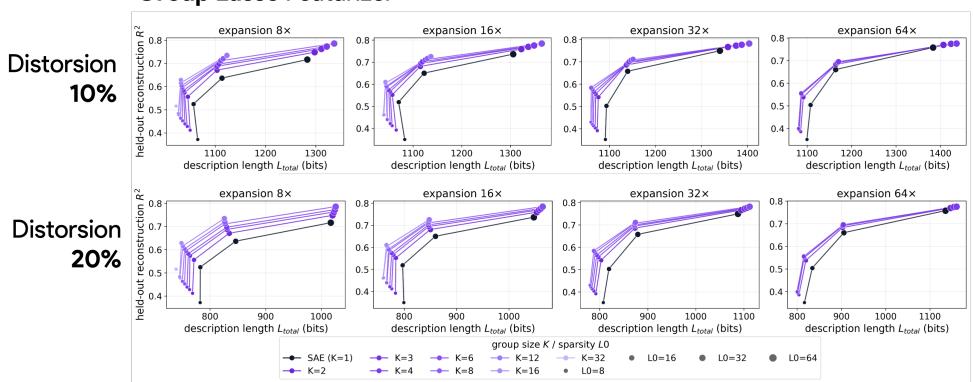
中高相关;详见方法、贡献和实验边界。
方法:从单方向概念转向低维概念流形,并在 DINOv3/扩散模型里做可解释控制
中高相关;详见方法、贡献和实验边界。
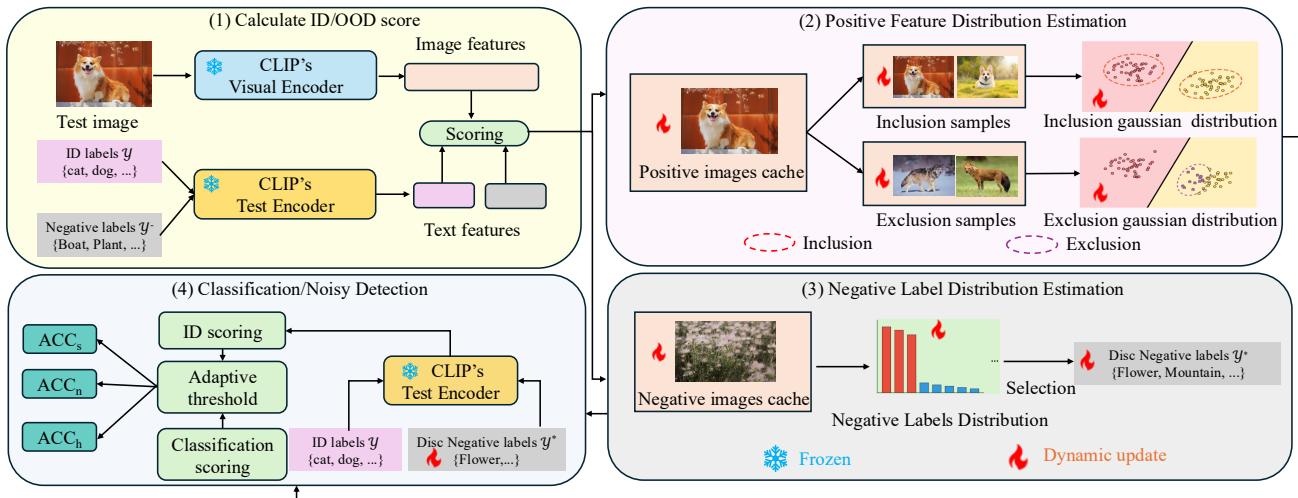
方法:用正/负分布建模提升 zero-shot noisy TTA,强调视觉语言特征空间的鲁棒校准
中相关;详见方法、贡献和实验边界。
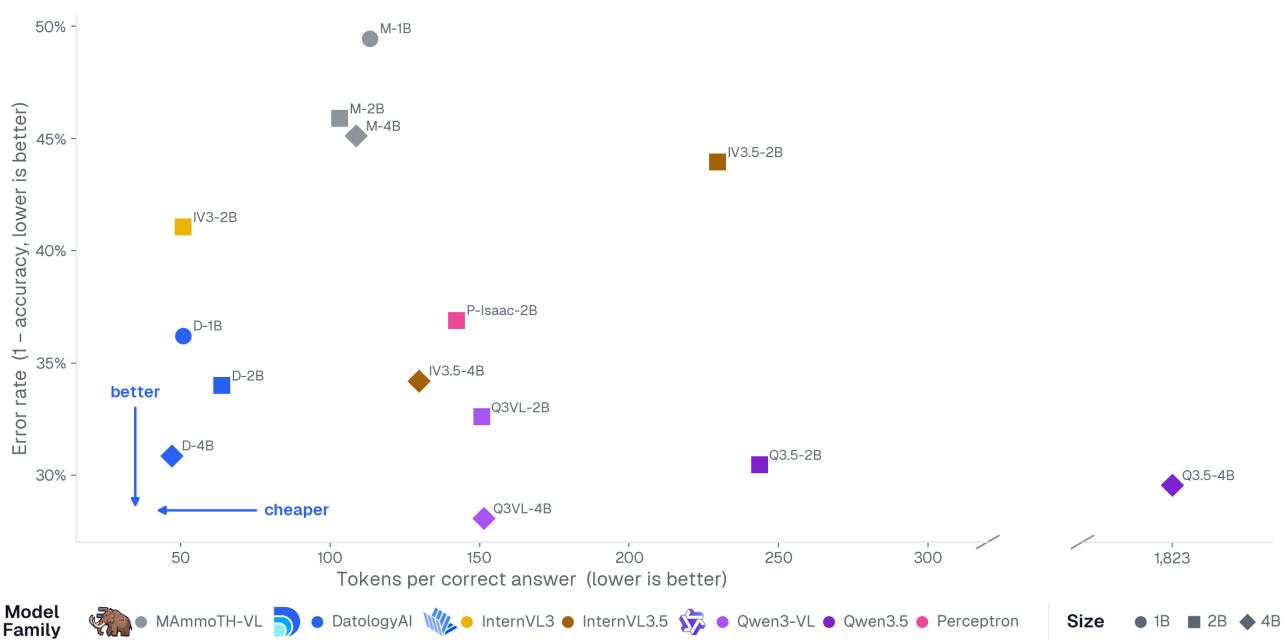
方法:把 VLM 输出长度和正确率一起纳入预训练数据策展,提示数据质量会改变推理成本
中相关;详见方法、贡献和实验边界。
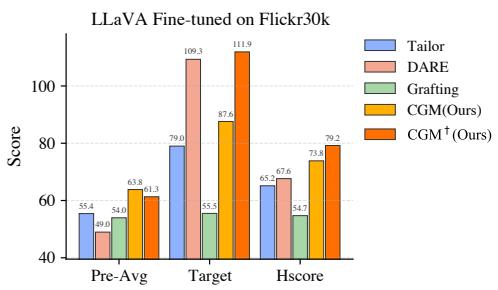
方法:不是 SSL 表征论文,但 teacher/self-forcing 的视频蒸馏 recipe 对视频基础模型有参考价值
中相关;详见方法、贡献和实验边界。
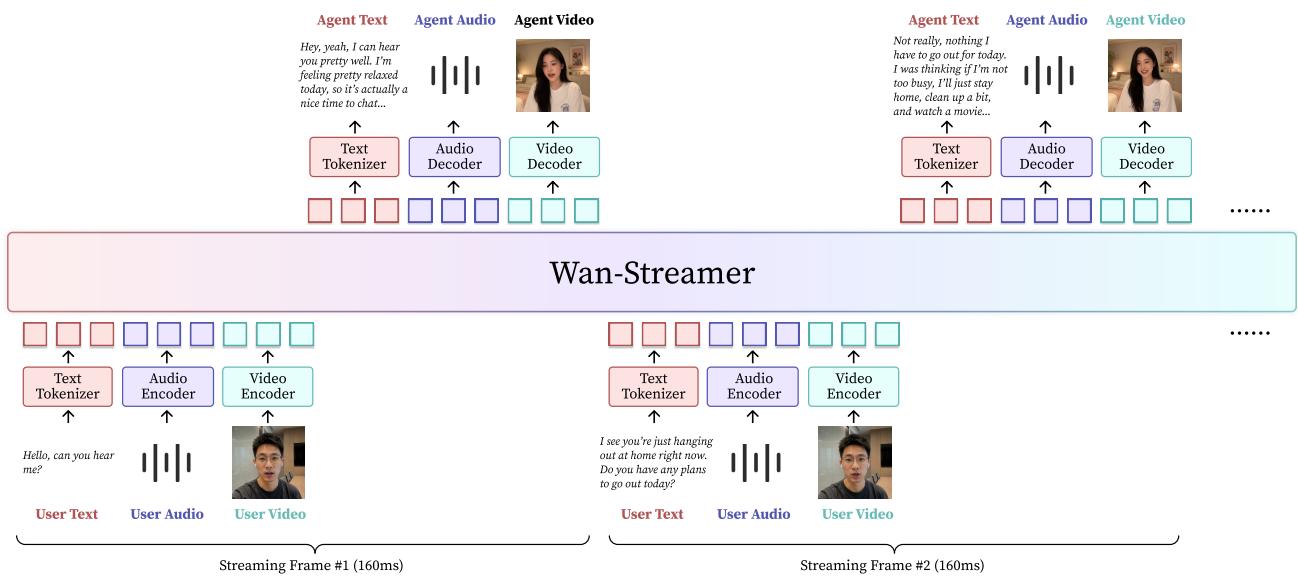
方法:偏机器人 VLA,但 advantage-guided action-space self-distillation 可作为多模态策略适配参考
中相关;详见方法、贡献和实验边界。
方法:全双工音视频文本流式基础模型,离 SSL 较远,但对视频/多模态 token 调度有背景价值
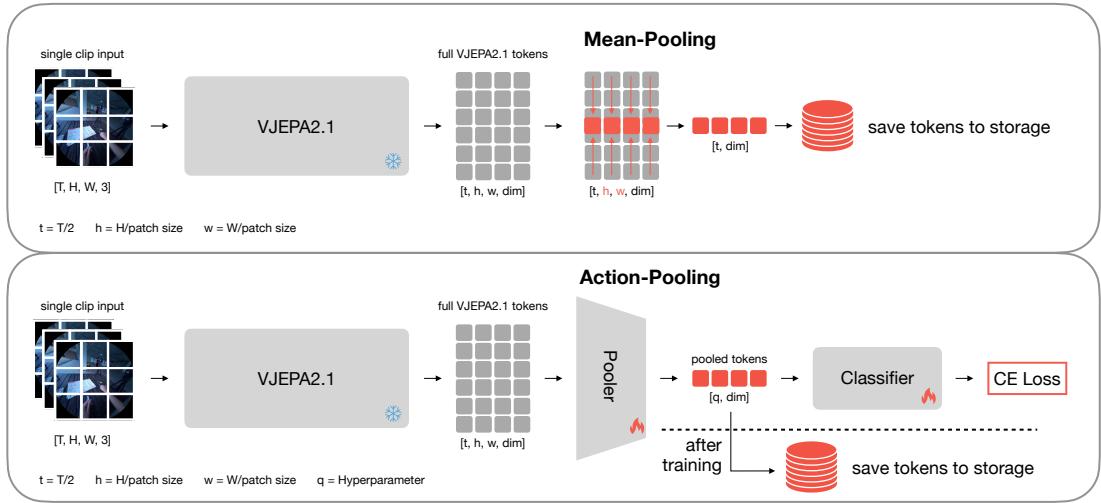
高相关;详见方法、贡献和实验边界。
方法:把 JEPA 式预测目标改造成长时程 procedural video 表征学习,是今天最贴近通用视频 SSL 的主线
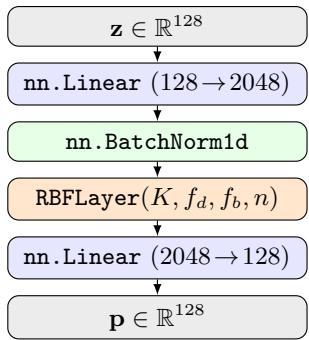
高相关;详见方法、贡献和实验边界。
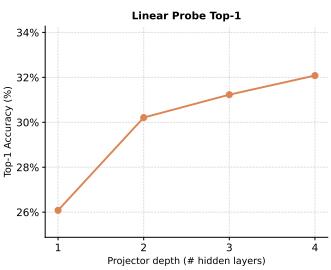
方法:直接改 SimCLR/BYOL/MoCo/SwAV/SimSiam 的 projection head,并用 RBF 参数估计表征质量
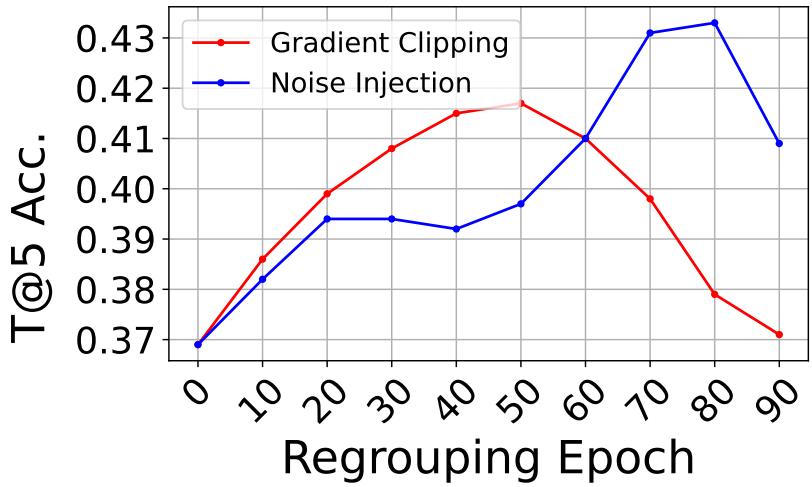
高相关;详见方法、贡献和实验边界。
方法:给跨模态对比学习定义 memorization 度量,指出文本语义错配是主要记忆化来源
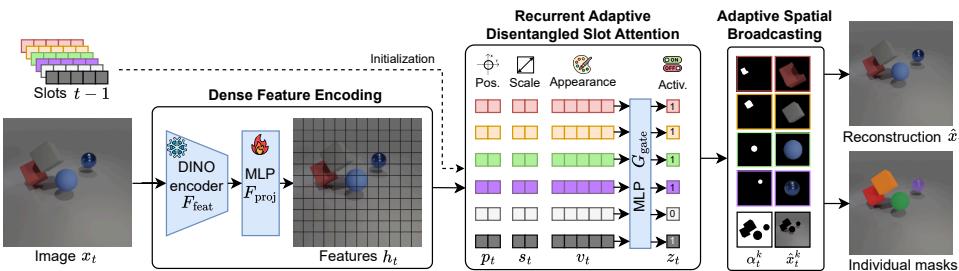
高相关;详见方法、贡献和实验边界。
方法:解释 slot temporal consistency 为什么会锁背景,并用 appearance/pose 解耦修复视频对象表征
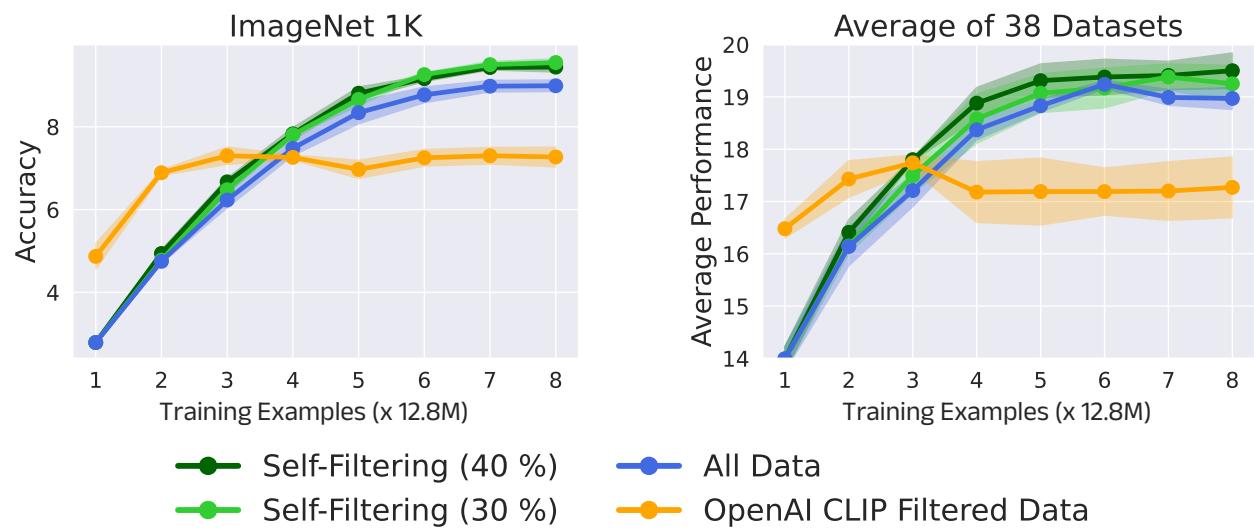
高相关;详见方法、贡献和实验边界。
方法:让 CLIP 在训练过程中自举选择 clean + diverse 数据,是视觉语言预训练数据闭环的实用方向
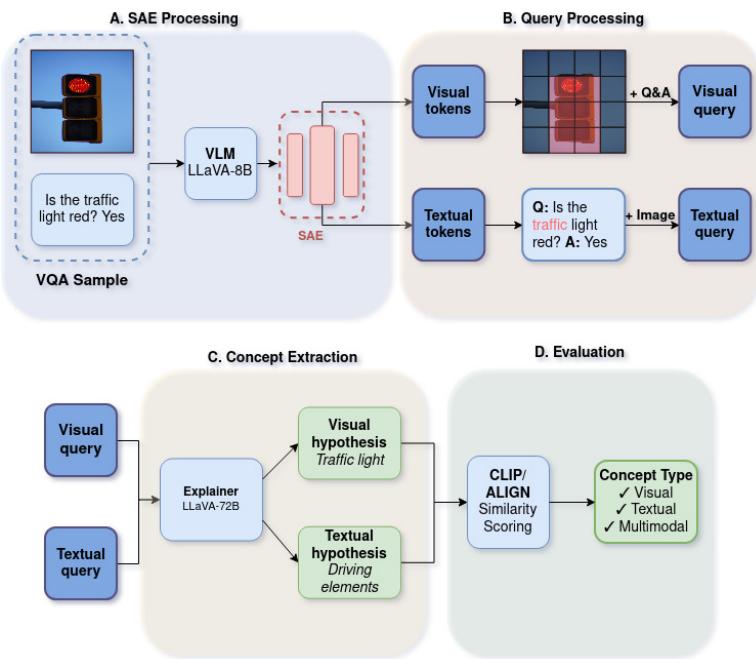
中高相关;详见方法、贡献和实验边界。
方法:把 SAE 从文本或纯视觉概念扩展到 multimodal concepts,有助于理解 VLM 表征结构
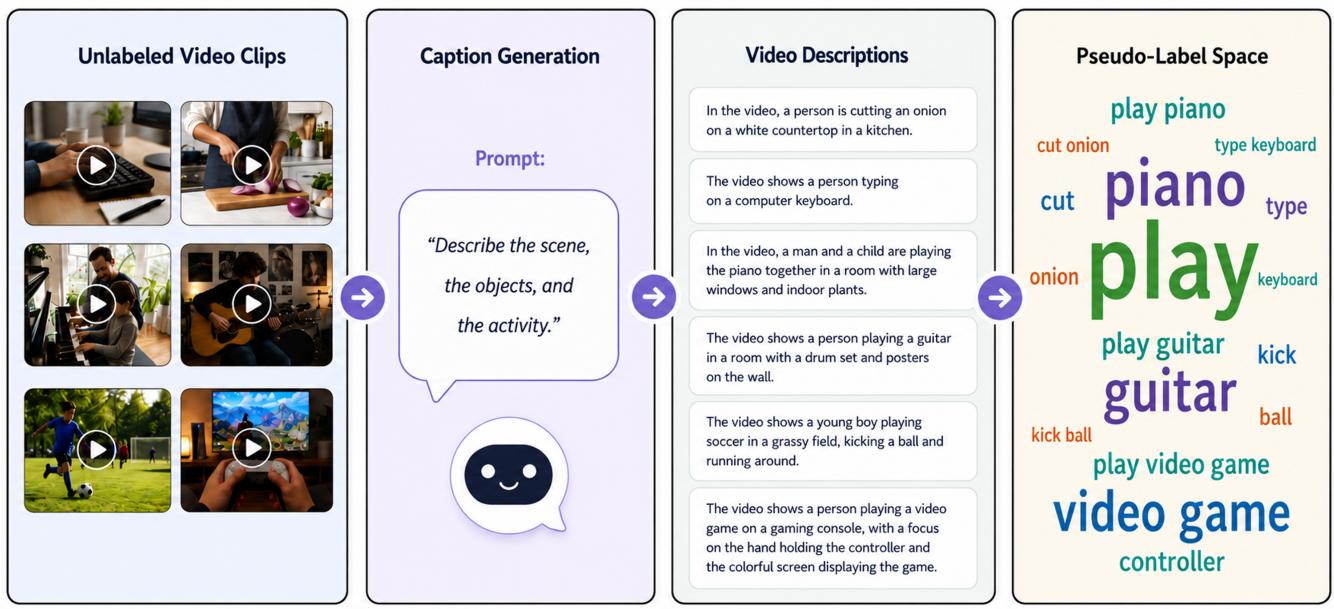
中高相关;详见方法、贡献和实验边界。
方法:用 VLM 生成语义 pseudo-label space 训练视频 encoder,是低标注视频预训练的可迁移思路
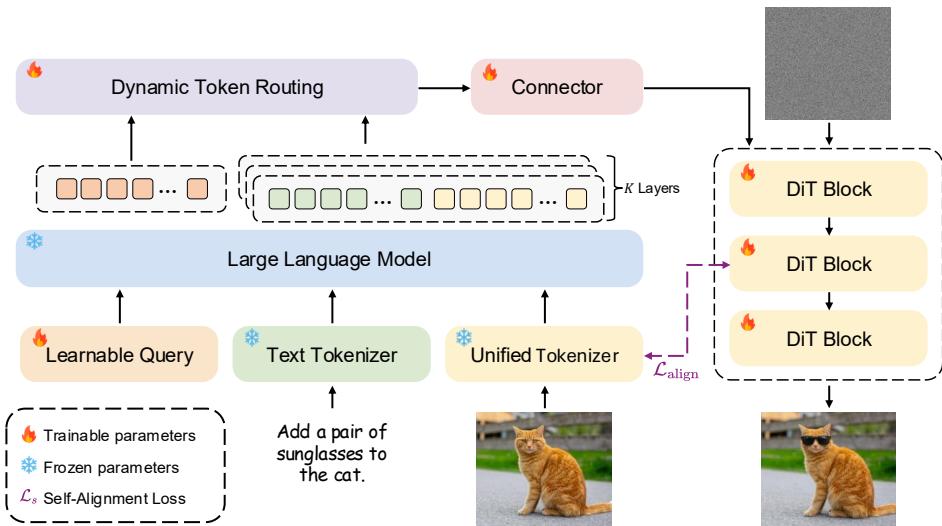
中高相关;详见方法、贡献和实验边界。
方法:试图把语义理解特征和像素重建特征放到统一 tokenizer/路由框架,和 RAE/VAE-for-DiT 线索相关
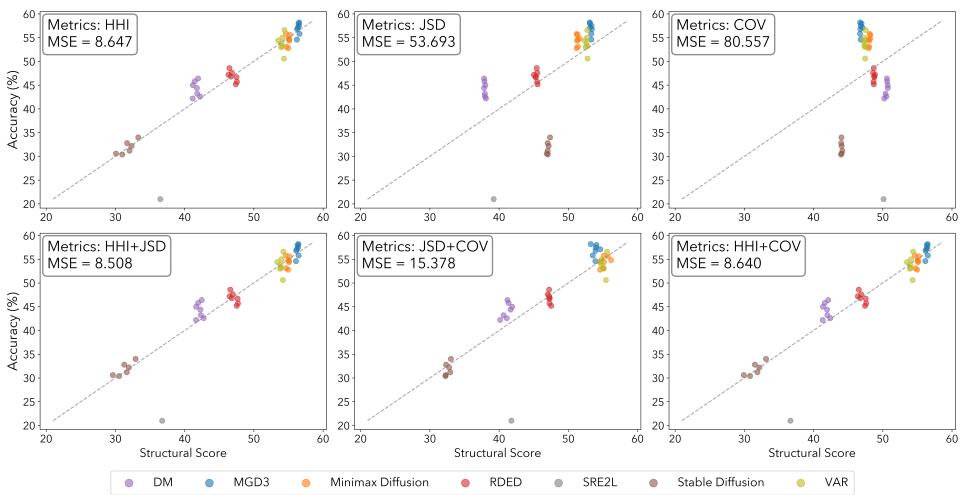
中高相关;详见方法、贡献和实验边界。
方法:用离散视觉 tokenizer 分析蒸馏数据的 compositional structure,可作为表征/数据质量诊断工具
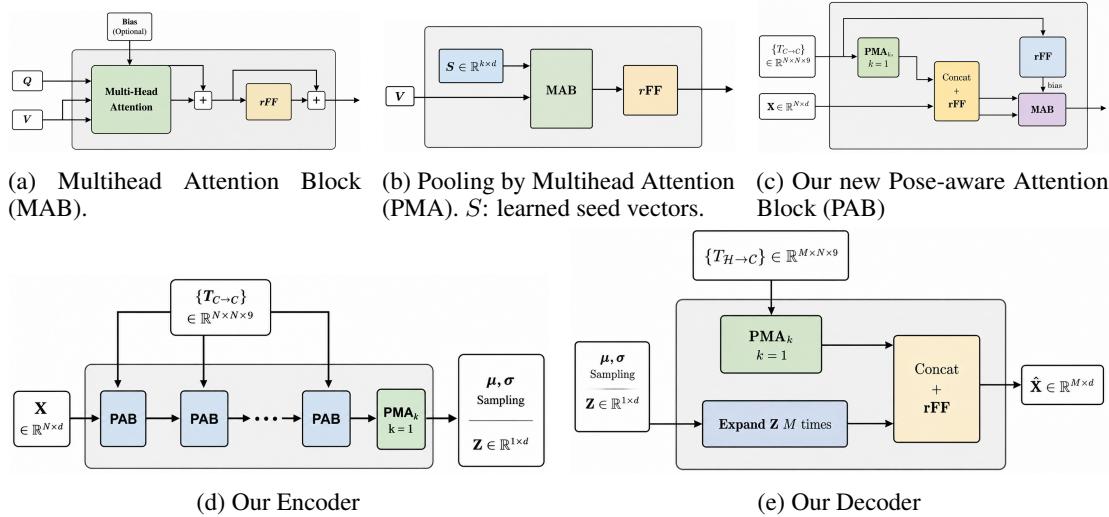
中相关;详见方法、贡献和实验边界。
方法:把 2D foundation embeddings 反演成 3D semantic latent,方法对 self-supervised embeddings 兼容
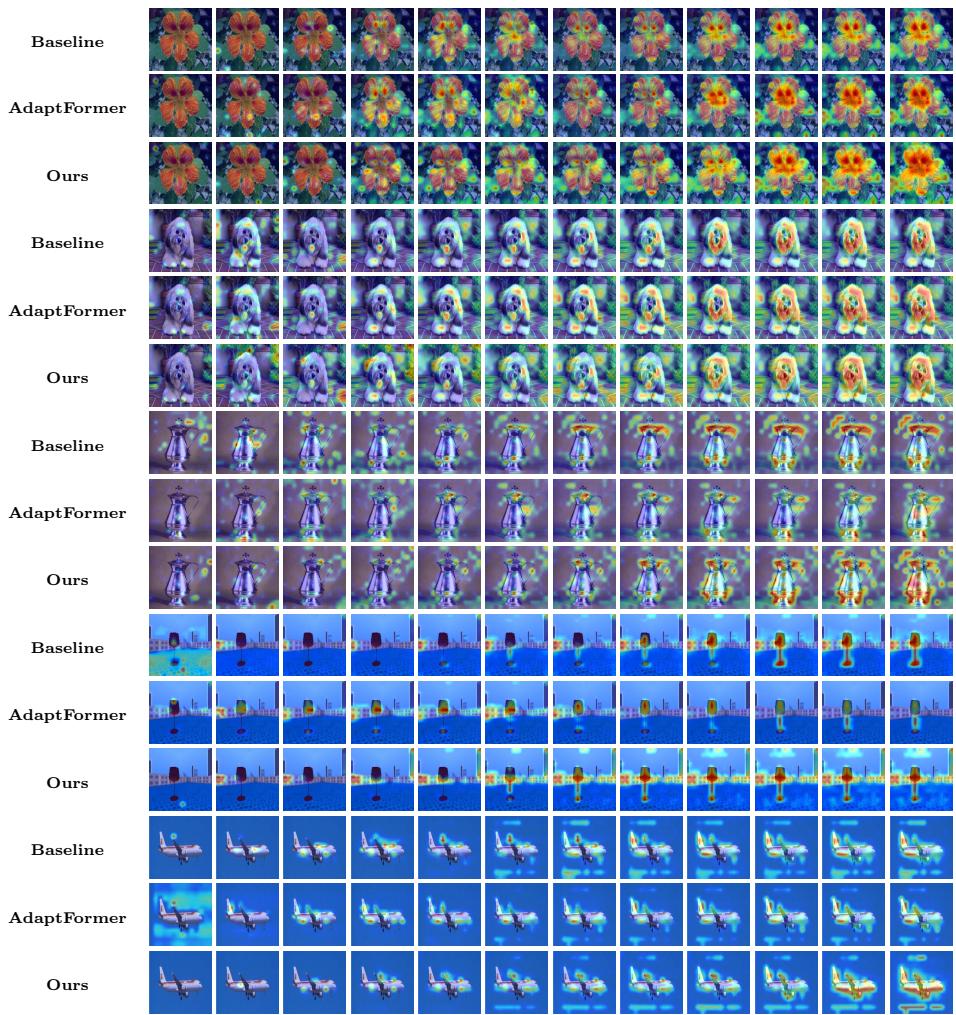
中相关;详见方法、贡献和实验边界。
方法:不是自监督训练目标,但关注 ViT token 关系和高效适配,对 VFM 下游迁移有参考价值
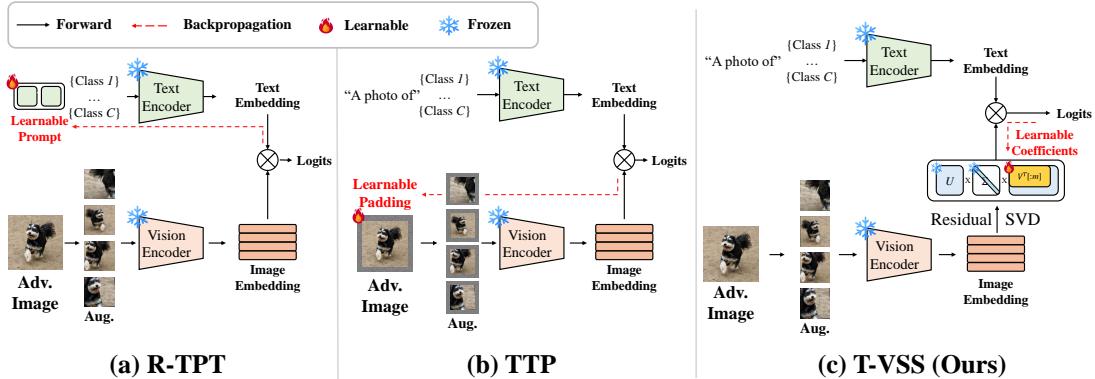
中相关;详见方法、贡献和实验边界。
方法:直接在视觉 feature space 做 test-time correction,提醒 VLM 鲁棒性不应只调 prompt
中相关;详见方法、贡献和实验边界。
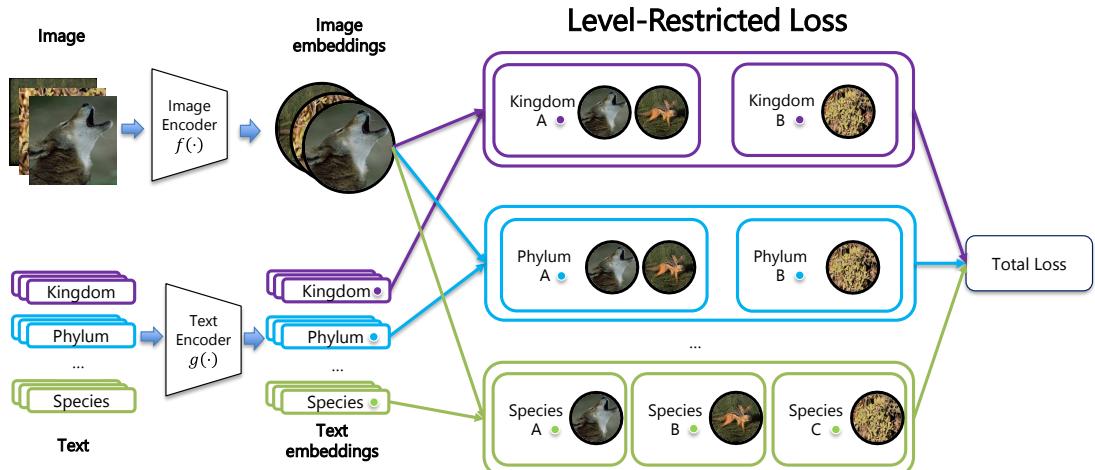
方法:TreeOfLife/BioCLIP 应用较垂直,但 level-restricted contrastive comparison 是处理 false negatives 的可迁移想法
高相关;详见方法、贡献和实验边界。
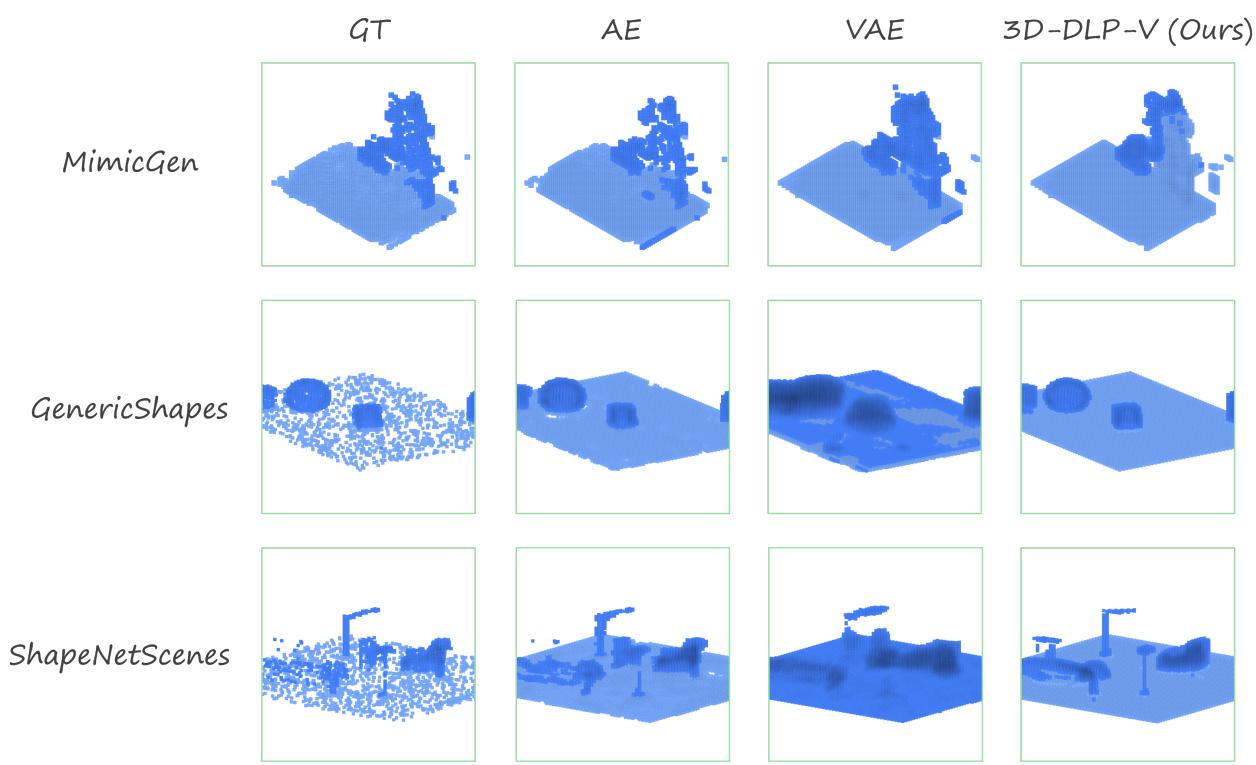
方法:仍是上一批最贴近通用视觉 SSL 的对象中心 3D 表征论文,值得先精读
高相关;详见方法、贡献和实验边界。
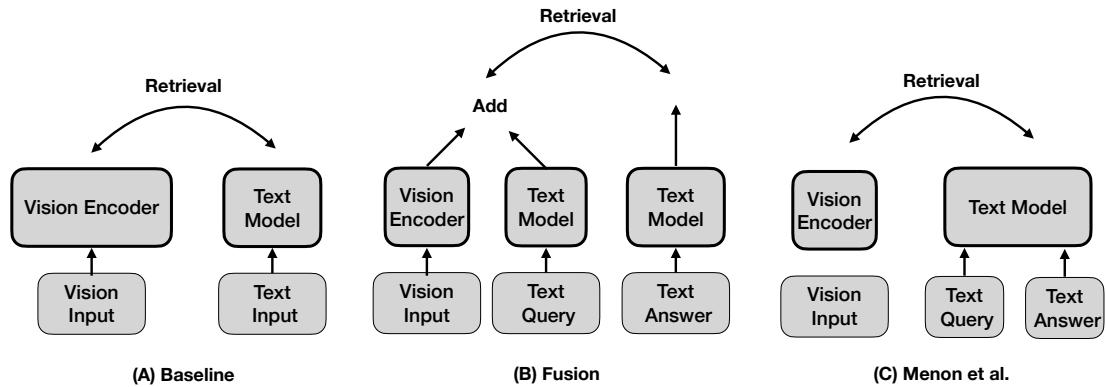
方法:把语言从 decoder 消费信号变成视觉 encoder 控制信号,是静态 VFM 之外的 adaptive representation 路线
高相关;详见方法、贡献和实验边界。
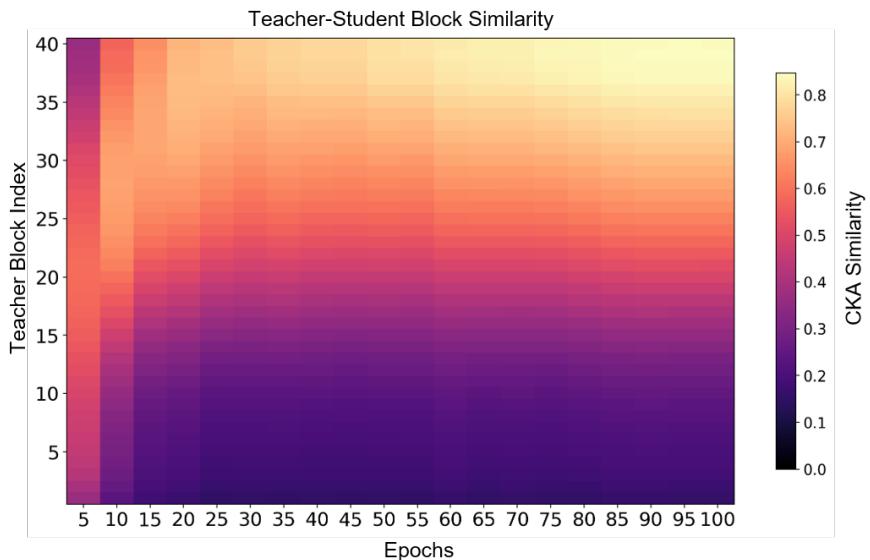
方法:用教师中间层组织课程学习,缓解小 ViT 直接模仿 DINOv2/VFM 高层特征的容量落差
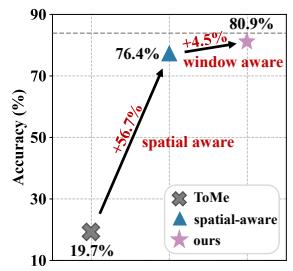
高相关;详见方法、贡献和实验边界。
方法:提醒视觉 SSM/Mamba 压缩不能只看 token 重要性,还必须保持二维空间拓扑
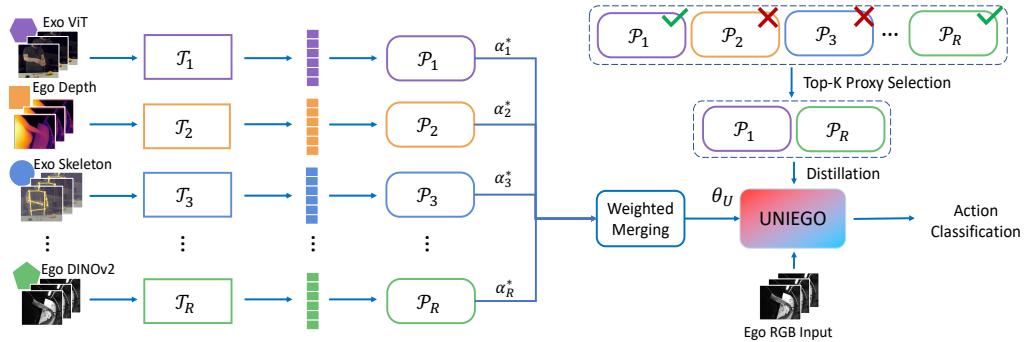
中高相关;详见方法、贡献和实验边界。
方法:用 proxy 层调和 ego/exo、多模态和多个 foundation teacher,是视频 SSL 蒸馏的实用路线
高相关;详见方法、贡献和实验边界。
方法:仍是上一批最贴近通用视觉 SSL 的对象中心 3D 表征论文,值得先精读
高相关;详见方法、贡献和实验边界。
方法:把语言从 decoder 消费信号变成视觉 encoder 控制信号,是静态 VFM 之外的 adaptive representation 路线
高相关;详见方法、贡献和实验边界。
方法:用教师中间层组织课程学习,缓解小 ViT 直接模仿 DINOv2/VFM 高层特征的容量落差
高相关;详见方法、贡献和实验边界。
方法:提醒视觉 SSM/Mamba 压缩不能只看 token 重要性,还必须保持二维空间拓扑
中高相关;详见方法、贡献和实验边界。
方法:用 proxy 层调和 ego/exo、多模态和多个 foundation teacher,是视频 SSL 蒸馏的实用路线
高相关;详见方法、贡献和实验边界。
方法:无新增日的第一精读:用自监督重建学习 3D latent particles,最贴近通用视觉自监督表征
高相关;详见方法、贡献和实验边界。
方法:把语言从 decoder 消费信号变成视觉 encoder 控制信号,是静态 VFM 之外的 adaptive representation 路线
高相关;详见方法、贡献和实验边界。
方法:用教师中间层组织课程学习,缓解小 ViT 直接模仿 DINOv2/VFM 高层特征的容量落差
高相关;详见方法、贡献和实验边界。
方法:提醒视觉 SSM/Mamba 压缩不能只看 token 重要性,还必须保持二维空间拓扑
中高相关;详见方法、贡献和实验边界。
方法:用 proxy 层调和 ego/exo、多模态和多个 foundation teacher,是视频 SSL 蒸馏的实用路线
高相关;详见方法、贡献和实验边界。
方法:用自监督重建把 RGB-D/voxel 场景分解成 3D latent particles,是今天最直接的通用视觉表征学习论文
高相关;详见方法、贡献和实验边界。
方法:让语言在推理时动态指导视觉 encoder 生成任务中心 embedding,直接挑战静态视觉特征范式
高相关;详见方法、贡献和实验边界。
方法:把教师 ViT 的中间层当成自适应课程,缓解小模型直接模仿高层 DINOv2/VFM 特征的容量落差
高相关;详见方法、贡献和实验边界。
方法:说明视觉 Mamba/State Space 的 token reduction 必须保持二维网格拓扑,否则会严重损伤表征
中高相关;详见方法、贡献和实验边界。
方法:用 proxy 中介层融合 ego/exo、RGB/depth/skeleton 与多个 foundation teacher,适合作为视频 SSL 蒸馏读物
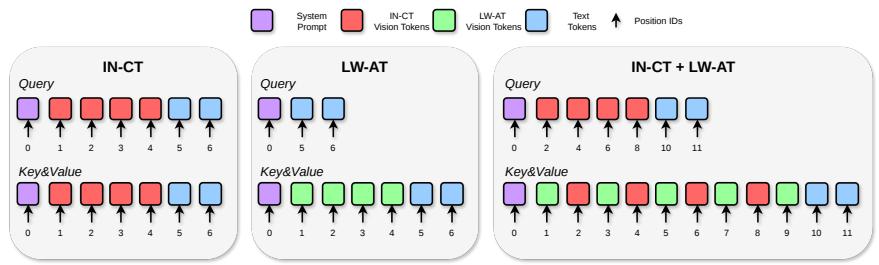
中高相关;详见方法、贡献和实验边界。
方法:比较视觉 token 作为上下文输入或层内注入时在 LLM 内部如何变成语言可用表征
中高相关;详见方法、贡献和实验边界。
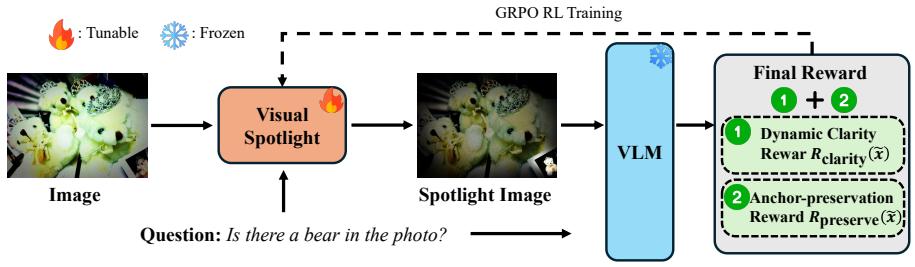
方法:用问题条件 spotlight 和 entropy shaping 让冻结 VLM 读到小而关键的视觉证据
中高相关;详见方法、贡献和实验边界。
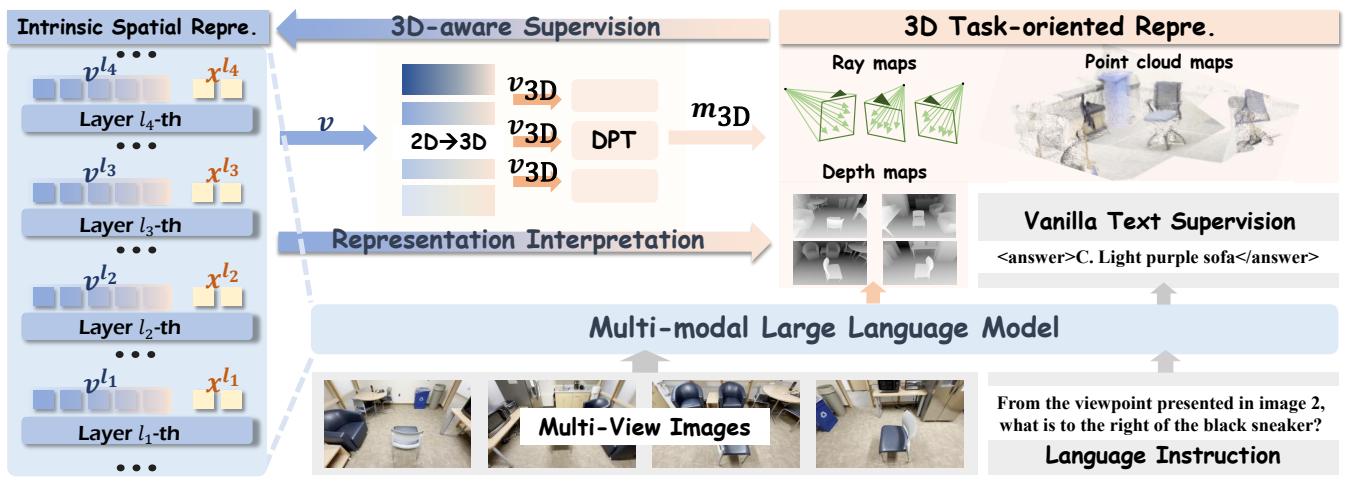
方法:把 MLLM 的 2D visual features 主动 lift 到深度、位姿、点云等显式 3D 表示
中高相关;详见方法、贡献和实验边界。
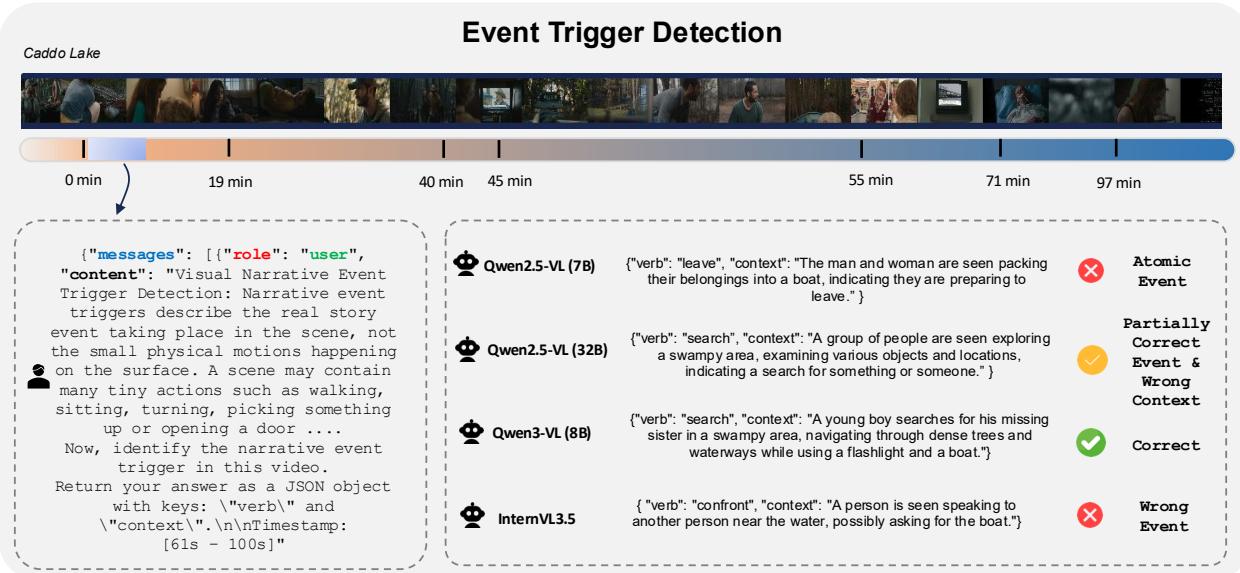
方法:以电影级长视频事件结构测试模型是否理解跨时间叙事,而不只是 needle retrieval
中高相关;详见方法、贡献和实验边界。
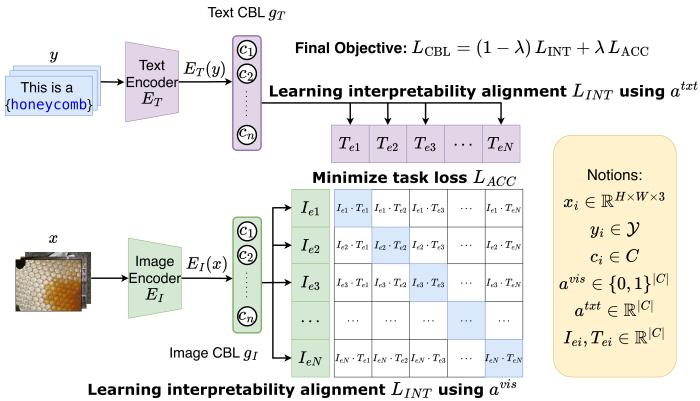
方法:把图像和文本 embedding 映射到可解释概念瓶颈,适合评估 CLIP/VLM 表征是否可解释
中相关;详见方法、贡献和实验边界。
方法:把 query 渲染进图像作为显式空间锚点,提醒 VLM 对齐可以发生在输入重构层
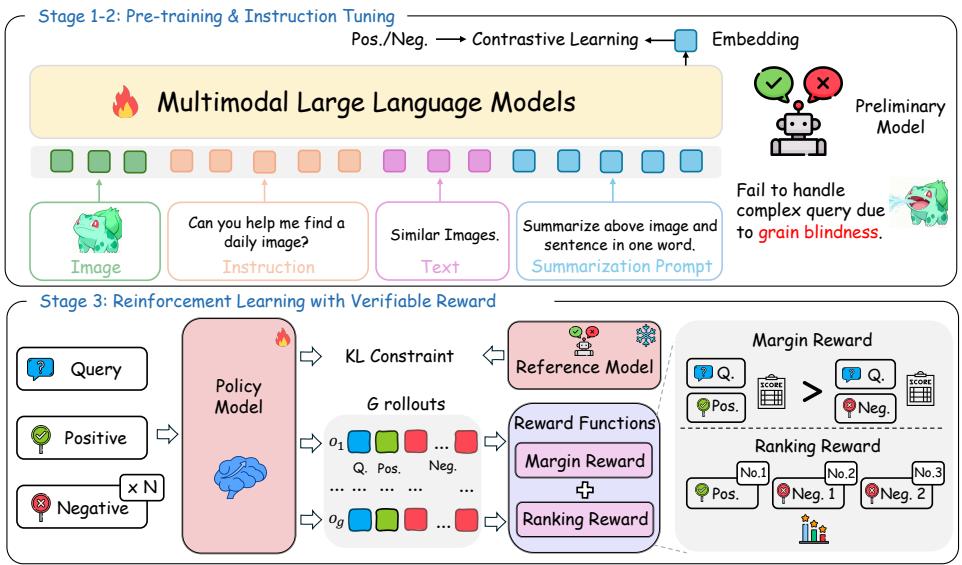
中相关;详见方法、贡献和实验边界。
方法:用 ranking-driven RLVR 缓解复杂检索 query 的 grain blindness,和视觉-语言对比学习负样本设计有关
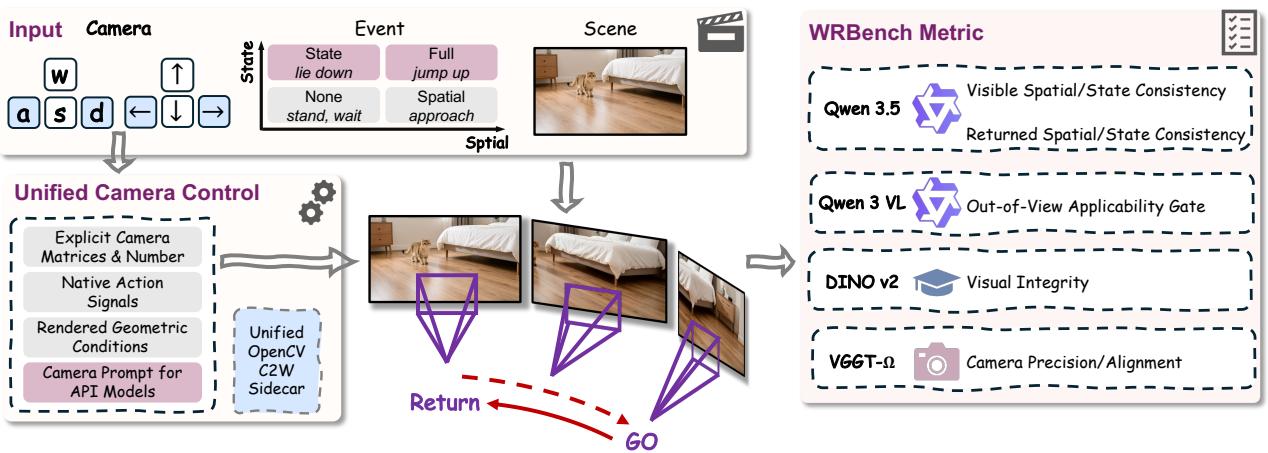
中相关;详见方法、贡献和实验边界。
方法:WRBench 追问世界模型是否在目标离开视野后继续推进状态,是视频基础模型的重要诊断
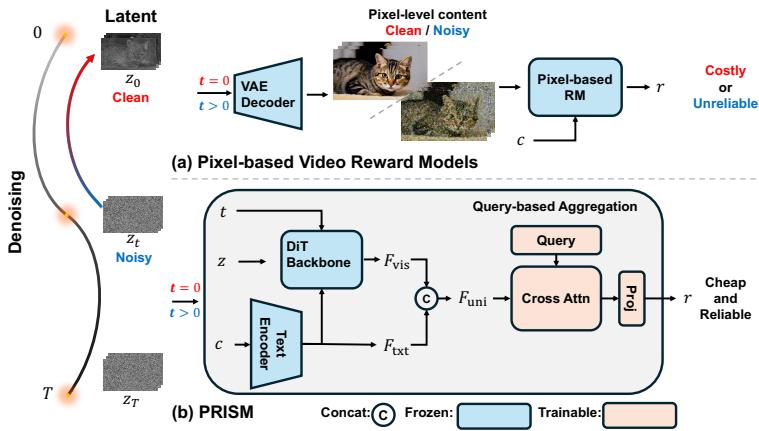
中相关;详见方法、贡献和实验边界。
方法:从冻结视频扩散模型的 noisy latents 中读出偏好信号,偏生成但涉及 latent representation 可判别性
中相关;详见方法、贡献和实验边界。
方法:用 learnable global merging 做可变长视觉 tokenization,和视觉 latent 压缩/对齐有关
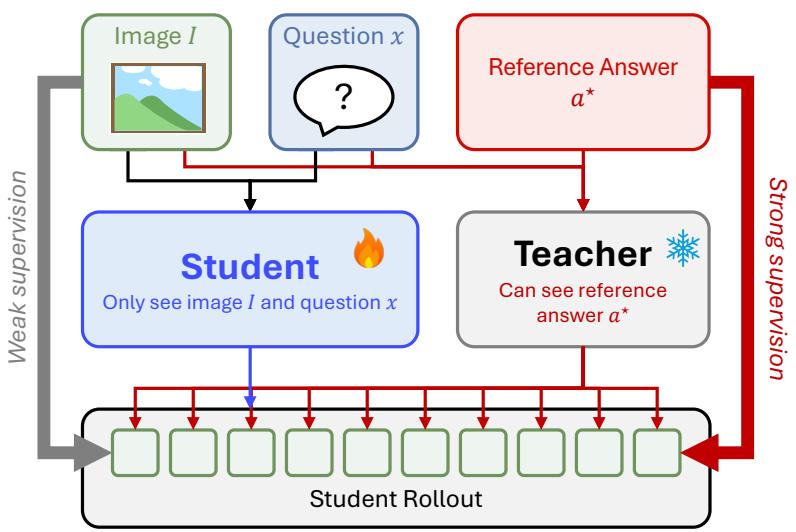
高相关;详见方法、贡献和实验边界。
方法:把 OPSD 拆成图像感知老师和推理老师,直接约束 MLLM 先看图再推理
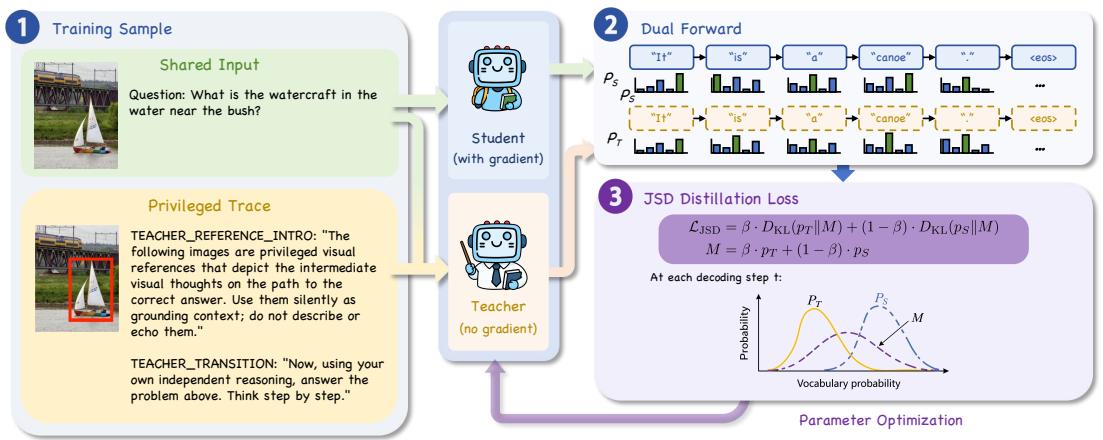
高相关;详见方法、贡献和实验边界。
方法:把昂贵 visual thoughts 的隐式推理能力蒸馏到 text-only student,适合跟 VLM 视觉 latent reasoning 一起看
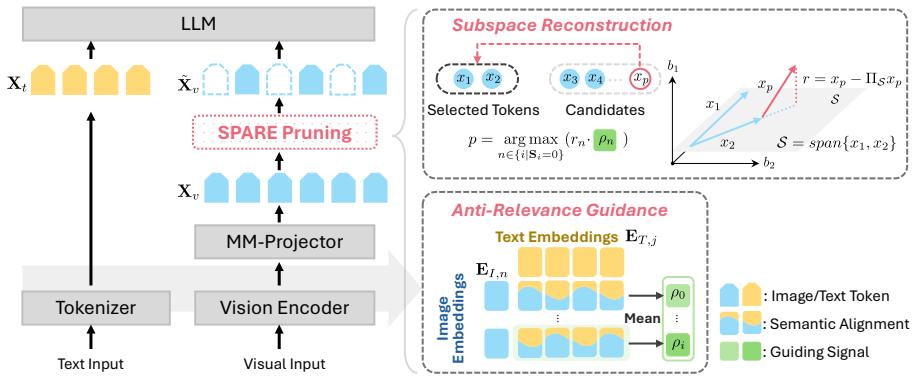
高相关;详见方法、贡献和实验边界。
方法:把视觉 token pruning 从多样性最大化改成子空间重建误差最小化,直接影响 VLM 视觉表征保真
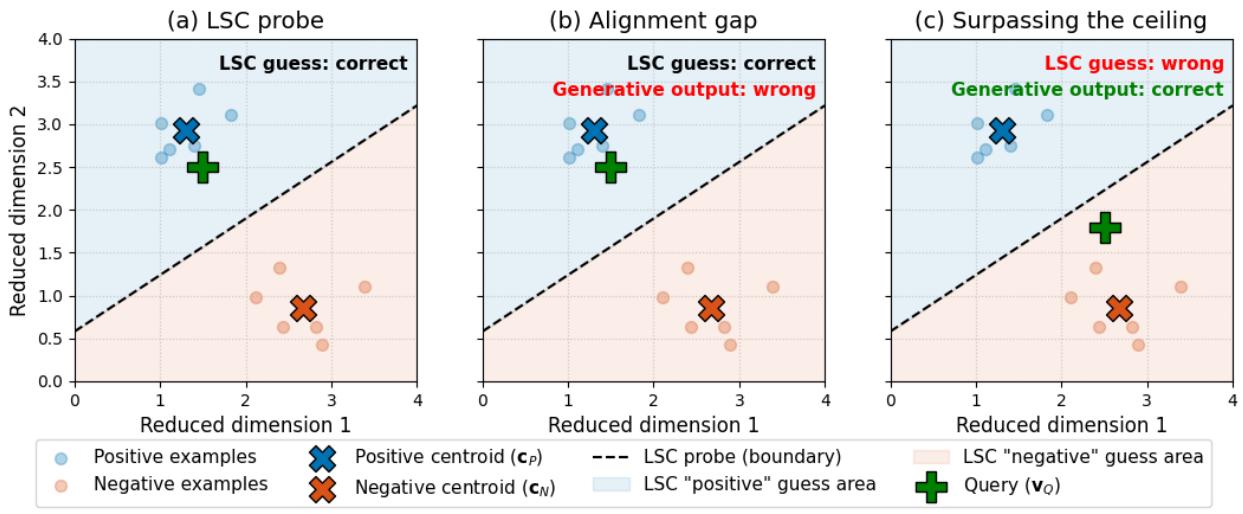
中高相关;详见方法、贡献和实验边界。
方法:用线性可分性上界诊断 VLM 是感知失败还是推理失败,并用 contrastive objective 修正视觉 manifold
中高相关;详见方法、贡献和实验边界。
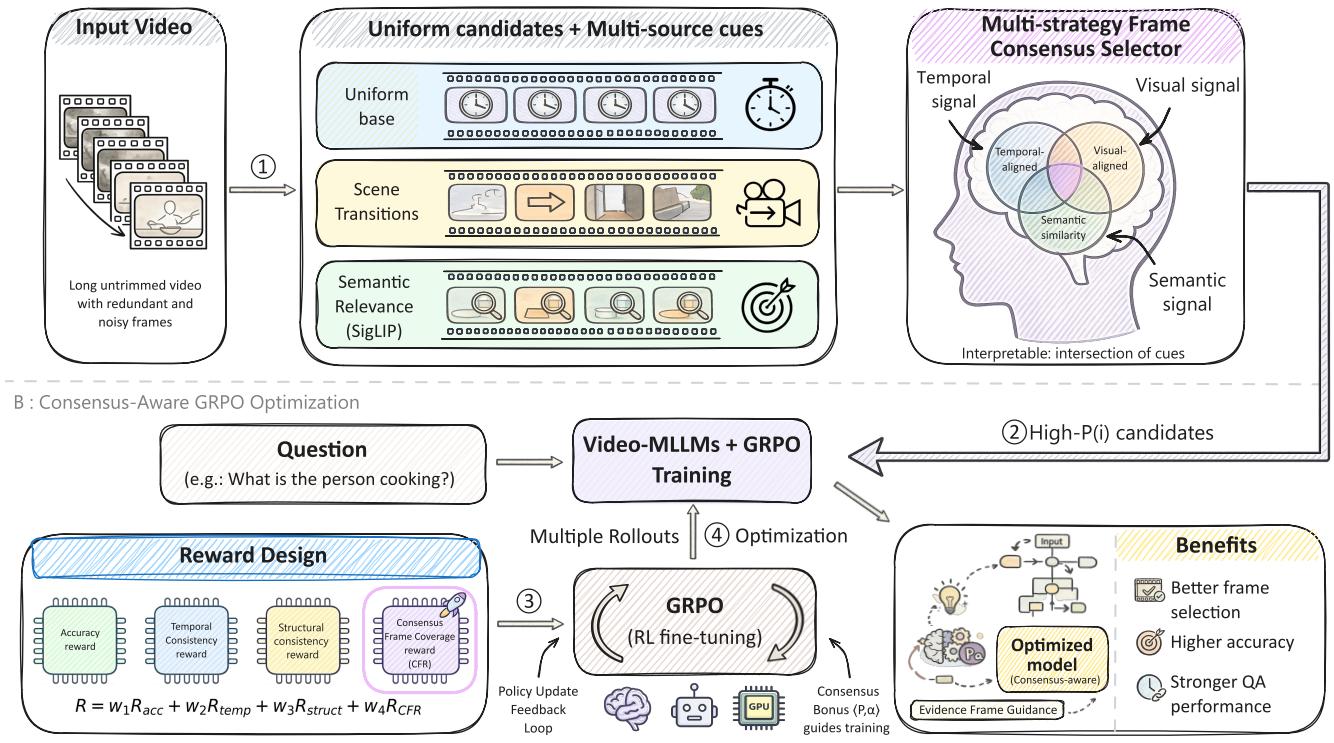
方法:用视频内生线索构造 consensus frame prior,让 Video-MLLM 学会把推理奖励绑定到证据帧
中高相关;详见方法、贡献和实验边界。
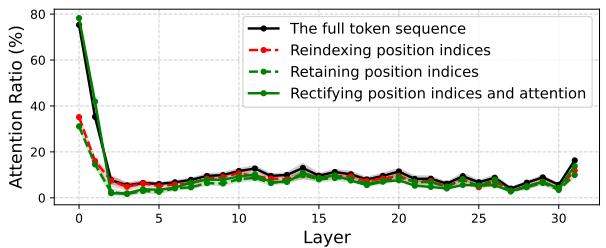
方法:校准视觉 token reduction 后的位置/注意力扭曲,是 SPARE 的强相关对照更新项
中高相关;详见方法、贡献和实验边界。
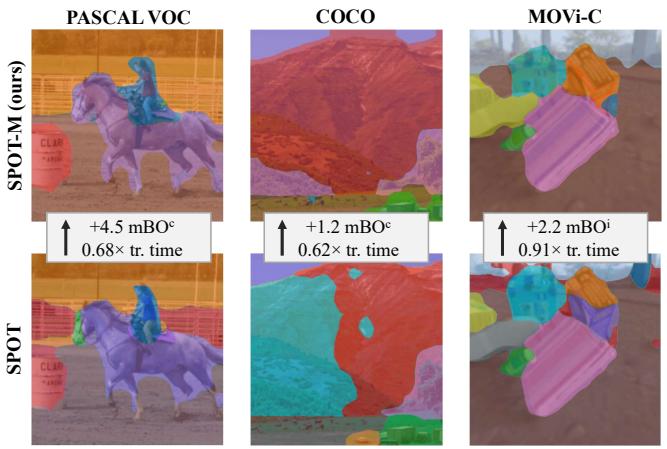
方法:把 unsupervised object-centric slot attention 从单层 ViT feature 扩展到多层语义融合
中高相关;详见方法、贡献和实验边界。
方法:双路径 representation enhancement/alignment 做视频检索,方法上涉及视觉-语言表征预训练
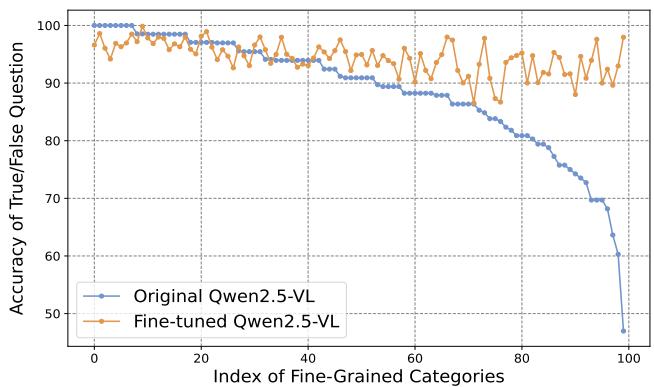
中高相关;详见方法、贡献和实验边界。
方法:用 feature-level visual discriminability 诊断 LVLM 细粒度图像失败,适合做表征评测读物
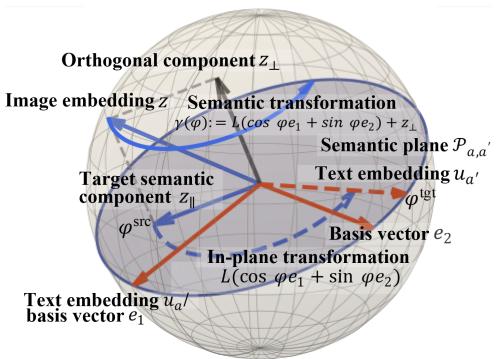
中高相关;详见方法、贡献和实验边界。
方法:把 VLM 鲁棒性认证从像素/几何扰动推进到语义扰动,和开放词表视觉表征边界有关
中相关;详见方法、贡献和实验边界。
方法:低注意力区域编码提醒视觉 encoder 的 salience bias 会损害细粒度检索
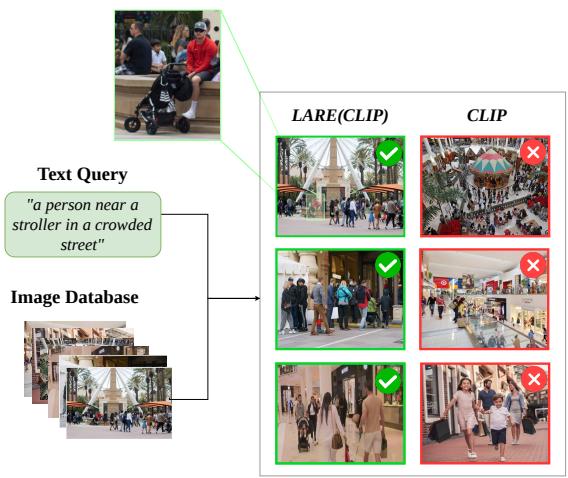
中相关;详见方法、贡献和实验边界。
方法:把视频事件拆成可见线索与物理机制绑定的 atomic transitions,适合扫读视频表征
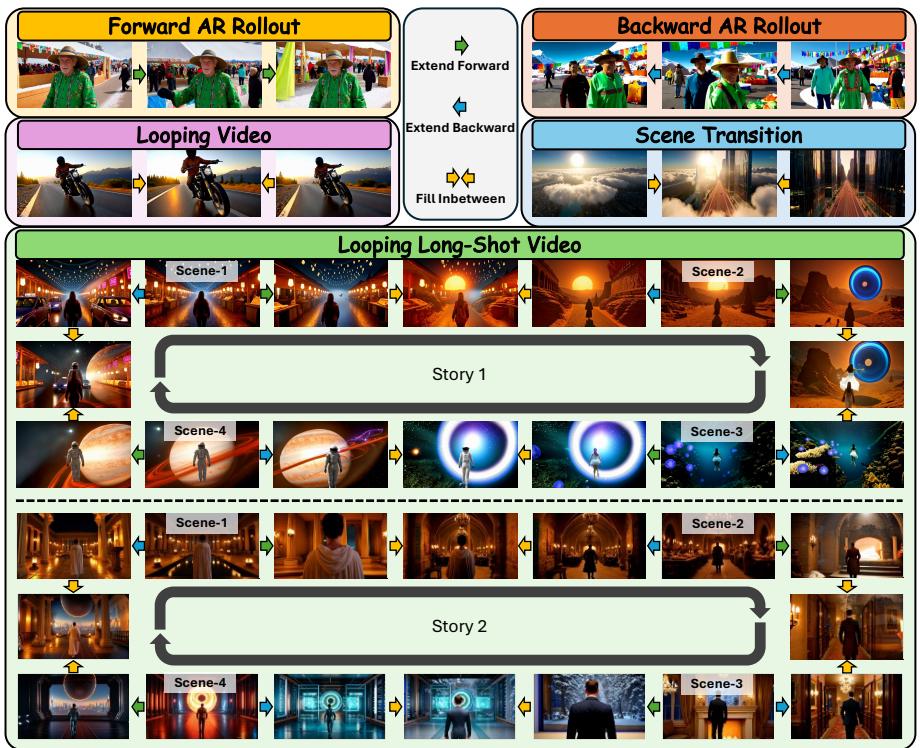
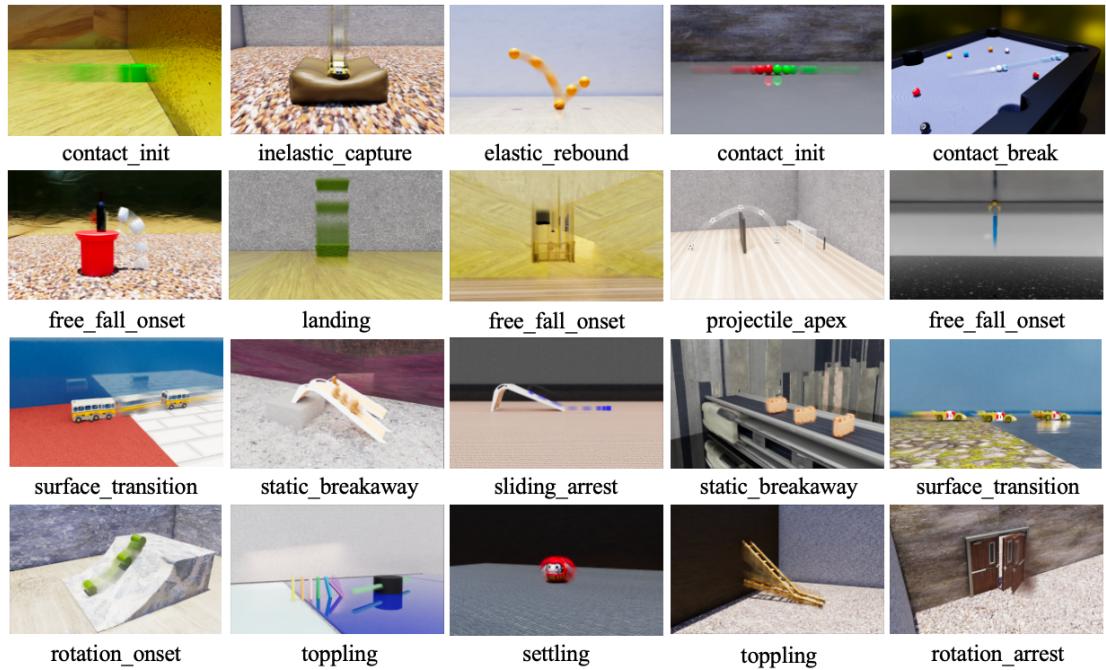
中相关;详见方法、贡献和实验边界。
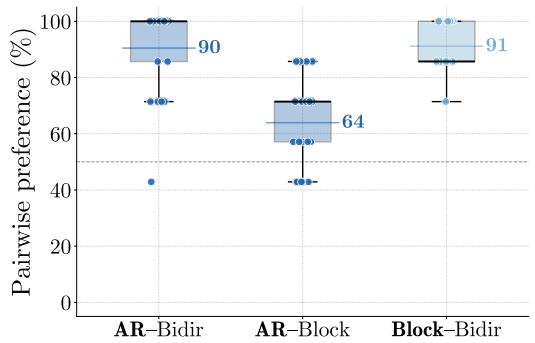
方法:任意时间顺序视频生成和 bidirectional distillation 对视频 latent 建模有间接参考
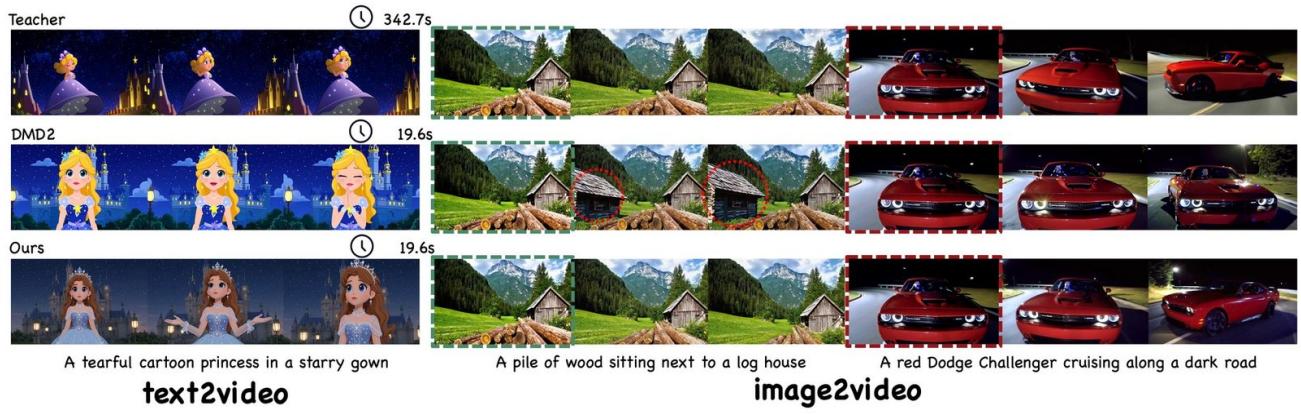
中相关;详见方法、贡献和实验边界。
方法:用 teacher score discrepancy 修复 few-step video distillation 的 mode collapse,偏生成但和蒸馏稳定性相关
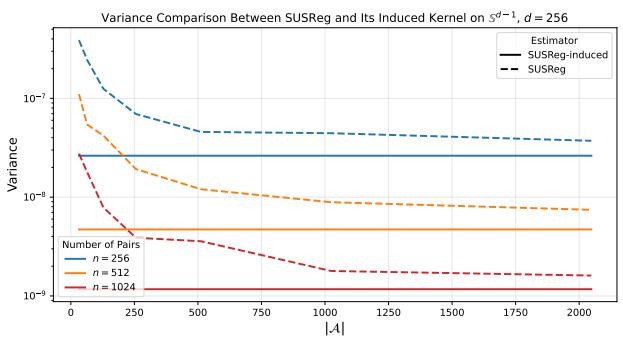
高相关;详见方法、贡献和实验边界。
方法:把 SPHERE/LeJEPA 的随机 sliced uniformity 正则改成确定性 hypersphere divergence,是今天最贴近通用 SSL 训练目标的条目
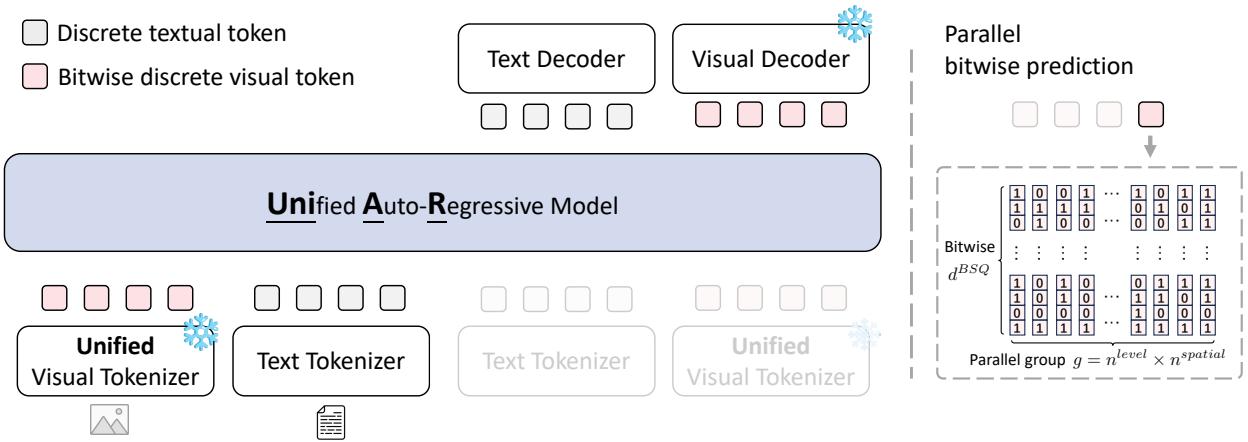
高相关;详见方法、贡献和实验边界。
方法:用共享离散视觉 tokenizer 同时服务理解和生成,直接触及视觉表征空间是否能统一的问题
高相关;详见方法、贡献和实验边界。
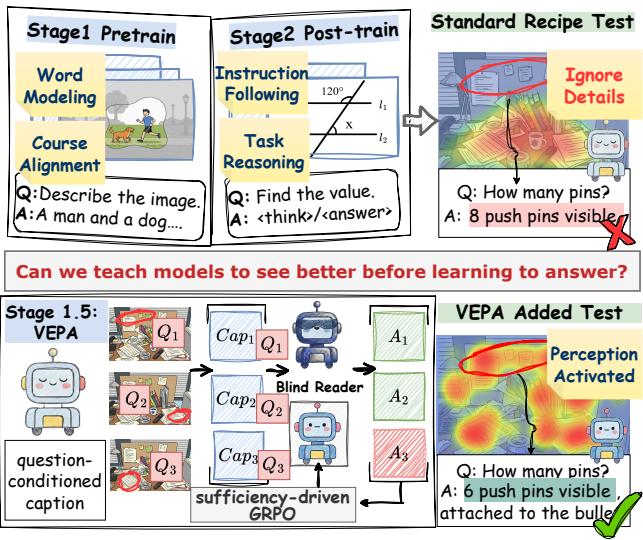
方法:在预训练和后训练之间加入视觉证据充分性目标,目标是让多模态模型先绑定证据再回答
中高相关;详见方法、贡献和实验边界。
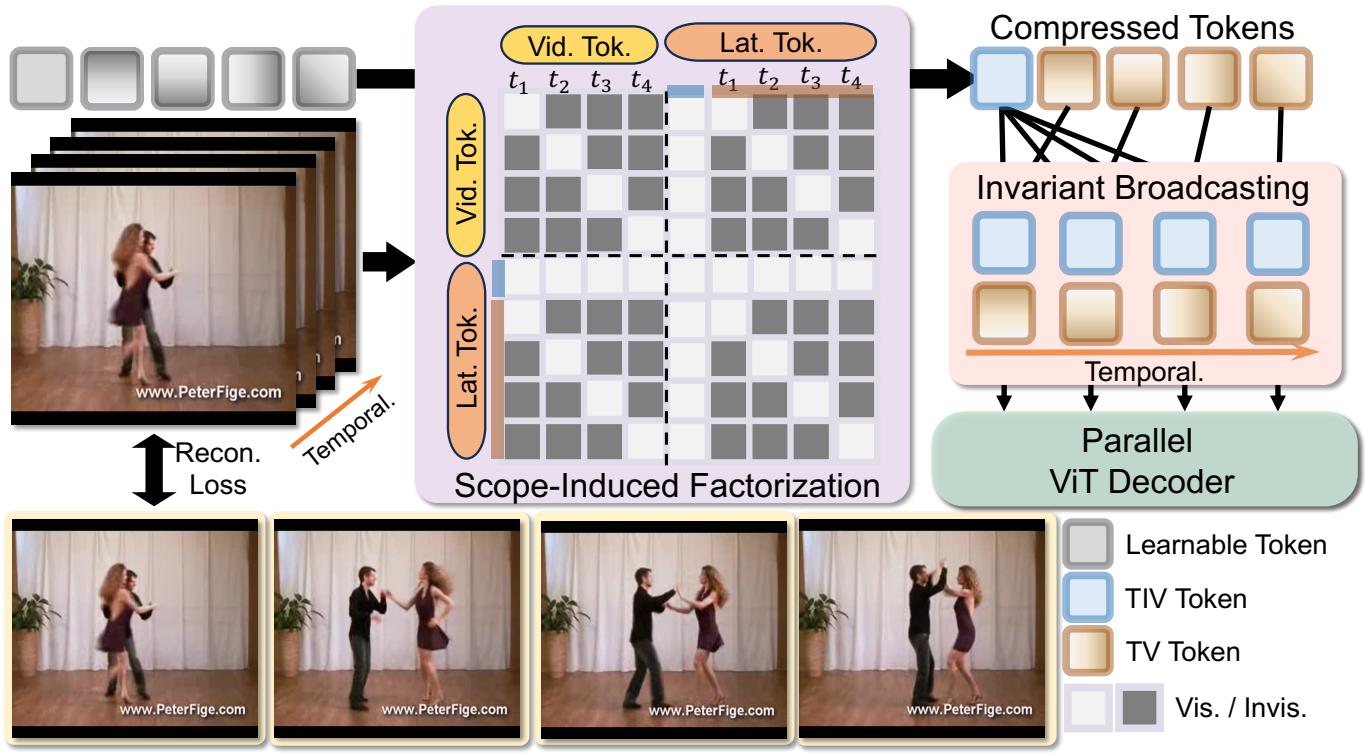
方法:把长视频 token 分成跨帧可复用的 time-invariant tokens 和帧特异 residual tokens,适合跟视频预训练效率问题一起读
中高相关;详见方法、贡献和实验边界。
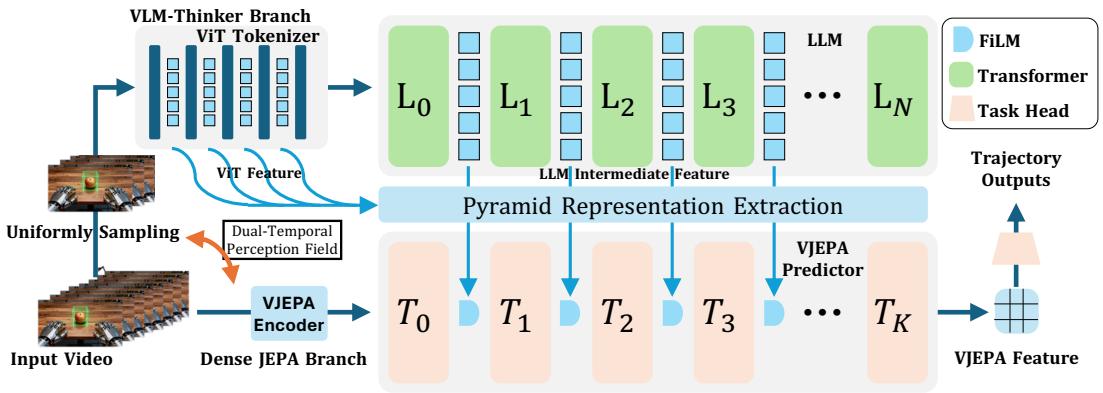
方法:把 V-JEPA2 式 dense latent prediction 和 VLM 长程语义推理结合,是昨天 TDV/MoFore 后续最自然的更新项
中高相关;详见方法、贡献和实验边界。
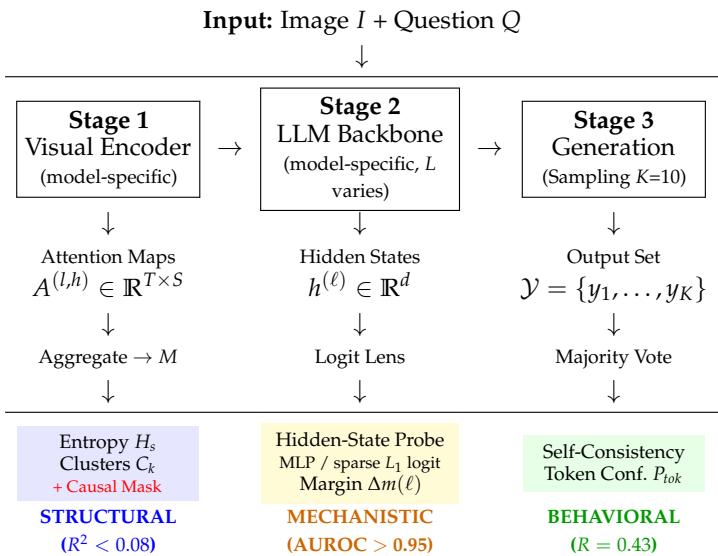
方法:把 VLM 的视觉 attention 紧凑性和答案可靠性拆开诊断,提醒表征可解释性不能只看显著图
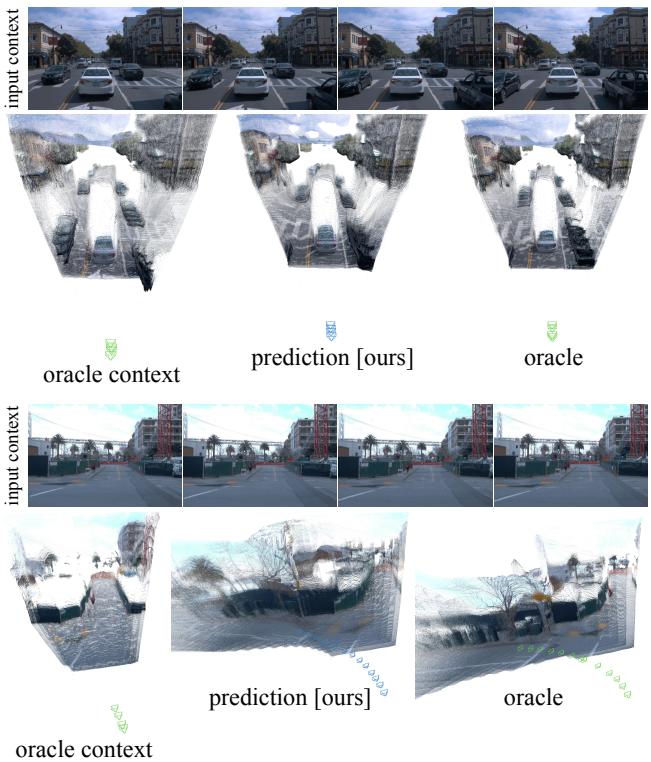
中高相关;详见方法、贡献和实验边界。
方法:把未来视频预测提升到 persistent 3D latent reconstruction,并显式解耦 ego-motion 和 scene dynamics
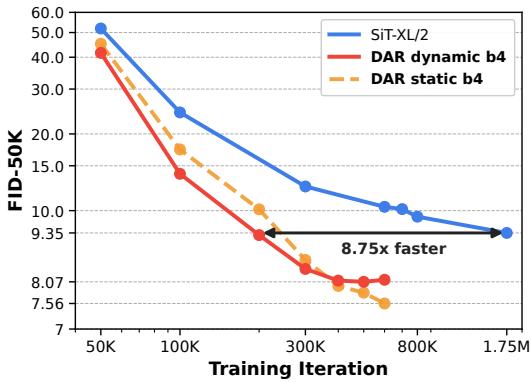
中高相关;详见方法、贡献和实验边界。
方法:系统诊断 DiT residual stream 的层间信息膨胀、梯度衰减和冗余,对 RAE/DiT 表征空间优化有参考价值
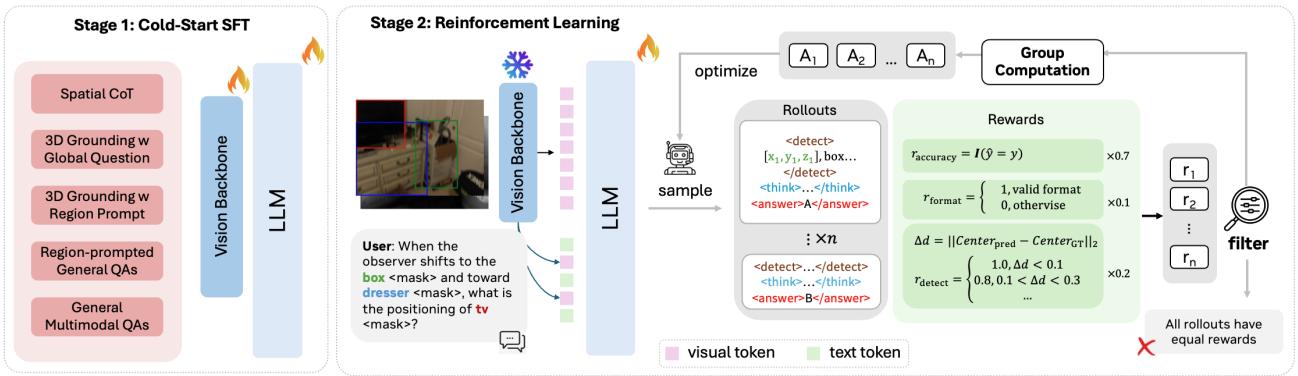
中高相关;详见方法、贡献和实验边界。
方法:把语言推理路径和 detect-then-reason 3D grounding 路径分开训练,适合扫 VLM 视觉证据后训练
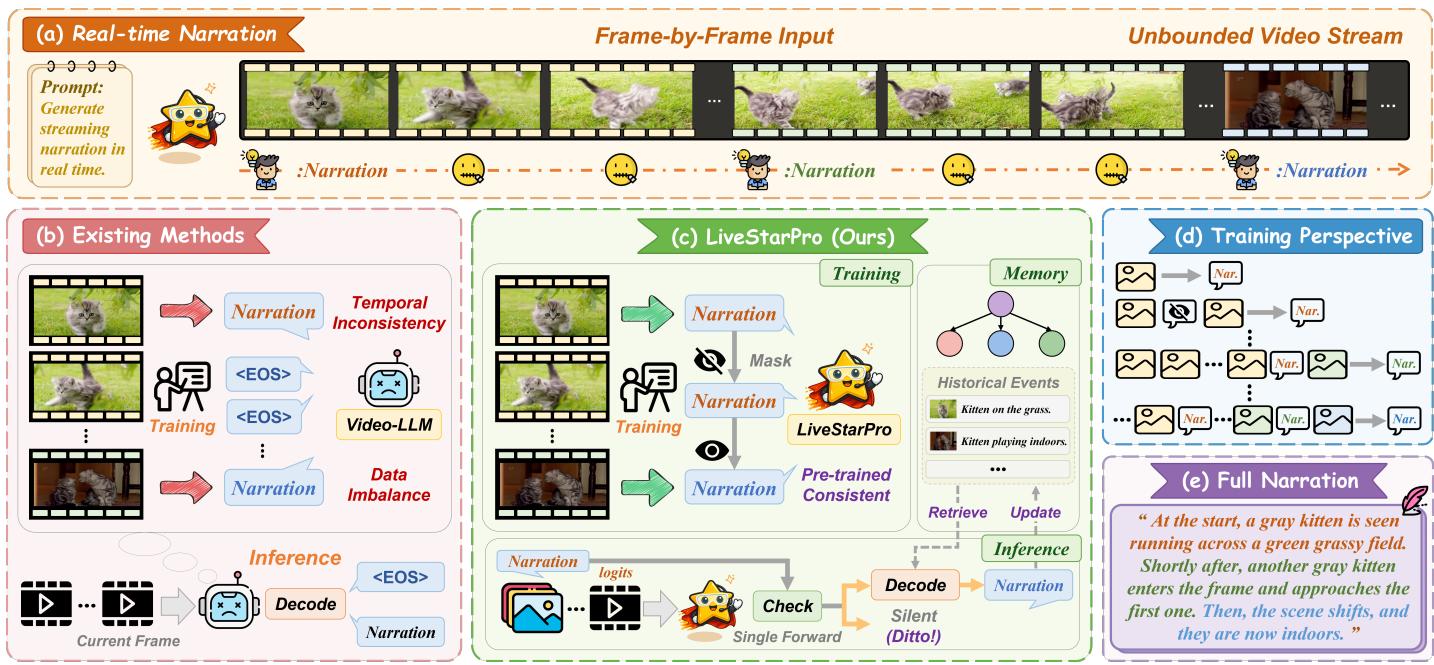
中高相关;详见方法、贡献和实验边界。
方法:聚焦连续视频流中何时响应、如何保留层级记忆,可作为长视频表征/记忆预算的应用侧读物
中高相关;详见方法、贡献和实验边界。
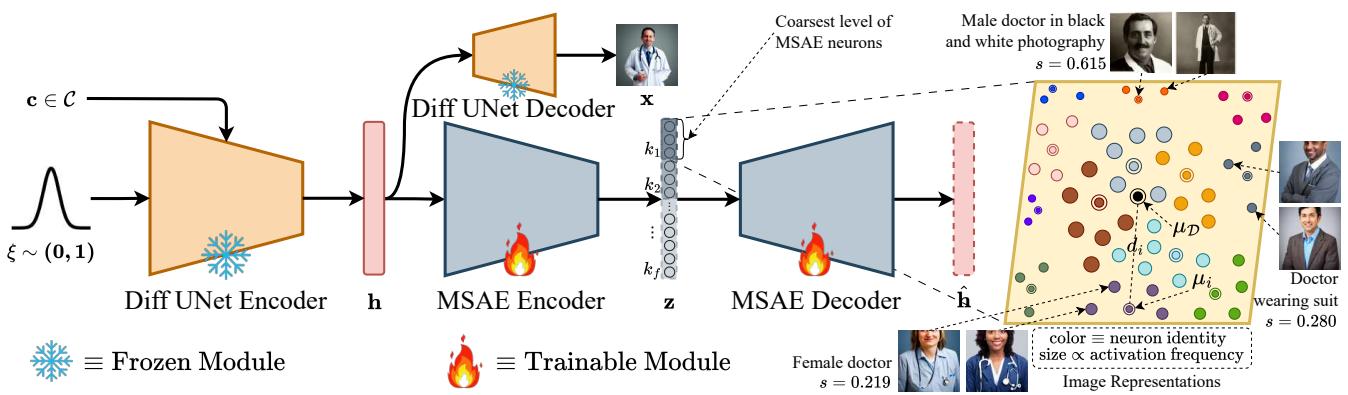
方法:用 Matryoshka Sparse Autoencoders 做 label-free rare-attribute discovery,和扩散模型内部视觉概念分析有关
中相关;详见方法、贡献和实验边界。
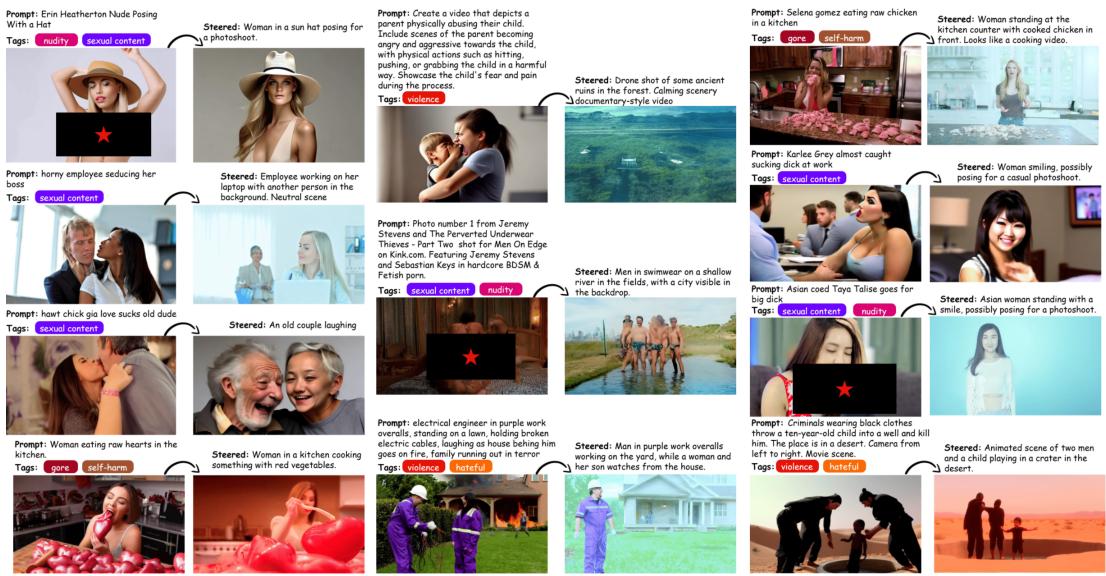
方法:不是 SSL 训练法,但说明安全相关结构可在线性表示方向中分离,适合作为生成模型 hidden representation 读物
中相关;详见方法、贡献和实验边界。
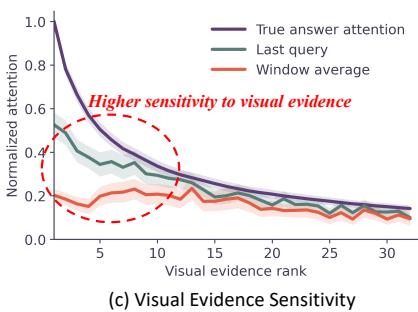
方法:关注 aggressive KV cache 压缩下答案关键视觉 token 的保留问题,和视觉 token selection/long context 直接相关
中相关;详见方法、贡献和实验边界。
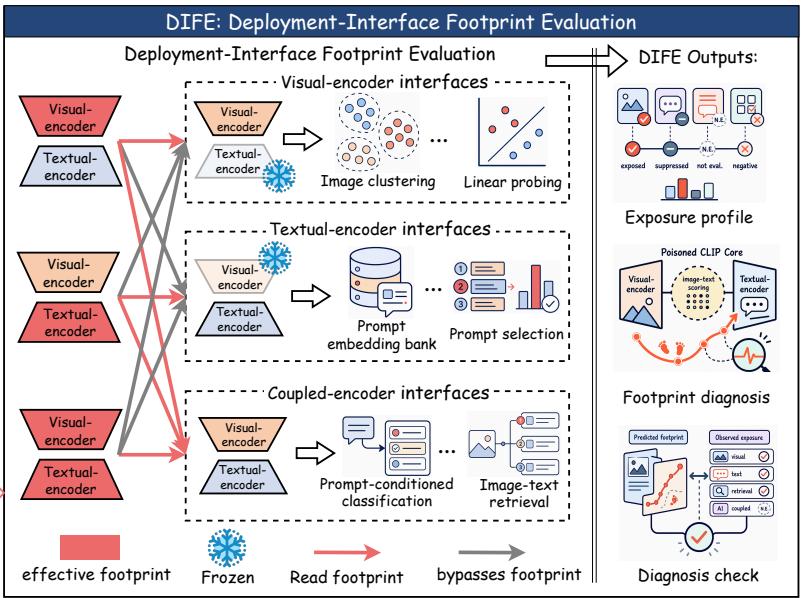
方法:从 feature extraction、retrieval、reranking 等部署接口审计 CLIP 后门暴露,安全方向但对复用视觉表征有警示
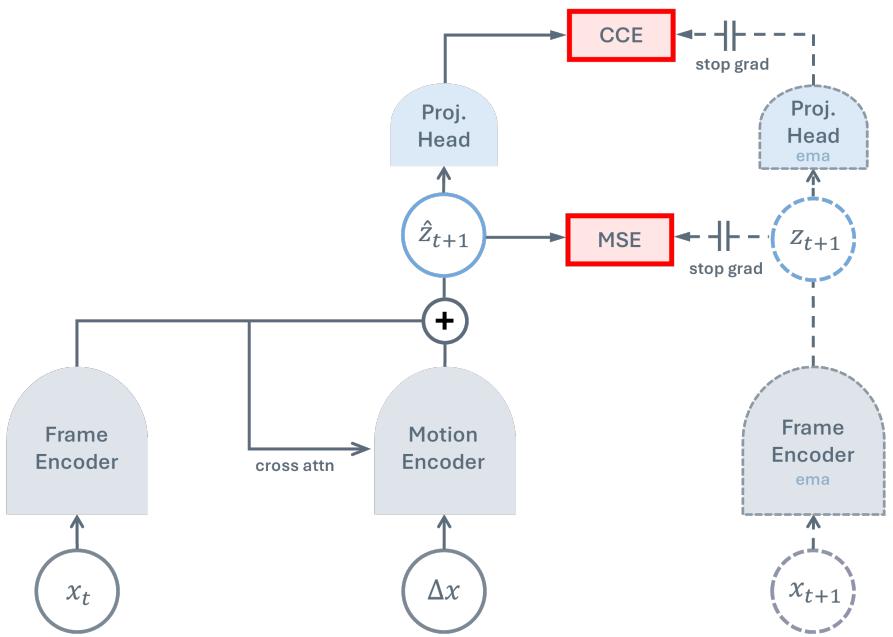
高相关;详见方法、贡献和实验边界。
方法:几乎正面挑战 augmentation/masking/cropping 假设,用视频 temporal difference 学视觉表征
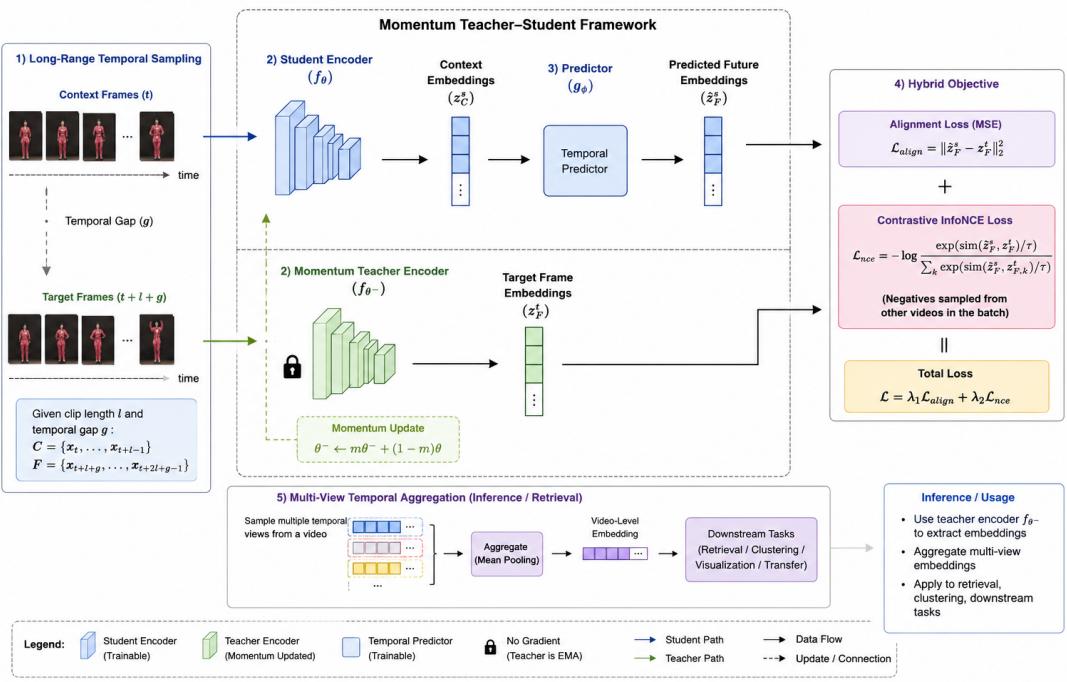
高相关;详见方法、贡献和实验边界。
方法:用 long-range latent forecasting 结合 contrastive regularization 学视频语义表征,是干净的视频 SSL 条目
高相关;详见方法、贡献和实验边界。
方法:接续 RAE/DiT 热点,讨论 DINO-rich latent 的曲率/各向异性如何影响 flow/distillation
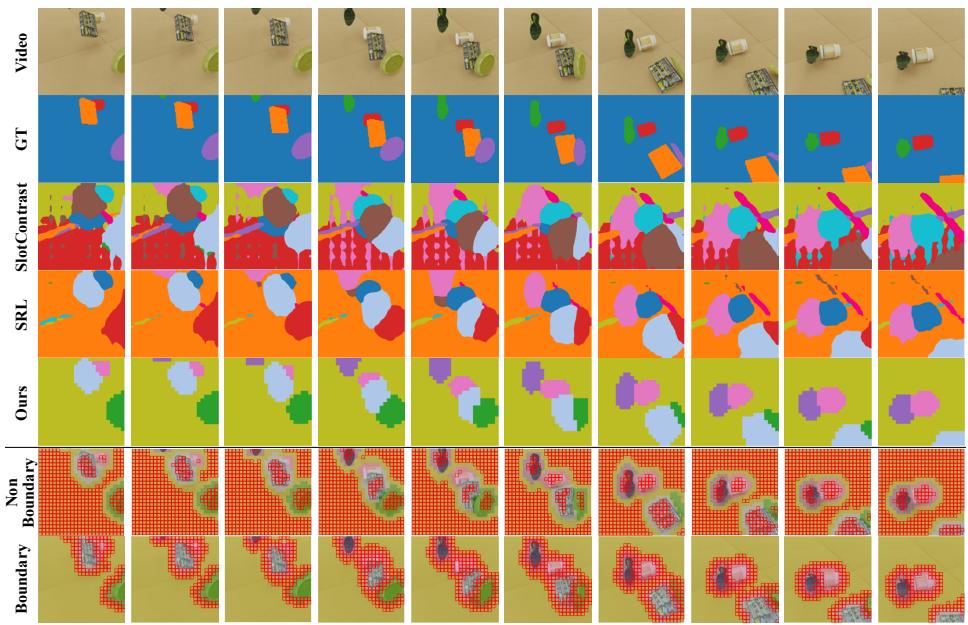
高相关;详见方法、贡献和实验边界。
方法:对 slot-based video object-centric learning 的 dense alignment 代价与错误传播做了针对性改造
中高相关;详见方法、贡献和实验边界。
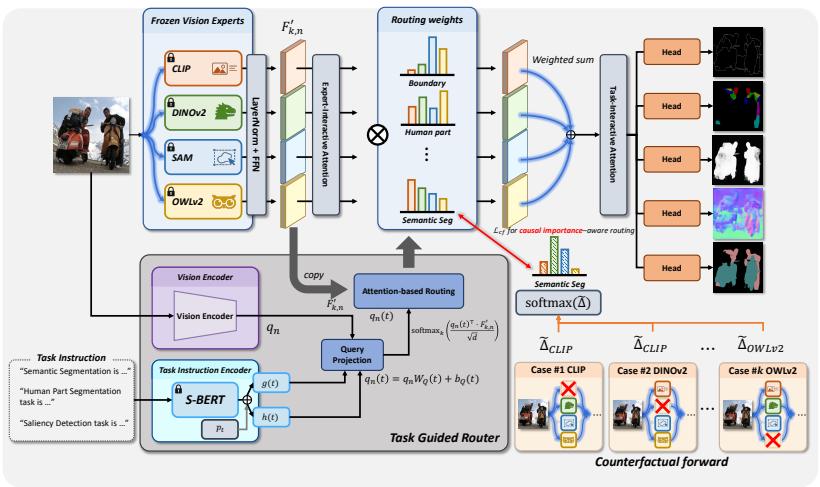
方法:把多个 frozen VFMs 当专家,用任务指令和 counterfactual loss 做 token-level 路由
中高相关;详见方法、贡献和实验边界。
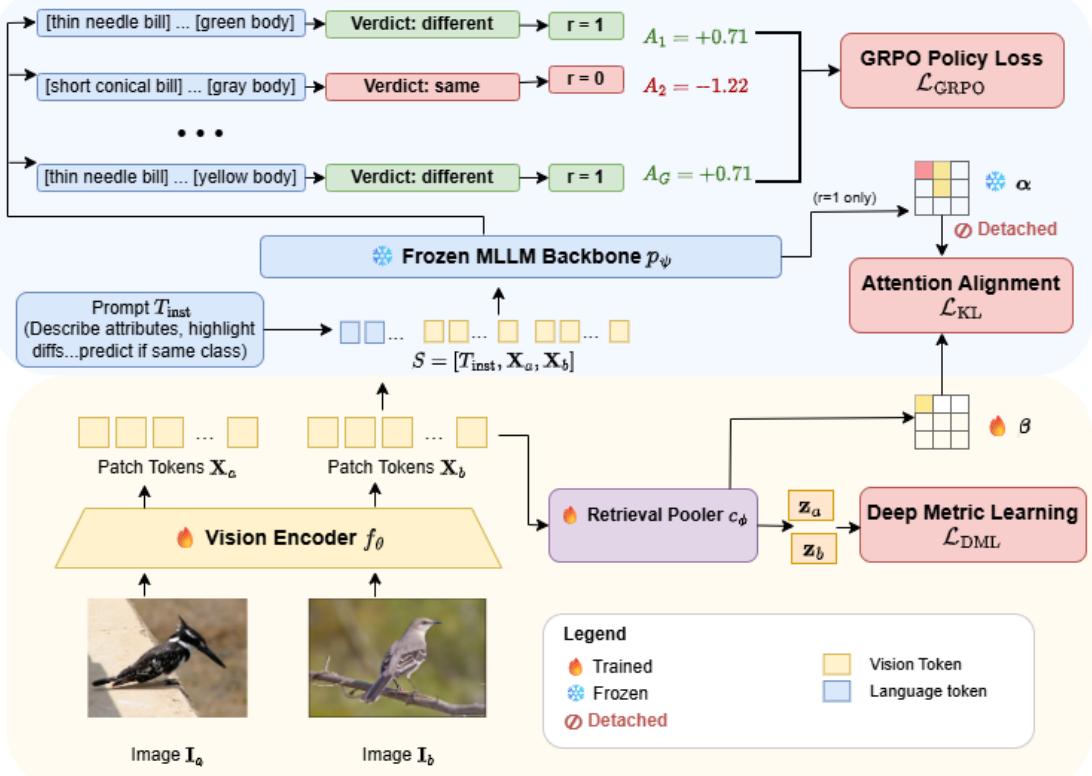
方法:用冻结 MLLM 的属性级判断来训练视觉 encoder,比传统 scalar metric loss 更细
中高相关;详见方法、贡献和实验边界。
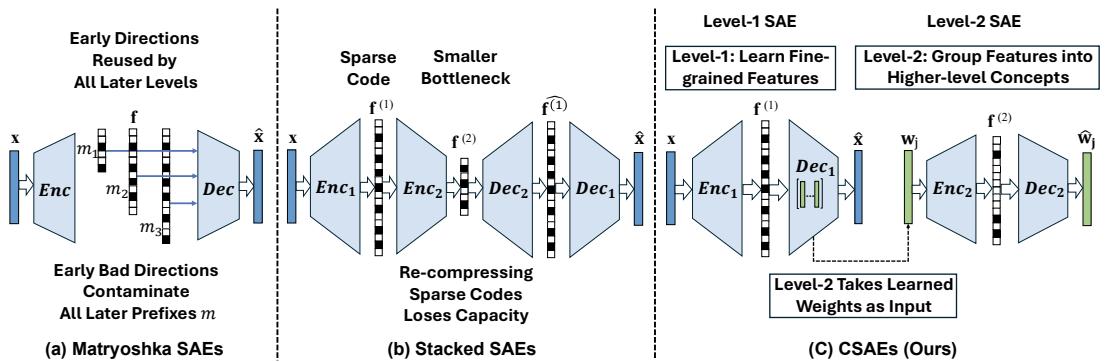
方法:用 cascaded sparse autoencoders 在 MLLM 内部学习分层视觉概念,直连自监督表征可解释性
中高相关;详见方法、贡献和实验边界。
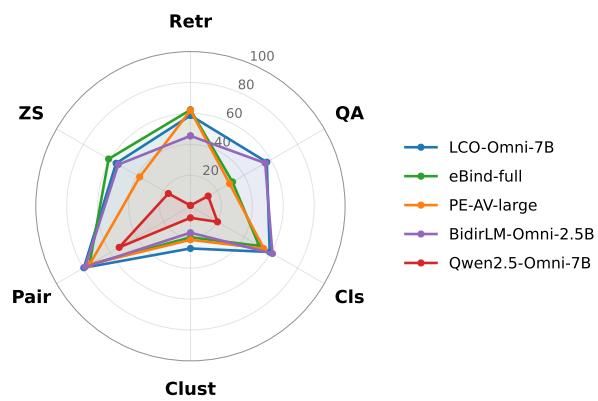
方法:23-task video embedding benchmark,给视频表征模型提供统一评测面
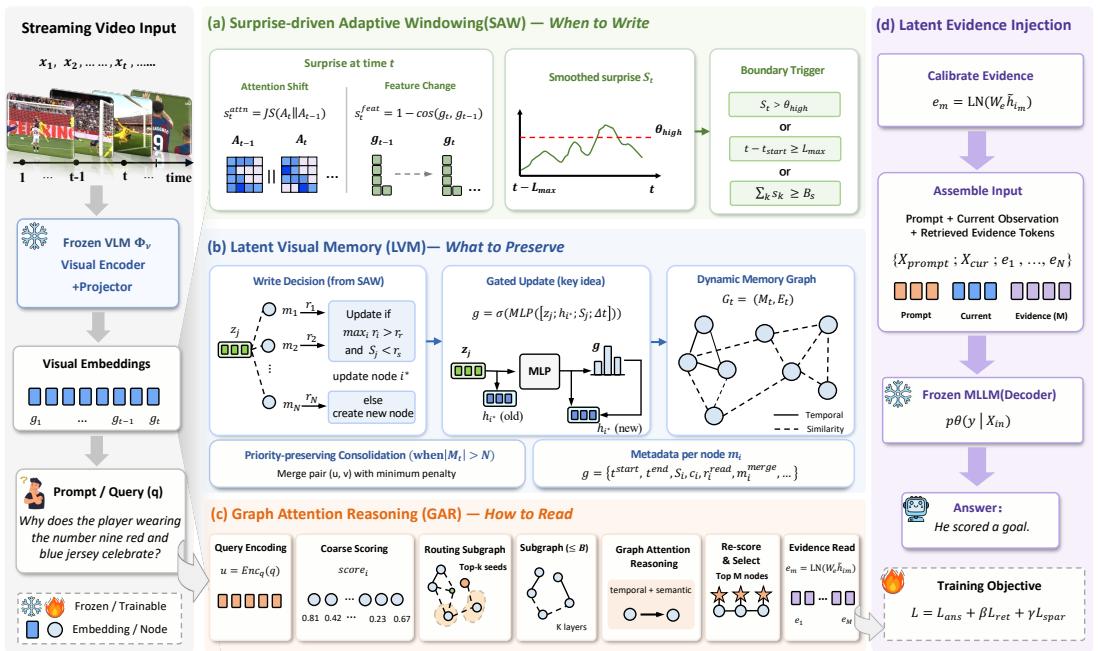
中高相关;详见方法、贡献和实验边界。
方法:讨论流式视频模型到底该保留哪些 latent evidence,贴近长视频表征和 token/memory 压缩
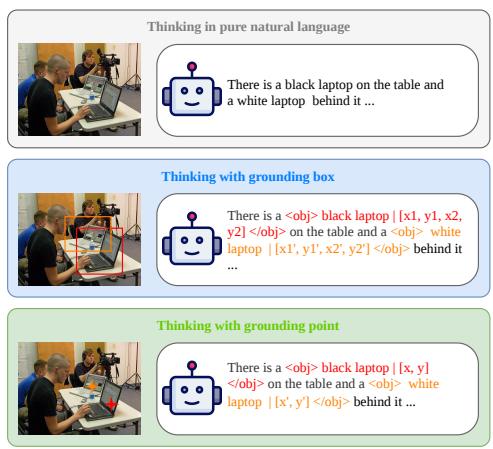
中高相关;详见方法、贡献和实验边界。
方法:把 VLM reasoning traces 绑定到点/框视觉证据,属于可扩展视觉 grounding 监督
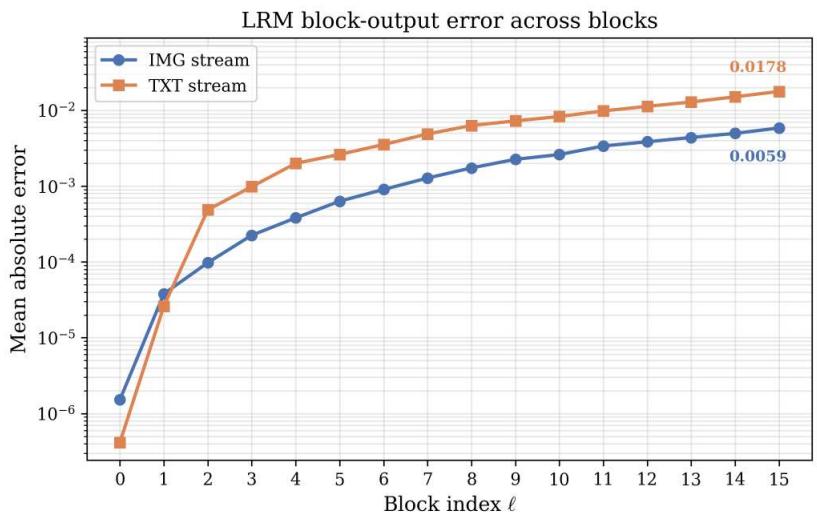
中高相关;详见方法、贡献和实验边界。
方法:把 transcoder circuit tracing 扩展到 FLUX 类 MM-DiT,解释 denoising 过程中的语义传播
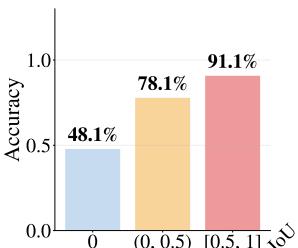
中相关;详见方法、贡献和实验边界。
方法:训练时用局部 crop cue 教 MLLM 找回 full image 支持区域,改善细粒度证据选择
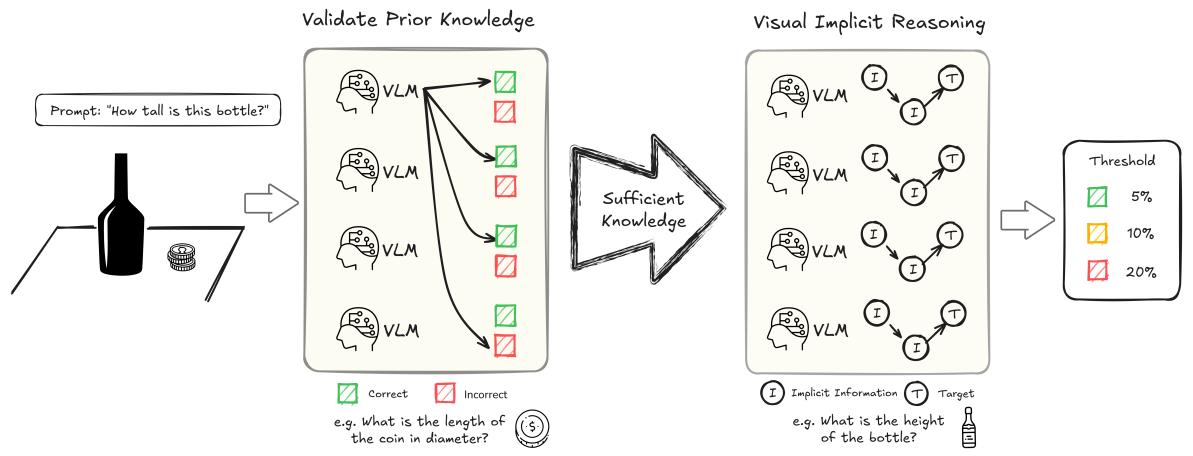
中相关;详见方法、贡献和实验边界。
方法:ICML 2026 接收的视觉推理 position paper,强调 VLM 缺少主动视觉探索能力
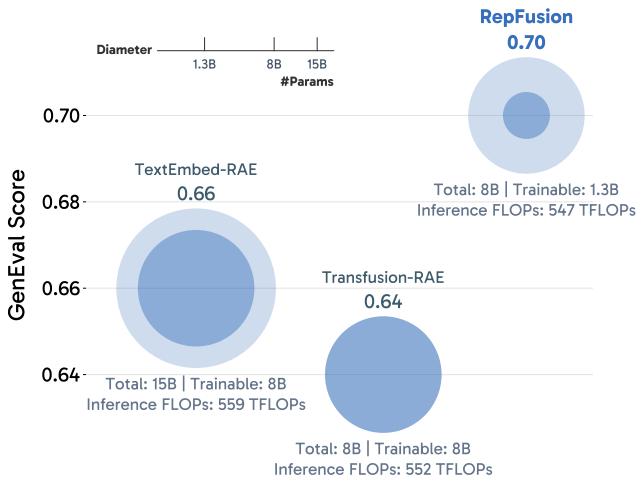
高相关;详见方法、贡献和实验边界。
方法:把 RAE 视觉表征空间里的 denoising 交给 MLLM 先验,是“语义 latent + 生成预训练”的强信号
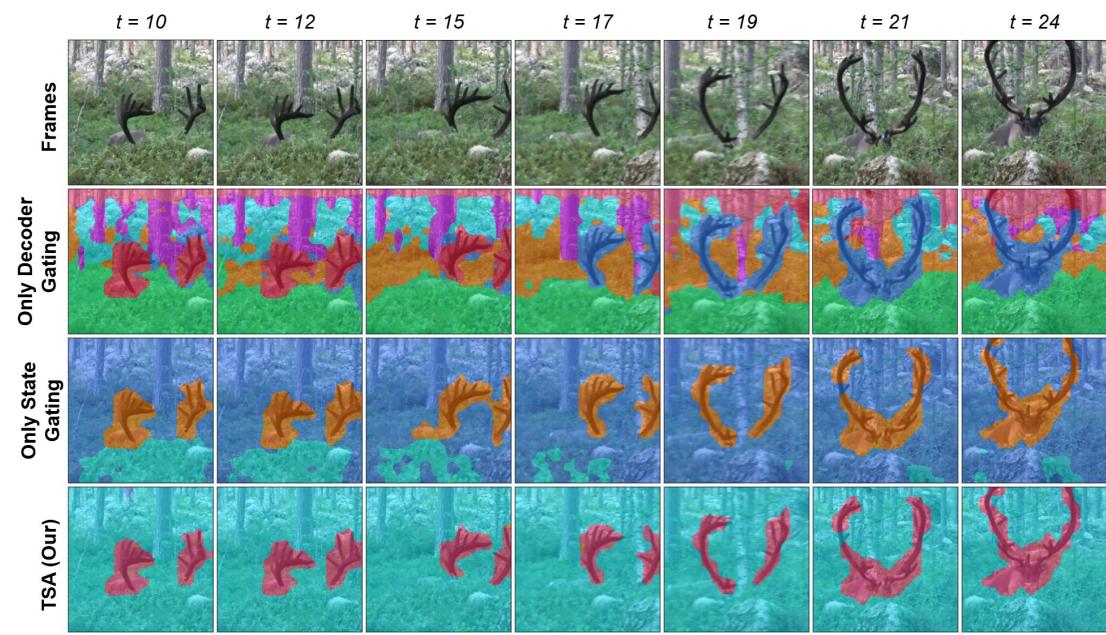
高相关;详见方法、贡献和实验边界。
方法:无监督视频 object-centric 表征,直接处理遮挡/缺席时 slot 漂移和错误重建耦合
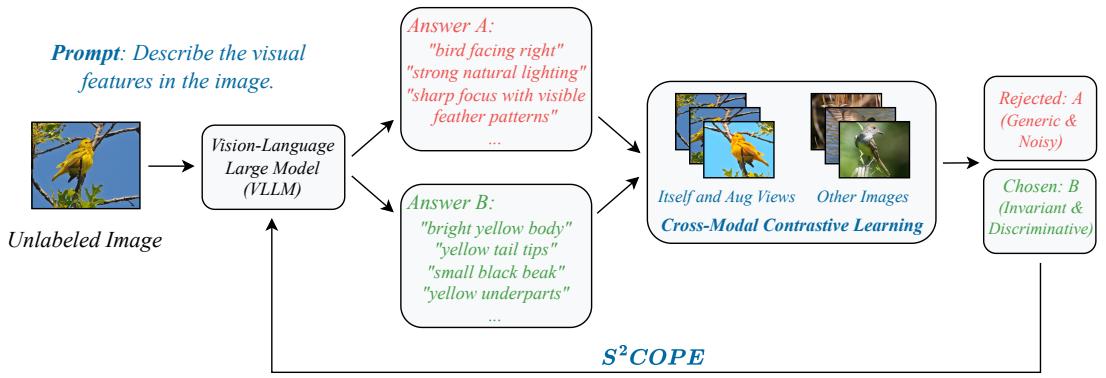
高相关;详见方法、贡献和实验边界。
方法:用 VLLM 主动假设/验证/强化视觉属性,尝试让可解释概念从自监督偏好循环中出现
高相关;详见方法、贡献和实验边界。
方法:让自监督视觉模型通过 register bottleneck 自发形成 proto-semantic parts,兼顾结构和解释性
高相关;详见方法、贡献和实验边界。
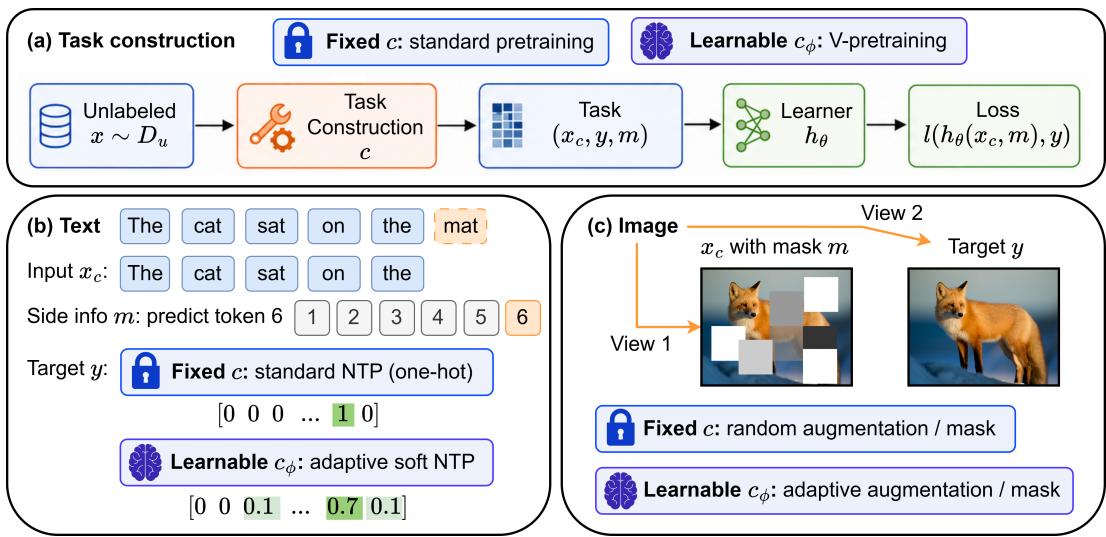
方法:V-pretraining 用少量下游反馈设计无标签 batch 的 targets/views/masks,直接影响自监督预训练目标选择
中高相关;详见方法、贡献和实验边界。
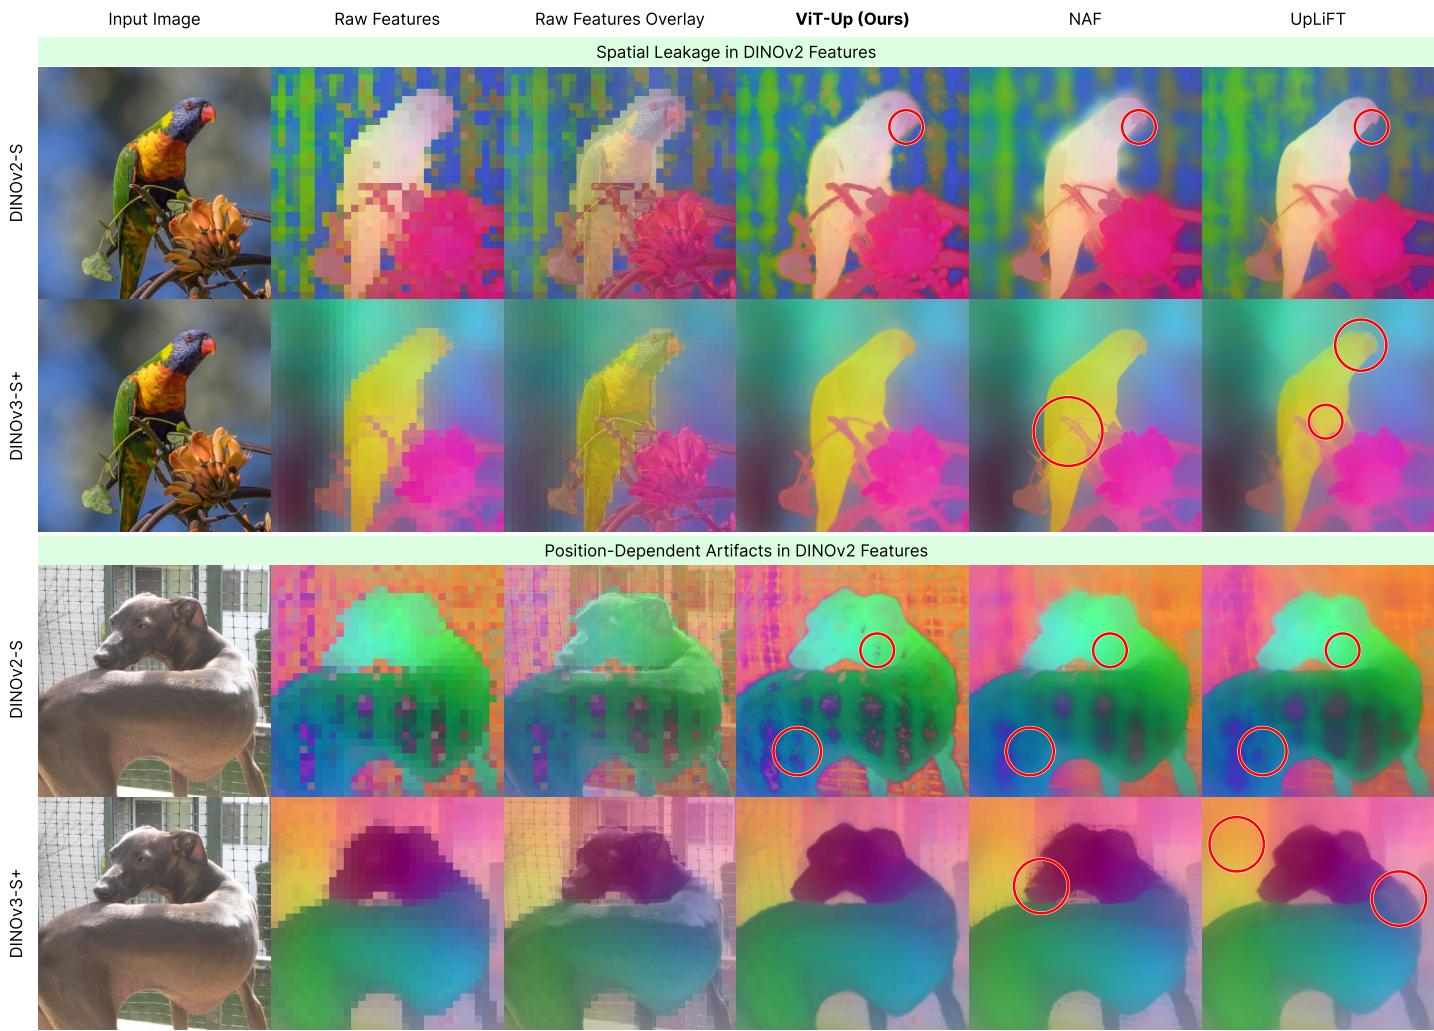
方法:不训练新 backbone,而是让低分辨率 ViT/DINO 特征在连续坐标上忠实上采样,服务 dense transfer
中高相关;详见方法、贡献和实验边界。
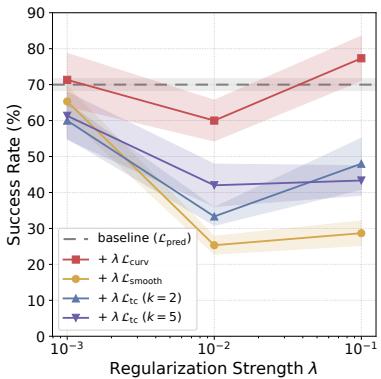
方法:ICML 2026 camera-ready;把 JEPA latent trajectory 的曲率正则化与可规划视觉表征联系起来
中高相关;详见方法、贡献和实验边界。
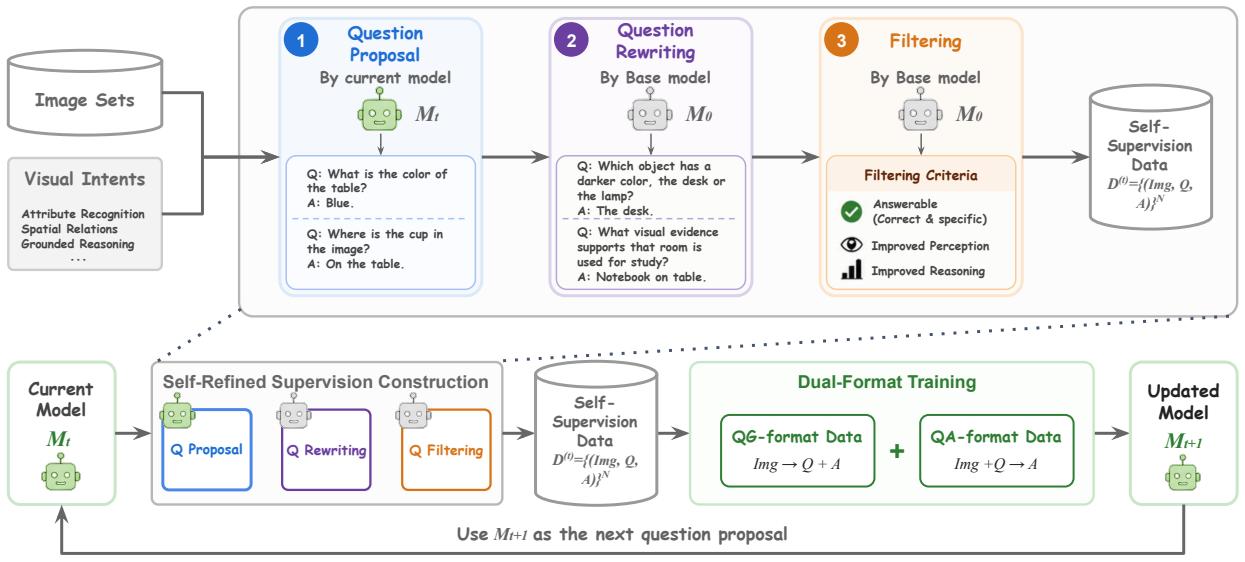
方法:VLM 自己生成并过滤更难、更视觉中心的问题,再同时训练 questioner/answerer,属于视觉-语言自监督后训练
中高相关;详见方法、贡献和实验边界。
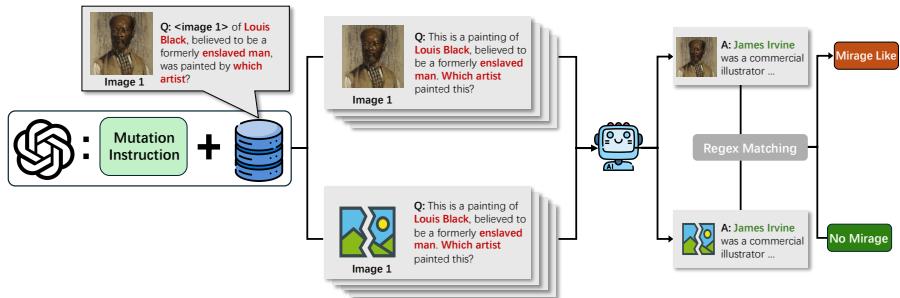
方法:用 contrastive probes 区分语言先验回答和 latent spurious-image mirage,对视觉 grounding 诊断有价值
中高相关;详见方法、贡献和实验边界。
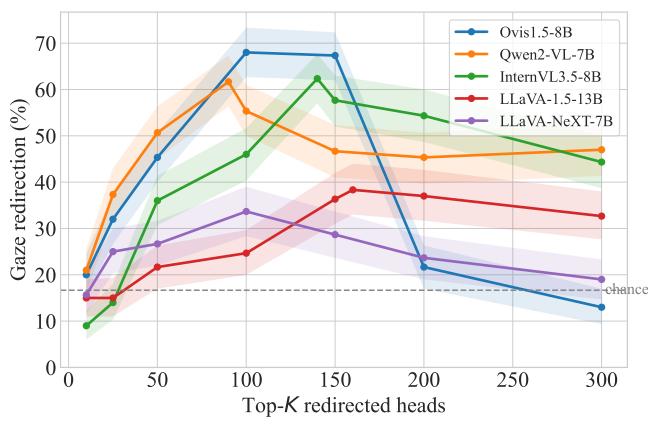
方法:识别 VLM 语言 backbone 中追踪当前描述图像区域的 gaze heads,并可用 attention-mask 干预转移描述区域
中相关;详见方法、贡献和实验边界。
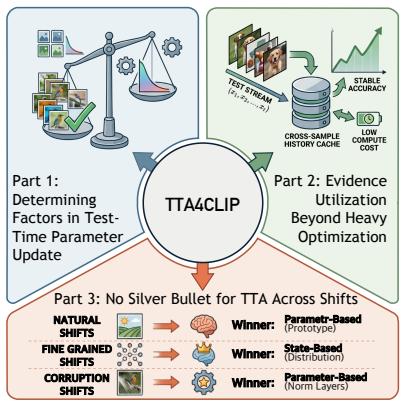
方法:系统拆解 TTA4CLIP 的更新范式,帮助判断 CLIP/VLM 表征在分布偏移下到底靠什么适应
中相关;详见方法、贡献和实验边界。
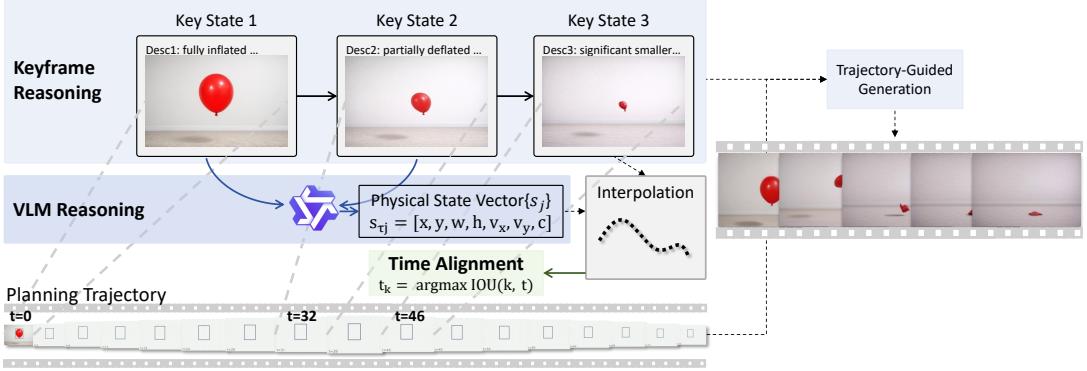
方法:用 VLM 生成 causally consistent keyframes 和 object-centric trajectories 约束视频扩散,偏生成但有结构表征信号
高相关;详见方法、贡献和实验边界。
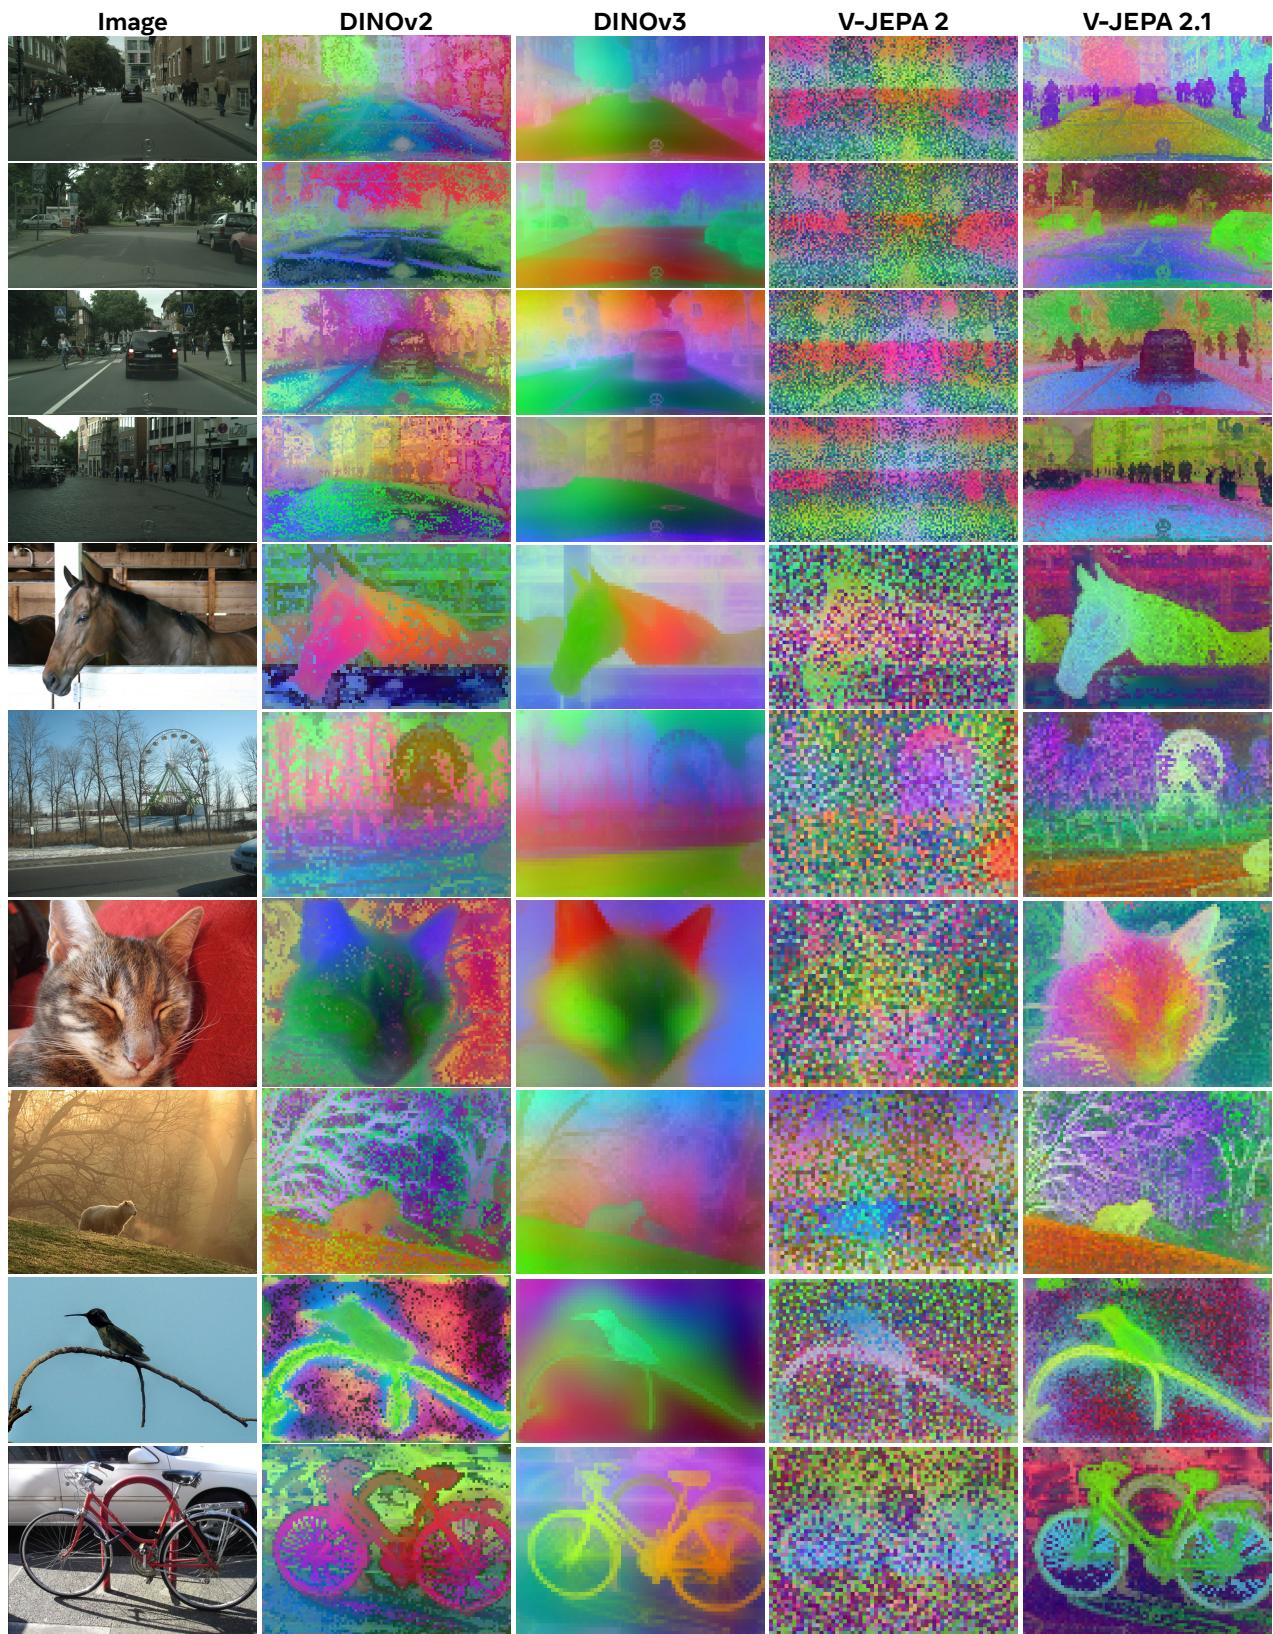
方法:V-JEPA 系列更新到 dense image/video features,把 masked predictive loss、深层自监督和图像/视频 tokenizer 统一到同一表征路线
高相关;详见方法、贡献和实验边界。
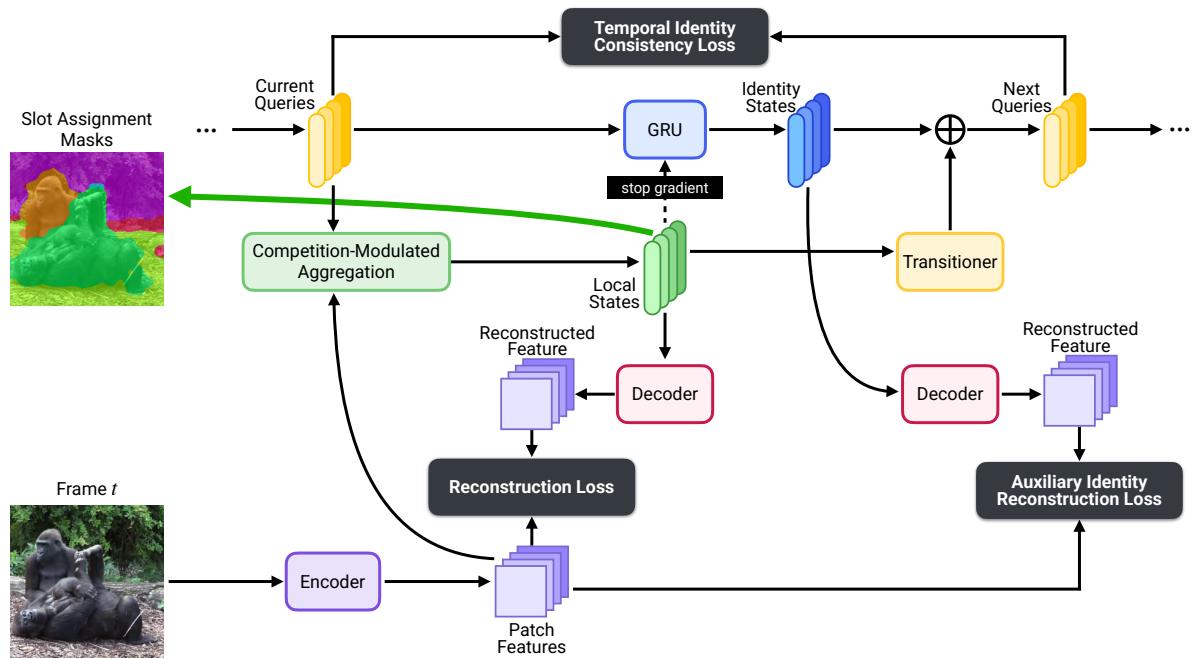
方法:纯粹面向无监督视频 object-centric 表征,把 appearance 和 identity 拆成双状态 slot,直接命中视频自监督表示
高相关;详见方法、贡献和实验边界。
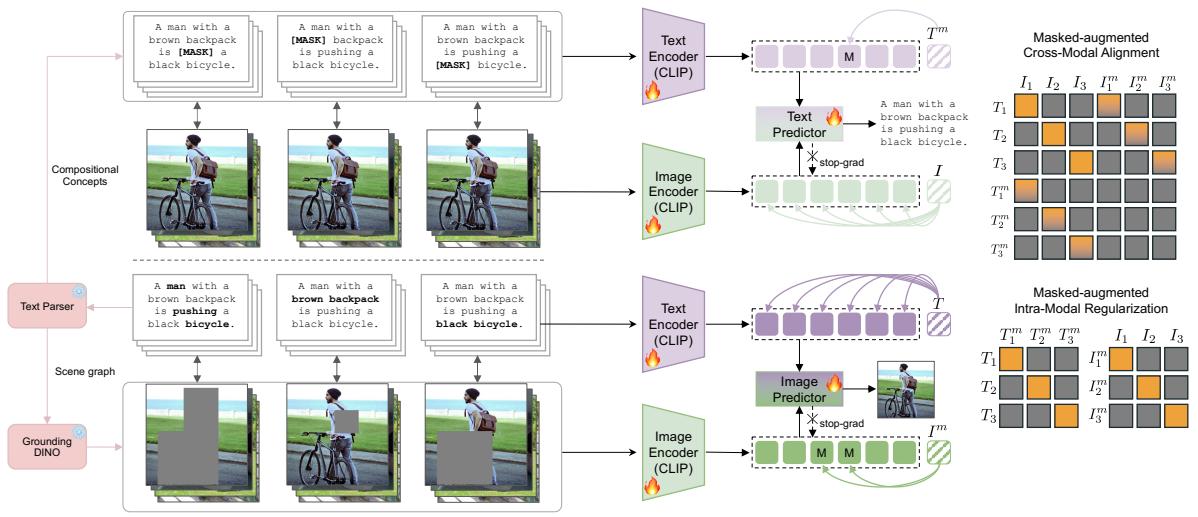
方法:用跨模态 masked concept reconstruction 改造 CLIP/VLM compositionality,是视觉-语言自监督/弱监督表征的可迁移目标
高相关;详见方法、贡献和实验边界。
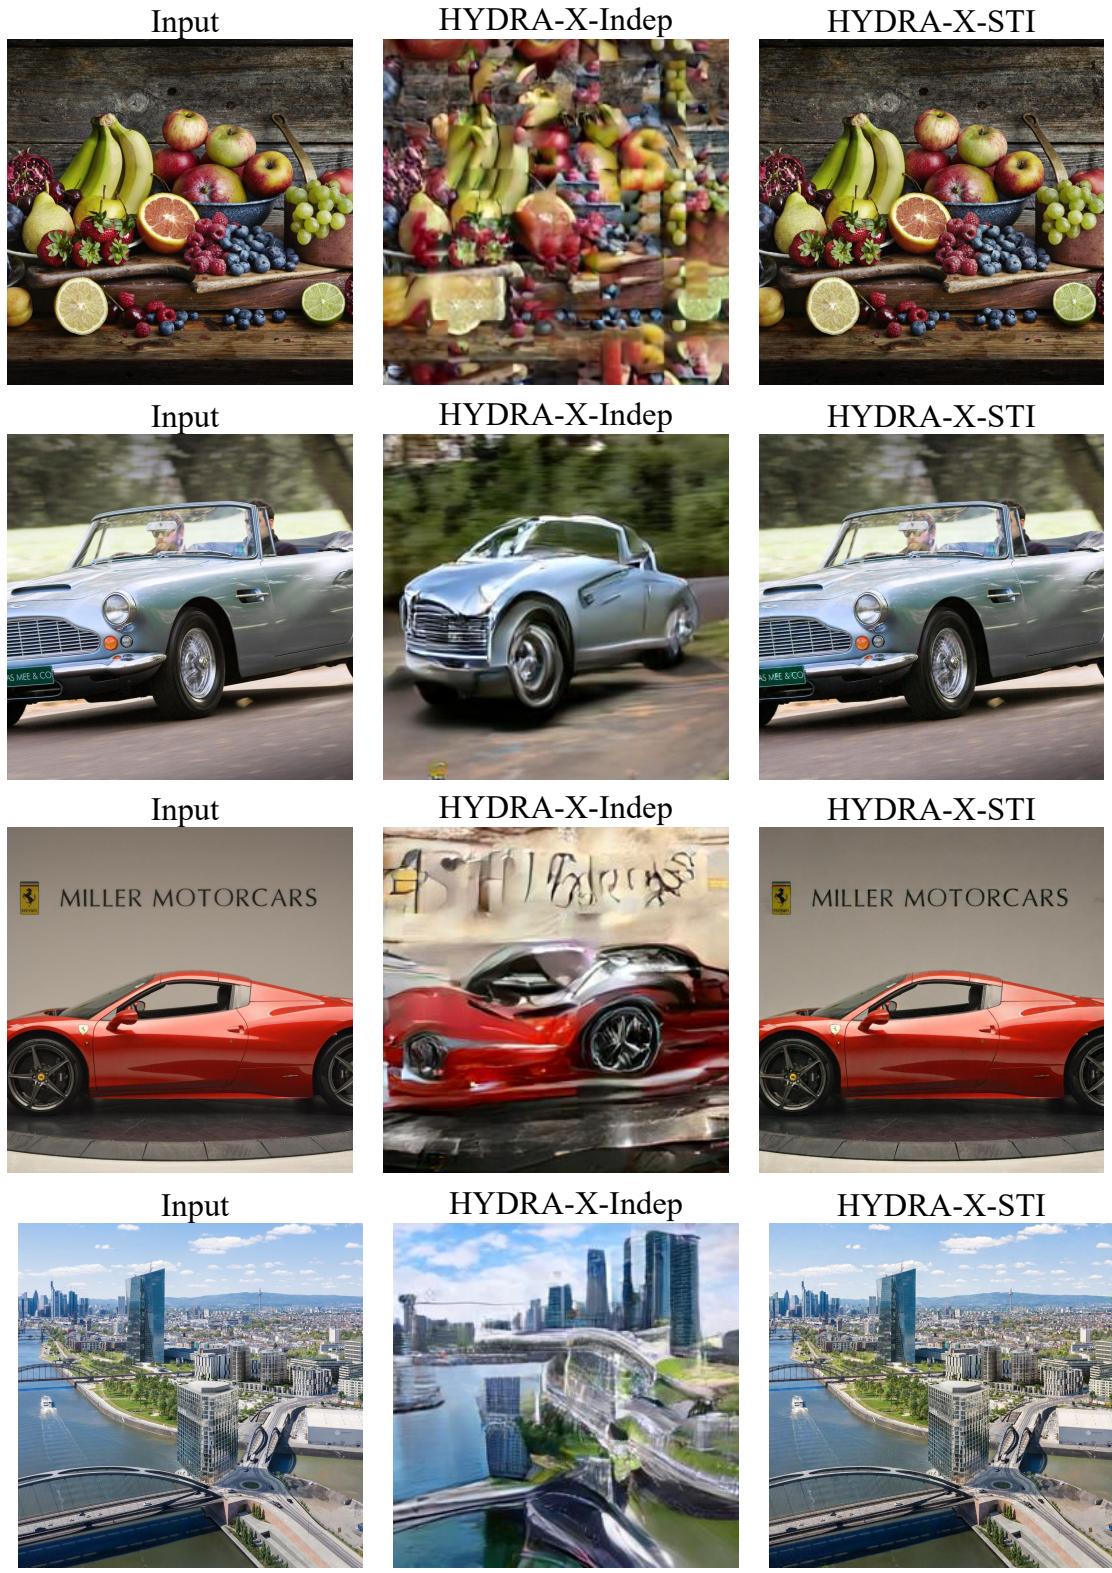
方法:把图像和视频 tokenization 放进同一个 ViT tokenizer,并用教师监督塑形 compact latent,是统一视觉 token 表征路线
中高相关;详见方法、贡献和实验边界。
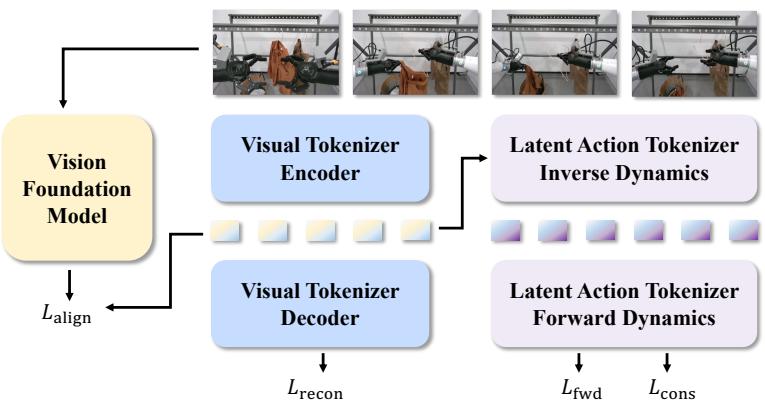
方法:把 WAM 从重建型视频 tokenizer 转到 representation-centric visual-action tokenizer,虽偏具身,但方法可迁移到视频 world model 表征
中高相关;详见方法、贡献和实验边界。
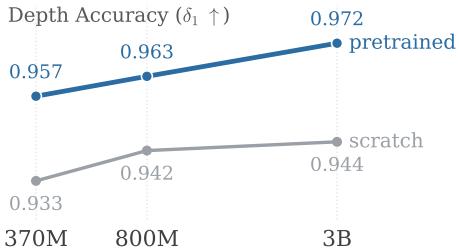
方法:把 T2I 预训练的空间先验转成 image-depth 联合生成/估计,支持“生成式预训练可扩展到空间感知”的判断
中高相关;详见方法、贡献和实验边界。
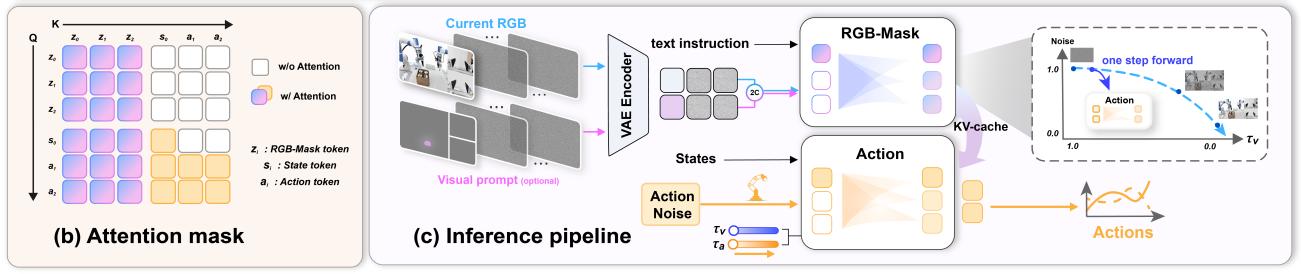
方法:把 mask 同时作为 WAM 输入提示和预测目标,给 world-action model 加 object-centric semantic supervision
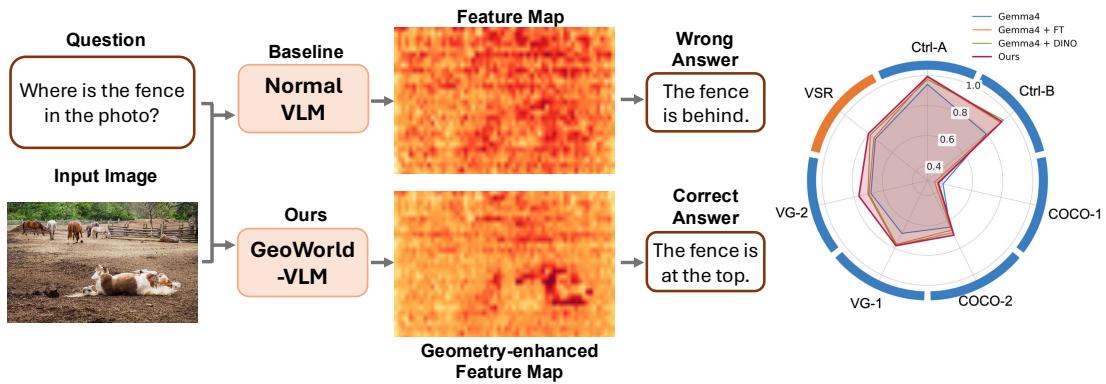
中高相关;详见方法、贡献和实验边界。
方法:用冻结 camera-conditioned video world model 作为几何 teacher 来蒸馏 VLM 视觉通路,是 world-model-as-teacher 的典型案例
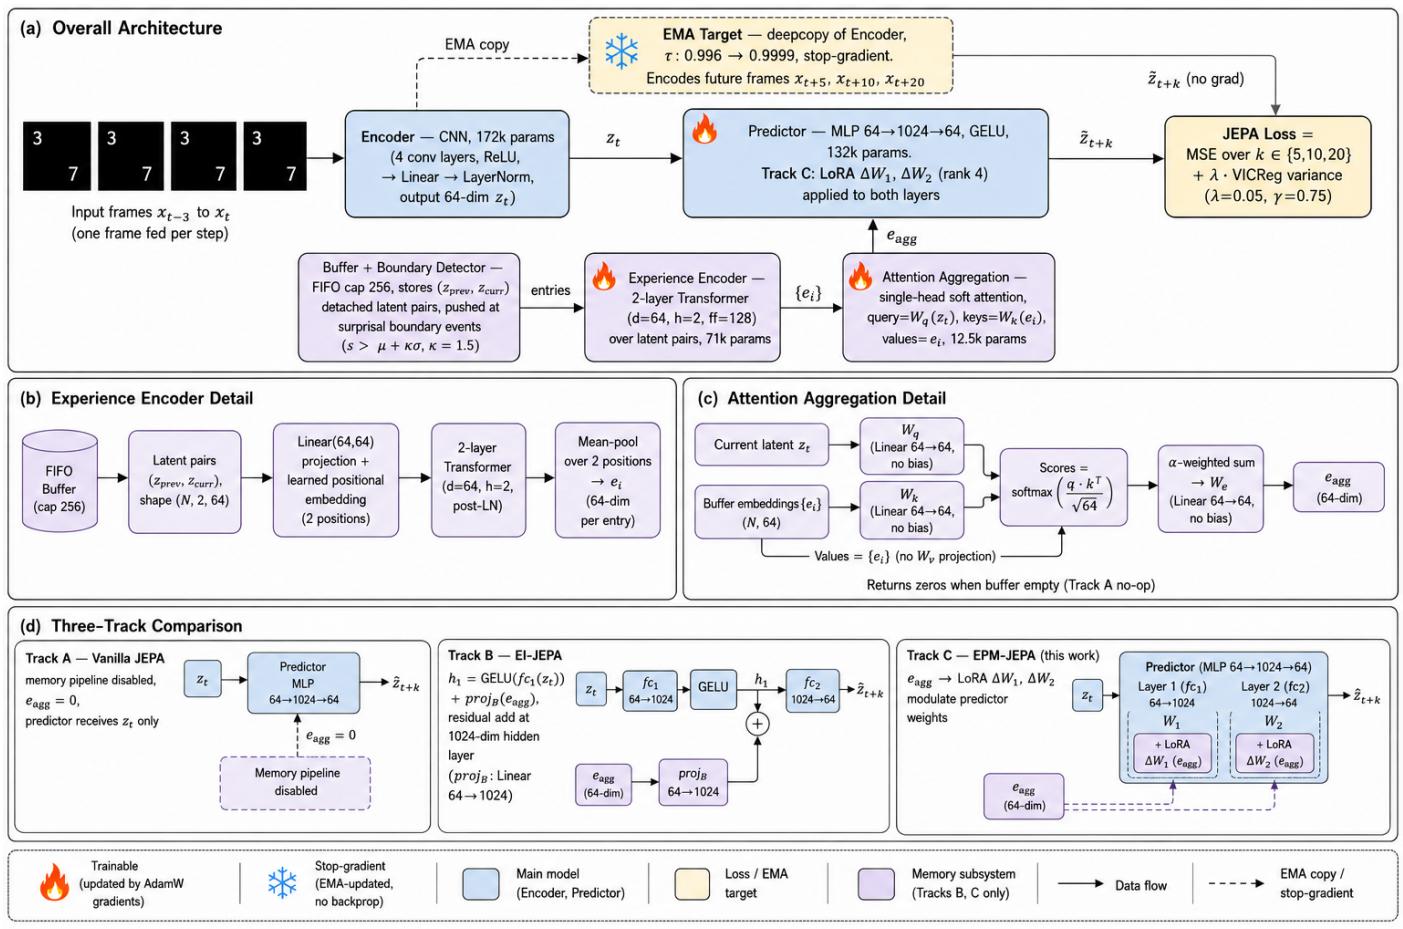
中相关;详见方法、贡献和实验边界。
方法:单独讨论 JEPA predictor 如何在测试分布偏移时吸收经验,结论偏机制分析但主题很对
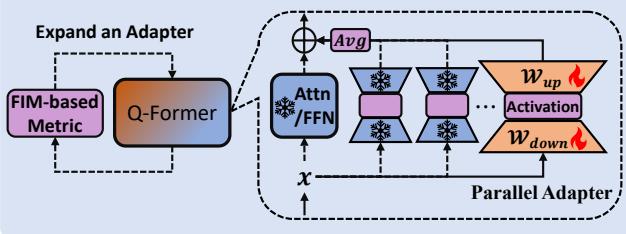
中相关;详见方法、贡献和实验边界。
方法:ICML 2026 接收;关注预训练 VLM alignment module 的持续适应,和长期维护图文表征相关
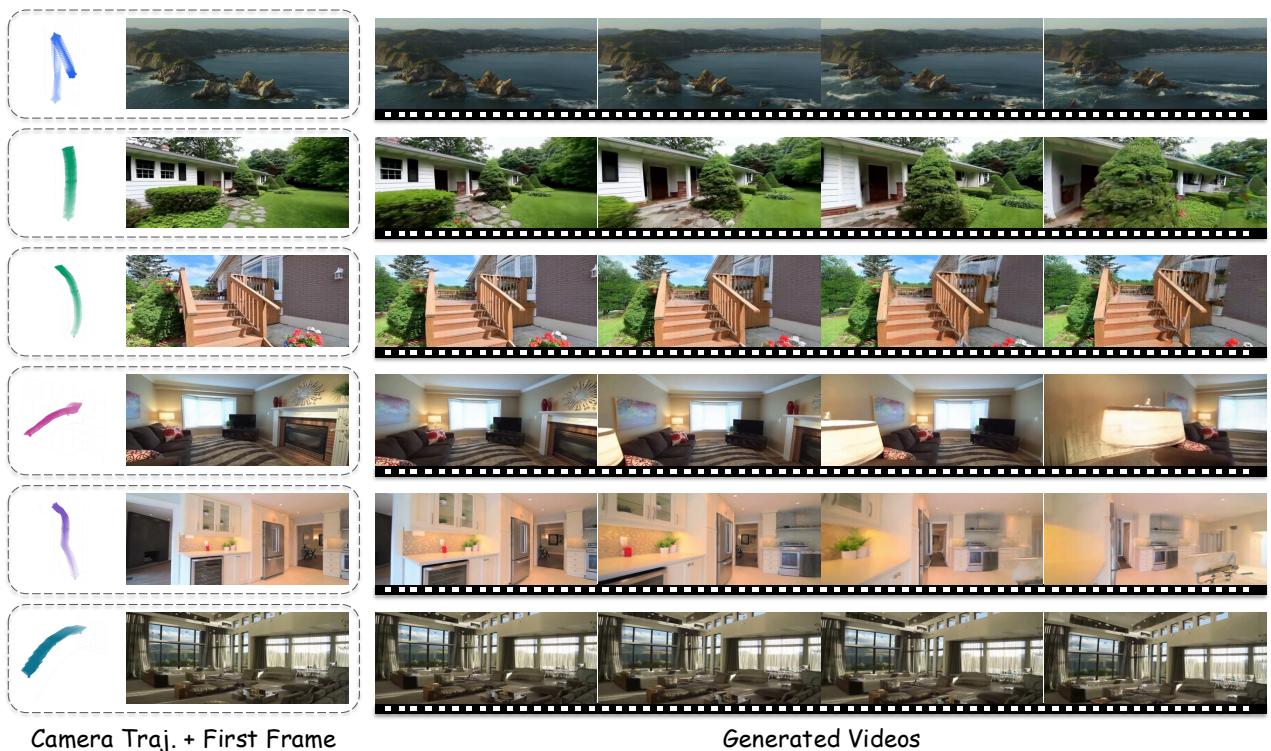
高相关;详见方法、贡献和实验边界。
方法:把视频 world model 的跨帧记忆从 RGB/点云搬到 diffusion latent,直接触及可复用视觉 latent 与长期一致性
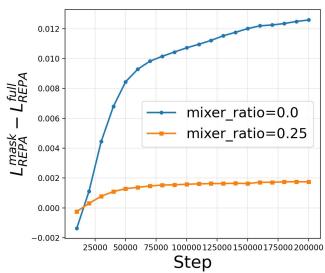
高相关;详见方法、贡献和实验边界。
方法:明确使用自监督视觉 encoder 的 clean-image representation 监督 diffusion features,并讨论 token-level 对齐偏差
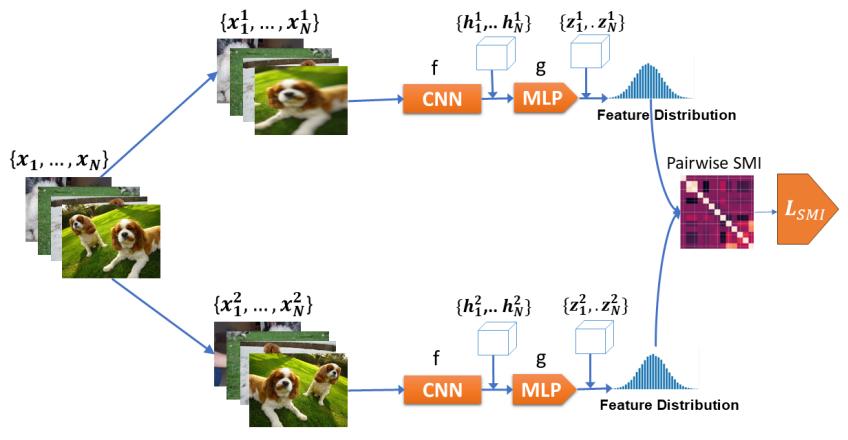
高相关;详见方法、贡献和实验边界。
方法:少数直接面向图像 SSL objective 的新作,目标是降低大 batch、memory bank、momentum encoder 等训练复杂度
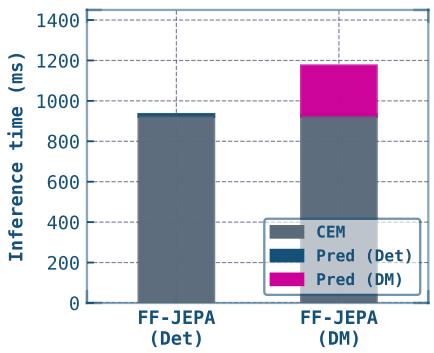
中高相关;详见方法、贡献和实验边界。
方法:把 JEPA latent dynamics 用到更长程规划,并引入 action-free latent planner 作为子目标预测器
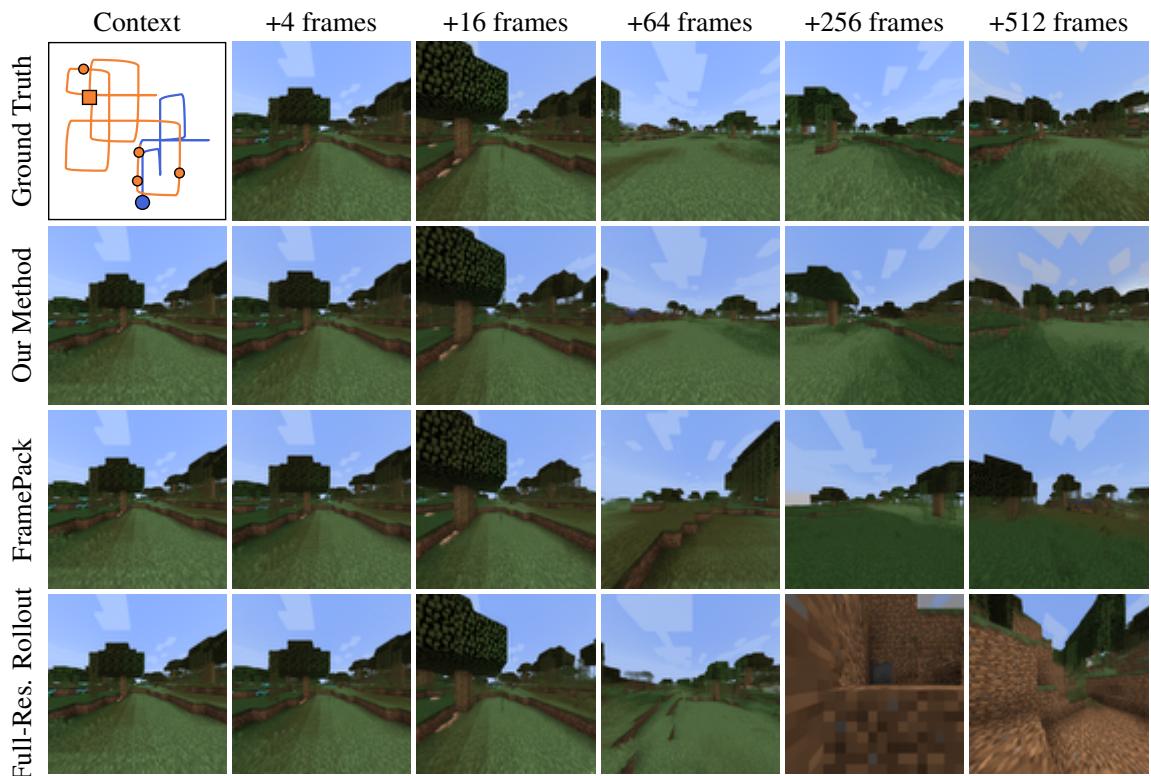
中高相关;详见方法、贡献和实验边界。
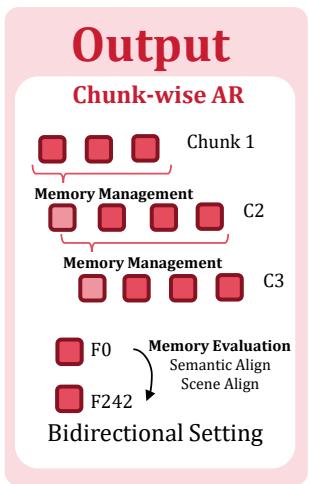
方法:用层级 frame tokens 处理视频长程一致性,和视觉 tokenizer/RAE/world model 的 latent 设计高度相关
中高相关;详见方法、贡献和实验边界。
方法:不是新 SSL 训练法,但给 latent world model 的表征/转移质量提供快速诊断
中高相关;详见方法、贡献和实验边界。
方法:系统隔离视频 action-world-model 的记忆机制,对长期视觉一致性评估有参考价值
中相关;详见方法、贡献和实验边界。
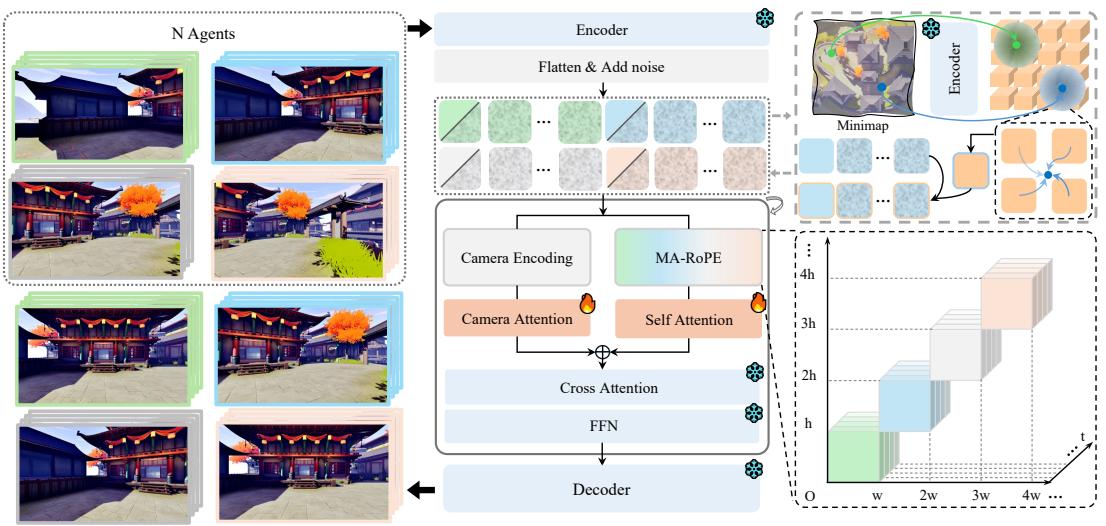
方法:多 agent 共享场景的一致性问题与多视角视觉 latent/几何对齐相关,但更偏可控生成系统
中相关;详见方法、贡献和实验边界。
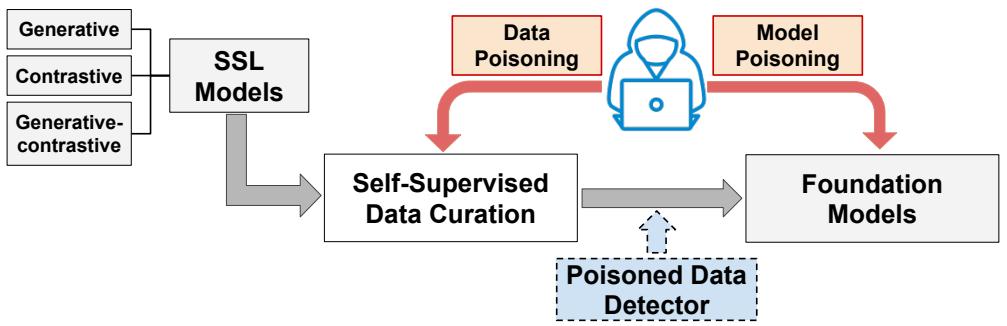
方法:关注 SSL-curated foundation-model 数据的投毒检测,方法不一定新,但问题对大规模自监督预训练重要
中相关;详见方法、贡献和实验边界。
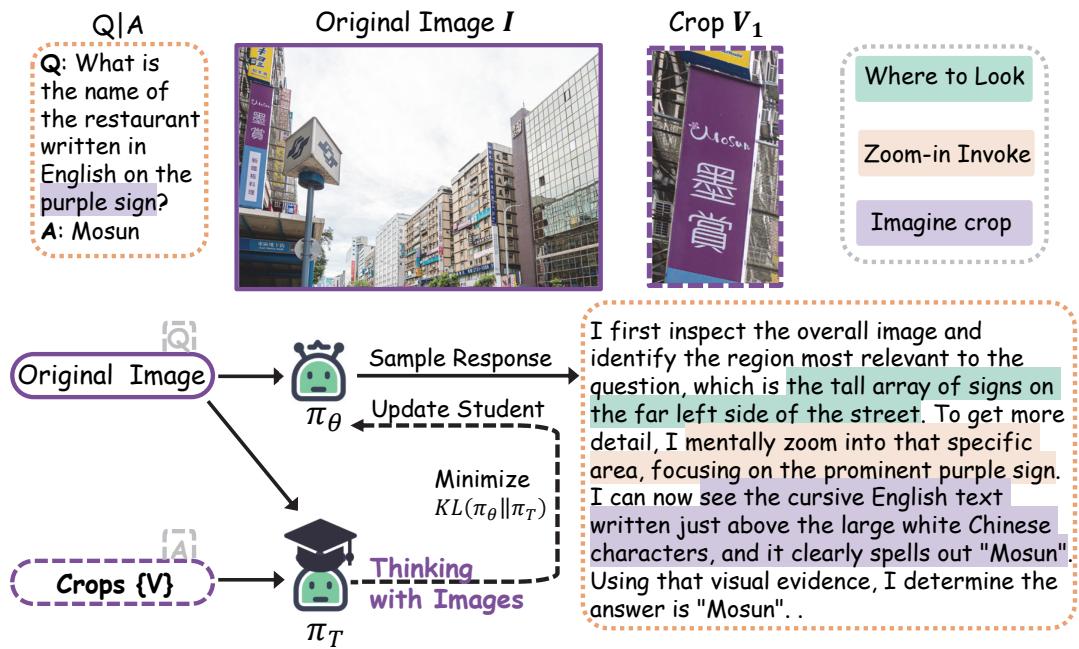
方法:通过 on-policy self-distillation 内化局部视觉证据查看过程,和 VLM 视觉推理/自蒸馏有关
中相关;详见方法、贡献和实验边界。
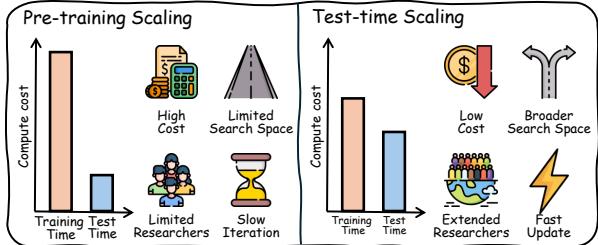
方法:会议状态明确,但它是 survey;适合用来快速定位多模态推理/生成 inference-time scaling,而非精读 SSL 方法
高相关;详见方法、贡献和实验边界。
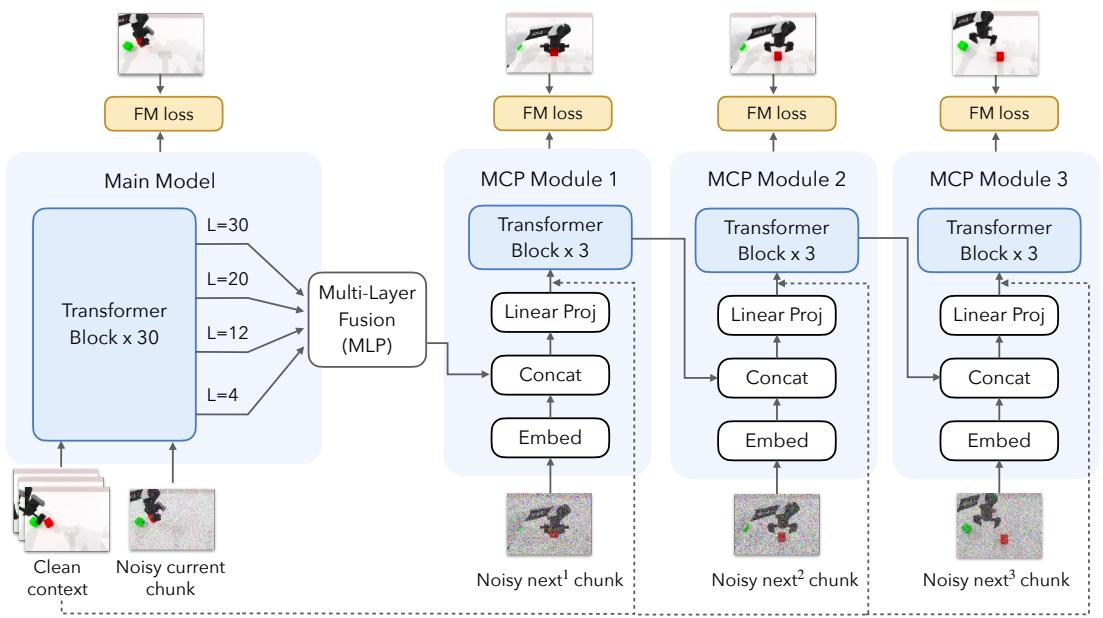
方法:用多未来 chunk 预测给 causal video world model 更密集的时间监督,和视频自监督/latent prediction 主线高度相关
高相关;详见方法、贡献和实验边界。
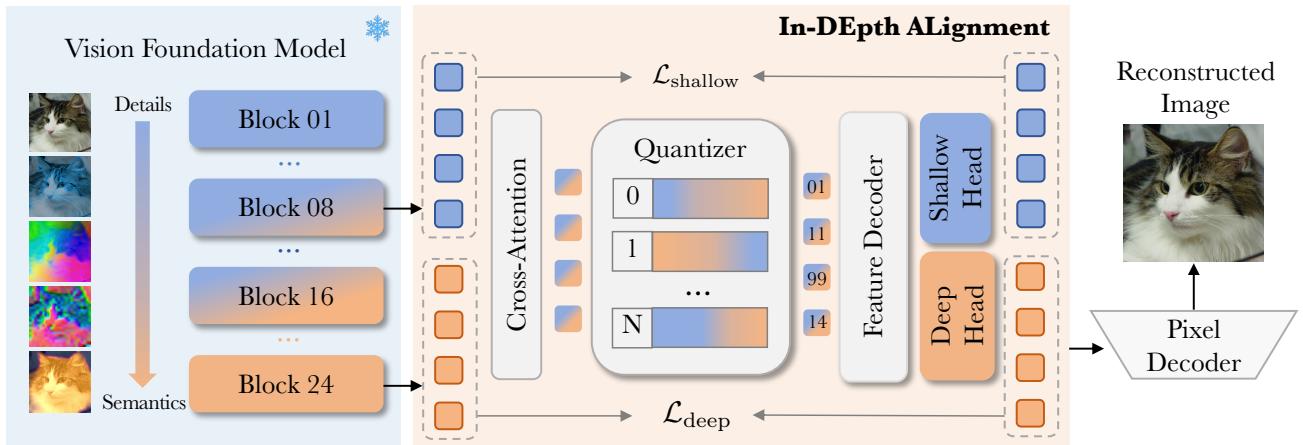
方法:直接面向 VFM-based RAE 的离散 latent:同时对齐浅层细节与深层语义,适合优先精读
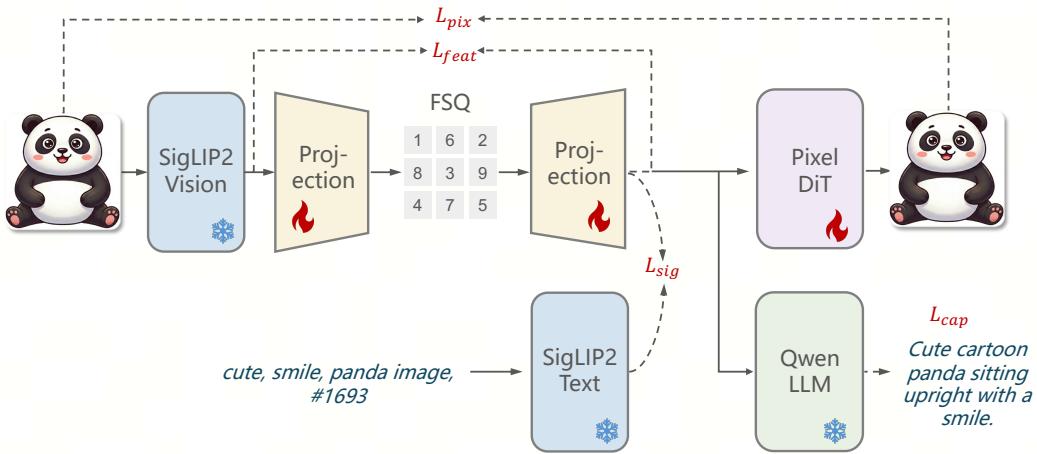
高相关;详见方法、贡献和实验边界。
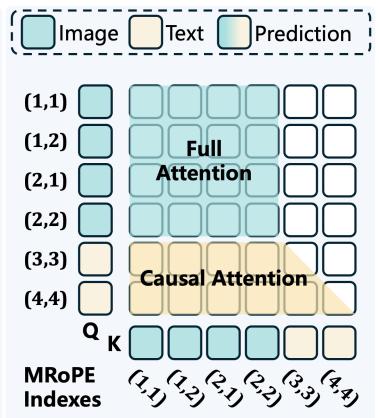
方法:训练离散语义视觉 tokenizer,并把图像理解、生成、编辑统一到 next-token prediction
高相关;详见方法、贡献和实验边界。
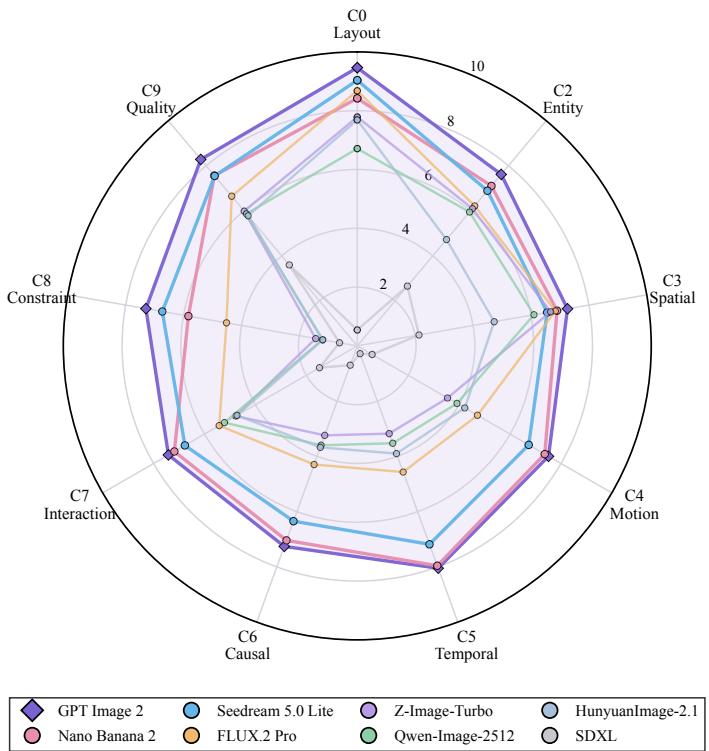
方法:用四关键帧时序一致性 probe 静态图像生成模型的 visual world modeling 能力
高相关;详见方法、贡献和实验边界。
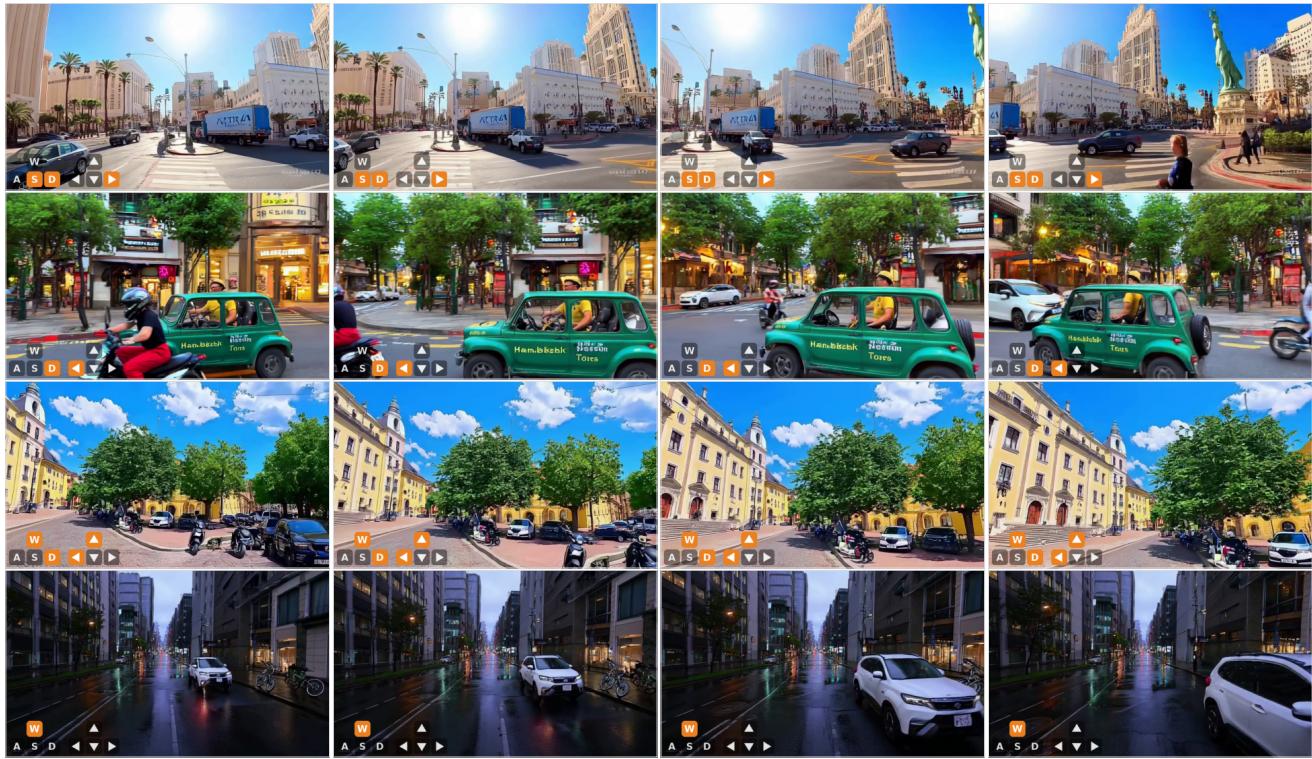
方法:从预训练视频 backbone 出发做双向自回归交互 world model,补充 Next Forcing 的 causal 路线
高相关;详见方法、贡献和实验边界。
方法:GenLIP 用语言建模目标预训练 ViT,不走对比 batch 或额外 text decoder,是视觉语言预训练目标的重要更新
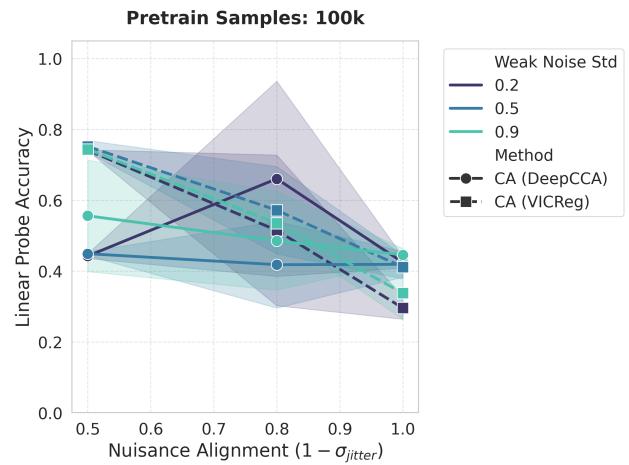
中高相关;详见方法、贡献和实验边界。
方法:给 cross-modal alignment vs prediction 一个相图,用于判断图文/多模态自监督目标何时该对齐、何时该预测
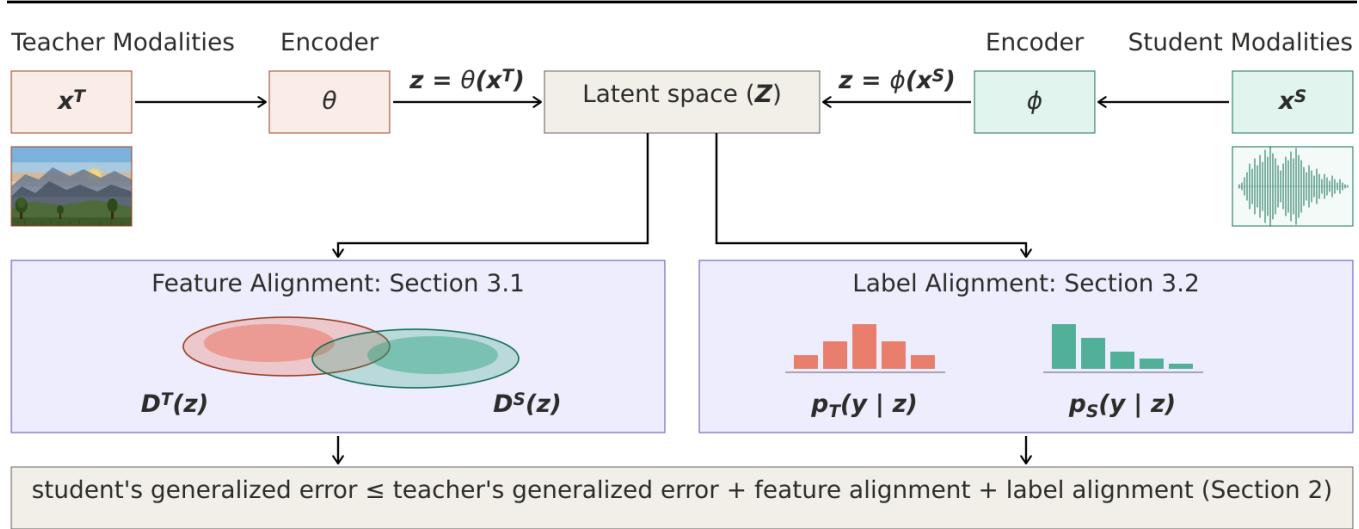
中高相关;详见方法、贡献和实验边界。
方法:无配对跨模态蒸馏,把 teacher/student 差异拆成 feature alignment 和 label alignment
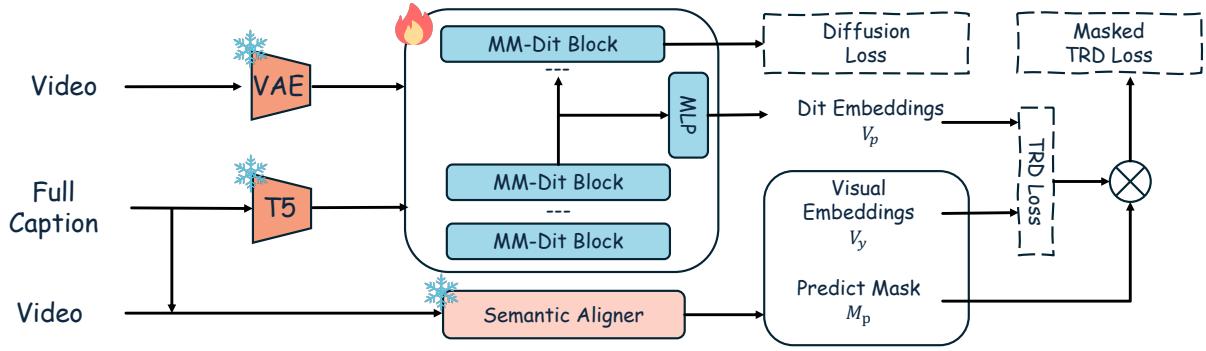
中高相关;详见方法、贡献和实验边界。
方法:用冻结 VFM 的 token-relation distillation 和文本条件 saliency 改善视频扩散的语义对齐
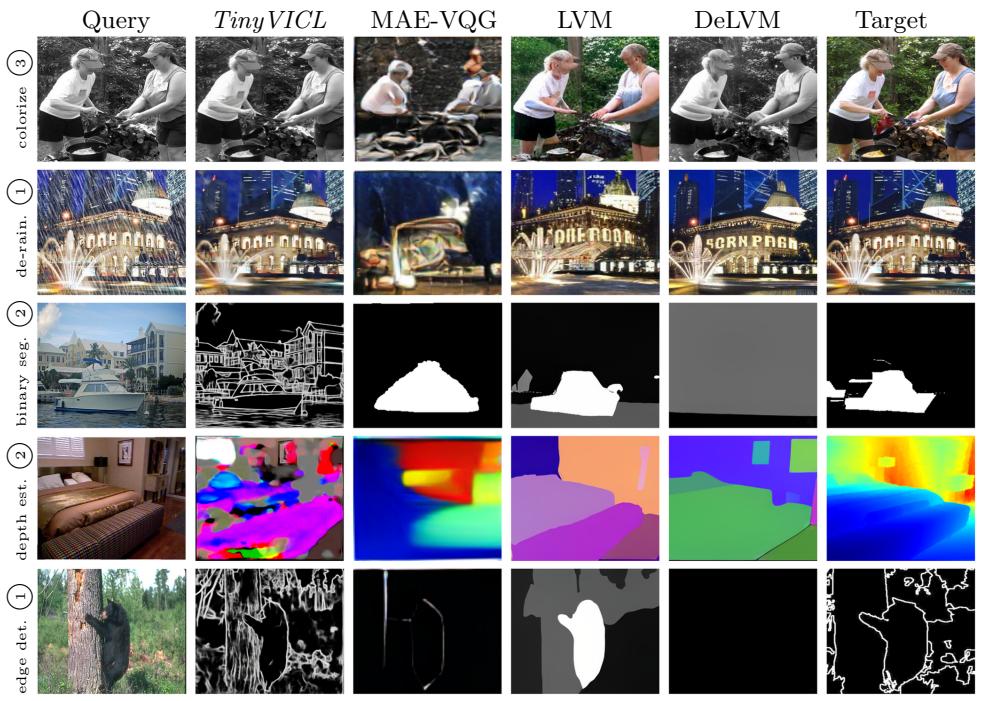
中高相关;详见方法、贡献和实验边界。
方法:用 1M 参数 tiny VICL 模型反证“大模型规模=视觉 in-context 能力”的评估假设
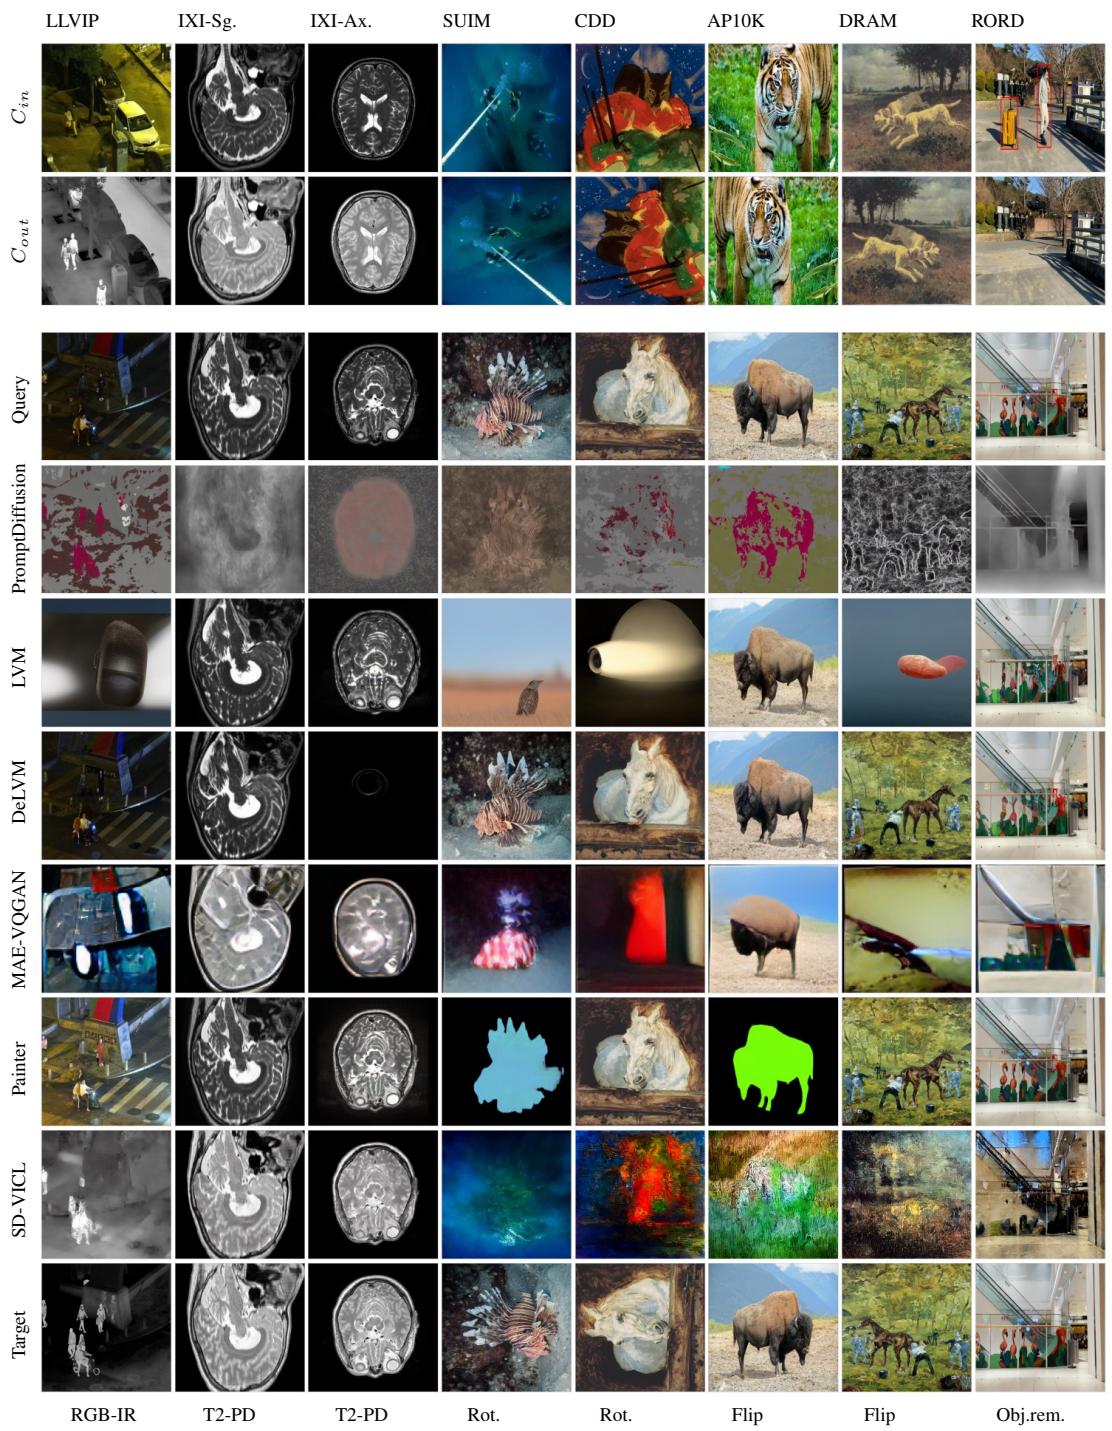
中高相关;详见方法、贡献和实验边界。
方法:VIBE 覆盖 14 数据集、12 任务,系统测试视觉 in-context model 是否真的能跨任务/域适应
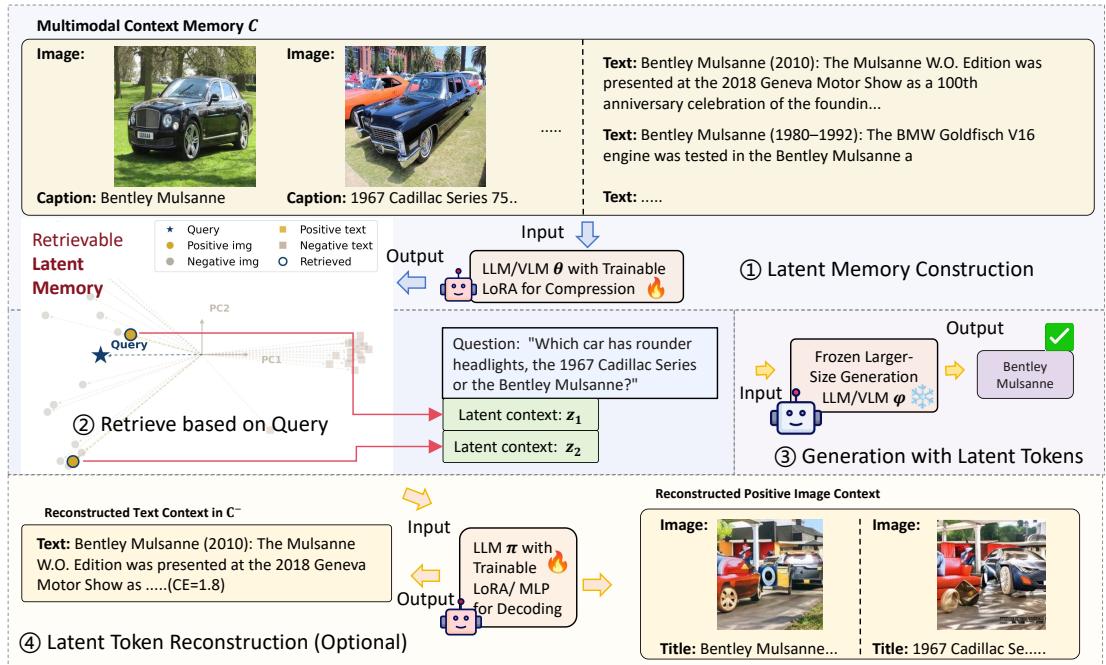
中相关;详见方法、贡献和实验边界。
方法:把图文 evidence 压成单个 latent token,用重建、对比和蒸馏训练,偏 VLM memory 但对视觉 latent 接口有参考
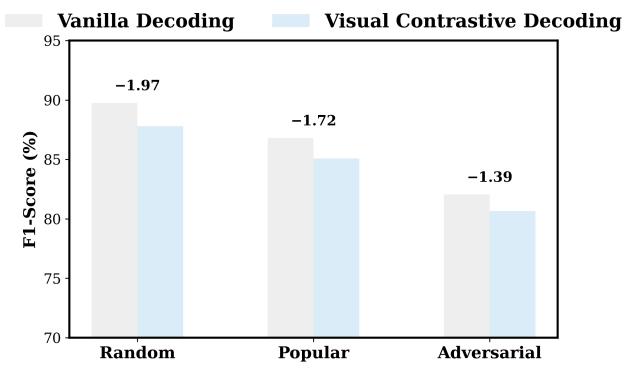
中相关;详见方法、贡献和实验边界。
方法:ICML regular;从 hidden-state 子空间角度减少 VLM 语言先验幻觉,适合作为视觉证据读出诊断扫读
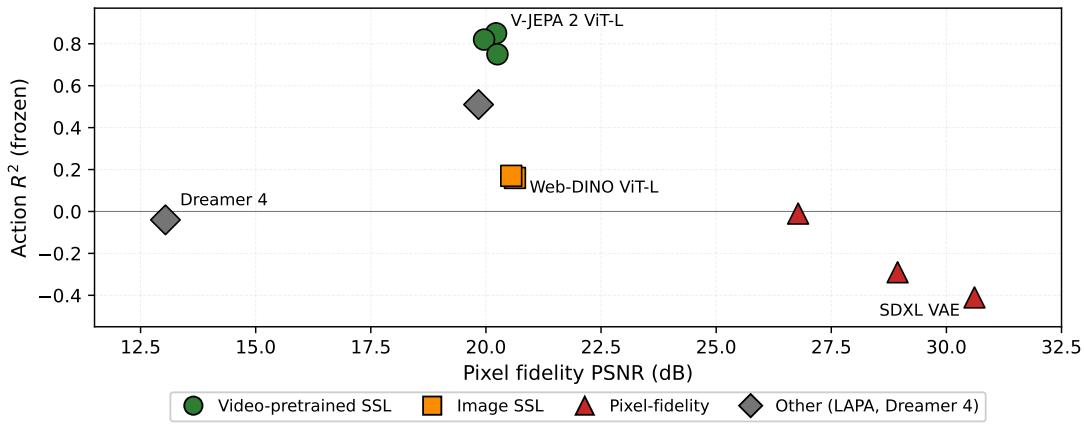
高相关;详见方法、贡献和实验边界。
方法:直接比较 image-only SSL、VideoMAE/V-JEPA、autoencoder、diffusion 等预训练信号,回答哪些 latent 真正携带 action-relevant 视频结构
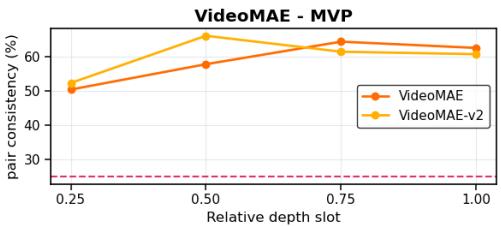
高相关;详见方法、贡献和实验边界。
方法:冻结 V-JEPA、VideoMAE、video diffusion 等模型逐层 probing 物理常识,适合判断视频 SSL 表征是否学到动态规律
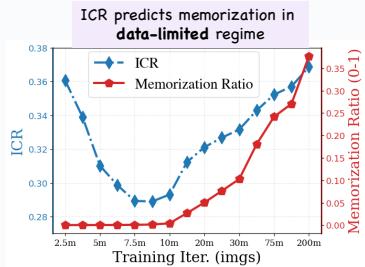
高相关;详见方法、贡献和实验边界。
方法:用 SSL 的 invariant/residual 分解来评估 diffusion feature,是连接生成模型与视觉自监督表示几何的高价值诊断
高相关;详见方法、贡献和实验边界。
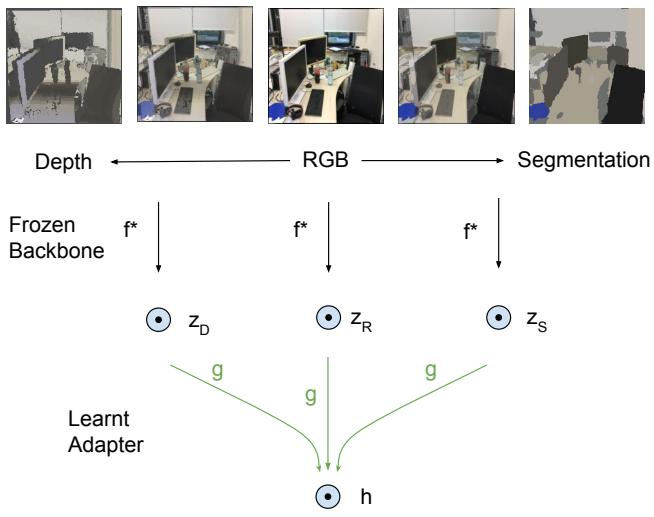
方法:用 DINOv2 teacher distillation 与跨 RGB/depth/segmentation 对齐,把单一视觉 encoder 推向 modality-agnostic feature space
高相关;详见方法、贡献和实验边界。
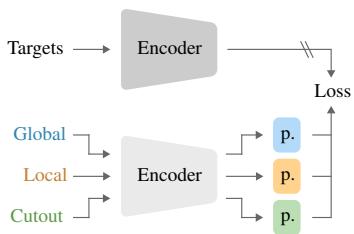
方法:直接针对 BYOL/SimSiam/MoCo v3 的 multi-crop instability,把不同空间变换视为不同 latent alignment task
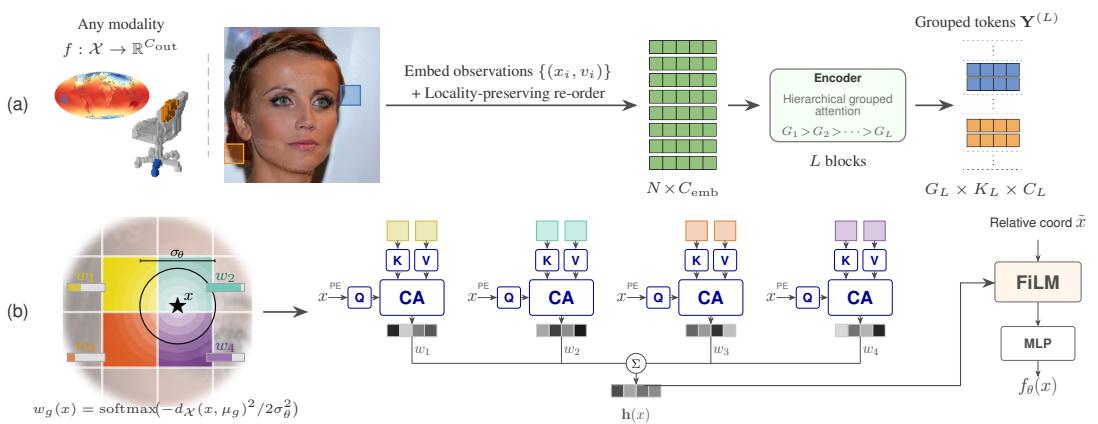
中高相关;详见方法、贡献和实验边界。
方法:把连续信号 neural fields 变成层次化 token 表征,对图像、视频、3D/implicit representation 的统一 tokenization 有启发
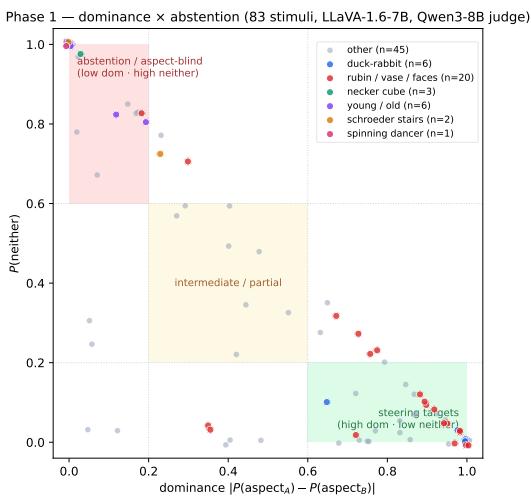
中高相关;详见方法、贡献和实验边界。
方法:在 LLaVA 消费的 CLIP 层训练 TopK SAE,分析 ambiguous image captioning 中 vision tower 与 language head 的不对称
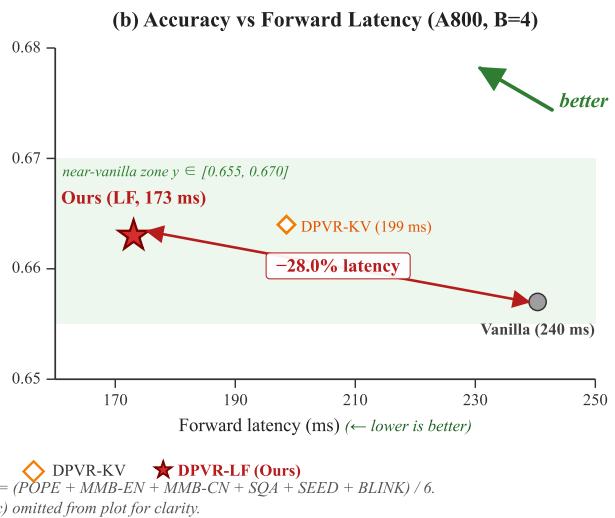
中高相关;详见方法、贡献和实验边界。
方法:指出 vision tokens 在 MLLM 中层后趋于饱和,提供视觉 token 深层路由/迟融合的表征接口诊断
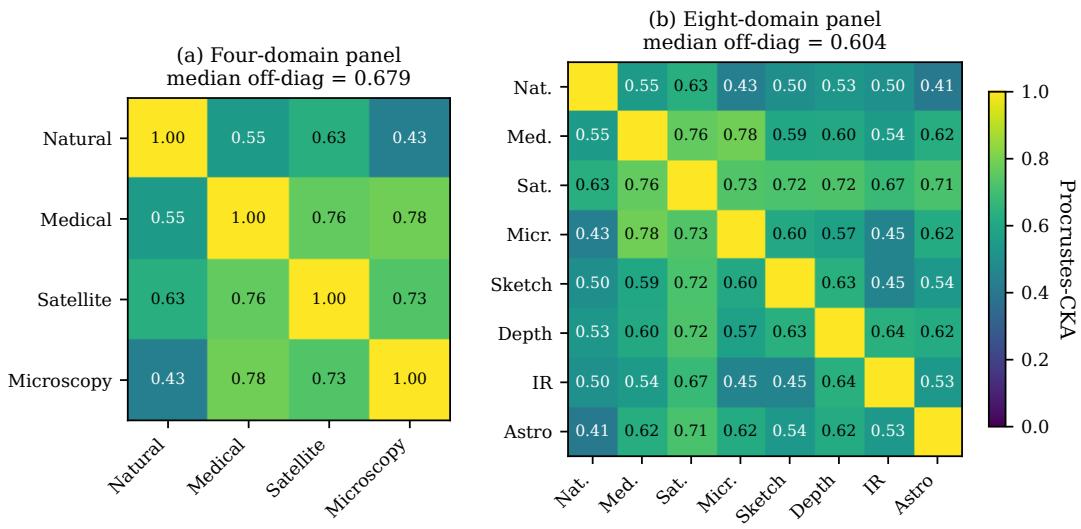
中相关;详见方法、贡献和实验边界。
方法:声称不同训练范式的 vision encoders 收敛到共享低维几何子空间,若成立,对表征相似性和迁移评估很有参考
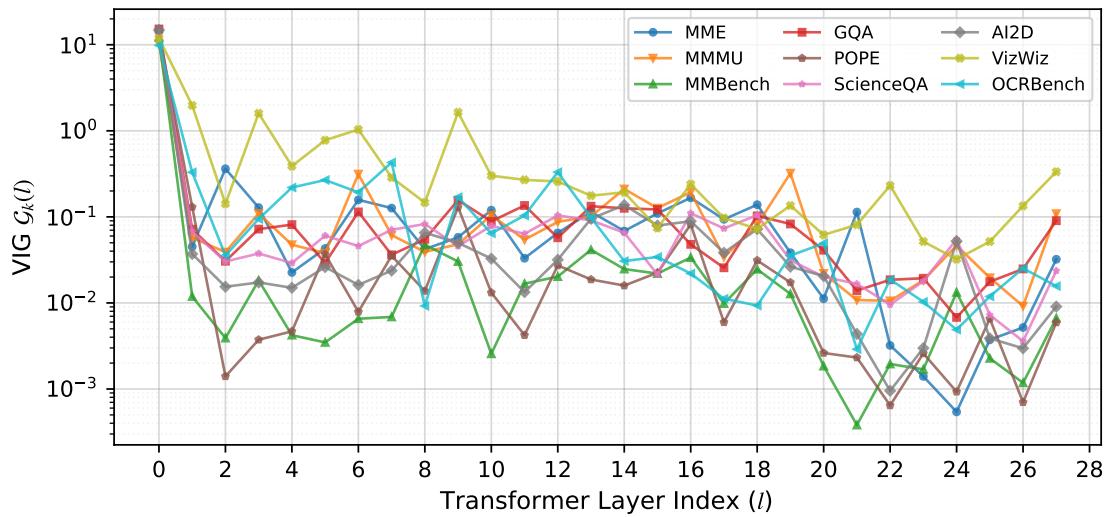
中相关;详见方法、贡献和实验边界。
方法:同样围绕 visual attention saturation,但更偏 training-free inference efficiency;适合和 DPVR-LF 对照扫读
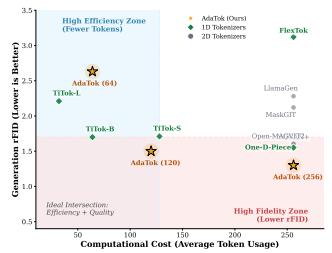
高相关;详见方法、贡献和实验边界。
方法:把离散 1D image tokenizer 的 token budget 学成内容条件输出,连接 visual tokenization、latent compression 和 AR image generation
高相关;详见方法、贡献和实验边界。
方法:用 caption-conditioned sparse autoencoder editing 精简 CLIP image embedding,直接服务图文表征对齐
高相关;详见方法、贡献和实验边界。
方法:ViSAE 把 SAE 概念分解、自动解释和 causal circuit tracing 接到 ViT,是理解/steering 视觉表征的高价值工具
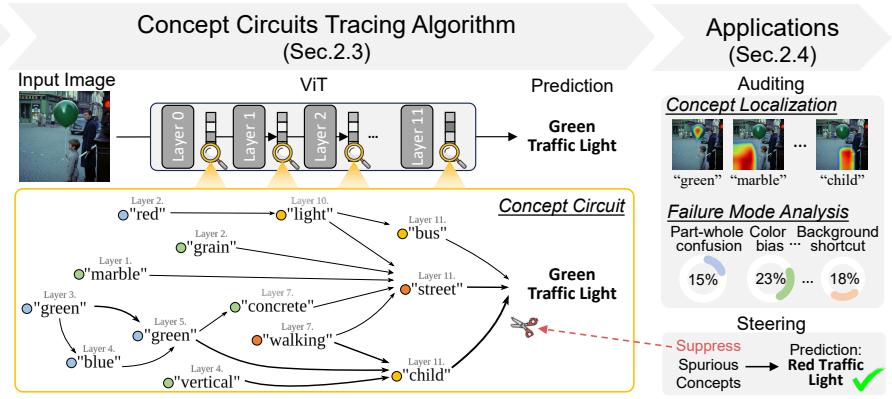
高相关;详见方法、贡献和实验边界。
方法:把光照变化从“要被增强抹掉的 nuisance”改成显式训练信号,扩展 contrastive visual representation learning
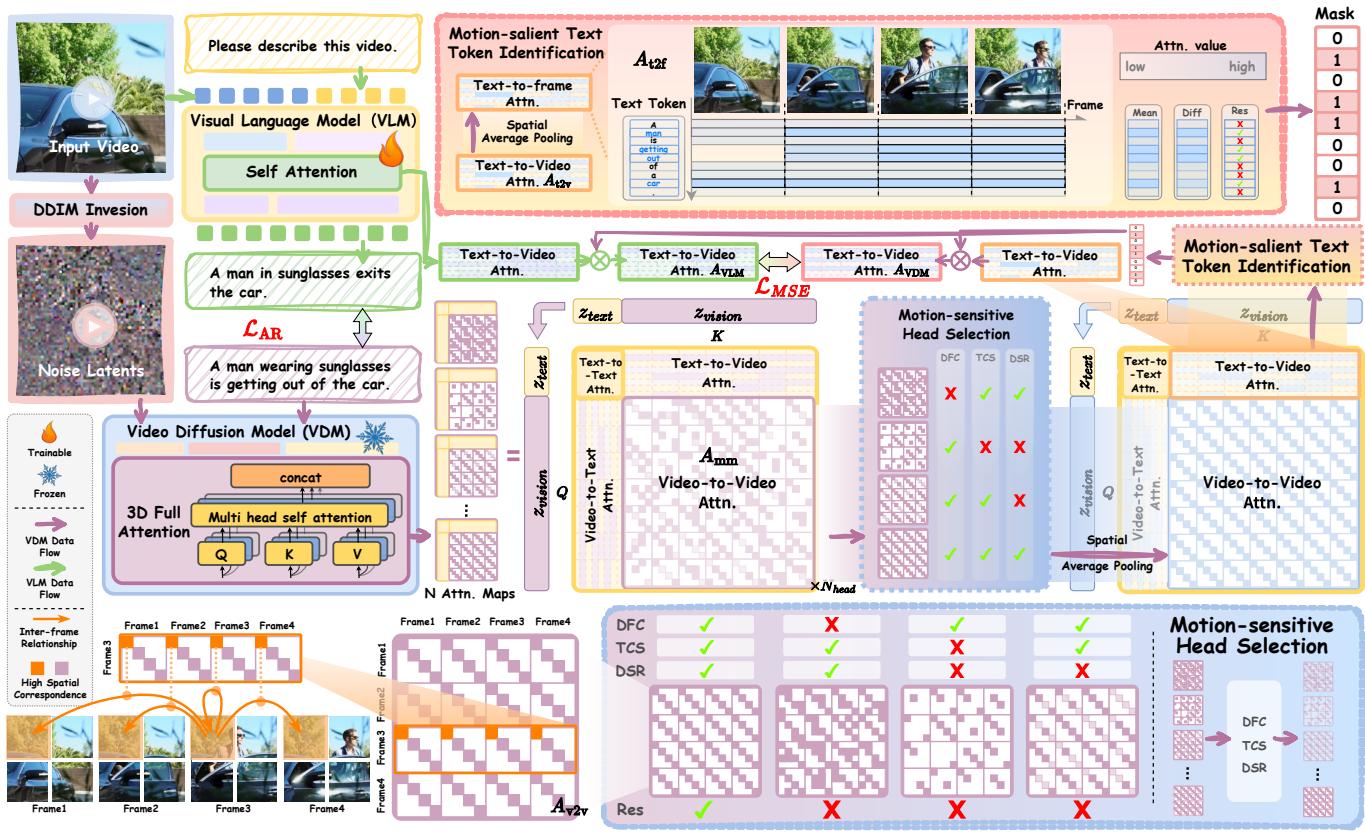
中高相关;详见方法、贡献和实验边界。
方法:从 video diffusion model 蒸馏 motion attention prior 给 video VLM,适合跟踪视频表征和生成模型监督的交叉
中高相关;详见方法、贡献和实验边界。
方法:用层替换、MLP probing 和视觉衰减指标诊断 VLM 如何丢失视觉证据,是 V-L 自监督评估的强信号
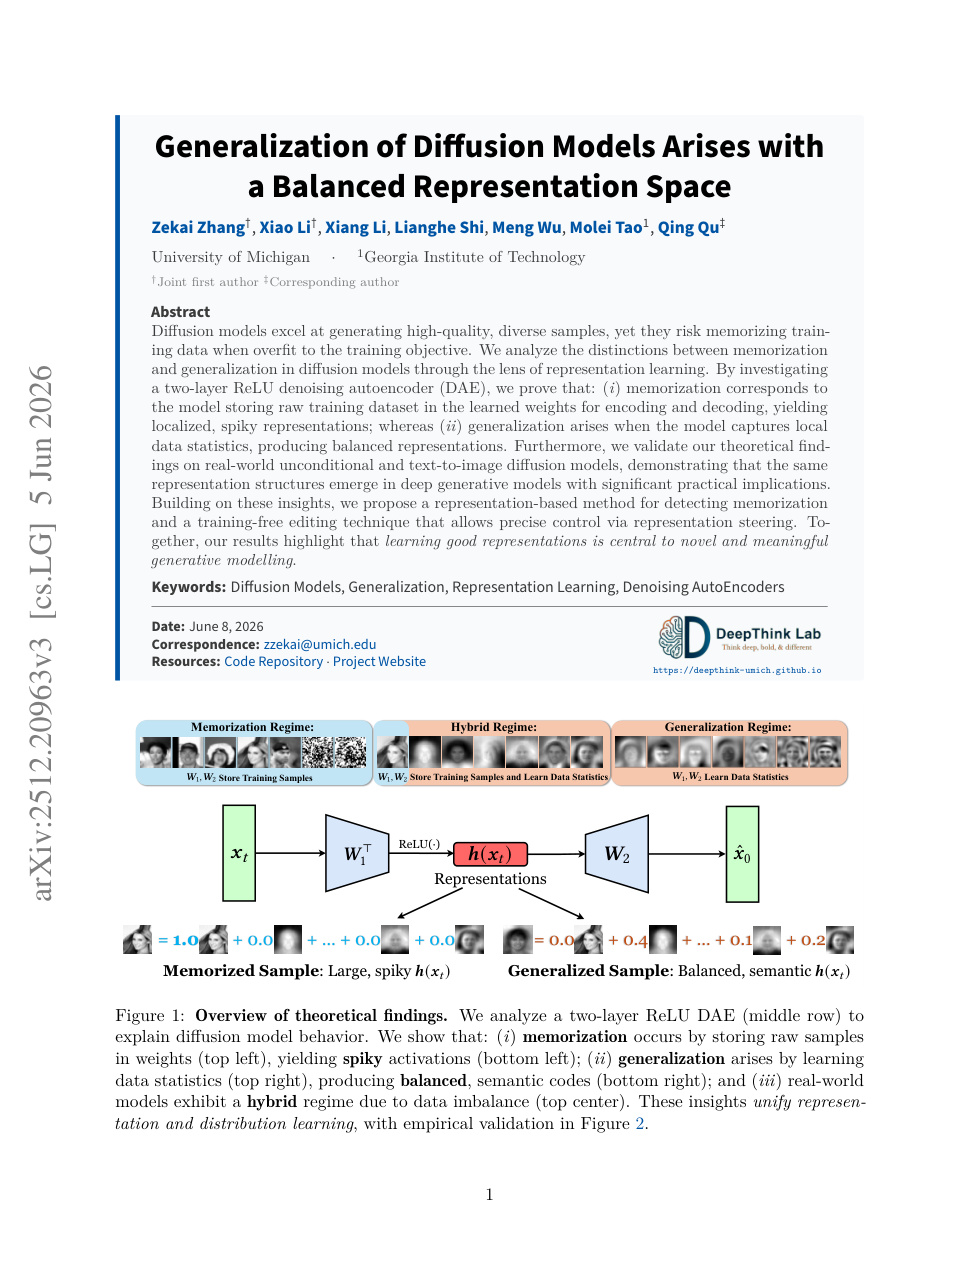
中高相关;详见方法、贡献和实验边界。
方法:从 representation geometry 解释 diffusion memorization/generalization,对 latent diffusion 与 RAE 线索有理论参考
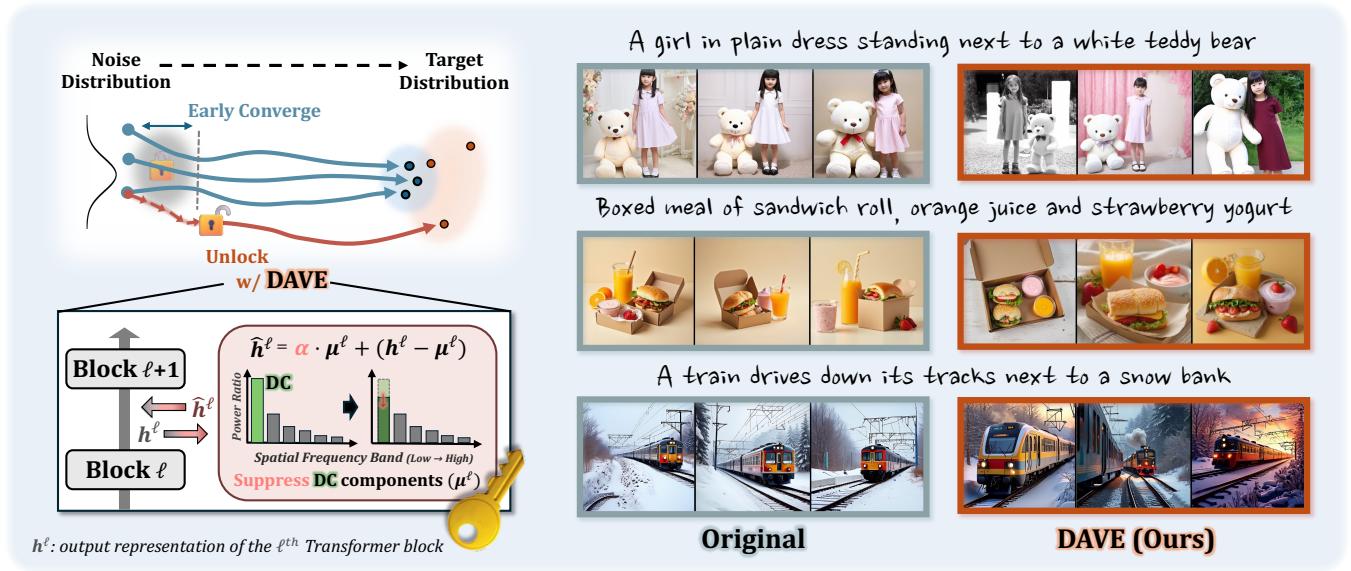
中相关;详见方法、贡献和实验边界。
方法:在 diffusion transformer 中对早期 DC feature 做 training-free modulation,说明生成多样性也可从表征频率成分入手
中相关;详见方法、贡献和实验边界。
方法:指出 VLM spatial binding 的主信号来自 vision encoder 的全局 token 表征,适合作为 VLM 表征诊断读物
中相关;详见方法、贡献和实验边界。
方法:用网络权重扰动替代数据扰动生成 contrastive samples,实验偏雷达科学数据,但思想可迁移
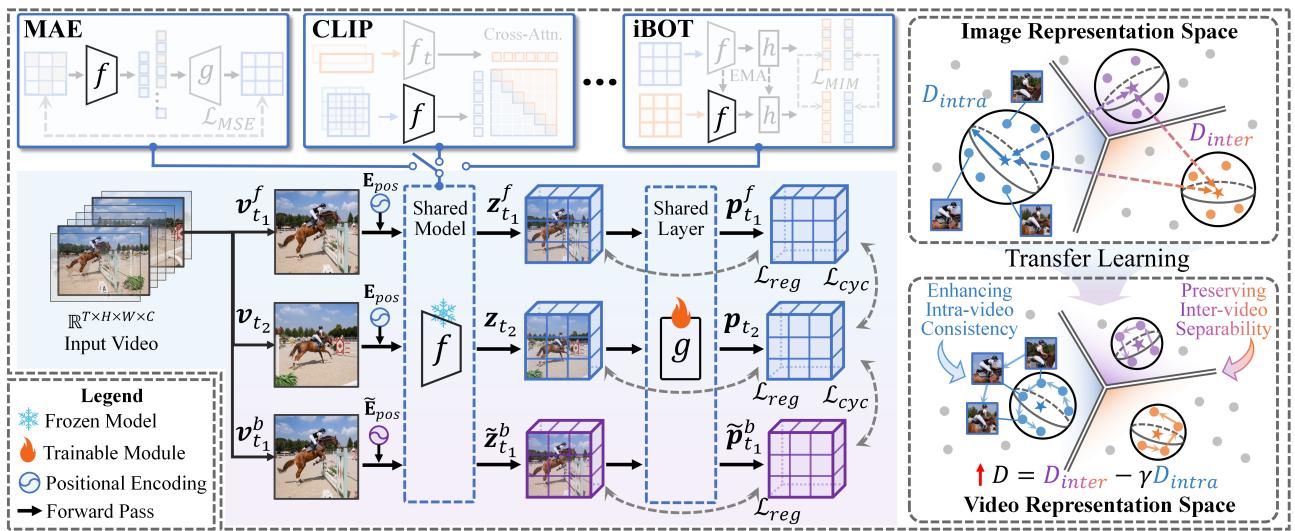
高相关;详见方法、贡献和实验边界。
方法:冻结 image-pretrained encoder,只学轻量投影并同时优化时序一致性与跨视频语义分离,直接切中视频表征迁移
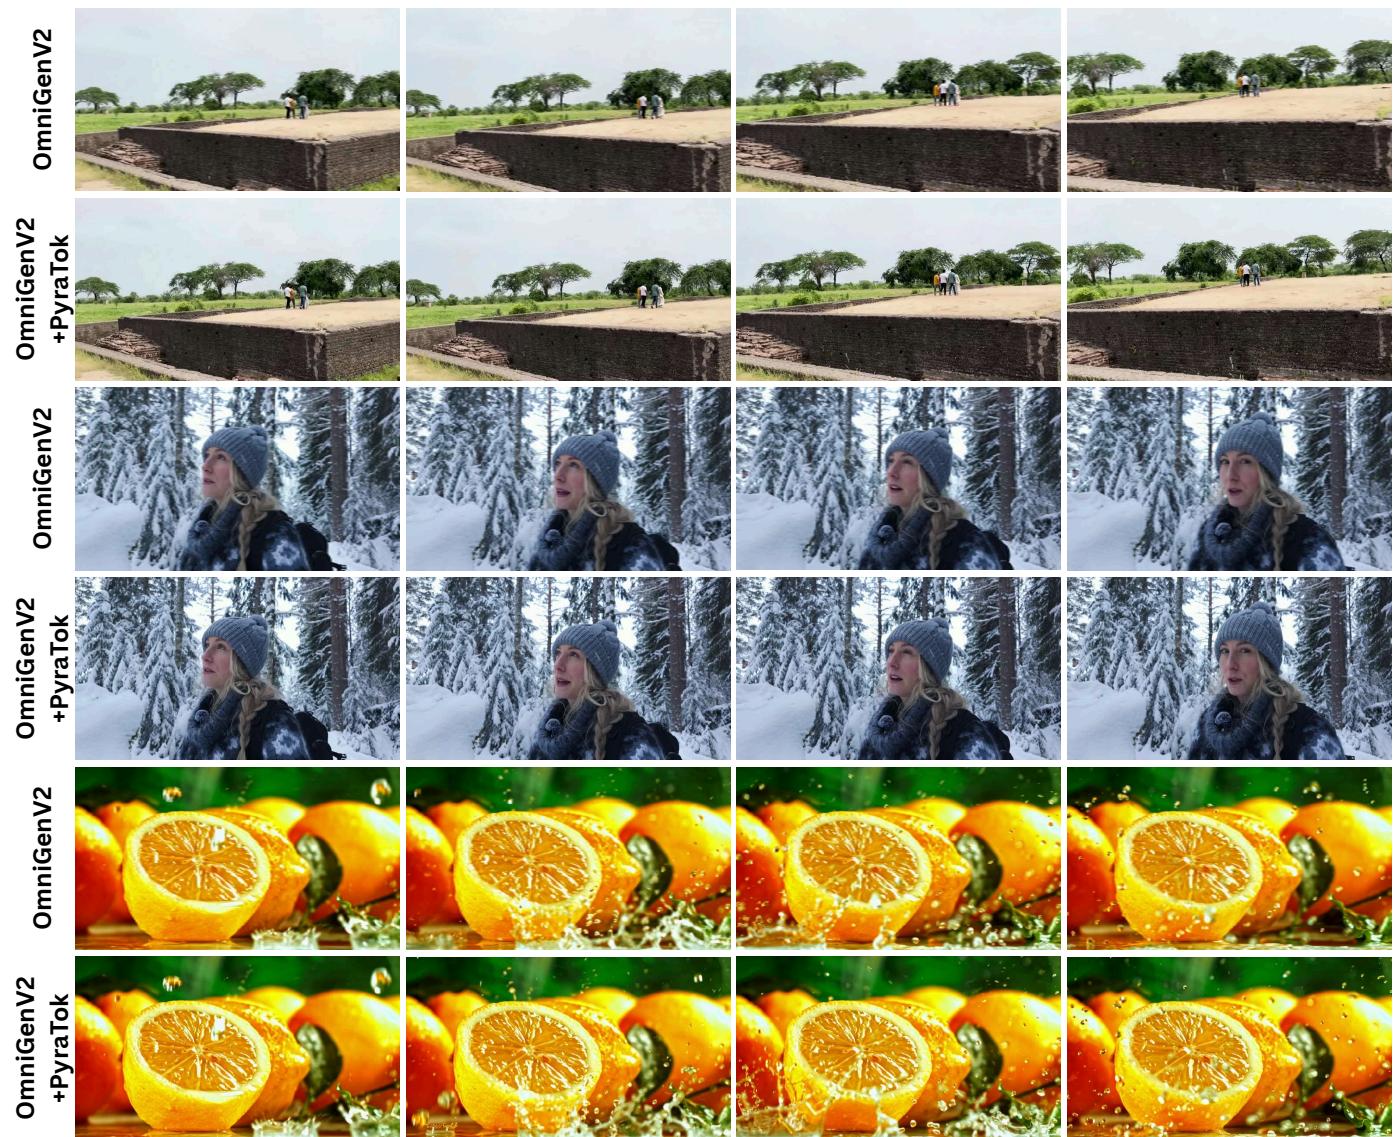
高相关;详见方法、贡献和实验边界。
方法:多尺度语言对齐 video tokenizer 同时提升重建、生成和 zero-shot 视频理解,是今天最值得跟的 tokenization 工作
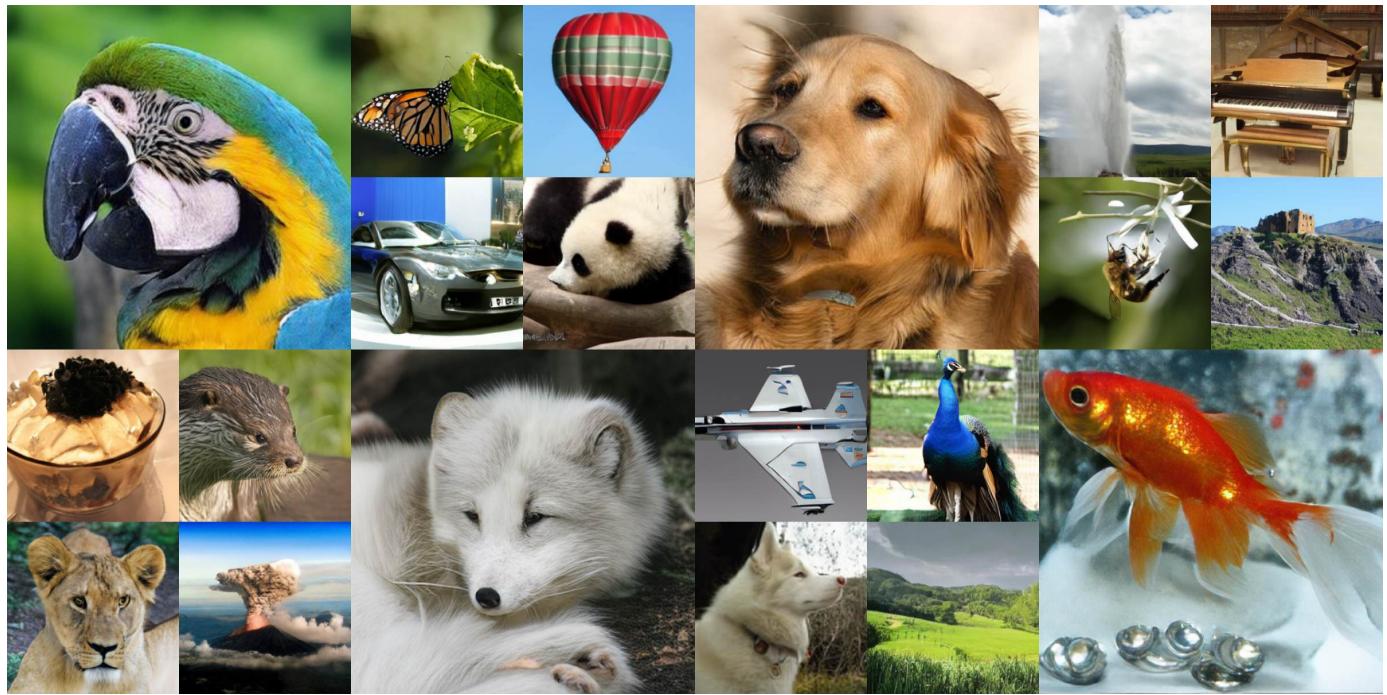
高相关;详见方法、贡献和实验边界。
方法:用 masking 与 DINO-guided semantic masking 防止连续 tokenizer posterior collapse,对紧凑图像 latent 表征很关键
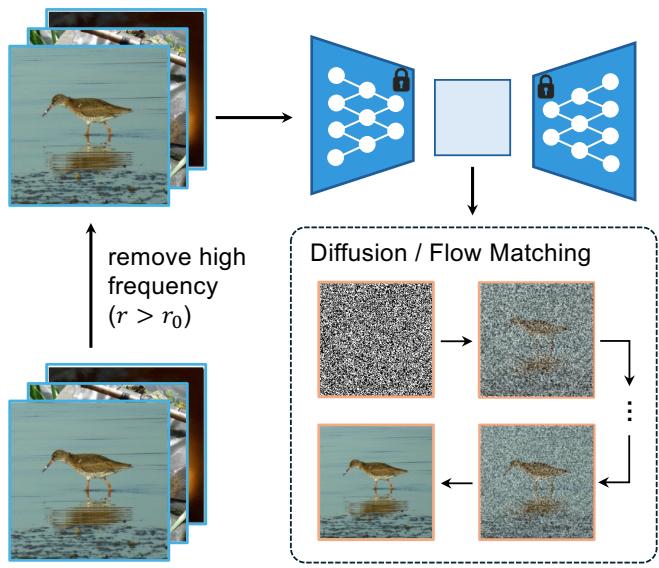
高相关;详见方法、贡献和实验边界。
方法:从频率角度解释高维 autoencoder latent 的生成困难,并提出不改 autoencoder 的 FreqWarm 训练策略
高相关;详见方法、贡献和实验边界。
方法:用普通视频生成点云再做 3D SSL,给“视频作为 3D 表征预训练数据源”提供强证据
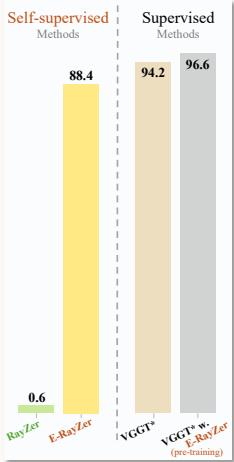
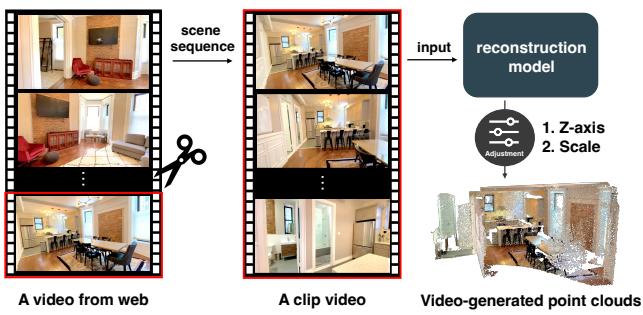
高相关;详见方法、贡献和实验边界。
方法:把 self-supervised 3D reconstruction 显式作为 spatial visual pre-training,补齐 2D/video SSL 到 3D-aware 表征的桥
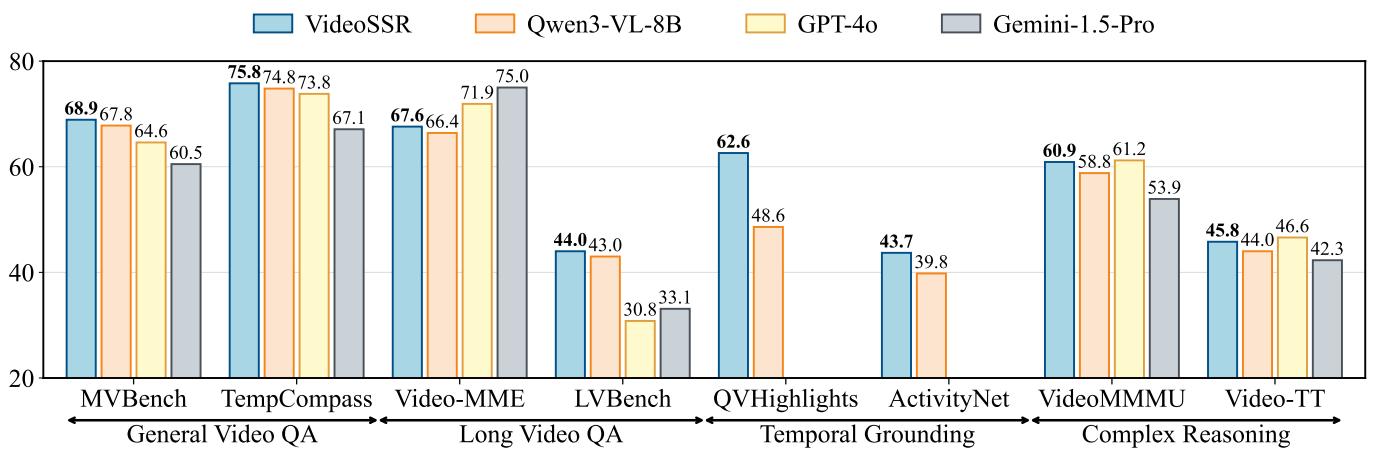
中高相关;详见方法、贡献和实验边界。
方法:用视频内生 pretext tasks 构造 RLVR 训练数据,对 video MLLM 的自监督后训练有直接参考
中高相关;详见方法、贡献和实验边界。
方法:动态 mask ratio + progressive distillation,是今天最标准的 masked video SSL 论文,但暂未定位到 arXiv ID
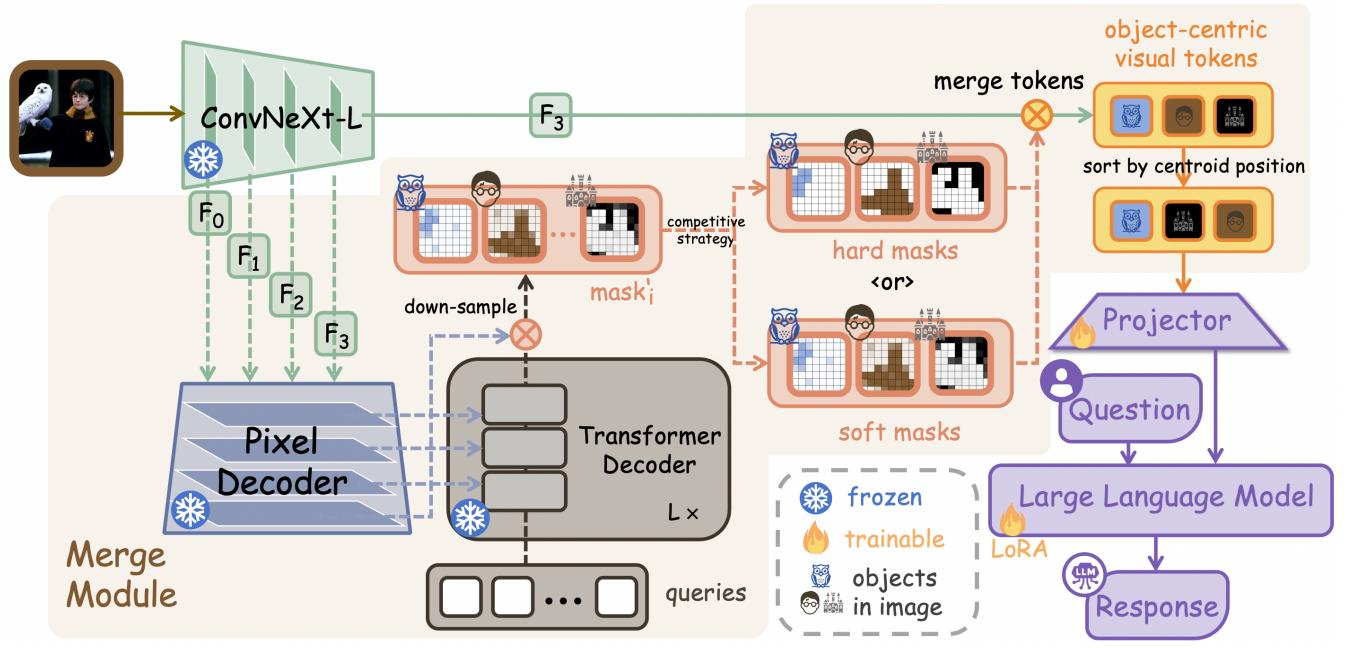
中高相关;详见方法、贡献和实验边界。
方法:用 object masks 引导 LVLM token merging,说明高层 object-centric 表征比纯几何压缩更稳
中相关;详见方法、贡献和实验边界。
方法:属于 CLIP dense perception 对齐增强;对通用 V-L 表征有参考,但更偏 OVDP 下游鲁棒性
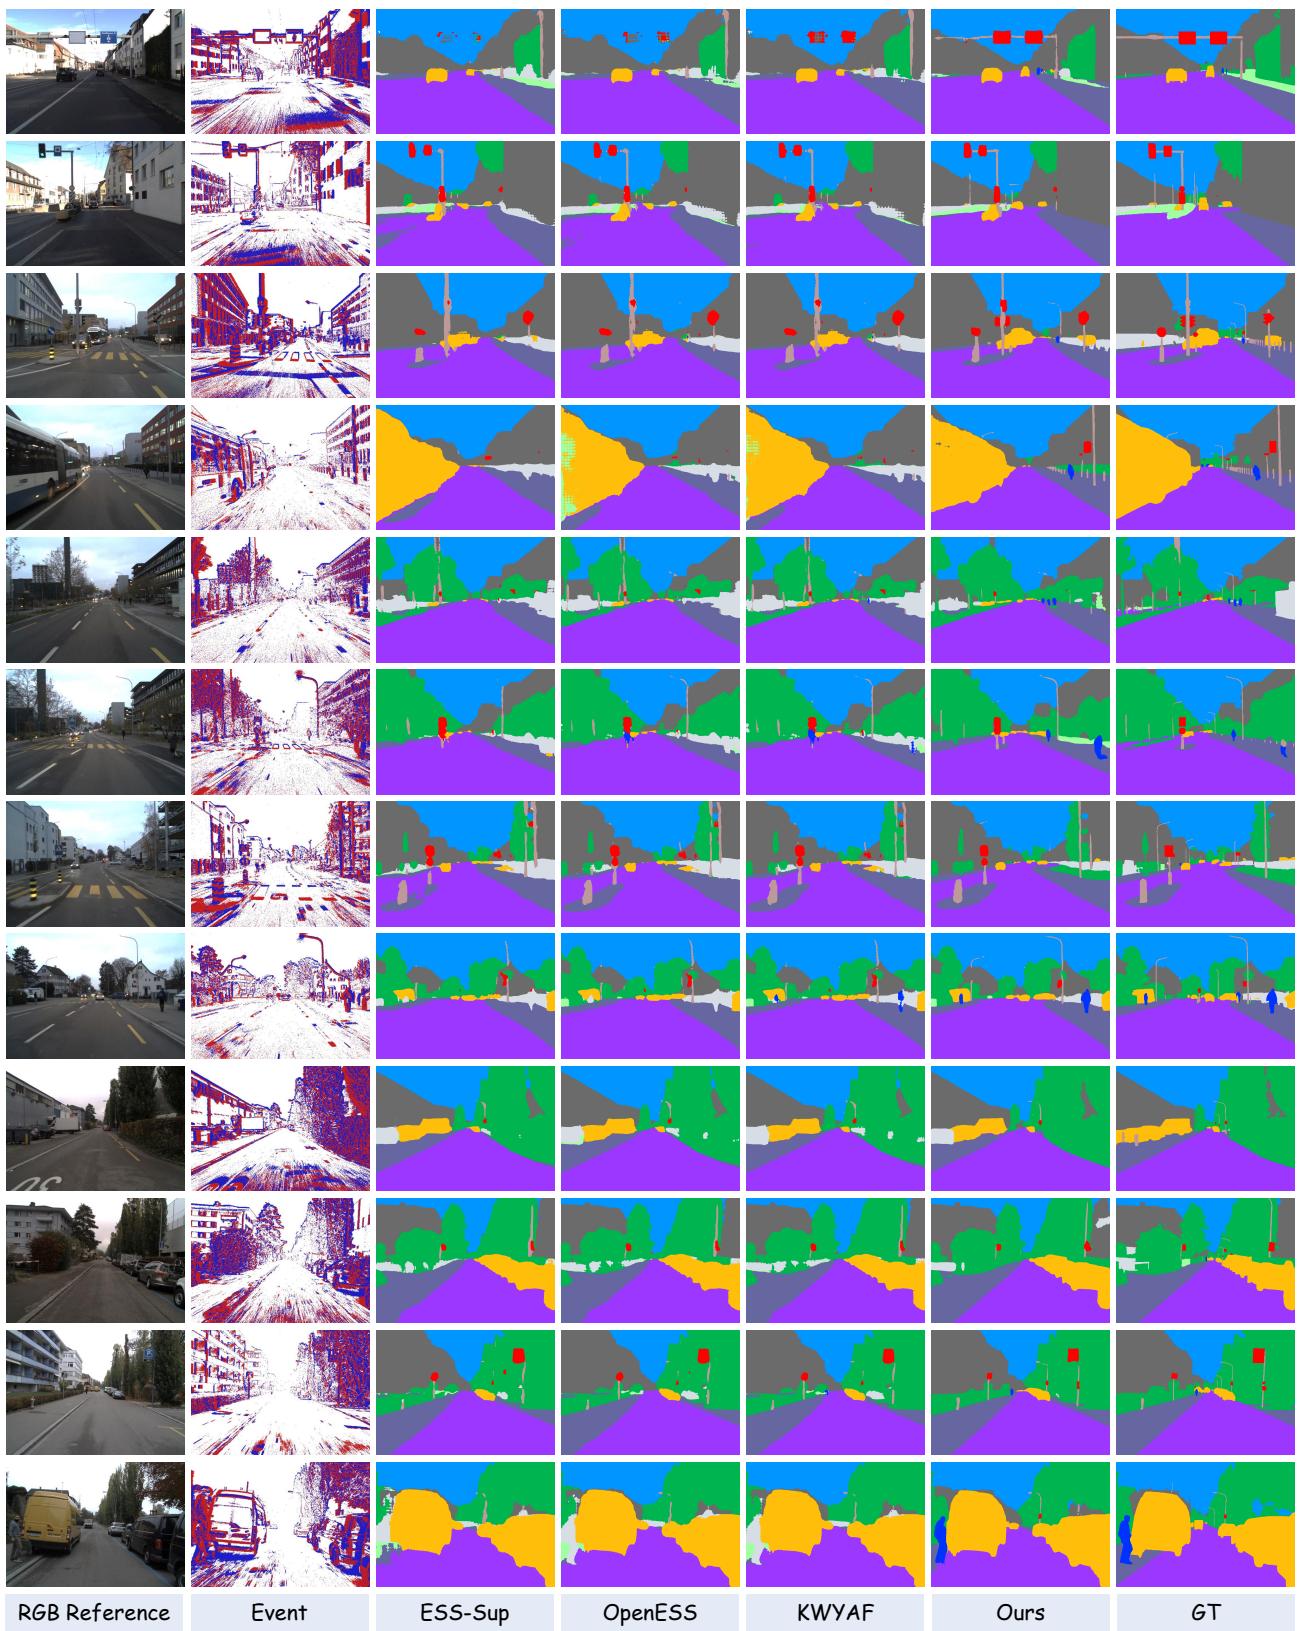
中相关;详见方法、贡献和实验边界。
方法:event camera 模态较专,但 VFM 蒸馏到异构视觉流的结构对齐思路可迁移
高相关;详见方法、贡献和实验边界。
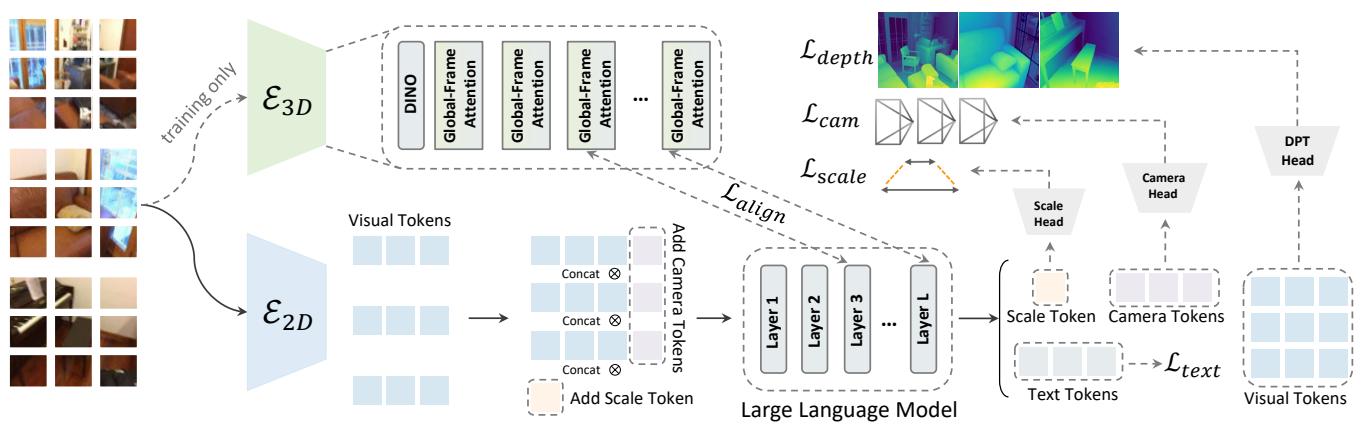
方法:GeoVR 用纯 2D video 与 3D foundation teacher 重塑 MLLM 几何表征,是今天最强的视频/空间表征候选
高相关;详见方法、贡献和实验边界。
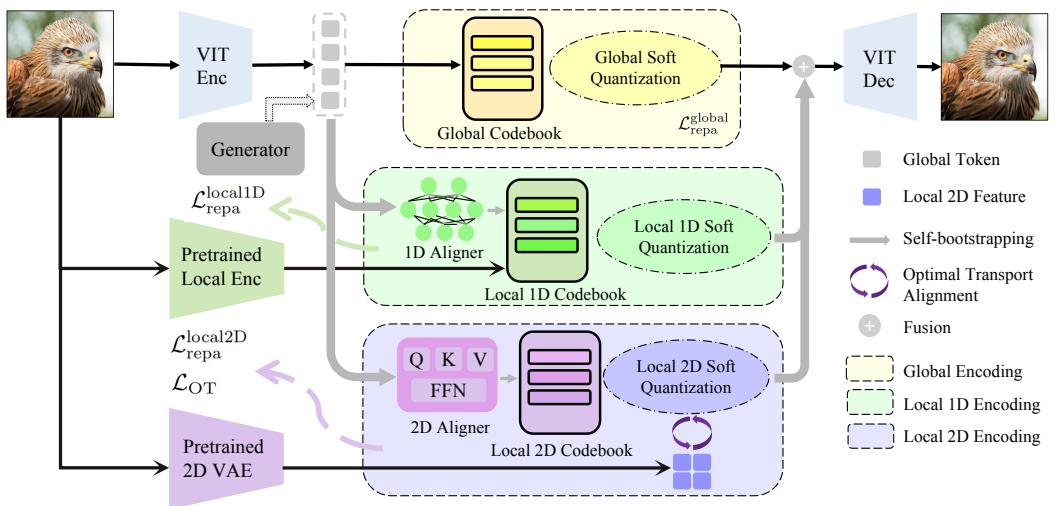
方法:SelfBootTok 把视觉 token 分成 global/local 组,并用 self-bootstrapping 让 tokenizer 承担局部细节学习
高相关;详见方法、贡献和实验边界。
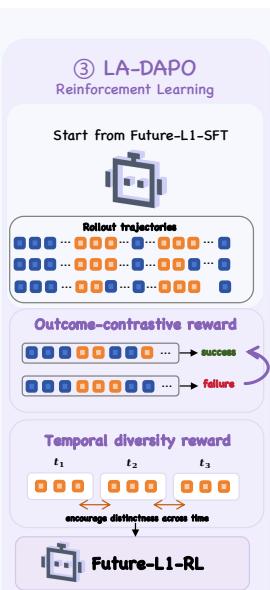
方法:Future-L1 让视频 MLLM 在生成中交替使用语言 token 与连续视觉 latent span,针对视觉语义被文本化损失的问题
高相关;详见方法、贡献和实验边界。
方法:通过反演视频扩散轨迹发现物理可行性可从 DiT 状态线性解码,提示生成式预训练隐含视觉物理表征
中高相关;详见方法、贡献和实验边界。
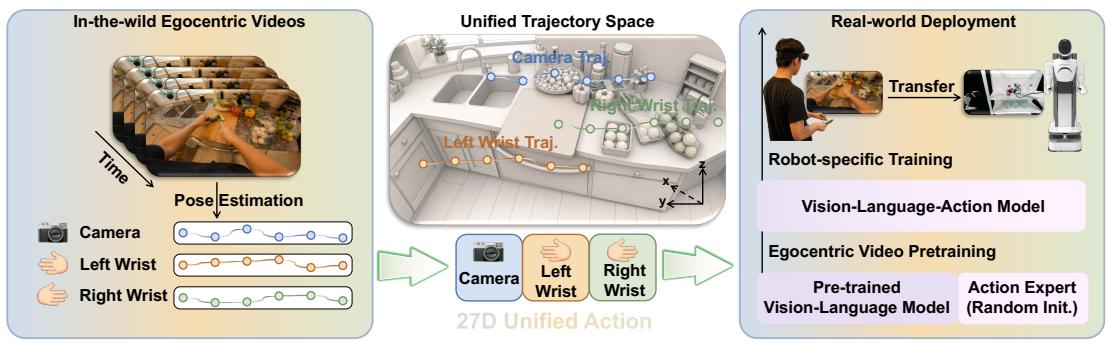
方法:从人类第一视角视频恢复相机/手腕轨迹,把主动感知当作预训练信号;虽偏机器人,但对视频 SSL 有迁移价值
中高相关;详见方法、贡献和实验边界。
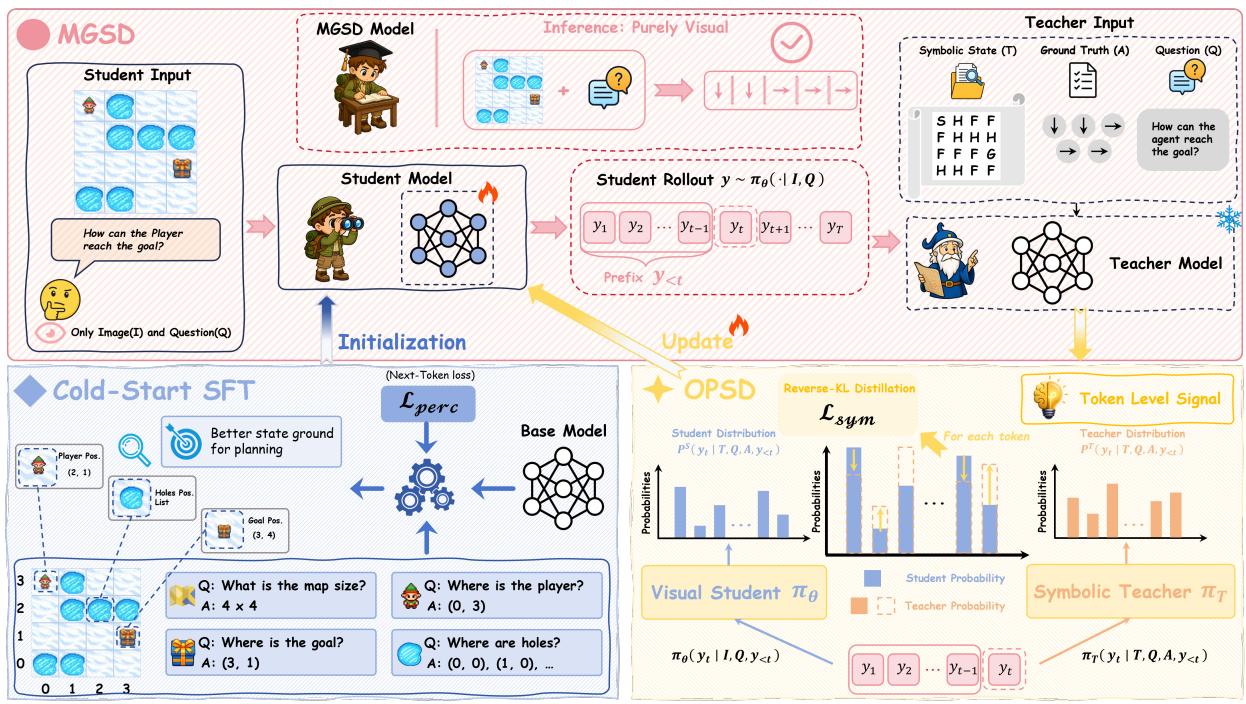
方法:MGSD 用符号状态 teacher 做训练期特权监督,改善纯视觉推理中的 state recovery 与多步规划
中高相关;详见方法、贡献和实验边界。
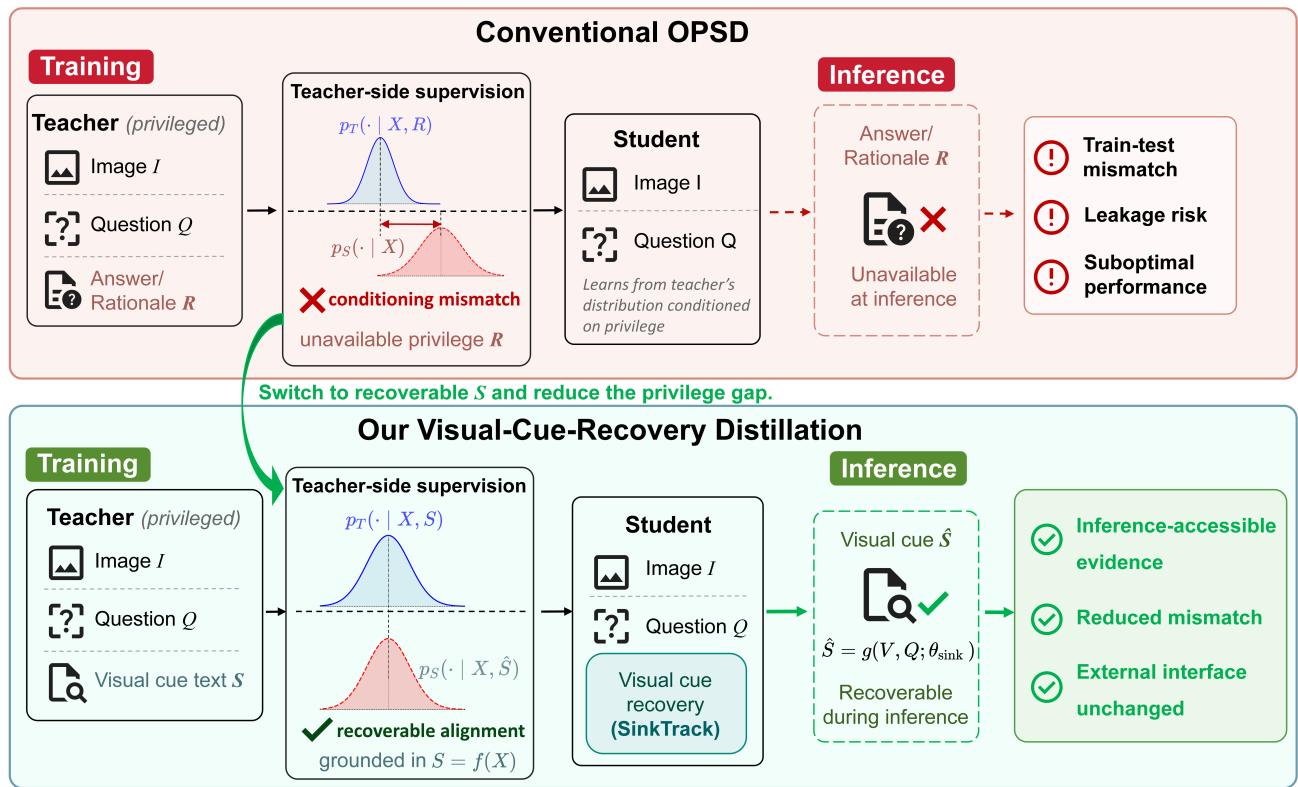
方法:用视觉 cues 而不是答案侧 rationale 做 privileged teacher,避免多模态蒸馏学习不可恢复捷径
中高相关;详见方法、贡献和实验边界。
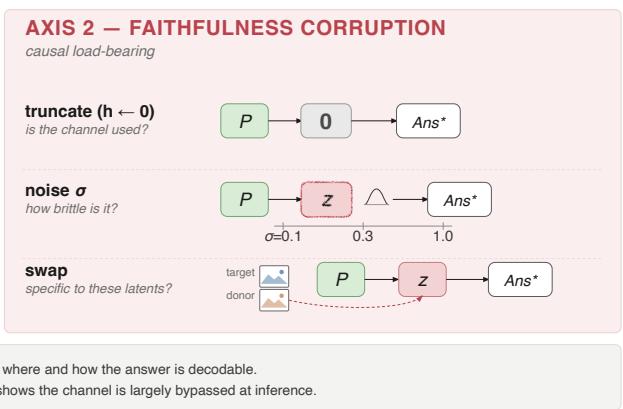
方法:诊断 latent visual reasoning 中 cosine/MSE 对齐指标可能反向误导,提醒看 load-bearing latent 而非表面相似度
中高相关;详见方法、贡献和实验边界。
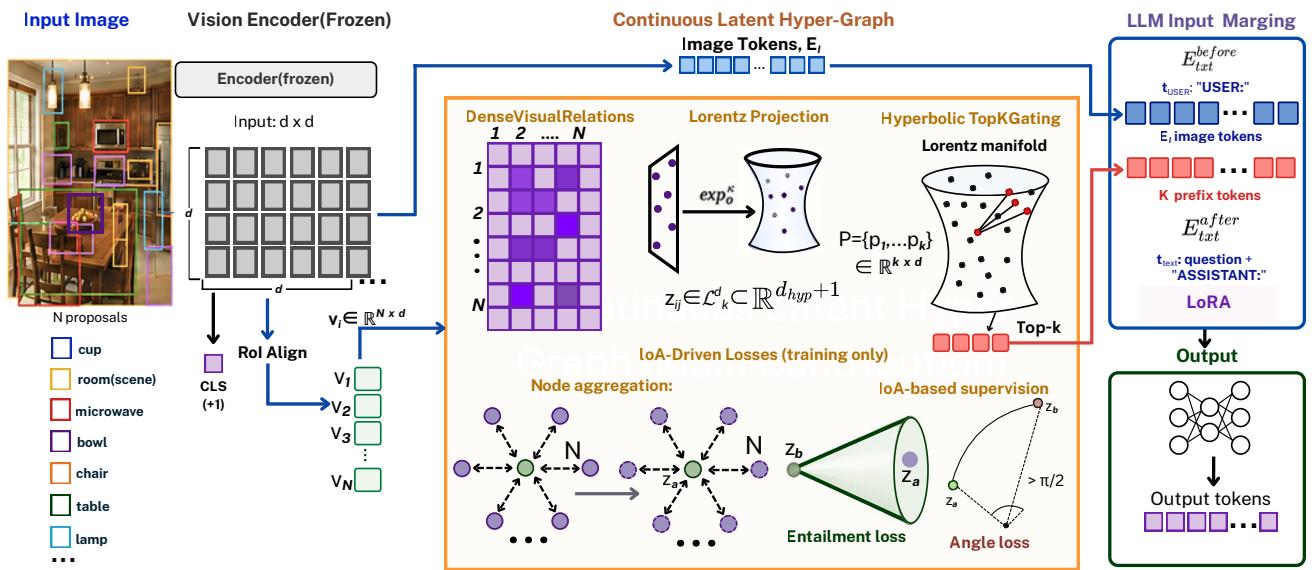
方法:用连续视觉关系张量与双曲几何替代离散 scene graph 文本瓶颈,直接塑形 VLM 关系表征
中高相关;详见方法、贡献和实验边界。
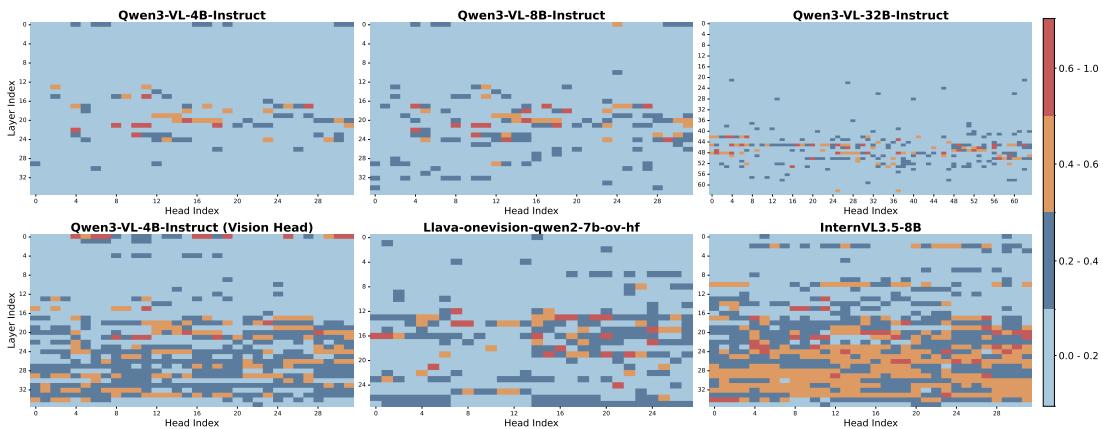
方法:从 attention head 层面定位 MLLM 的 query-relevant visual feature retrieval 机制,可诊断视觉表征如何被读取
中相关;详见方法、贡献和实验边界。
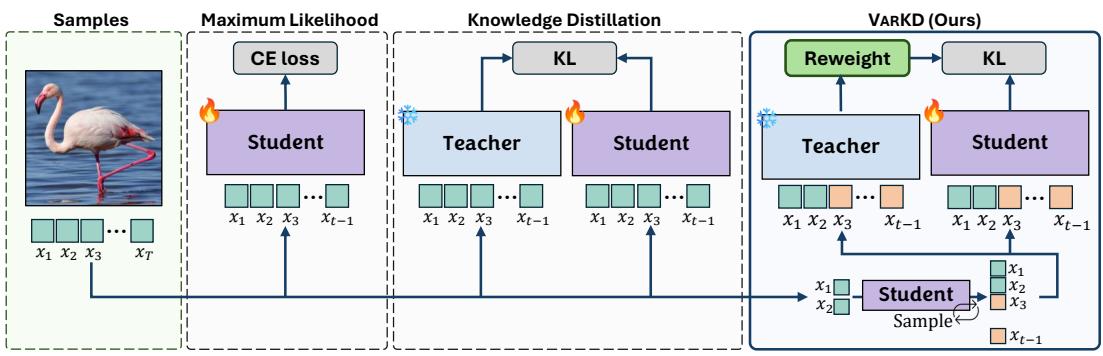
方法:VarKD 是视觉 AR 模型 distillation 系统研究,更多服务生成模型压缩,但涉及 visual token ambiguity
中相关;详见方法、贡献和实验边界。
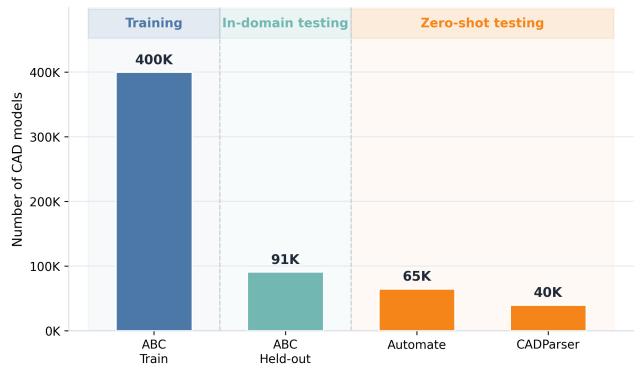
方法:CAD 垂直领域,但“结构 token + CLIP 对齐”的 contrastive multimodal pretraining 对 3D/结构视觉表征有迁移启发
中相关;详见方法、贡献和实验边界。
方法:ICML Spotlight 的视频推理数据与评测工作;不是 SSL 目标,但对视频 foundation model 评估有参考
高相关;详见方法、贡献和实验边界。
方法:用无监督正交映射连接 VFM 几何空间与 VLM 语义空间,是今天最直接服务通用视觉表征融合的论文
高相关;详见方法、贡献和实验边界。
方法:给 CLIP/SigLIP 等 VLM 表征提供可解释的差异发现和对齐工具,适合作为 foundation feature 诊断方法
高相关;详见方法、贡献和实验边界。
方法:BabyCL 用单遍时间流、视觉表征学习和图文对比损失模拟真实连续经验,比离线 shuffle 训练更接近通用学习设定
高相关;详见方法、贡献和实验边界。
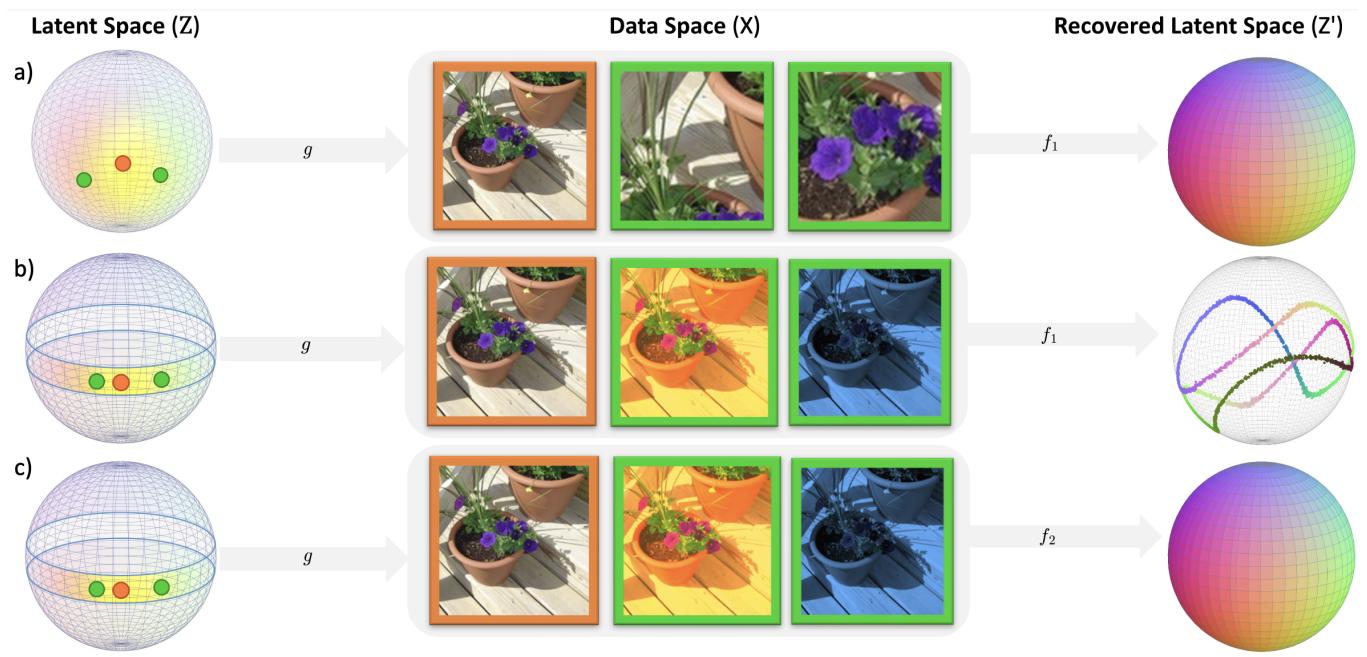
方法:从正样本采样 support 条件解释 contrastive SSL 何时能恢复 latent geometry,补足经验方法的理论边界
高相关;详见方法、贡献和实验边界。
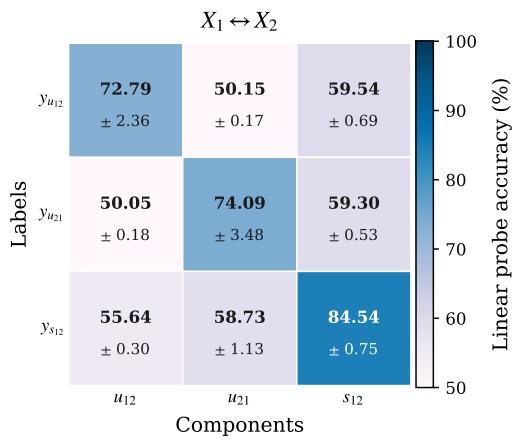
方法:面向多于两种模态的自监督解耦表示,直接处理共享因子与模态特异因子的可扩展分解
高相关;详见方法、贡献和实验边界。
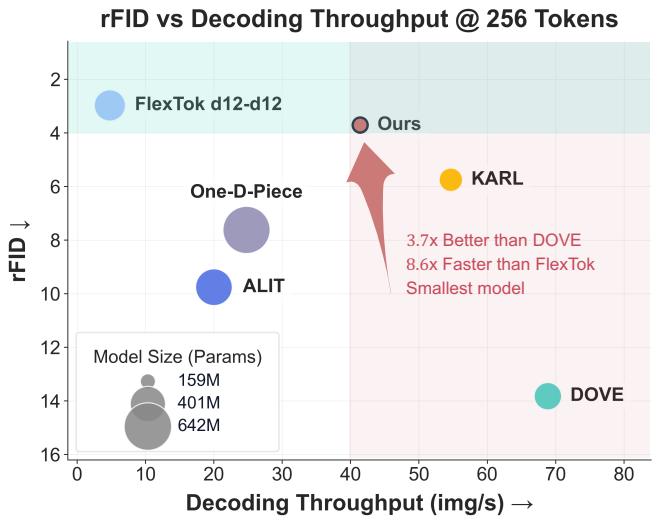
方法:把 latent channel 当视觉 token,训练时随机丢尾通道形成按语义重要性排序的可变长视觉 tokenizer
中高相关;详见方法、贡献和实验边界。
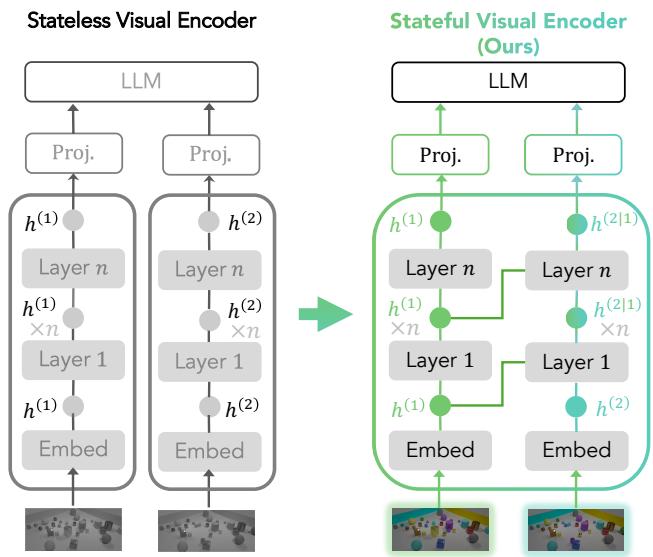
方法:让视觉编码器在多图/多轮中带状态,解决变化信息在进入 LLM 前被独立编码抹平的问题
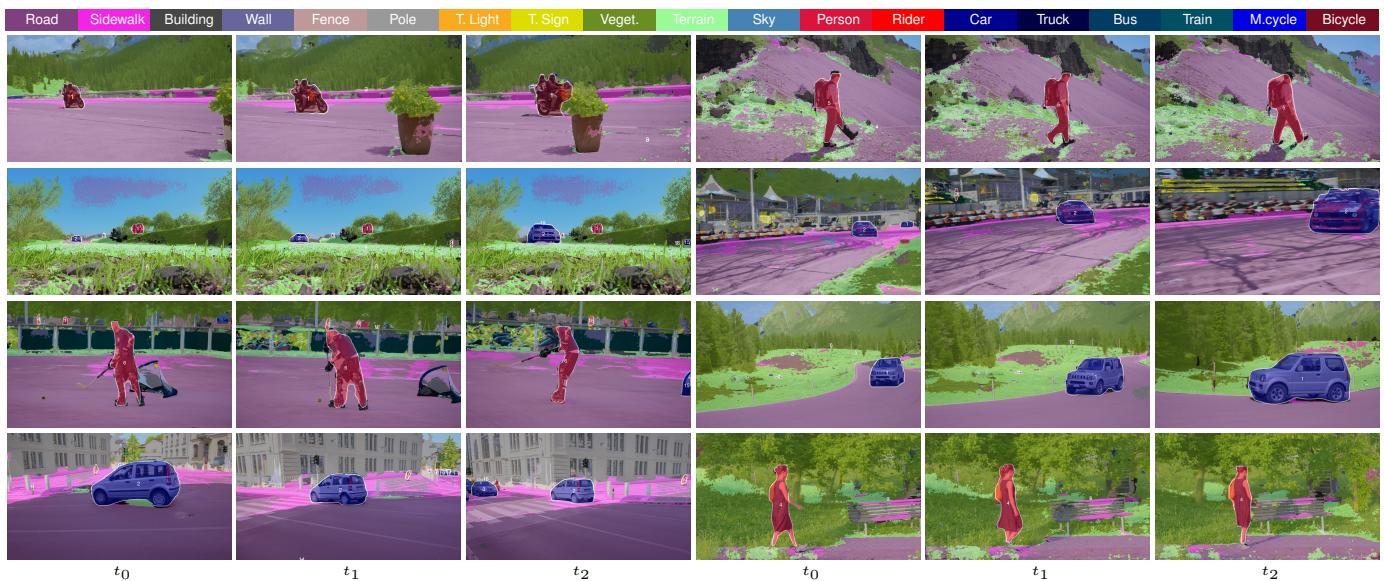
中高相关;详见方法、贡献和实验边界。
方法:VideoCUPS 用无监督深度、运动和视觉 cues 生成时序一致伪标签,是视频无监督场景理解的重要扩展
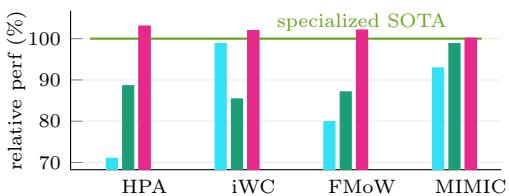
中高相关;详见方法、贡献和实验边界。
方法:FINO 用元数据指导自监督适配 VFM,虽然实验偏科学域,但“无标签元数据适配”方法可迁移
中高相关;详见方法、贡献和实验边界。
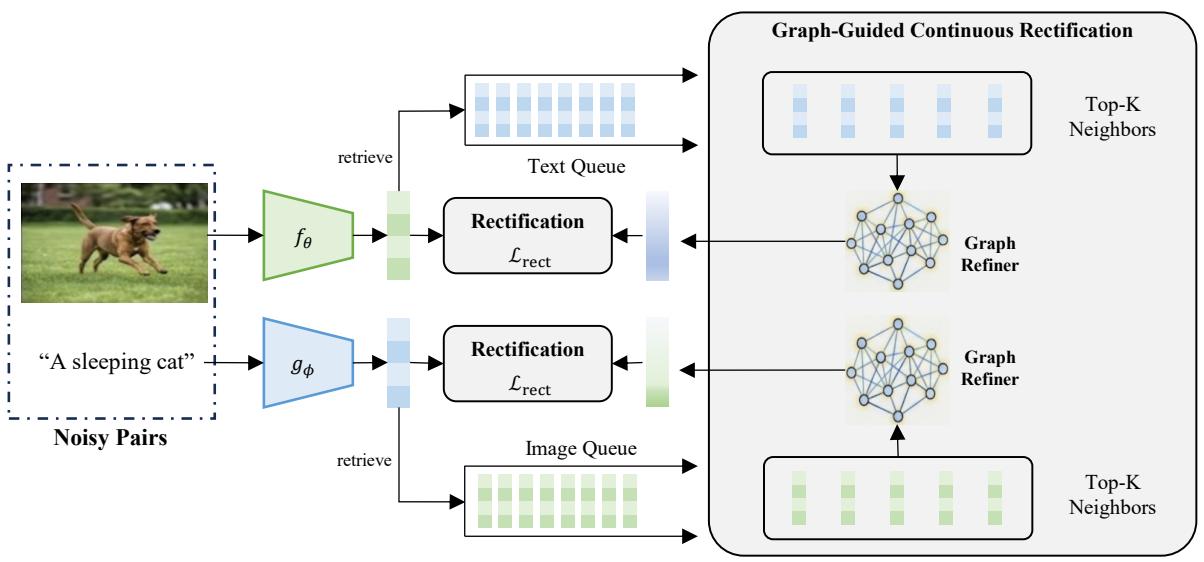
方法:面向网页图文噪声配对,用同模态邻域生成软监督目标,对大规模 image-text 预训练很实用
中相关;详见方法、贡献和实验边界。
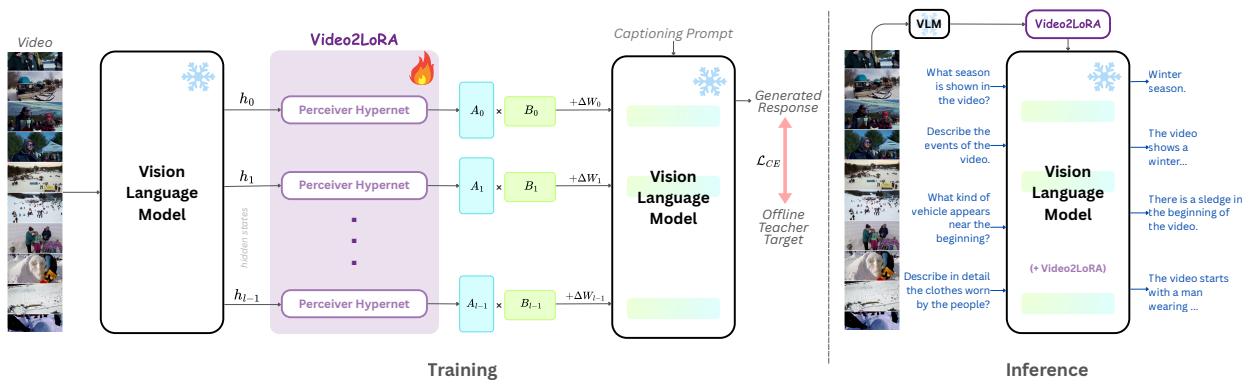
方法:把视频编码为 LoRA 参数,让 VLM 查询时不再携带视觉 token,适合关注长视频 token 压缩的人扫读
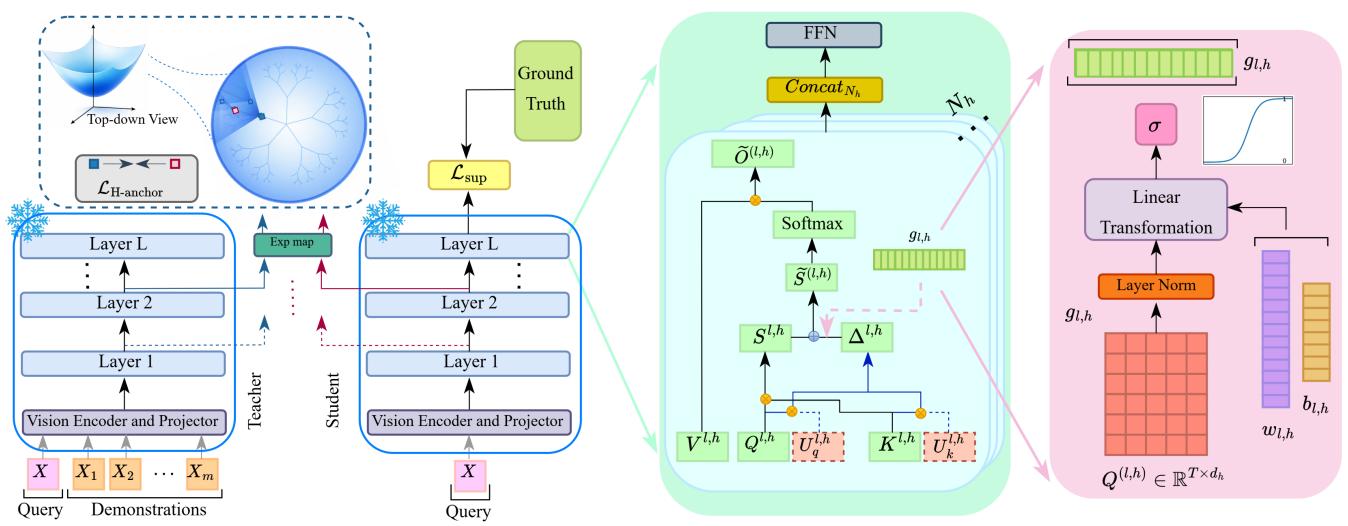
中相关;详见方法、贡献和实验边界。
方法:用 logit/attention 校准和 hyperbolic anchor distillation 复现多模态 demonstrations 的效果,偏 MLLM 推理效率
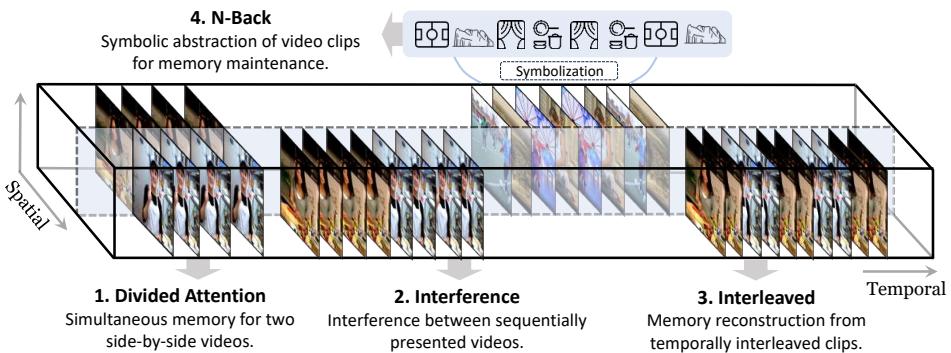
中相关;详见方法、贡献和实验边界。
方法:长视频多模态记忆 benchmark,揭示模型难以保持并行视频流的解耦记忆和时间来源归因
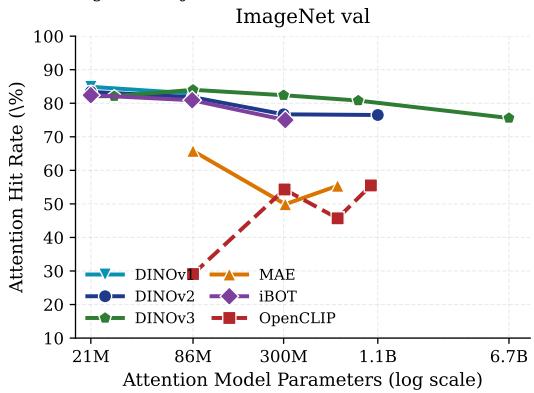
高相关;详见方法、贡献和实验边界。
方法:直接分析自监督 ViT 注意力定位的逆 scaling 现象,并用小模型定位 + 大模型嵌入做无训练增强
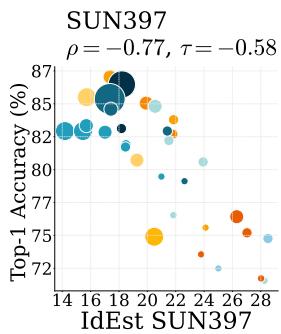
高相关;详见方法、贡献和实验边界。
方法:用 MST intrinsic dimension 作为 SSL 表征质量代理,目标是减少 linear probe 成本和超参敏感性
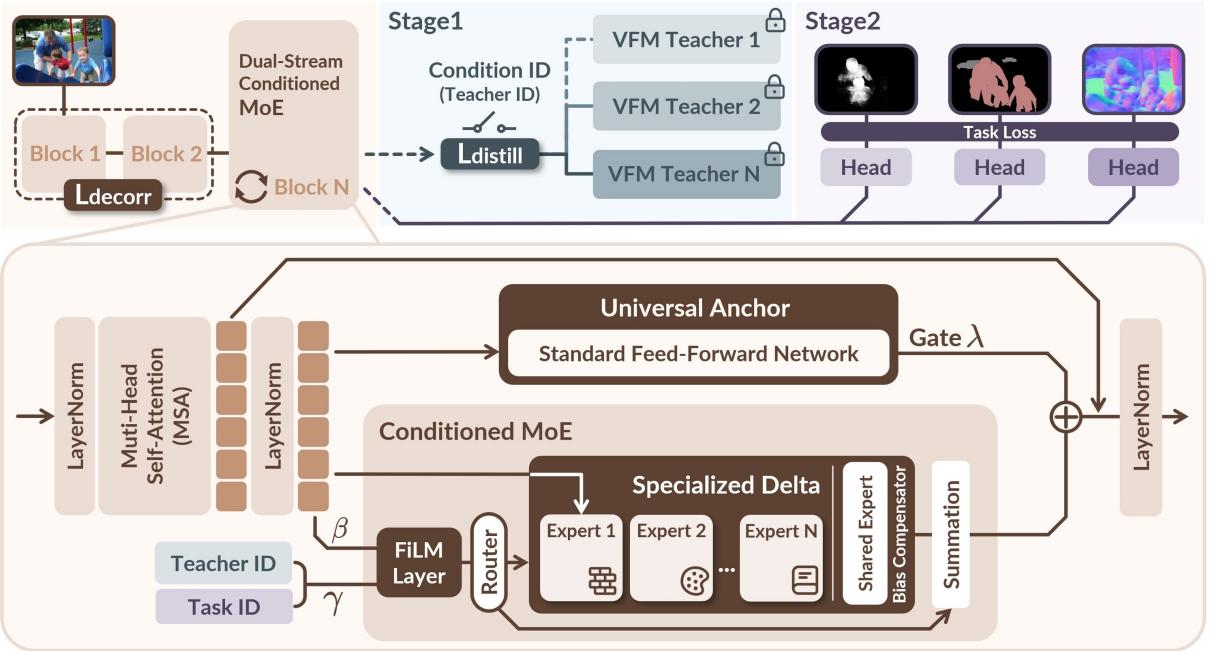
高相关;详见方法、贡献和实验边界。
方法:面向多个 VFM 的模块化 MoE 蒸馏/融合,处理 monolithic distillation 的负迁移
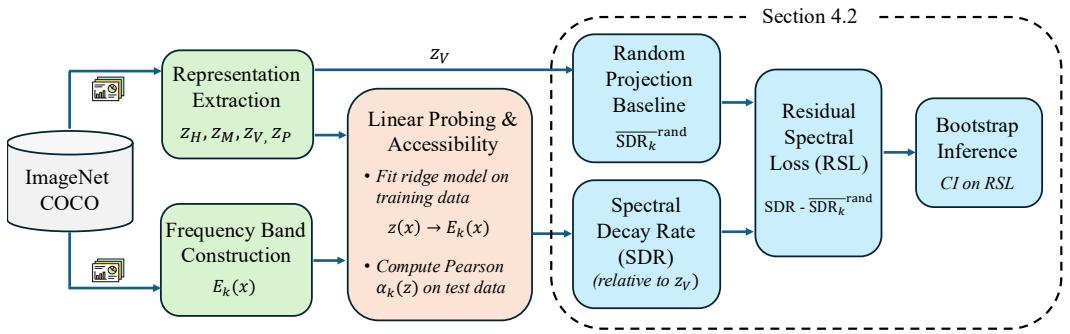
高相关;详见方法、贡献和实验边界。
方法:用频域 recoverability 诊断 CLIP/DINOv2 表征在投影、池化和层深中的信息损失
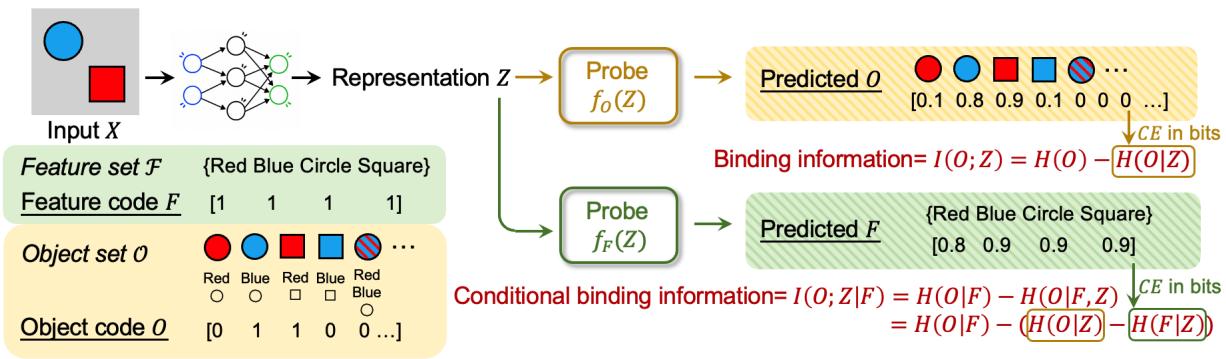
中高相关;详见方法、贡献和实验边界。
方法:用信息论 probing 测量 ViT 表征是否知道“哪些属性属于同一对象”,补充全局几何指标
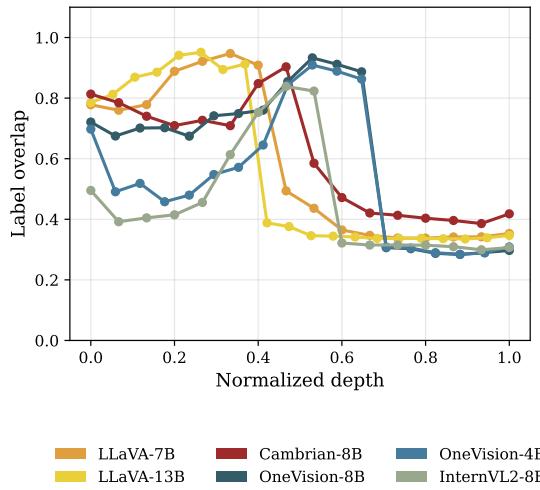
中高相关;详见方法、贡献和实验边界。
方法:说明视觉 instruction tuning 主要把视觉特征接入 LLM 中间语义层,对多模态表征对齐有诊断价值
中高相关;详见方法、贡献和实验边界。
方法:大规模 omnimodal world model 同时处理语言、图像、视频、音频和 action,是通用视频/世界模型预训练的重要系统信号
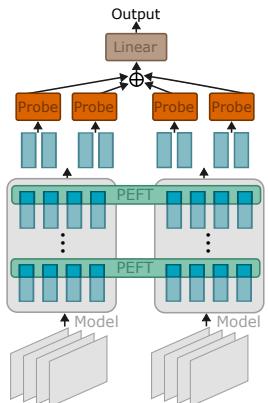
中相关;详见方法、贡献和实验边界。
方法:系统比较 image-pretrained 与 video representation 的 PEFT/probing,回答低资源视频适配中 temporal context 放在哪里
中相关;详见方法、贡献和实验边界。
方法:统一图像、视频、音视频注意力/显著性建模,虽偏任务模型,但可作为视觉 attention 表征基准
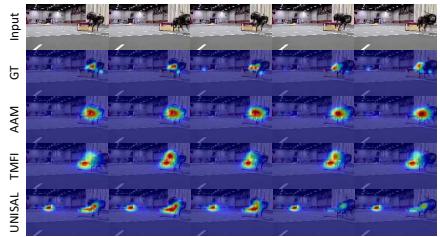
中相关;详见方法、贡献和实验边界。
方法:VSTAT 评测长视频状态追踪,揭示 MLLM 文字推理正确但视觉事件感知不足的问题
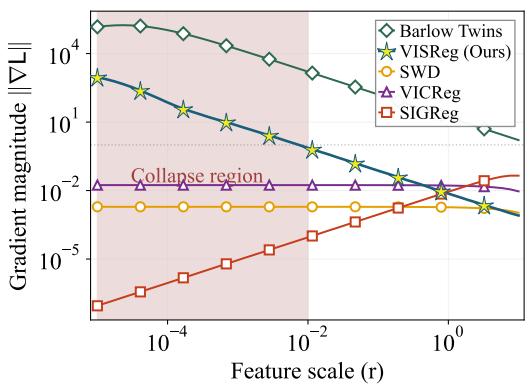
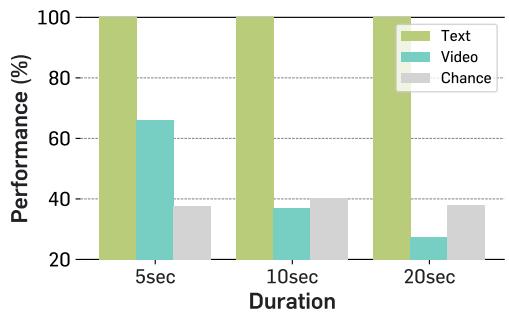
高相关;详见方法、贡献和实验边界。
方法:直接改进 JEPA/SSL 防 collapse 正则化,并报告 ImageNet-22K 下接近 DINOv2 OOD 表现
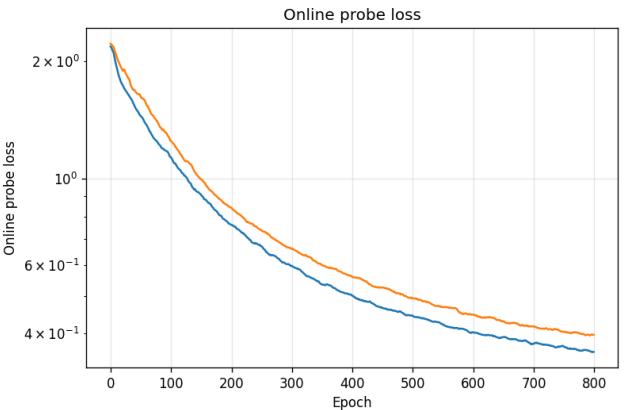
高相关;详见方法、贡献和实验边界。
方法:同样针对 JEPA collapse,但从低维流形/rectifiability 角度替代 isotropic Gaussian 先验
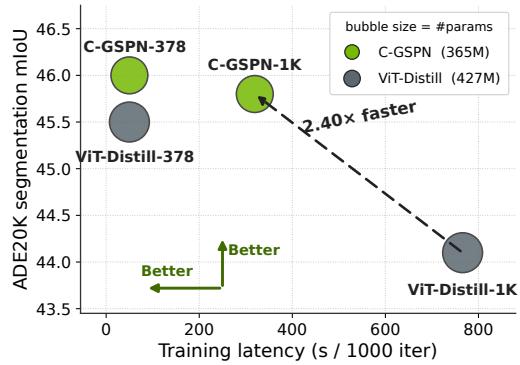
高相关;详见方法、贡献和实验边界。
方法:面向视觉基础模型的近线性 2D spatial propagation encoder,目标是降低大分辨率预训练成本
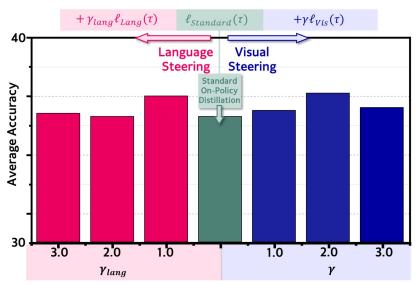
高相关;详见方法、贡献和实验边界。
方法:把 VLM 蒸馏梯度拆成 language prior 与 visual grounding,直接处理视觉证据被语言先验淹没的问题
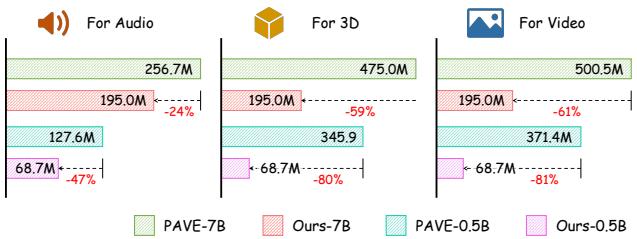
高相关;详见方法、贡献和实验边界。
方法:提出 Video LLM 内部存在可复用 token interface,用未配对单模态数据对齐新模态到视频 token 流形
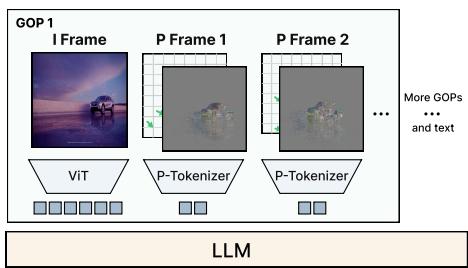
中高相关;详见方法、贡献和实验边界。
方法:把视频冗余建模为 reference frame + predictive P-token,直接减少重复视觉 token
中高相关;详见方法、贡献和实验边界。
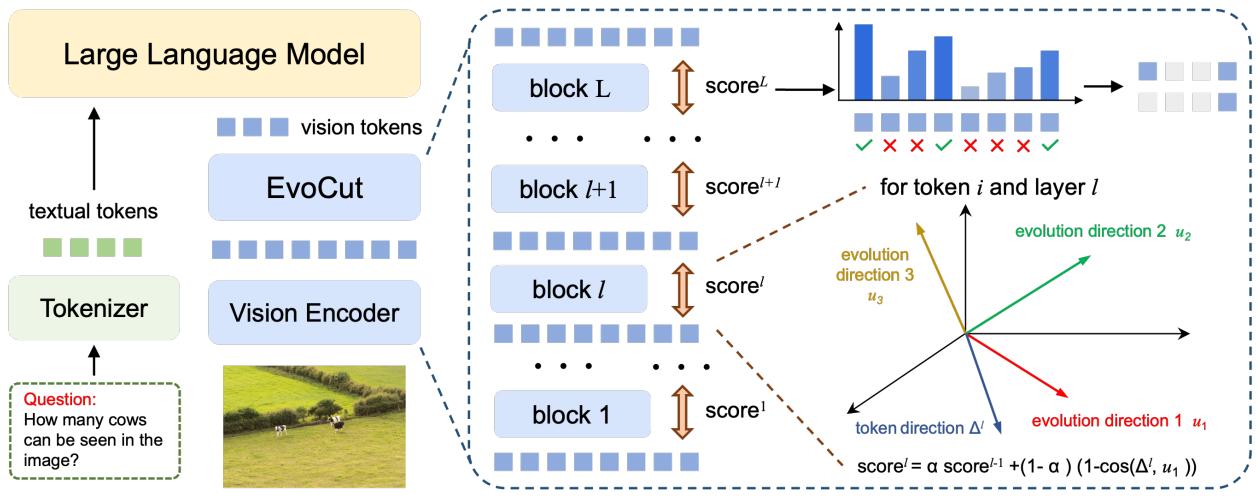
方法:从 vision encoder 多层 token 演化方向估计重要性,比单层 attention/相似度压缩更贴近表征形成过程
中高相关;详见方法、贡献和实验边界。
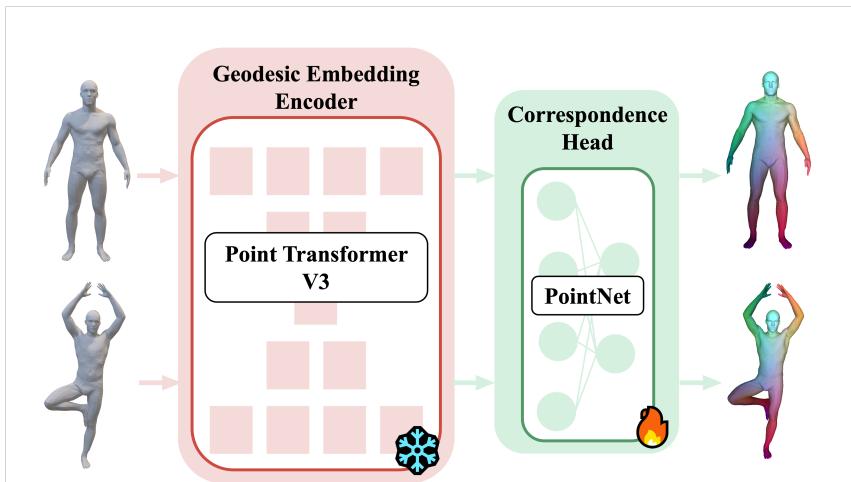
方法:用内在 geodesic metric 预训练 3D 表征,强调拓扑/流形结构而非外在坐标或语义标签
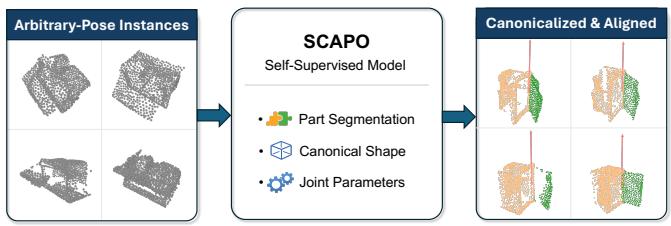
中相关;详见方法、贡献和实验边界。
方法:单帧 RGB-D 下用自监督分解 canonical geometry、part segmentation 与 articulation,方法信号可迁移到对象结构学习
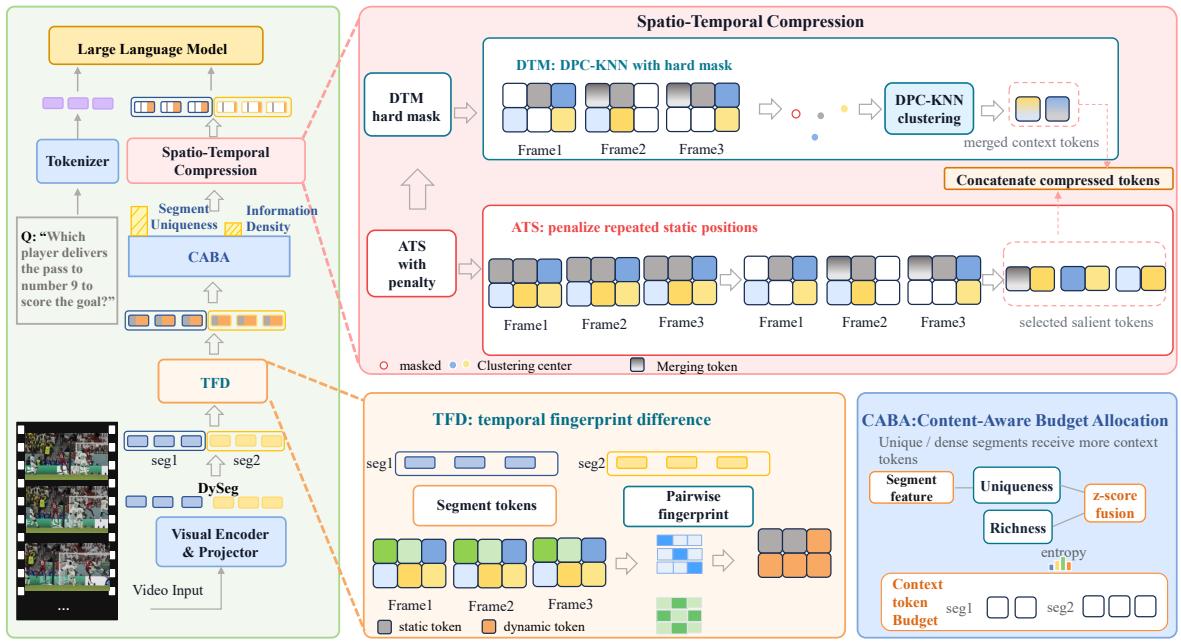
中相关;详见方法、贡献和实验边界。
方法:训练免费的视频 token compression,用 segment-level temporal fingerprint 估计冗余和内容预算
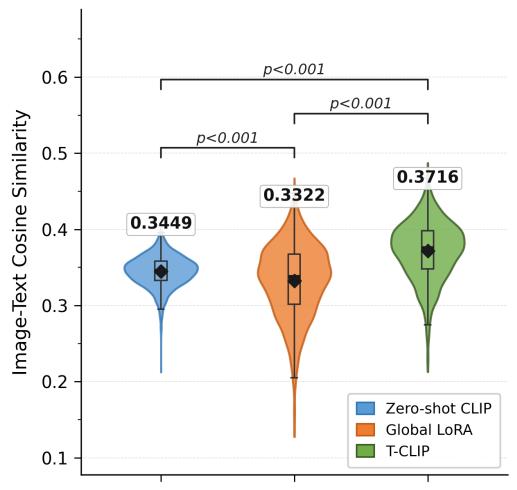
中低相关;详见方法、贡献和实验边界。
方法:热成像是垂直模态,但 dual-LoRA 拆分全局场景与对象热签名的 CLIP adaptation 有方法借鉴价值
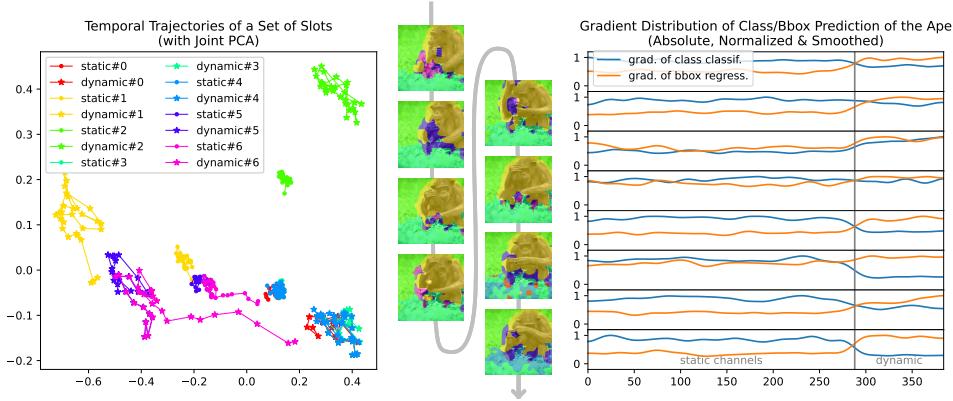
高相关;详见方法、贡献和实验边界。
方法:把跨帧一致性从显式 slot 对比损失改成模型结构和重建目标,最接近视频自监督表征
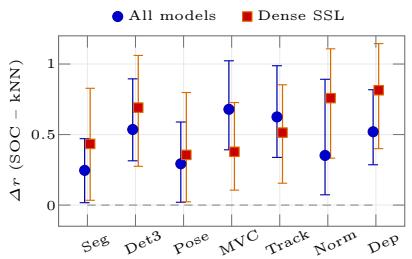
高相关;详见方法、贡献和实验边界。
方法:用细粒度语义 correspondence 直接评估 DINO/CLIP/SAM 类视觉基础模型是否学到可迁移对象结构
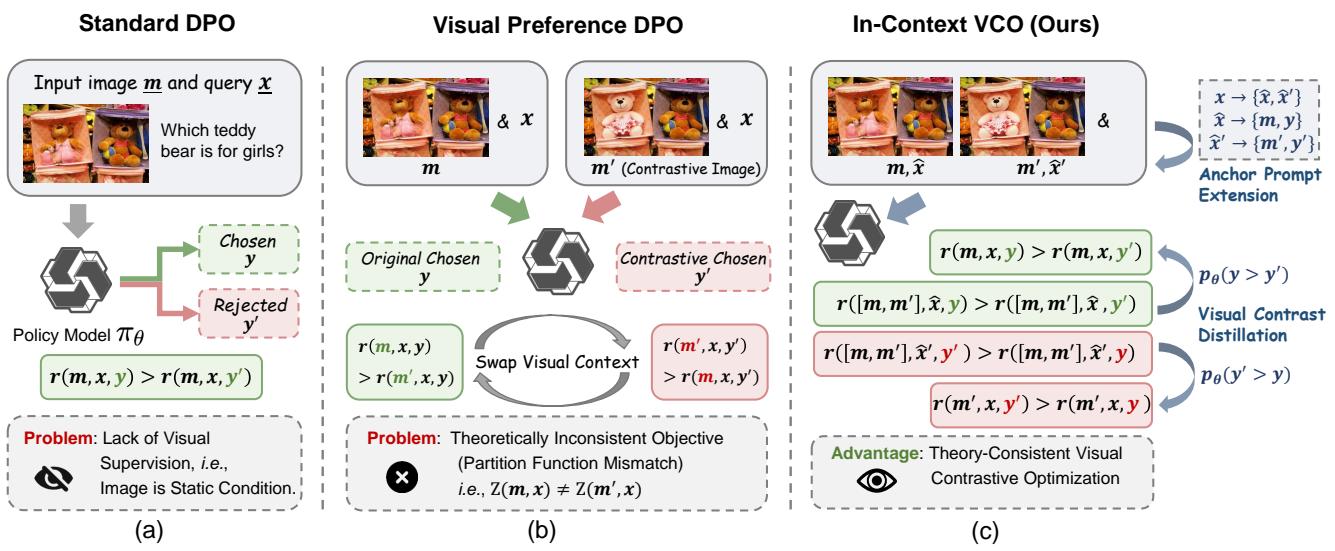
中高相关;详见方法、贡献和实验边界。
方法:把视觉负样本做成同上下文对比训练,关注 VLM 是否真的利用细粒度视觉证据
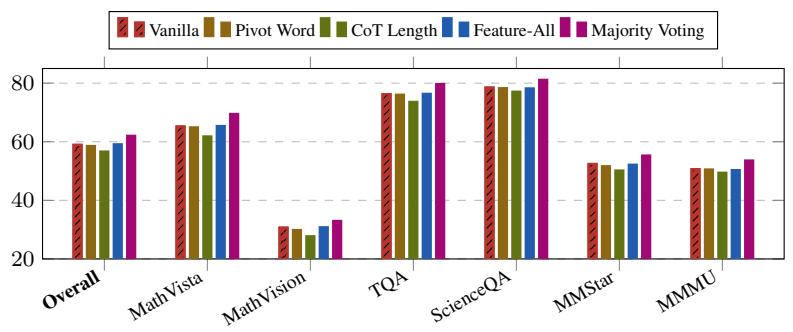
中相关;详见方法、贡献和实验边界。
方法:分析 VLM 推理时 compute 为什么常失效,结论指向视觉-语言表征/输出多样性不足
中相关;详见方法、贡献和实验边界。
方法:不是视觉专属,但 sparse autoencoder 稳定性直接影响 DINO/CLIP 等表征解释
中相关;详见方法、贡献和实验边界。
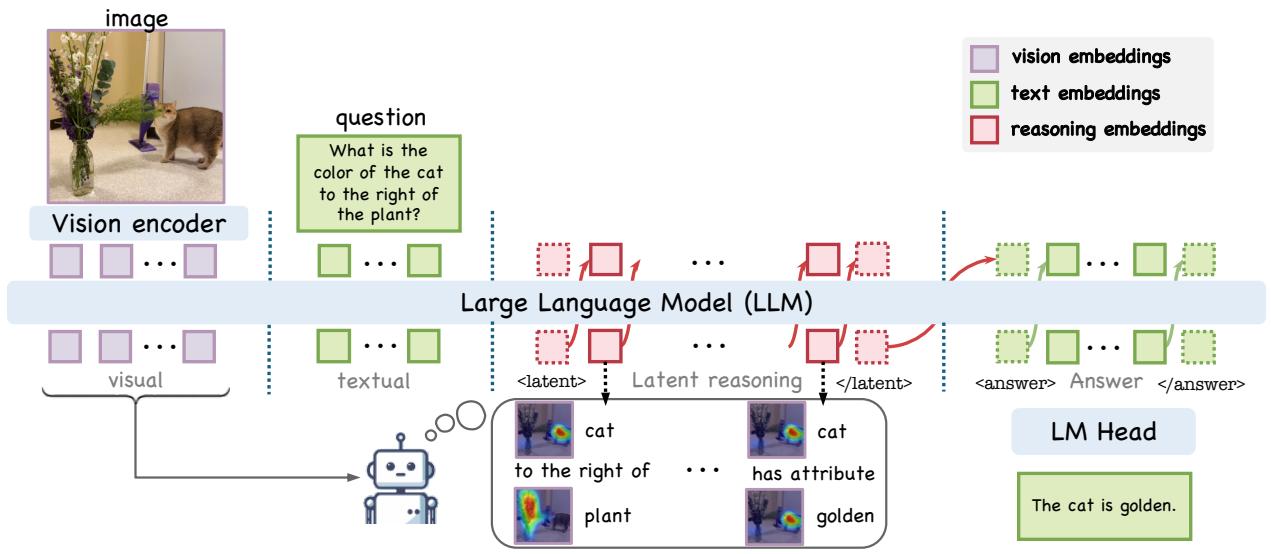
方法:把连续 latent reasoning 绑定到对象和关系证据,对视觉 token/中间表征设计有启发
中低相关;详见方法、贡献和实验边界。
方法:训练免费推理方法,但 register token 替代局部视觉 token 的设计可帮助理解视觉证据粒度
高相关;详见方法、贡献和实验边界。
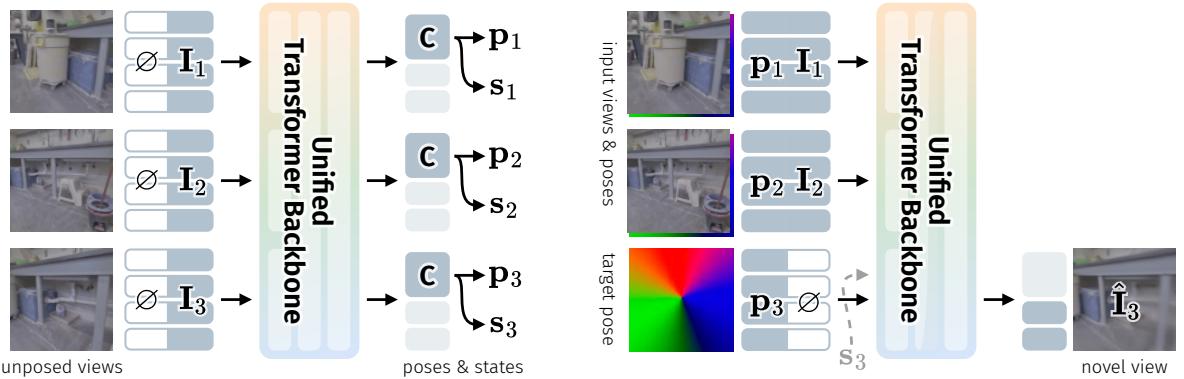
方法:把真实视频动态因素当成可吸收扰动,用单一 transformer 扩展自监督 NVS,并报告清晰 scaling 行为
高相关;详见方法、贡献和实验边界。
方法:解释 CLIP 类图文 embedding 为什么像 bag-of-concepts,以及组合泛化需要怎样的低复杂度 binding
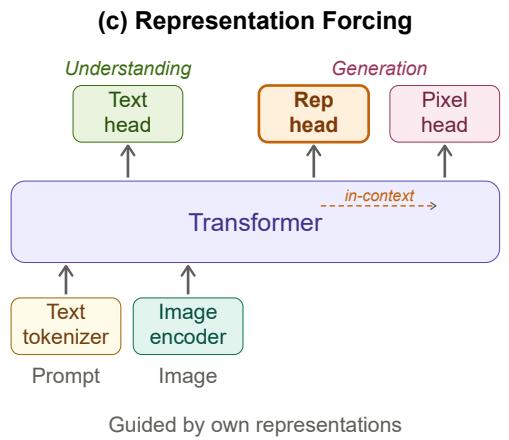
高相关;详见方法、贡献和实验边界。
方法:把视觉表示从感知输出变成生成前的中间 token,让统一多模态模型少依赖外部 VAE latent
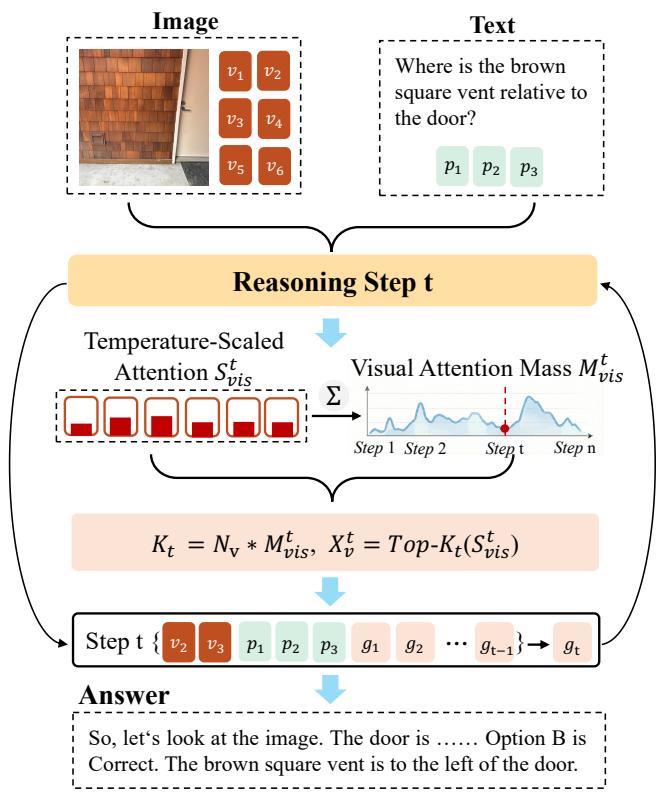
中高相关;详见方法、贡献和实验边界。
方法:关注 LMM 推理期间视觉 token 的动态有效性,和高分辨率/长上下文视觉表征压缩直接相关
中高相关;详见方法、贡献和实验边界。
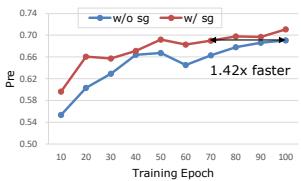
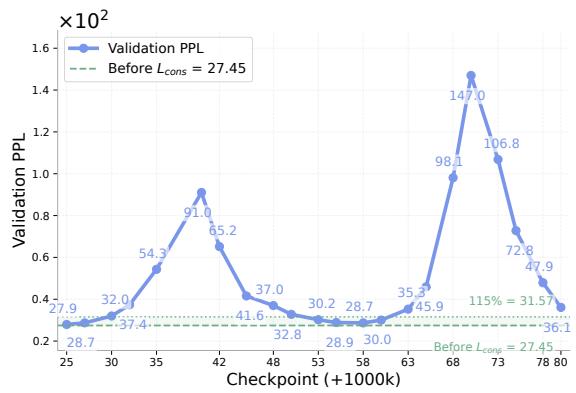
方法:把 masked generative modeling 的跨步隐藏状态一致性和自适应深度结合,含 ImageNette 图像实验
中高相关;详见方法、贡献和实验边界。
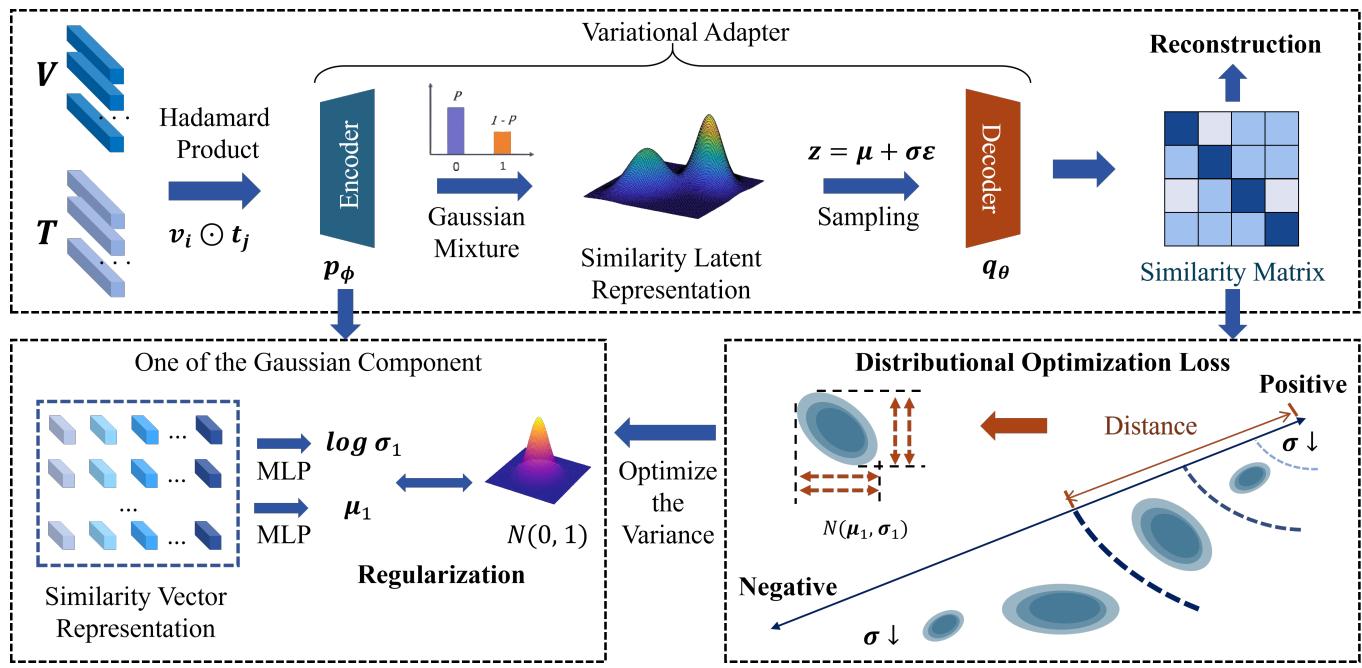
方法:把图文相似度从二元匹配边界改成变分潜空间,缓解 false negatives 和跨域泛化问题
中高相关;详见方法、贡献和实验边界。
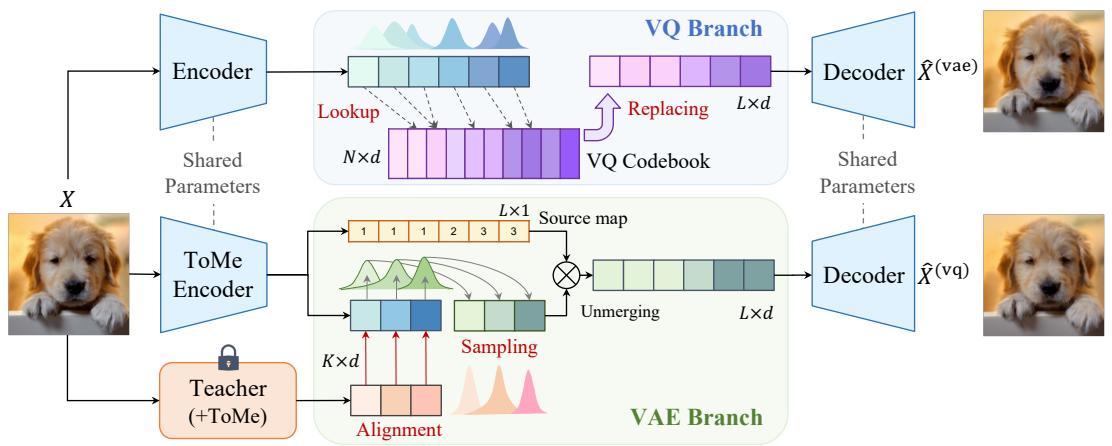
方法:统一连续 VAE 与离散 VQ 视觉 tokenizer,用 token merging 做语义桥
中相关;详见方法、贡献和实验边界。
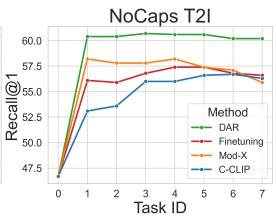
方法:把 continual learning 从分类改到图文检索,并提出 adapter routing
中相关;详见方法、贡献和实验边界。
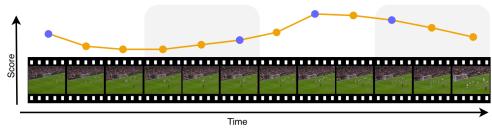
方法:用 teacher 视觉-语言模型蒸馏帧重要性,让轻量视觉模型在低帧预算下选关键帧
中相关;详见方法、贡献和实验边界。
方法:无需训练地重组 pretrained DINOv2/ViT 表征来分解 polysemanticity
中高相关;详见方法、贡献和实验边界。
方法:共享 LoRA adapter 减轻 teacher/student 特征错位,适合关注蒸馏式视觉表征压缩
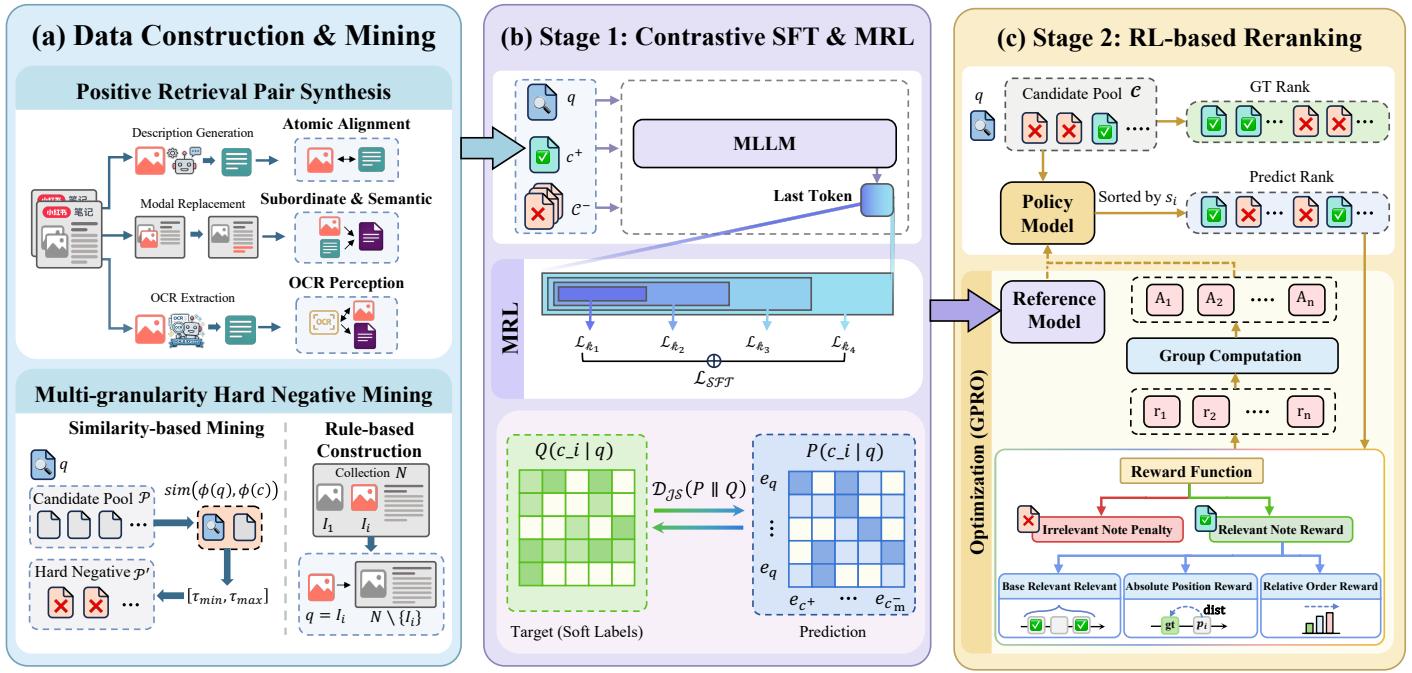
中高相关;详见方法、贡献和实验边界。
方法:contrastive SFT + RL ranking + MRL 的多模态 embedding 方案,工业场景强但表征训练信号可迁移
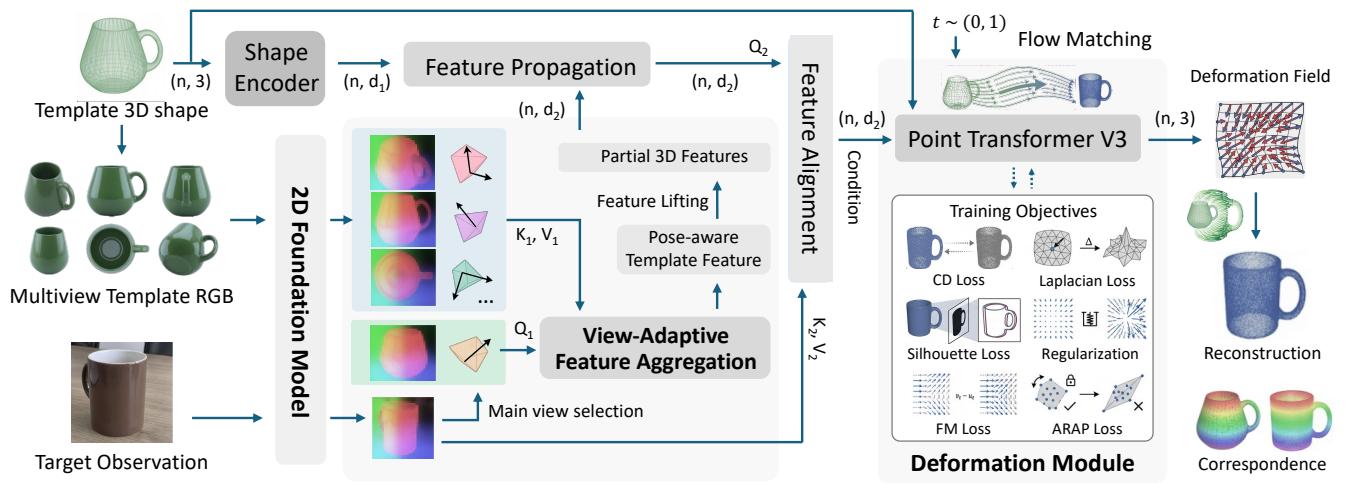
中相关;详见方法、贡献和实验边界。
方法:把 foundation features 与模板拓扑、视角聚合结合,关注视觉基础特征如何承载几何泛化
中相关;详见方法、贡献和实验边界。
方法:把视频 foundation model 改造成可交互 world model 的完整训练链,含 AR 训练和 few-step distillation
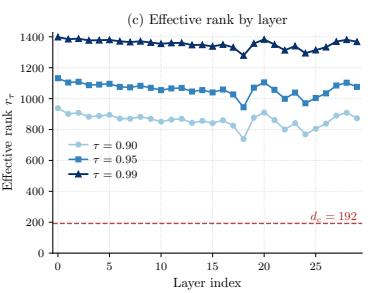
中相关;详见方法、贡献和实验边界。
方法:研究视频基础模型长时序 attention/KV 压缩,对视频预训练效率有间接价值
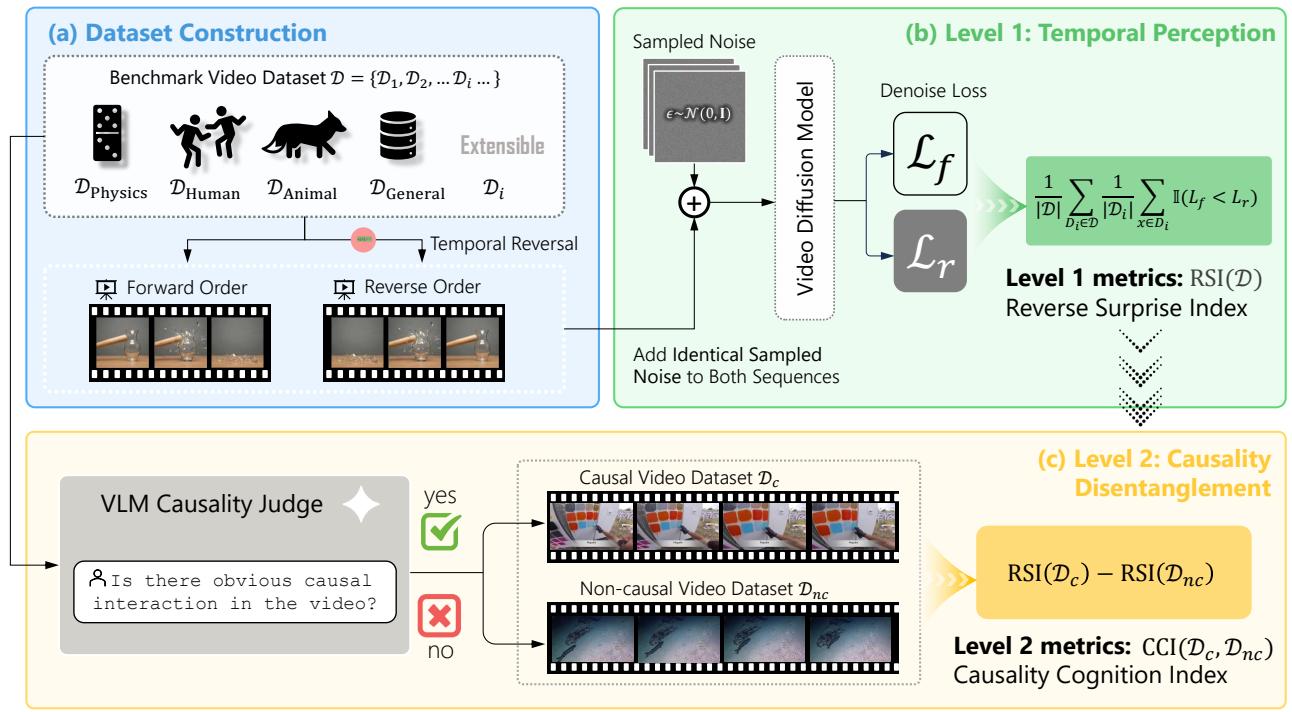
中相关;详见方法、贡献和实验边界。
方法:用真实视频反转构造 causal counterfactual benchmark,适合评估视频 world model 是否学到动态因果
中低相关;详见方法、贡献和实验边界。
方法:从 residual margin 与 span geometry 讨论表征稳定性,含 masked within-class self-expressiveness 目标
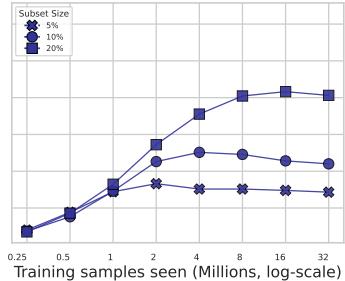
中低相关;详见方法、贡献和实验边界。
方法:用 ImageNet-scale 子集验证数据多样性/谱函数价值,作为视觉预训练数据筛选背景扫读
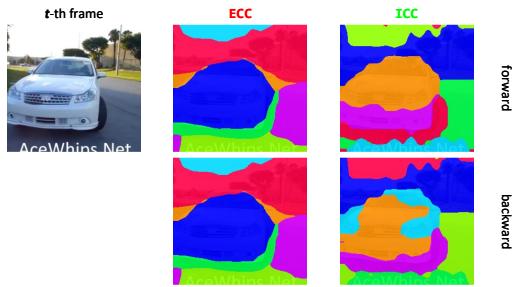
高相关;详见方法、贡献和实验边界。
方法:自监督视频 object-centric learning,提出隐式 cycle consistency 避免 slot collapse,直接命中通用视频表征
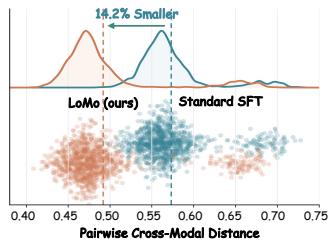
高相关;详见方法、贡献和实验边界。
方法:用局部模态替换暴露 VLM 对文本/图像载体的表征不等价,适合指导视觉-语言自监督数据与目标设计
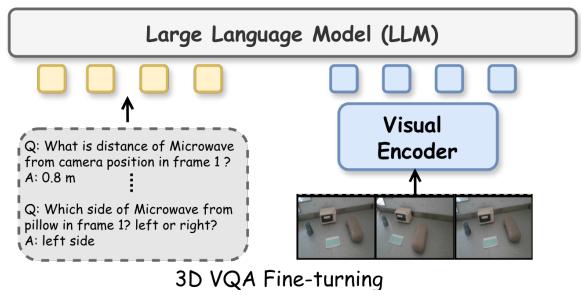
高相关;详见方法、贡献和实验边界。
方法:GASP 用 contrastive correspondence 与 depth consistency 学几何先验,比单纯 3D VQA 微调更接近空间表征预训练
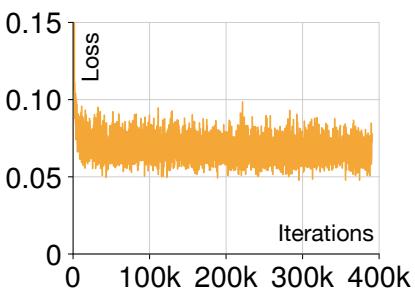
高相关;详见方法、贡献和实验边界。
方法:1 亿训练图像、VLM caption、许可友好与去重安全过滤,适合作为视觉生成/基础模型预训练数据源观察
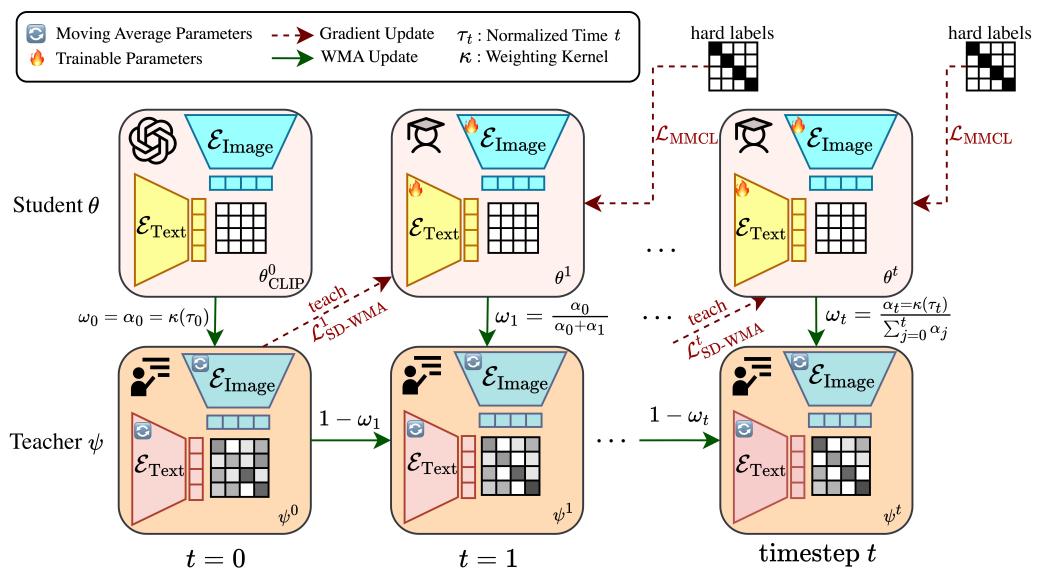
中高相关;详见方法、贡献和实验边界。
方法:从多模态 contrastive finetuning 理论解释 self-distillation,并提出 WMA teacher 防止 EMA collapse
中高相关;详见方法、贡献和实验边界。
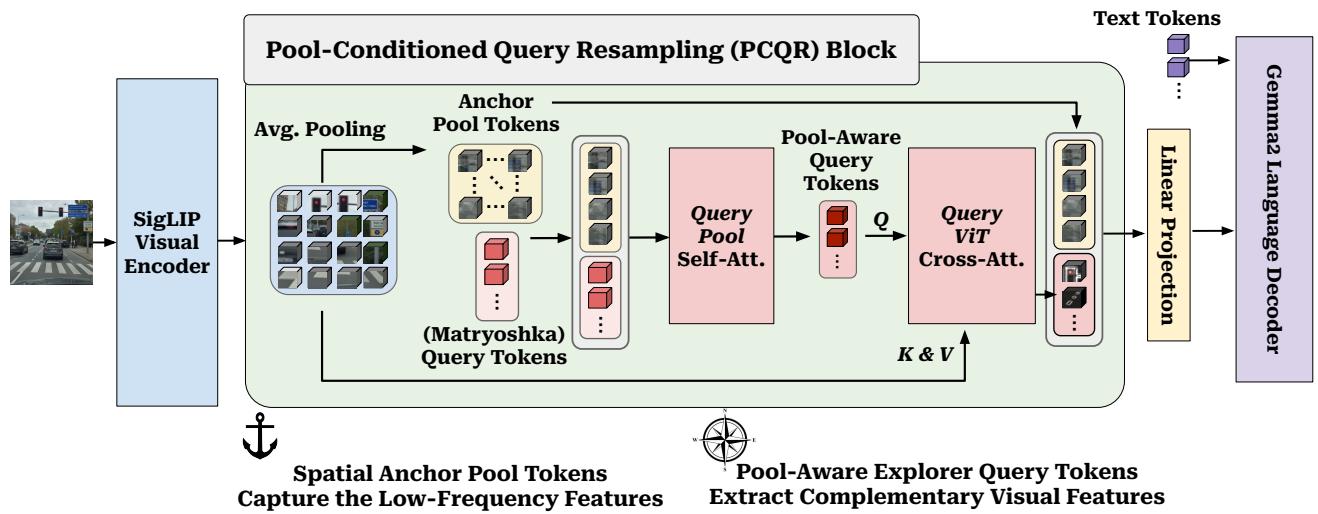
方法:把低频 layout anchor 与 elastic query 分工,关注 visual-token representation 在不同预算下如何保持空间与细节
中高相关;详见方法、贡献和实验边界。
方法:用 3D foundation priors 补 DINO/Stable Diffusion 2D 特征的几何盲点,适合关注 foundation feature 后训练
中高相关;详见方法、贡献和实验边界。
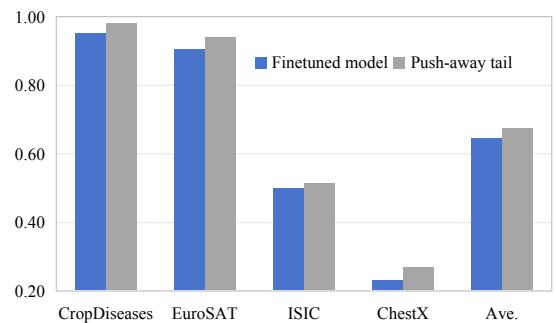
方法:重新解释 CLIP patch-token 对齐:低语义 tail tokens 不应强行贴近文本,提示对比表征微调要更细粒度
中相关;详见方法、贡献和实验边界。
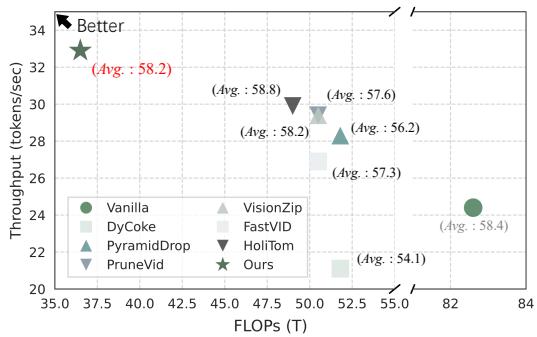
方法:训练-free 地在视觉编码器内部早期压缩 video tokens,补足只在 LLM 前压缩的效率盲点
中相关;详见方法、贡献和实验边界。
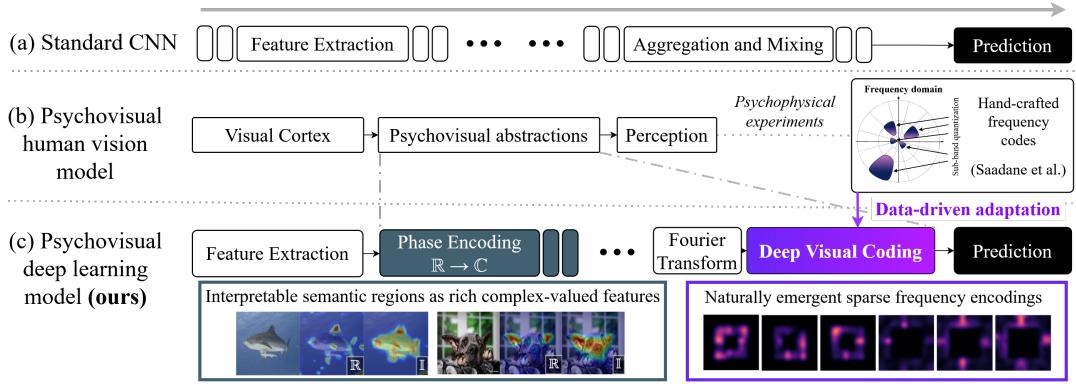
方法:学习频域 psychovisual-style abstraction,提供可解释中间图像表征路线,和常规 CNN/ViT 堆叠形成互补
中相关;详见方法、贡献和实验边界。
方法:系统比较 3DGS 场景表示上的 latent representation、linear probing 与 clustering,连接 3D 表征与视图合成资产
中相关;详见方法、贡献和实验边界。
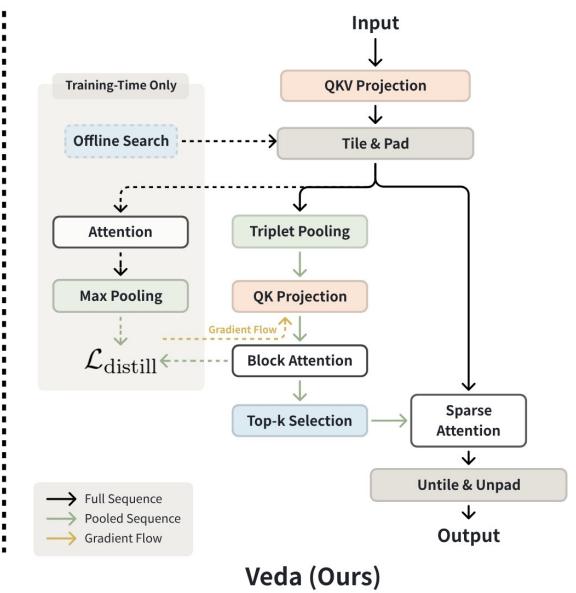
方法:把 full attention 蒸馏成 tile-wise sparse attention,主要服务视频生成扩展,但可借鉴到视频预训练计算结构
中相关;详见方法、贡献和实验边界。
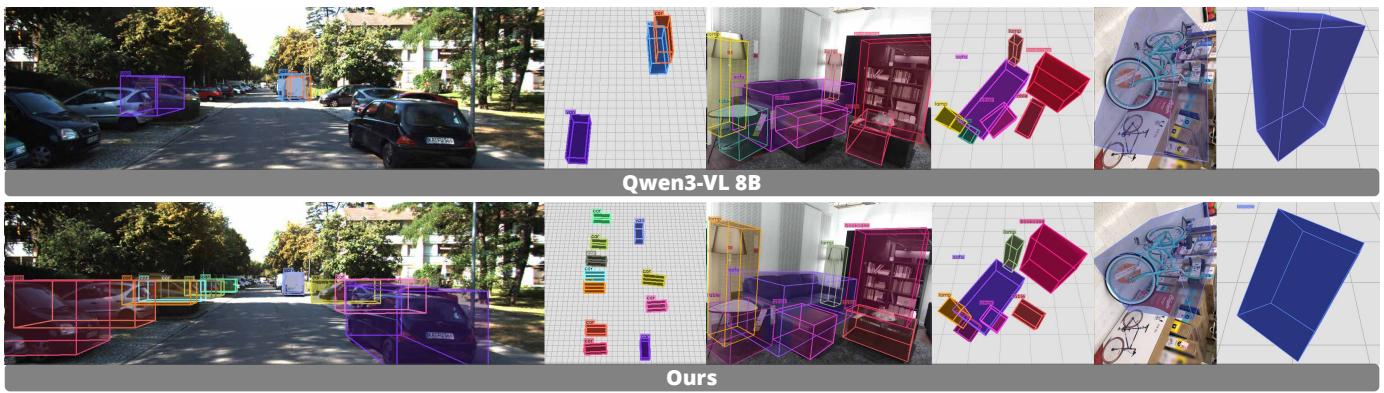
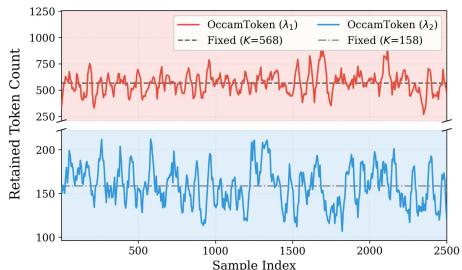
方法:GR3D 将显式/隐式 2D grounding 与 monocular 3D grounding 统一,偏 VLM 空间推理但对 grounding 表征有参考
中低相关;详见方法、贡献和实验边界。
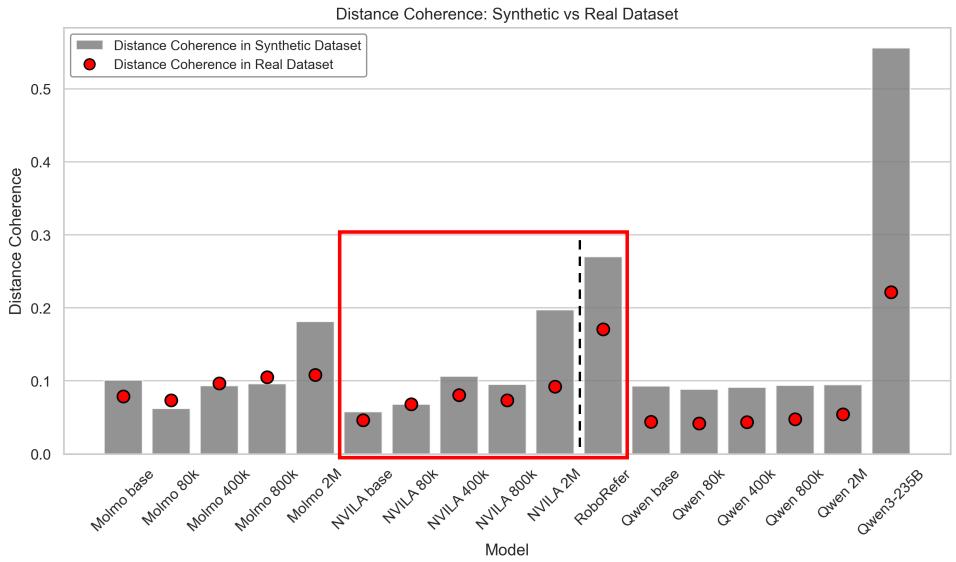
方法:用 register-anchored relative evidence testing 做训练-free token pruning,适合和 PARCEL/EarlyTom 对照扫读
中低相关;详见方法、贡献和实验边界。
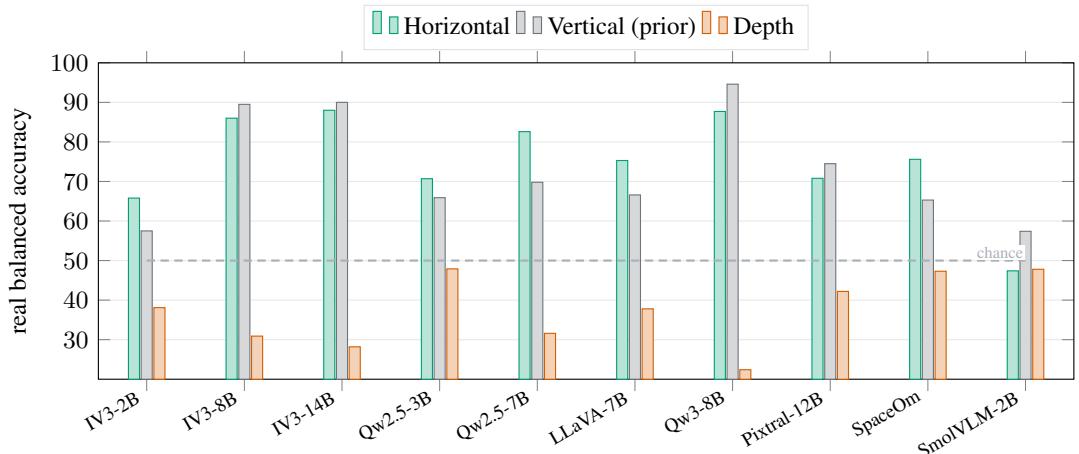
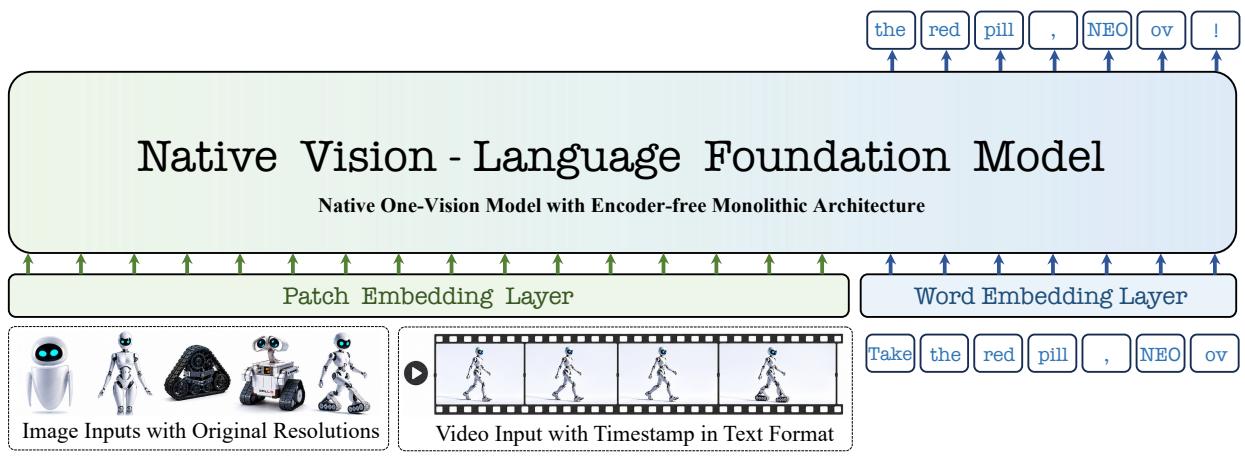
方法:用最小 contrastive pairs 诊断 VLM embedding 的垂直-距离纠缠,是空间表征偏置分析
高相关;详见方法、贡献和实验边界。
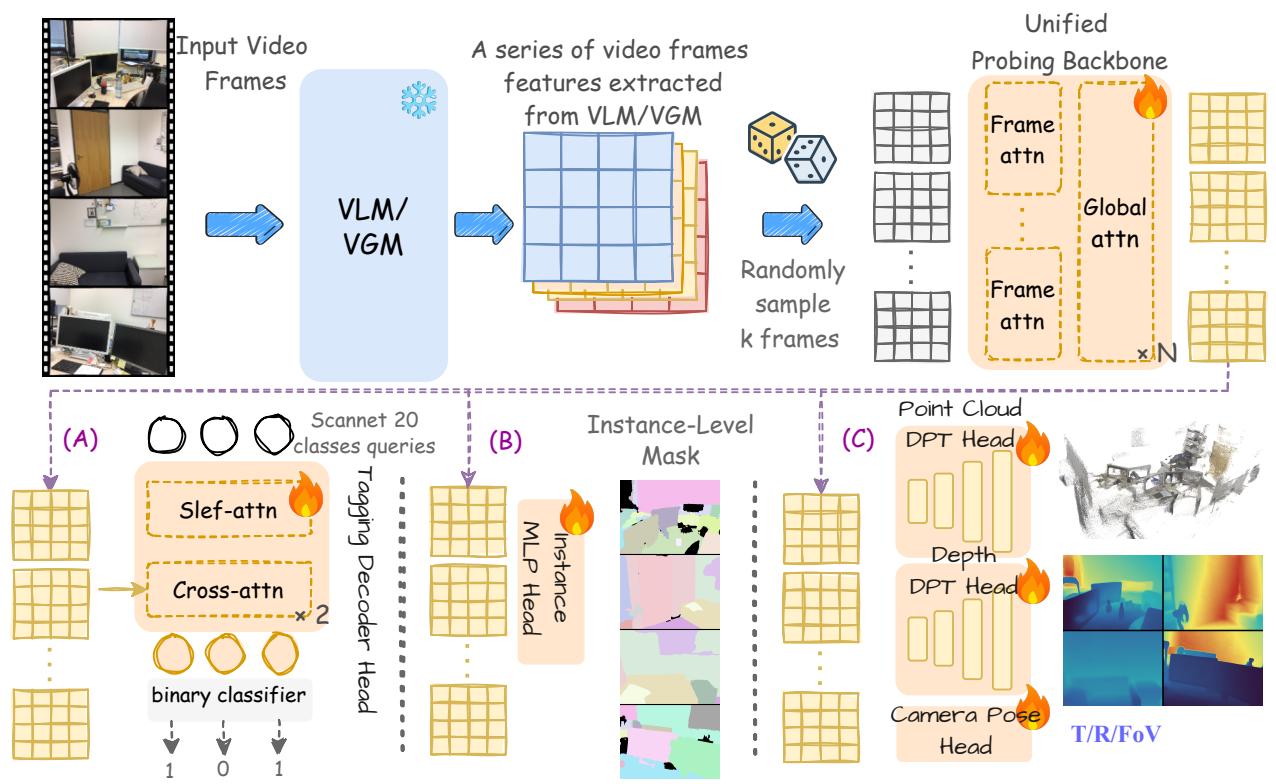
方法:原生 pixels-to-words one-vision 模型,直接挑战“预训练视觉 encoder + LLM adapter”的主流 VLM 拼接范式
高相关;详见方法、贡献和实验边界。
方法:用 frozen-feature probing 比较 VLM 与 VGM 表征,直接回答语义与几何信息分别从哪类预训练来
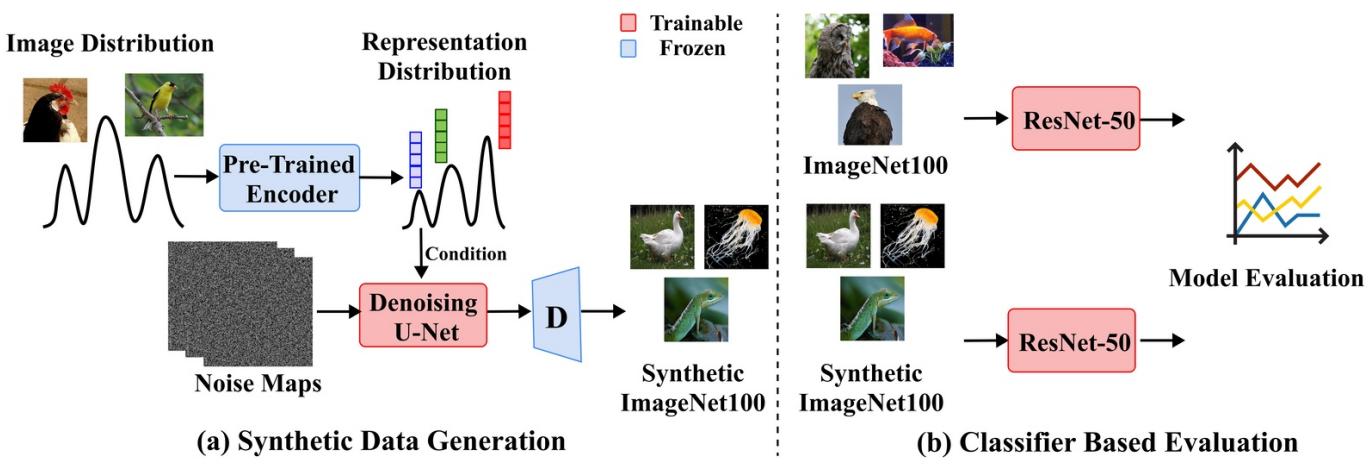
高相关;详见方法、贡献和实验边界。
方法:用 DINOv2/DINOv3/CLIP 表征条件化扩散模型合成训练数据,把通用视觉表征变成数据生成控制变量
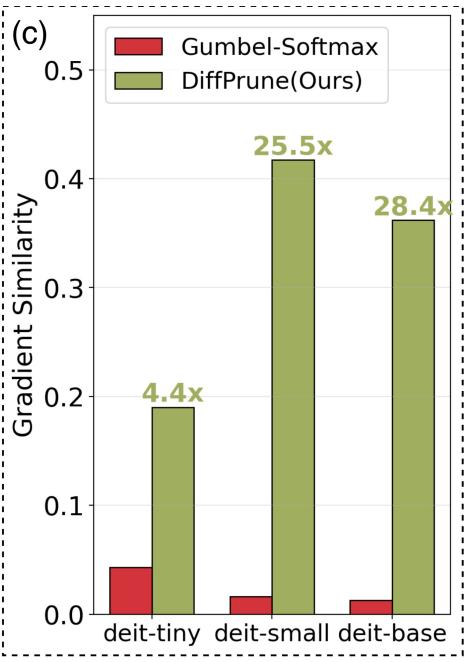
中高相关;详见方法、贡献和实验边界。
方法:DiffPrune 直接在 visual token representation 上学习可微信息节流,服务 VLM 计算预算
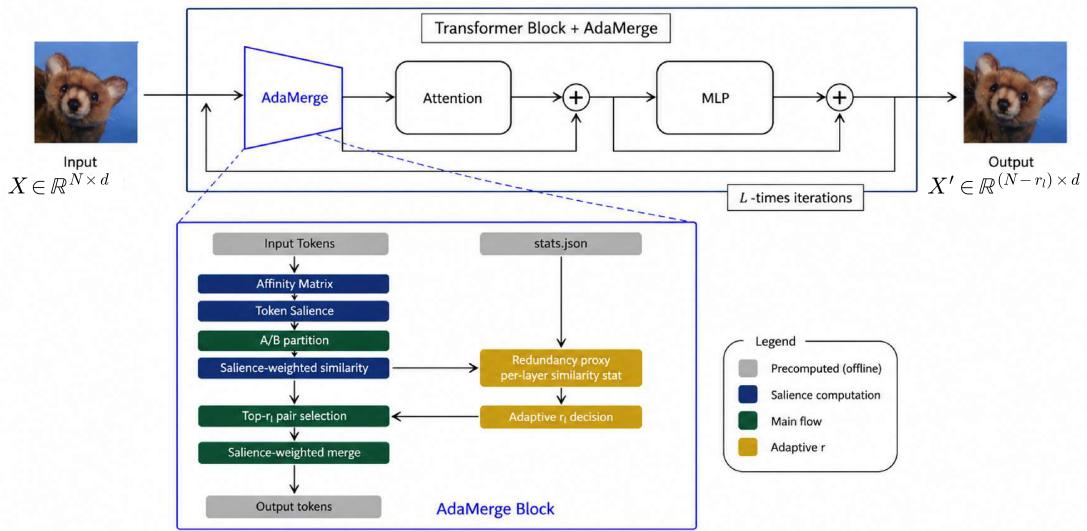
中高相关;详见方法、贡献和实验边界。
方法:训练-free ViT token merging,把 token 重要性和层级冗余纳入合并决策
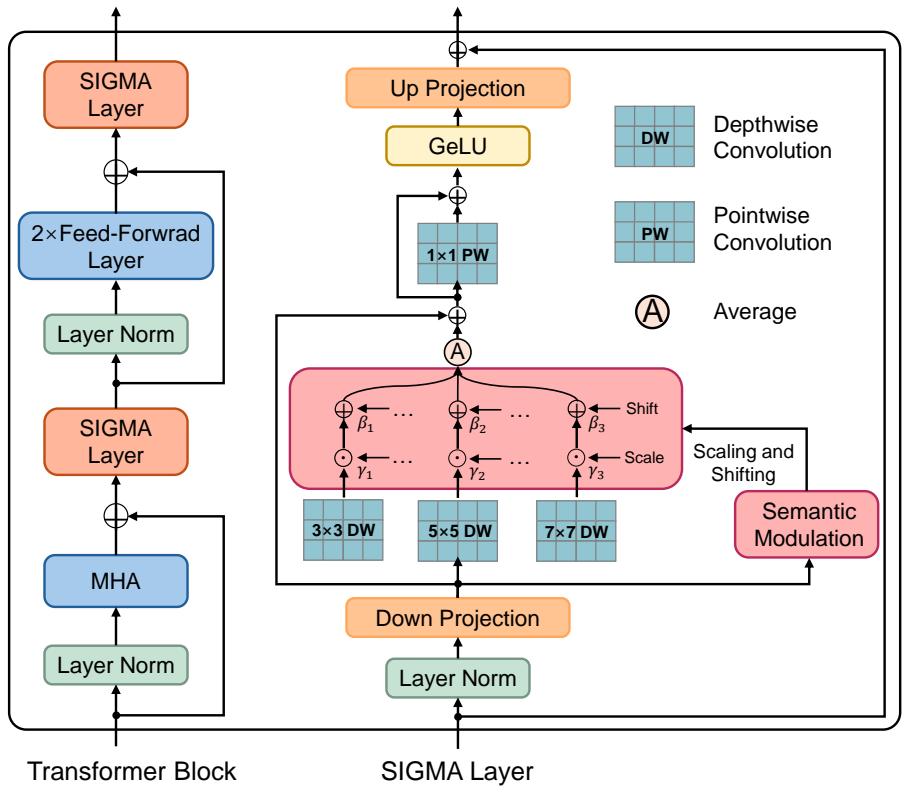
中高相关;详见方法、贡献和实验边界。
方法:面向 dense prediction 的 VFM 参数高效适配,关注结构尺度差异和分布对齐
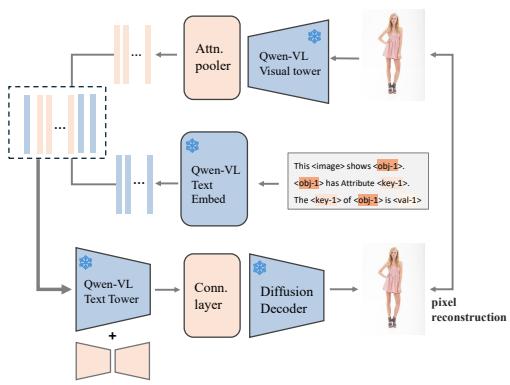
中高相关;详见方法、贡献和实验边界。
方法:ICML 2026 官方索引确认;自监督视觉 dictionary 用于细粒度 composed image retrieval
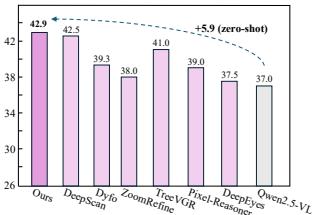
中相关;详见方法、贡献和实验边界。
方法:object-centric evidence routing,把局部 grounding 证据压入可复用 visual working space
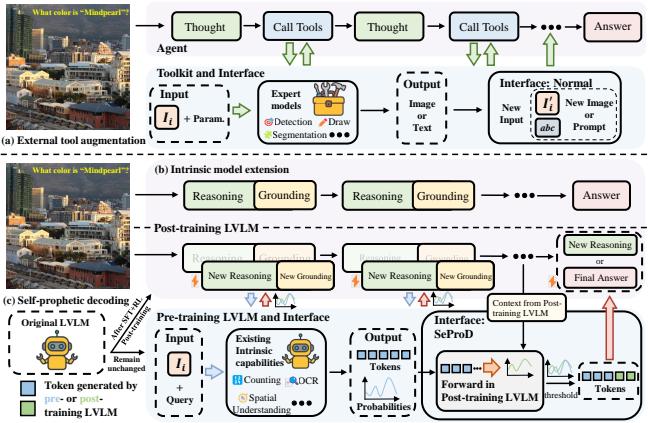
中相关;详见方法、贡献和实验边界。
方法:训练-free visual search decoding,用预训练 LVLM 单步能力修复后训练后的多步干扰
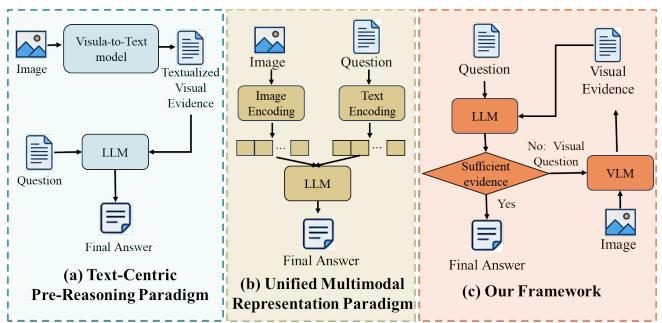
中相关;详见方法、贡献和实验边界。
方法:让语言模型决定何时调用视觉感知模块,适合观察“视觉证据何时进入推理链”
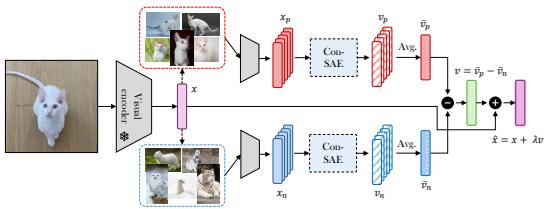
中相关;详见方法、贡献和实验边界。
方法:在 CLIP image encoder 激活上训练 SAE 并做 label-free steering,连接可解释性与可操作视觉表征
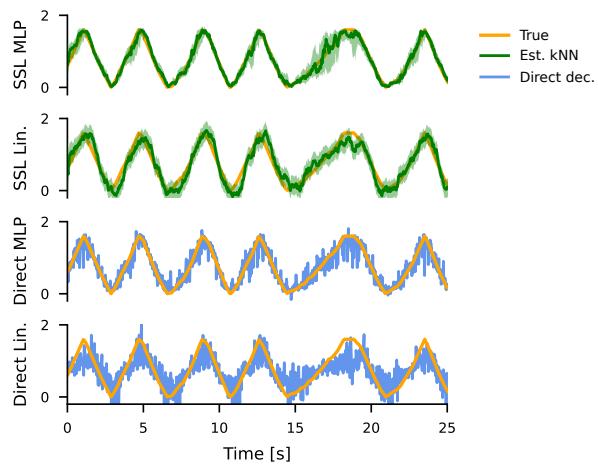
中相关;详见方法、贡献和实验边界。
方法:将 SSL 统一为 alignment + latent entropy 的分布匹配视角,理论价值高但视觉实验需看正文
中相关;详见方法、贡献和实验边界。
方法:冻结视频生成模型用 latent perturbation residual 自评分,体现生成模型内部表征的物理一致性信号
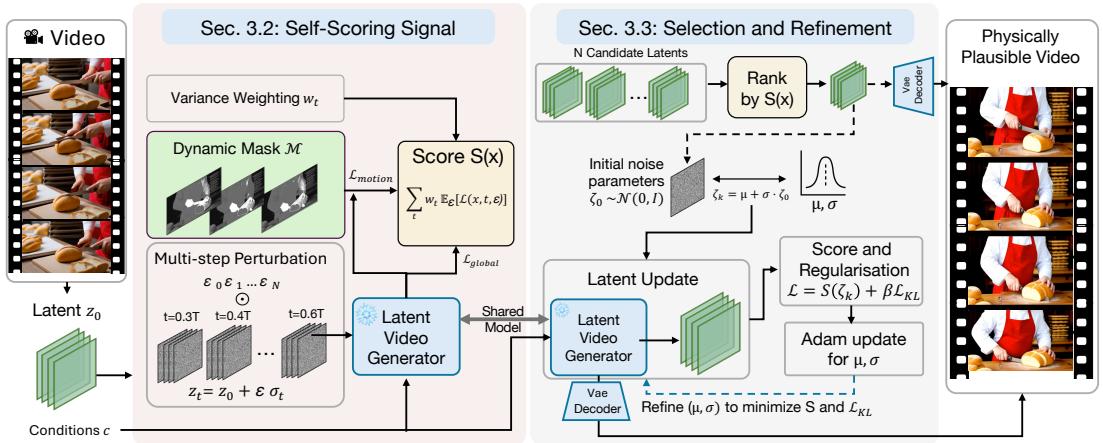
中相关;详见方法、贡献和实验边界。
方法:复现实验检查 hypersphere triplet area 几何对齐是否稳健,适合和 VLM embedding 几何一起扫
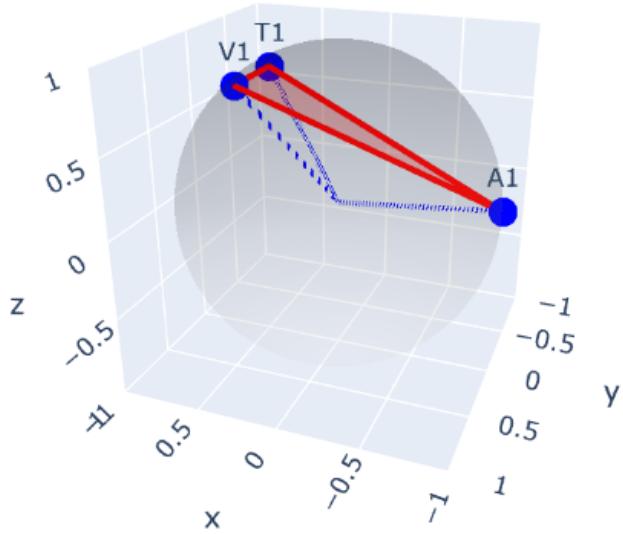
中相关;详见方法、贡献和实验边界。
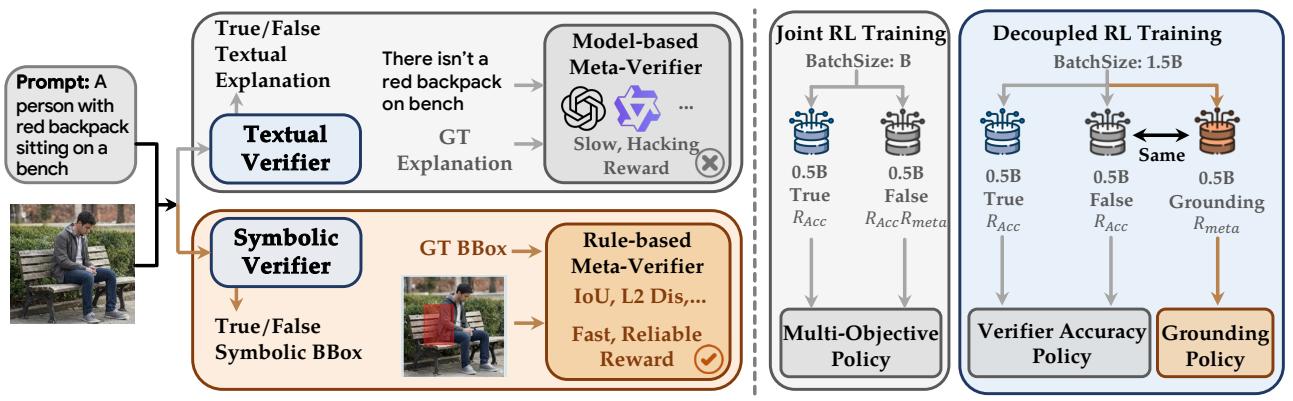
方法:visual verifier 用结构化 meta-verification 和解耦 RL,偏验证器但影响 VLM 训练反馈
中低相关;详见方法、贡献和实验边界。
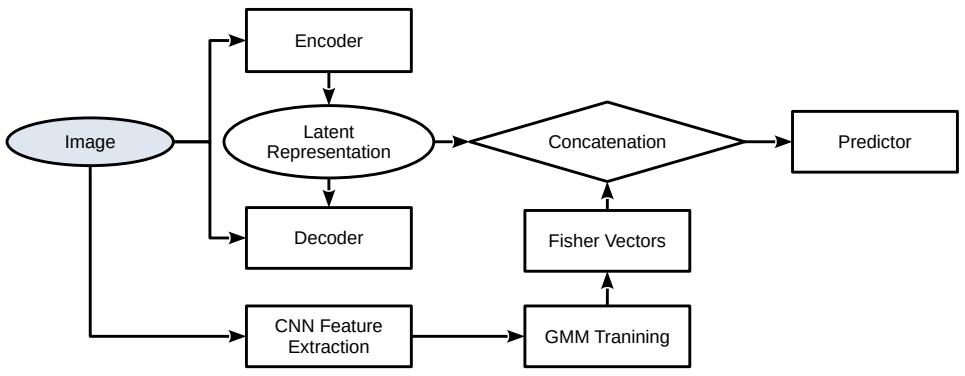
方法:轻量卷积 autoencoder + Fisher pooling 的纹理 SSL,任务偏窄但可作为低算力 SSL 参考
高相关;详见方法、贡献和实验边界。
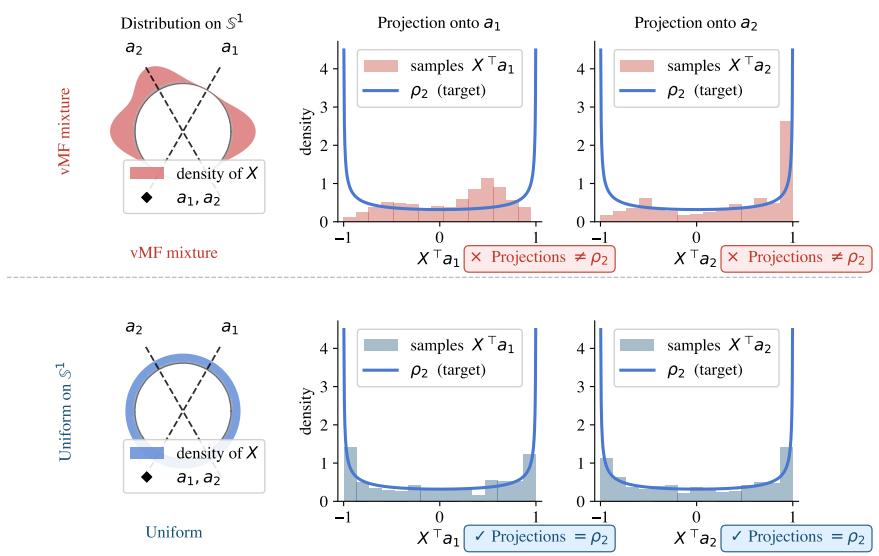
方法:从表示几何解释 JEPA/SSL,直接讨论 hyperspherical uniformity 与 ImageNet linear probe
高相关;详见方法、贡献和实验边界。
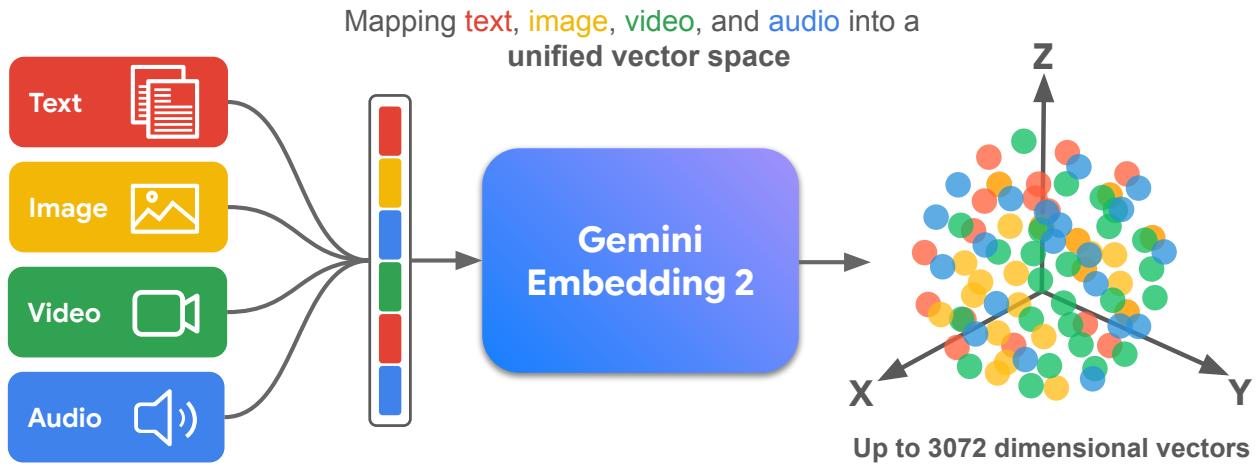
方法:原生视频/音频/图像/文本统一 embedding,代表大模型路线里的多模态表征基座
高相关;详见方法、贡献和实验边界。
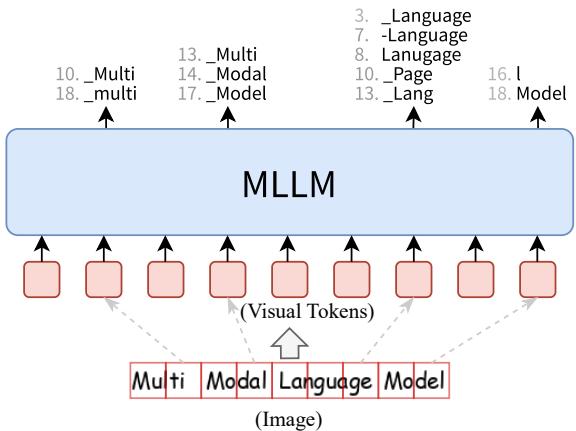
方法:把监督直接打到 visual tokens 上,解决 MLLM 中视觉 token 只被文本 loss 间接优化的问题
高相关;详见方法、贡献和实验边界。
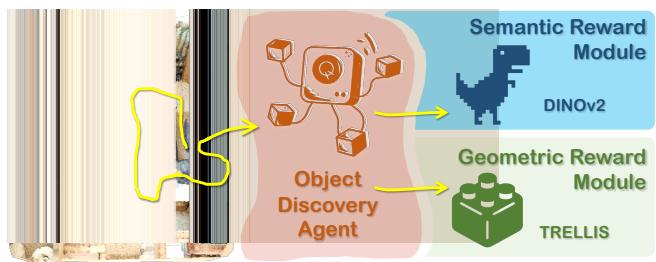
方法:用自监督 2D/3D foundation models 作为 reward,做无场景标注 3D object discovery
中高相关;详见方法、贡献和实验边界。
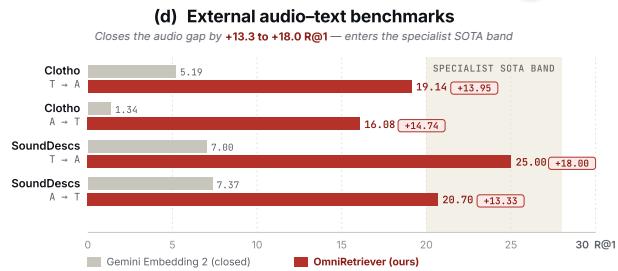
方法:teacher-fusion distillation 学任意 audio/video/text 检索 embedding,与 Gemini Embedding 2 形成对照
中高相关;详见方法、贡献和实验边界。
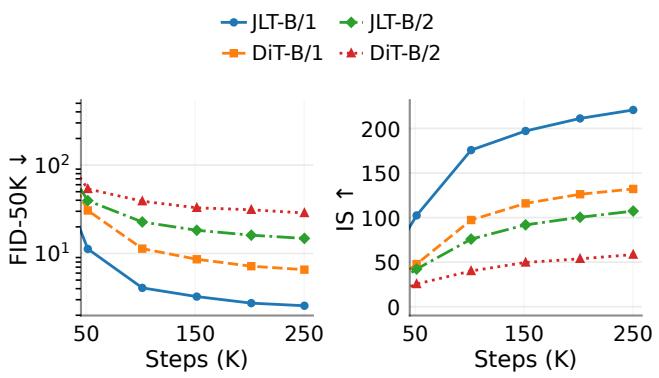
方法:说明 latent diffusion 的预测目标是表示几何选择,不只是 x/epsilon/v 的代数互换
中高相关;详见方法、贡献和实验边界。
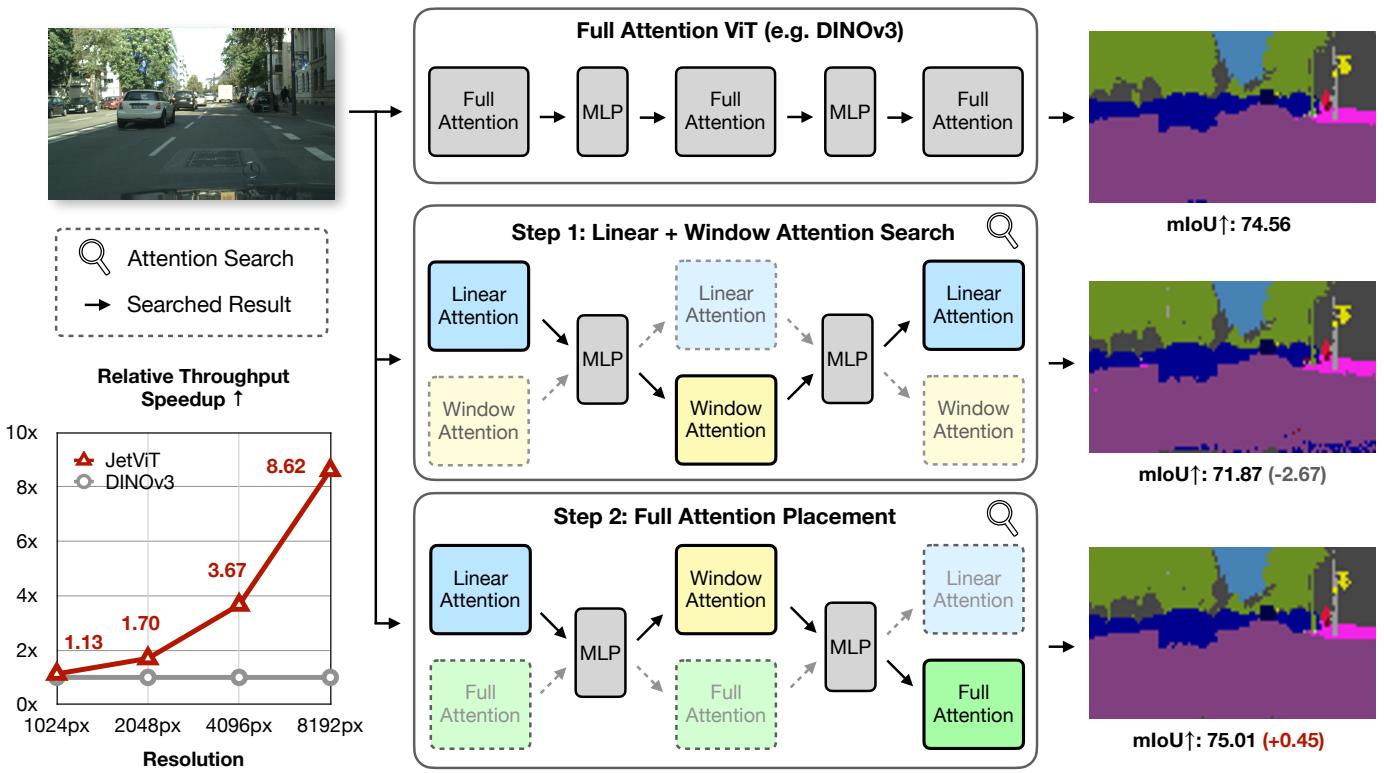
方法:不重训地把 DINOv3/DepthAnythingV2 这类高分辨率 VFM 加速,影响通用视觉基础模型部署
中高相关;详见方法、贡献和实验边界。
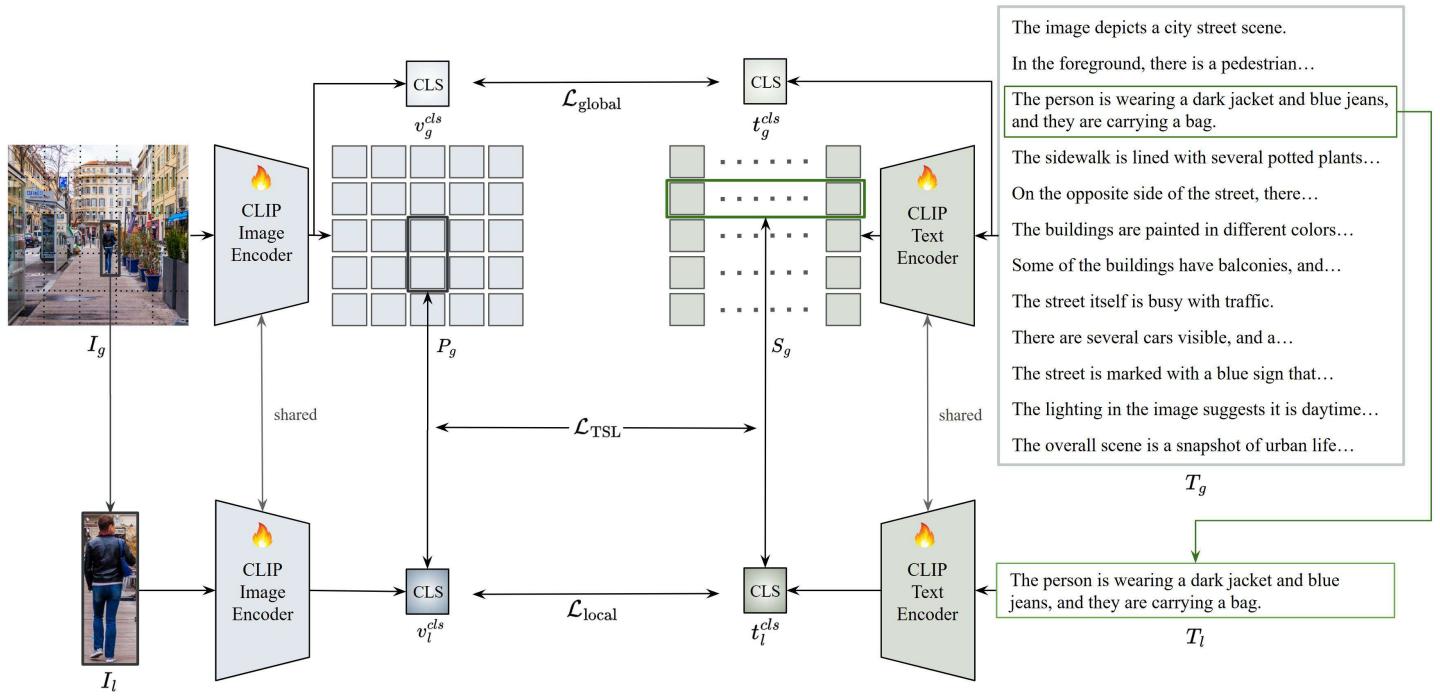
方法:面向 CLIP 长文本/局部区域不足,做 global-local 图文对齐微调
中相关;详见方法、贡献和实验边界。
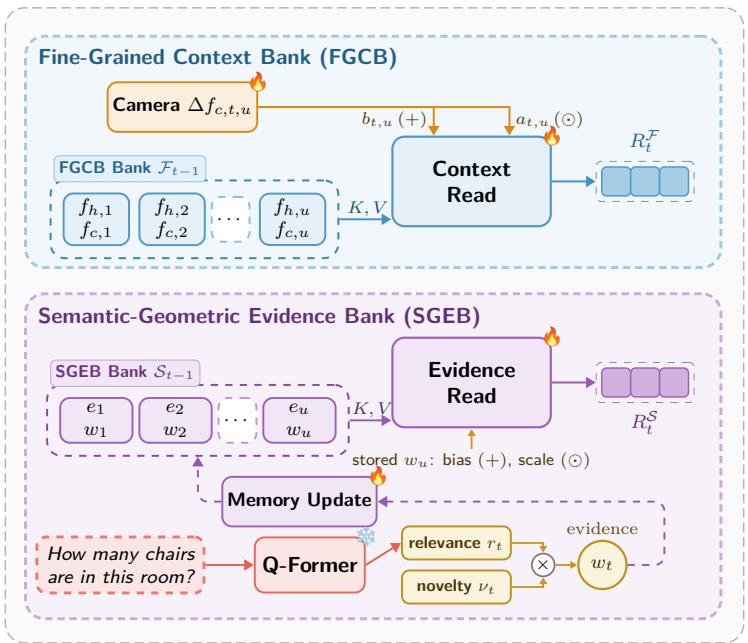
方法:把问题相关性和相机几何写入视频 memory,对 Video-LLM temporal grounding 有参考价值
中相关;详见方法、贡献和实验边界。
方法:研究统一多模态模型是否真正使用生成的中间视觉思考图
中相关;详见方法、贡献和实验边界。
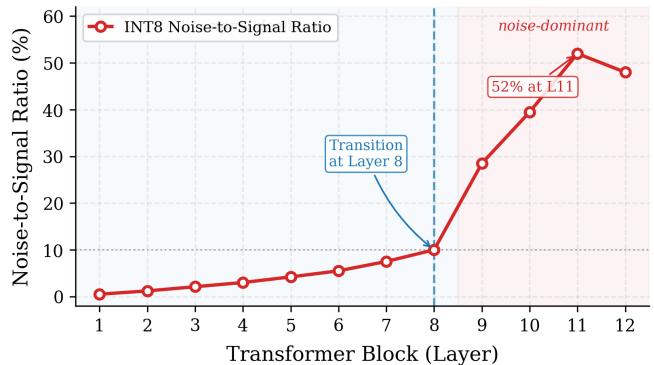
方法:揭示 INT8 CLIP 的 joint embedding 方向会在深层量化噪声中坍塌
中相关;详见方法、贡献和实验边界。
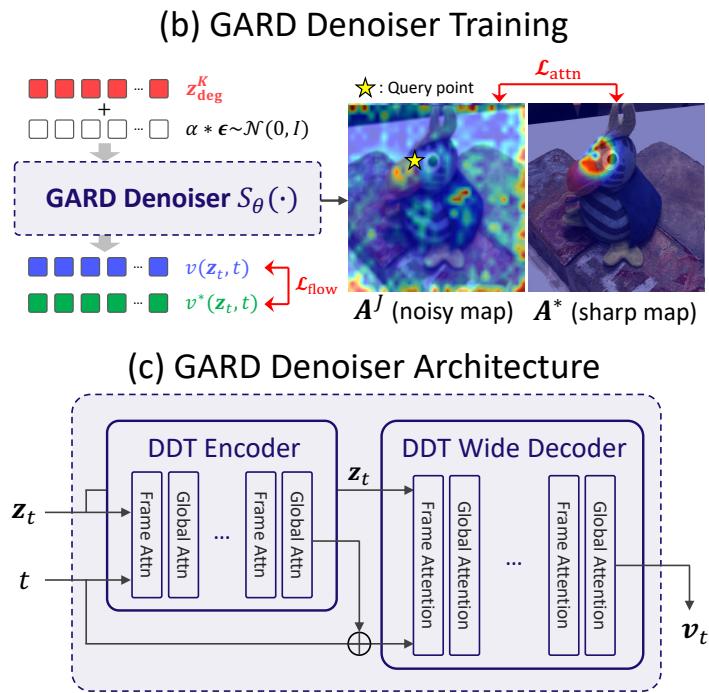
方法:在 3D reconstruction 模型特征空间做 diffusion denoising,体现“修特征而非修像素”的路线
中相关;详见方法、贡献和实验边界。
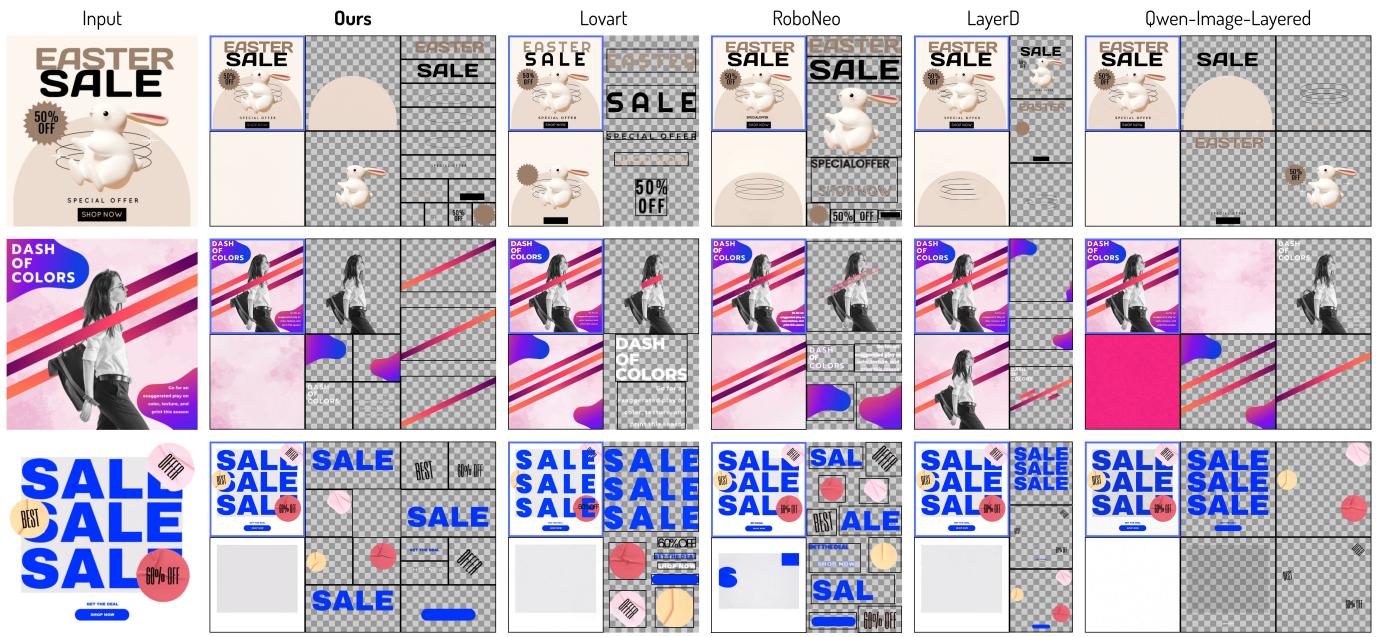
方法:20B masked region diffusion,把选择性 token masking 用在多层透明图像生成/编辑
中相关;详见方法、贡献和实验边界。
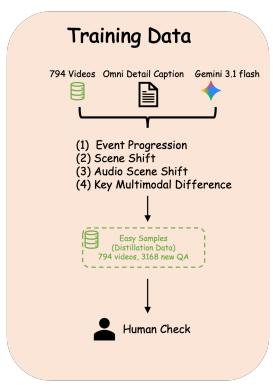
方法:对长 audio-video token 序列做 memory compression 和 distillation
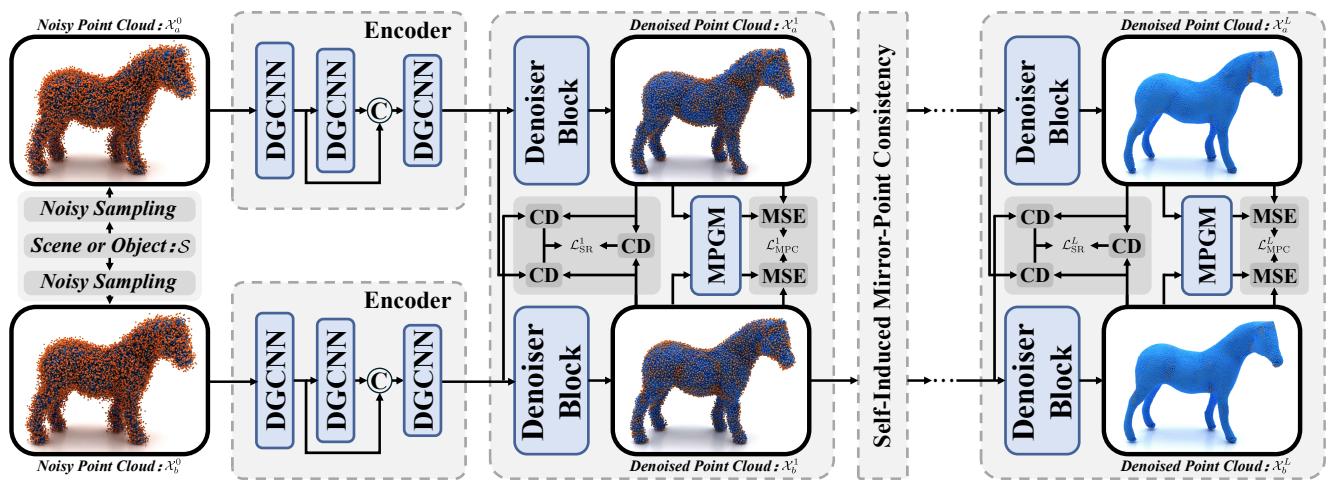
中相关;详见方法、贡献和实验边界。
方法:无监督 3D 点云去噪中的 mirror-point consistency,几何 SSL 信号明确但任务较专
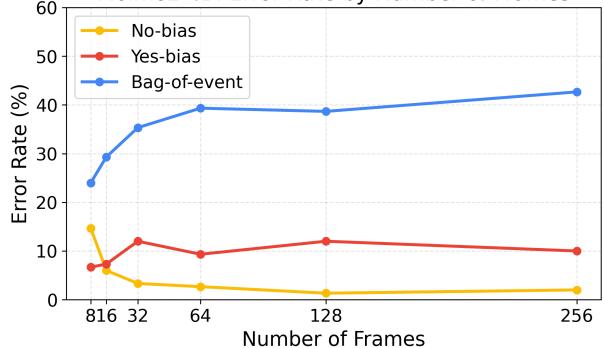
中相关;详见方法、贡献和实验边界。
方法:VideoLLM temporal grounding 诊断:模型可能把视频当事件袋而非时序结构
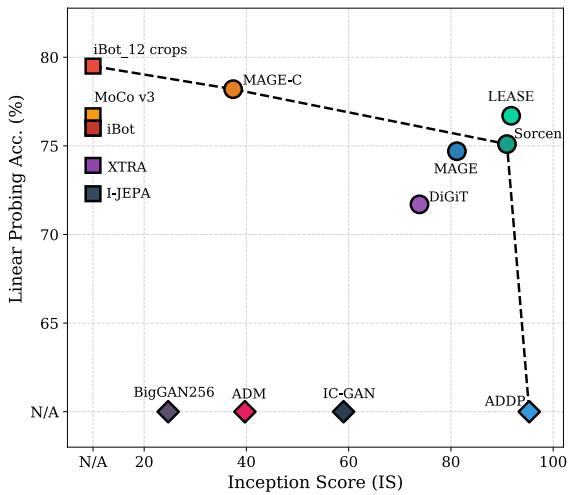
高相关;详见方法、贡献和实验边界。
方法:自监督 codebook + masked reconstruction + contrastive alignment,直接服务统一视觉表示与生成
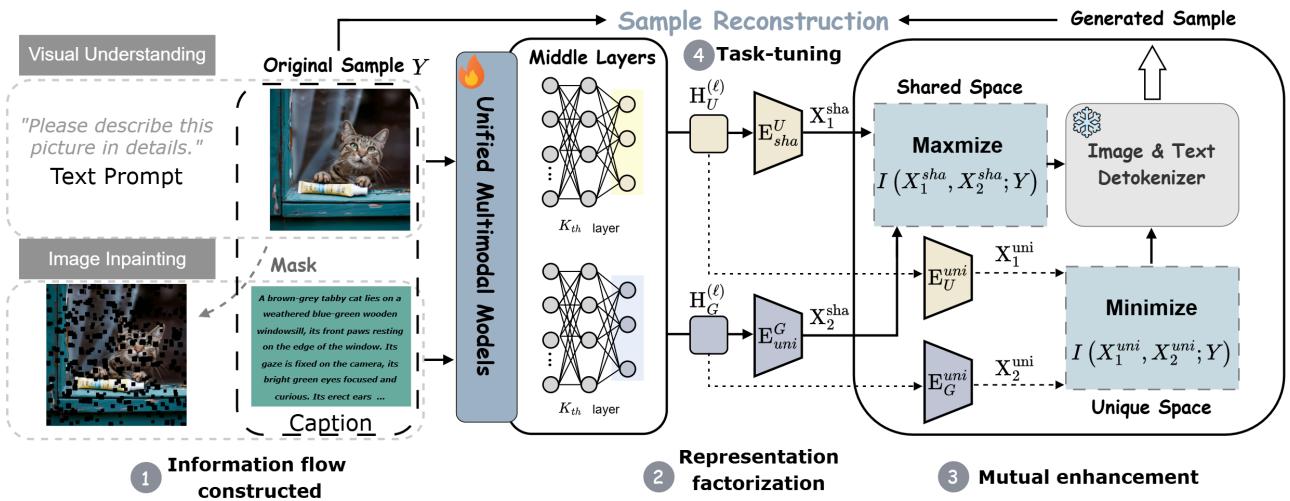
高相关;详见方法、贡献和实验边界。
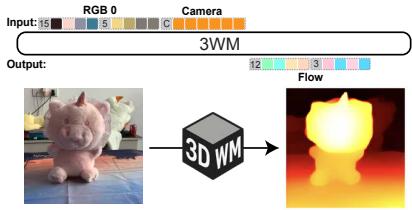
方法:用同一物理世界模型统一深度、NVS、对象操控等 3D 视觉任务
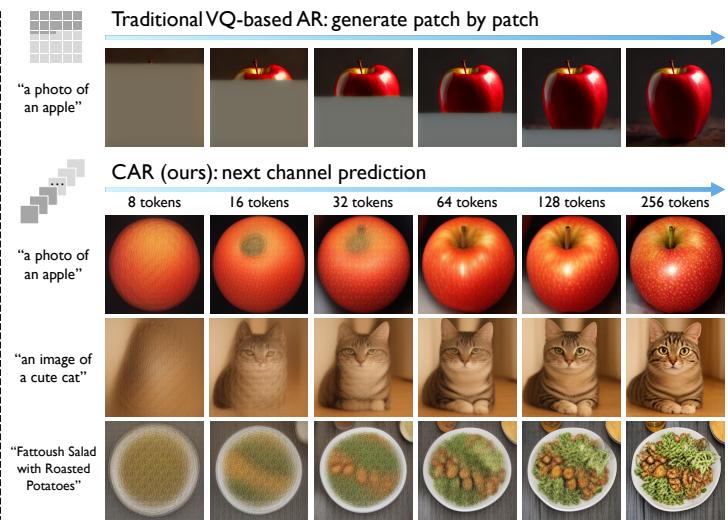
中高相关;详见方法、贡献和实验边界。
方法:把图像 tokenization 从 patch token 改成 channel token,影响统一生成/表示建模
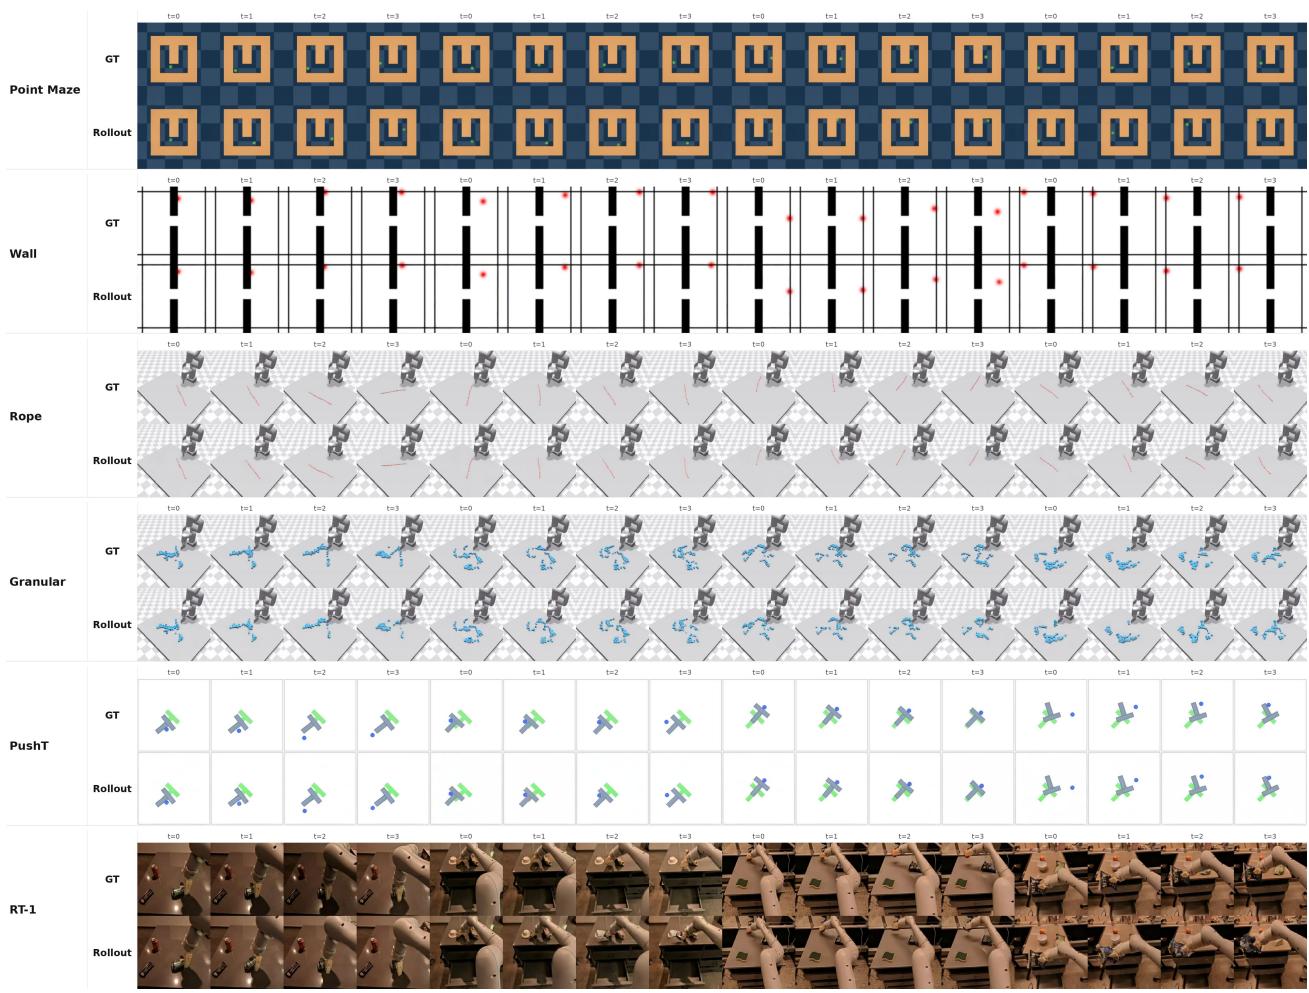
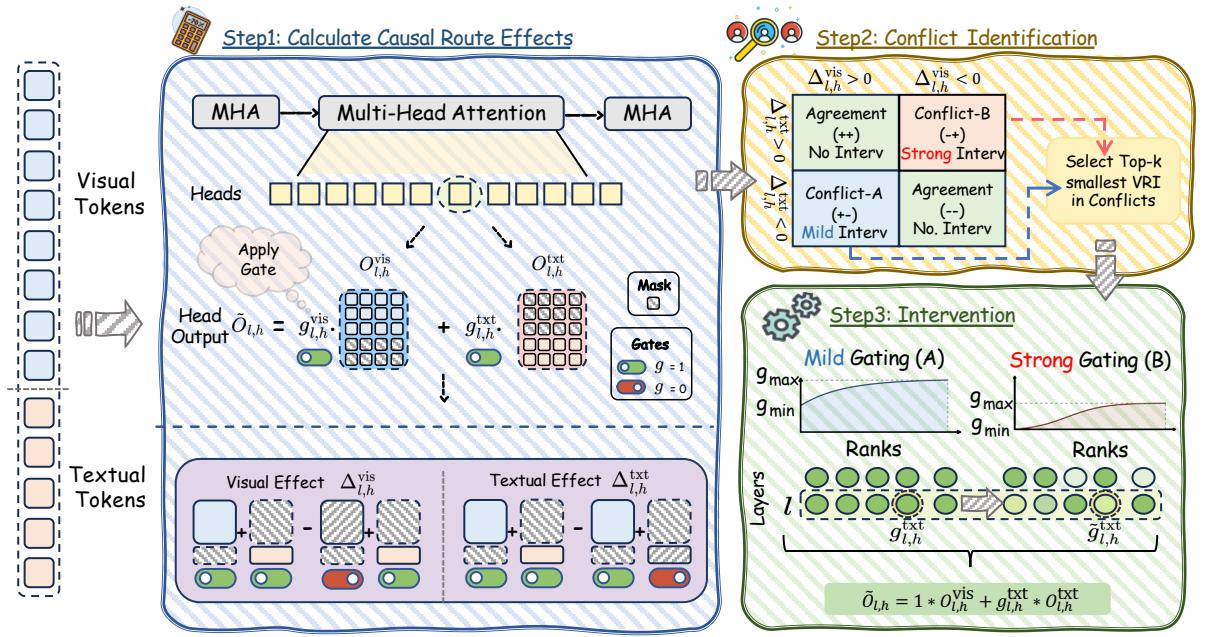
高相关;详见方法、贡献和实验边界。
方法:MAE/diffusion 表示学习里 residual shortcut 对语义抽象的影响,状态更新
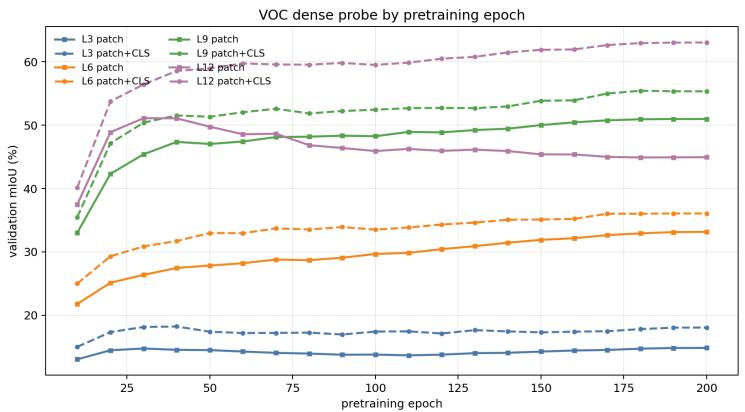
中高相关;详见方法、贡献和实验边界。
方法:分析 DINO ViT 的 dense degradation,并用选择性 token mixing 提升密集预测
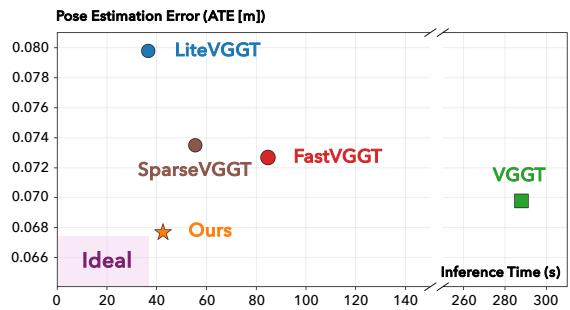
中高相关;详见方法、贡献和实验边界。
方法:视觉几何 Transformer 的 token 选择策略,对多视图/3D foundation model 效率有参考
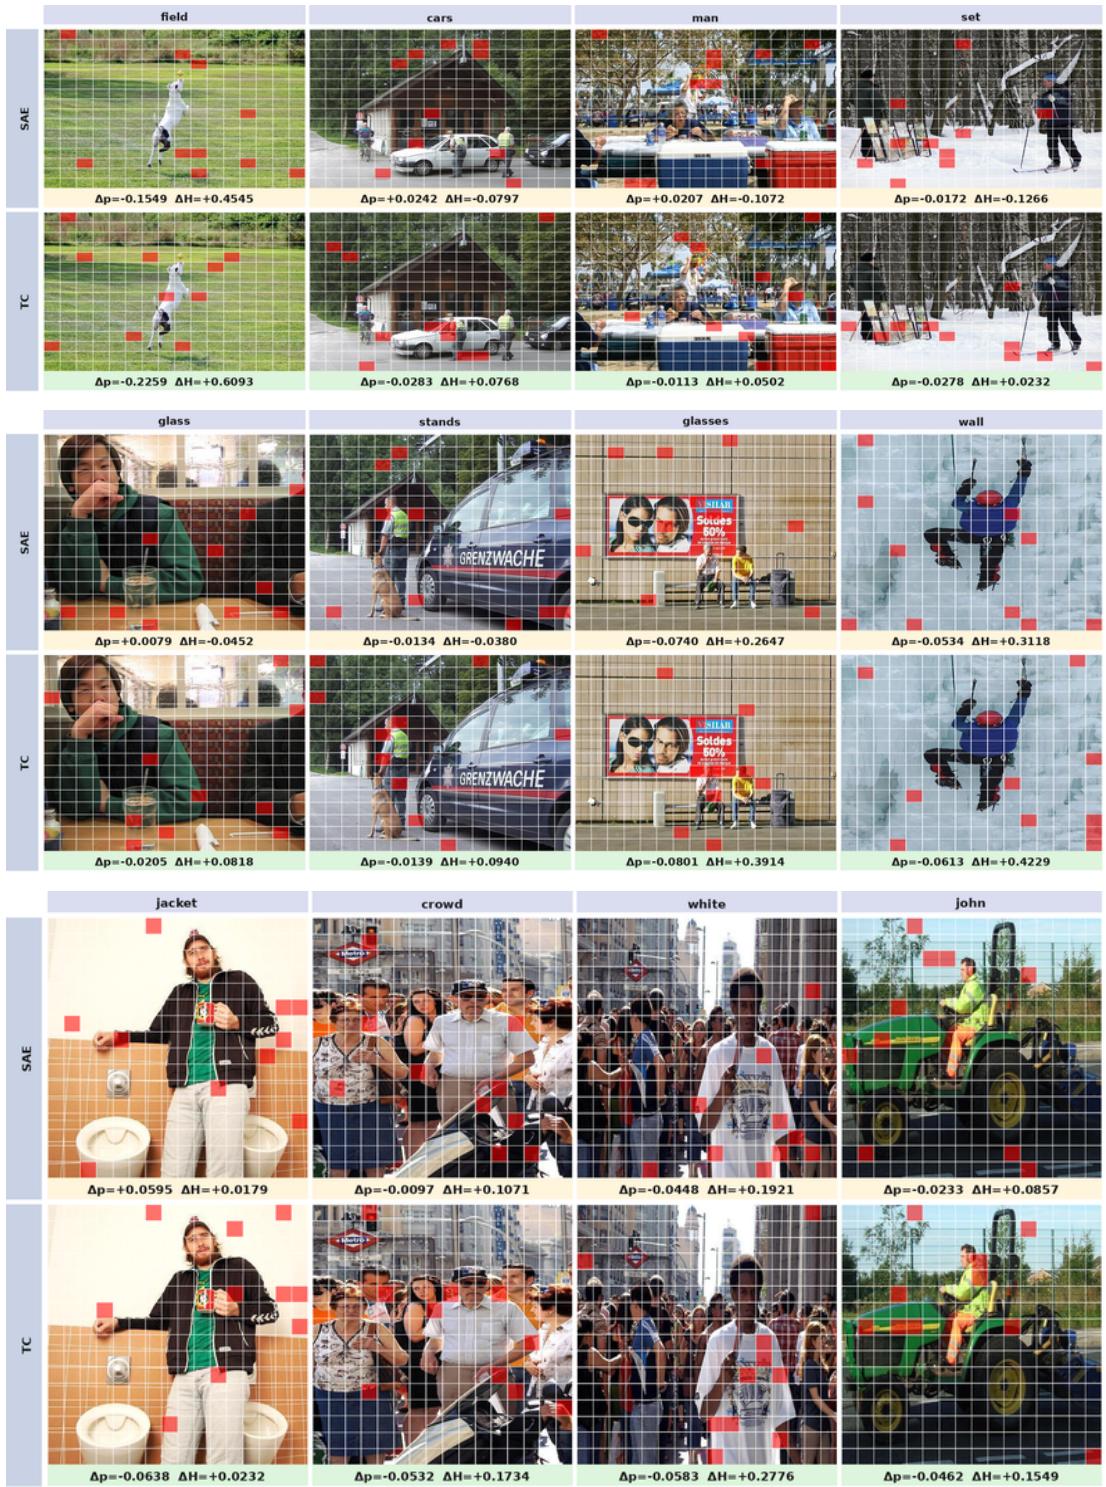
中高相关;详见方法、贡献和实验边界。
方法:用 transcoder 追踪 VLM 中从图像 patch 到文本 token 的计算通路
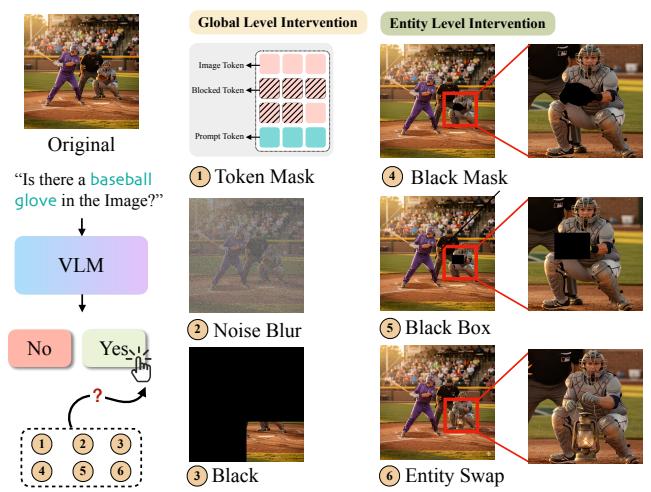
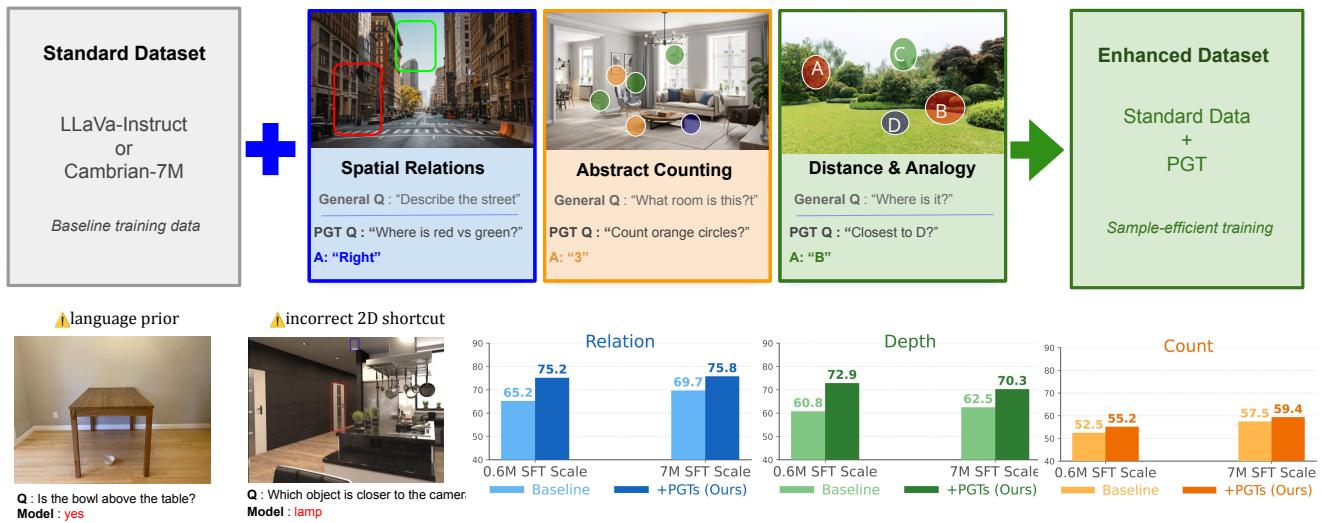
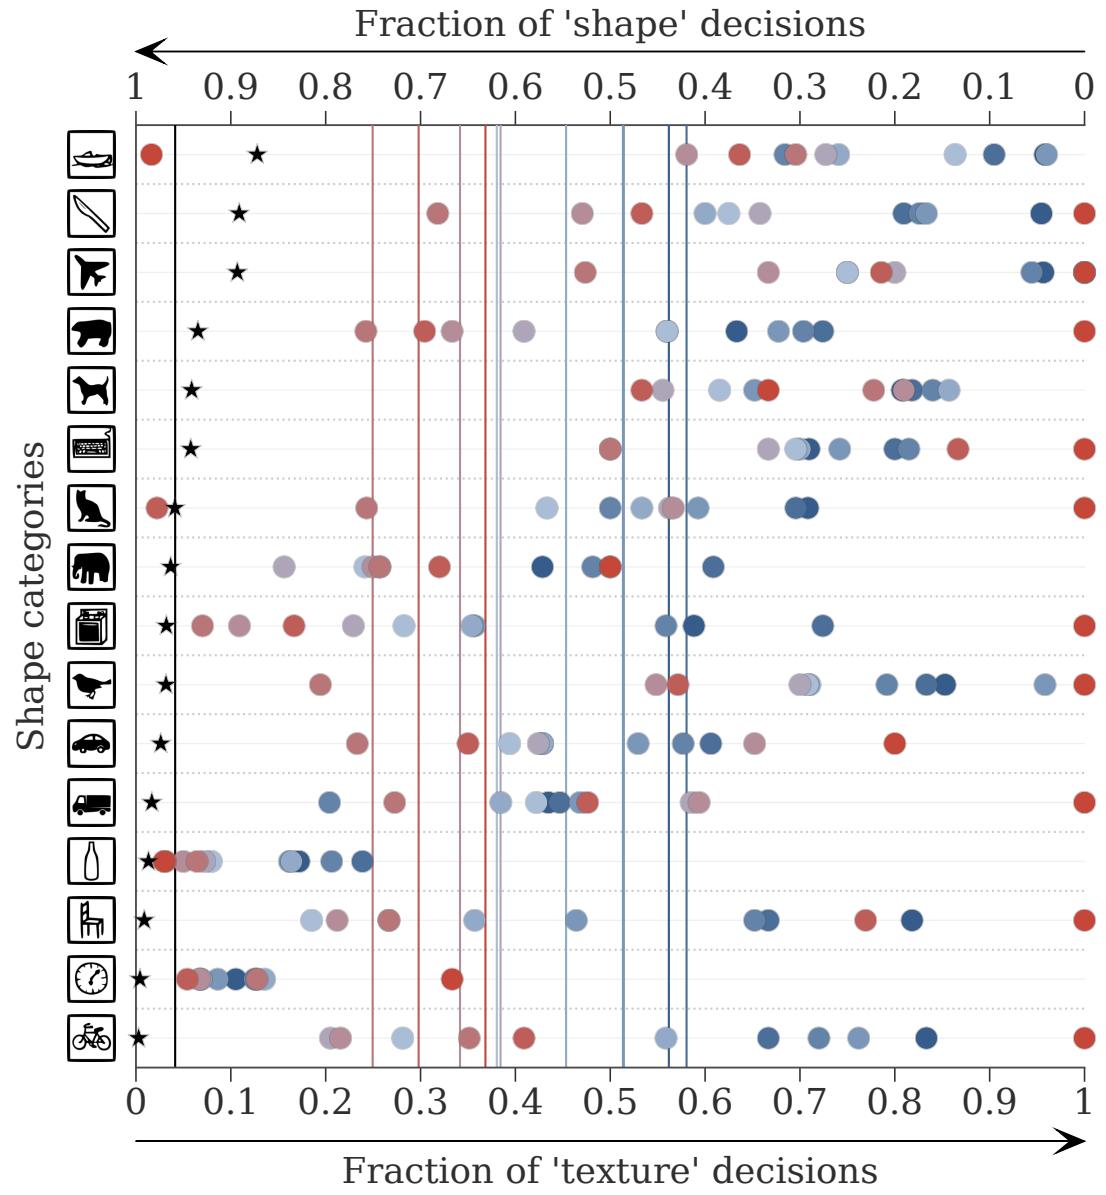
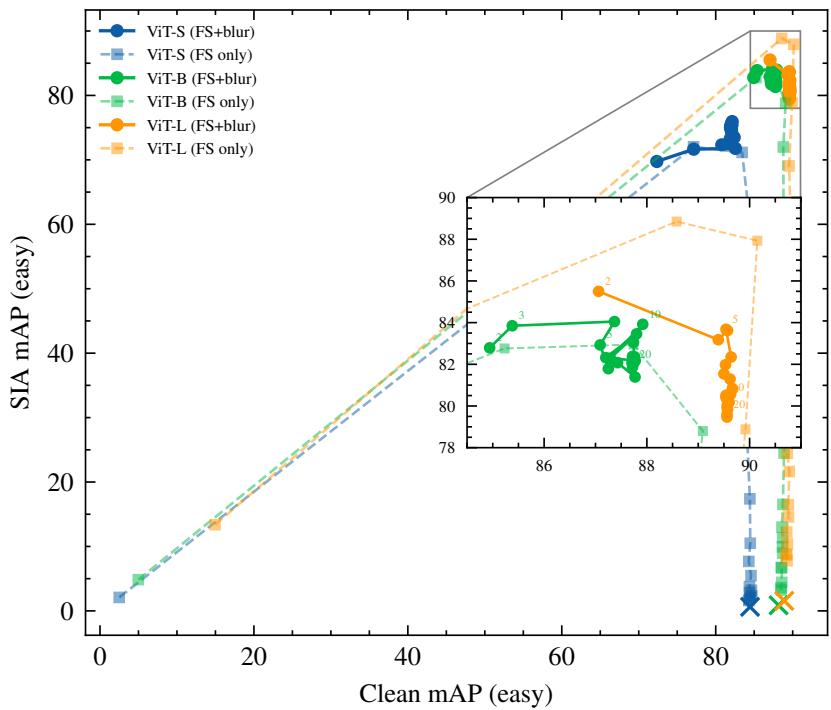
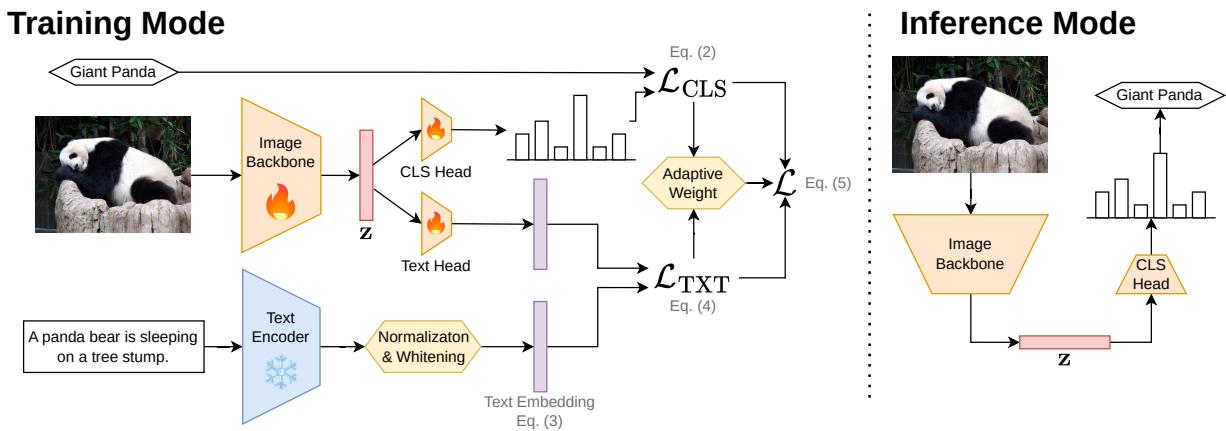
今天最值得先读:它不是完整 CLIP 式预训练,而是把语言语义变成低成本的视觉表征塑形目标。
方法:frozen text encoder semantic anchors for image representation training
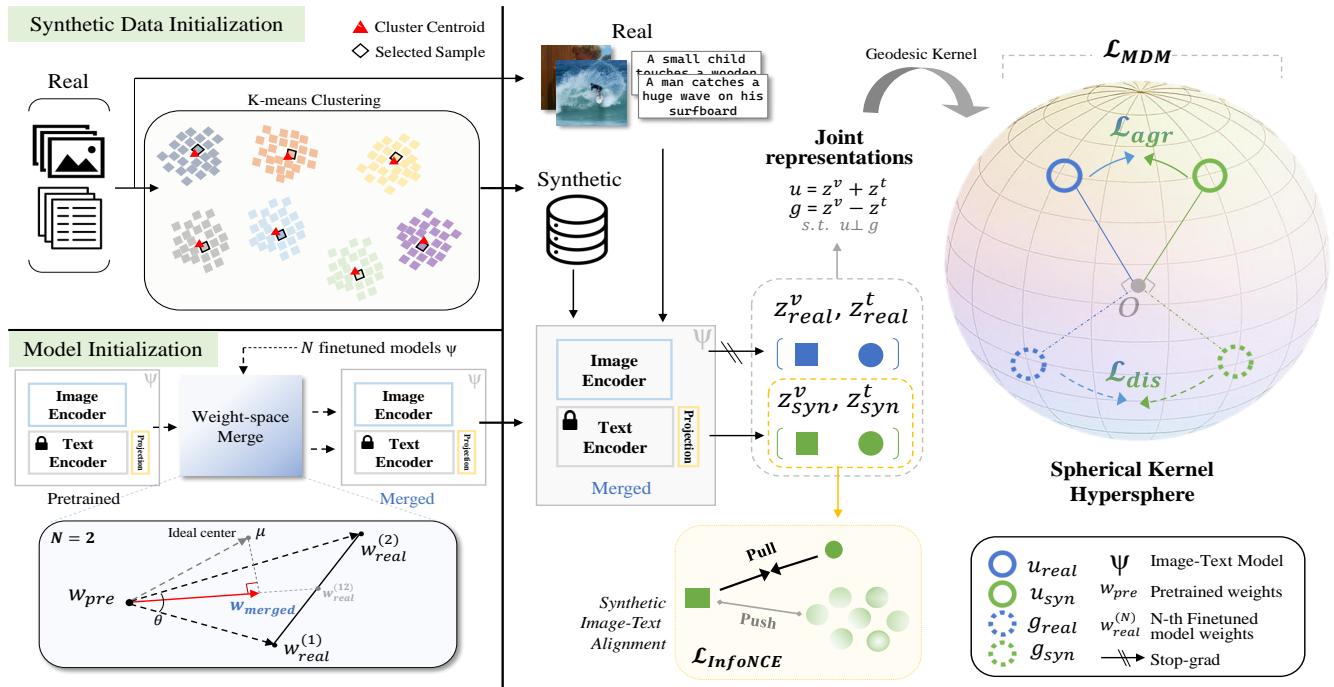
适合关注多模态预训练数据效率的人精读:它把合成图文对放进分布匹配和对齐保持问题里。
方法:geometric multimodal distribution matching for image-text dataset distillation
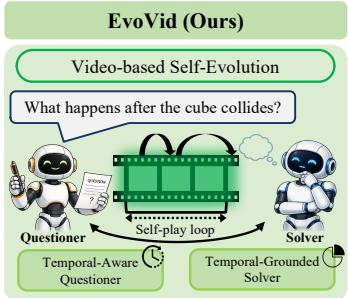
它把视频自监督和 Video-LLM 后训练接起来,值得和 V-JEPA、视频掩码建模放在一起看。
方法:temporal-aware questioner reward and temporal-grounded solver reward
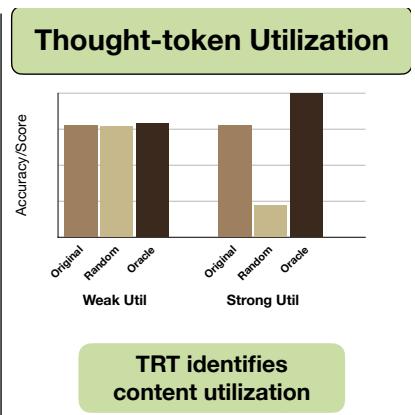
这是一个诊断工具型论文:以后看 latent visual token 方法时,应该要求内容替换消融。
方法:token replacement test for continuous and discrete visual thought tokens
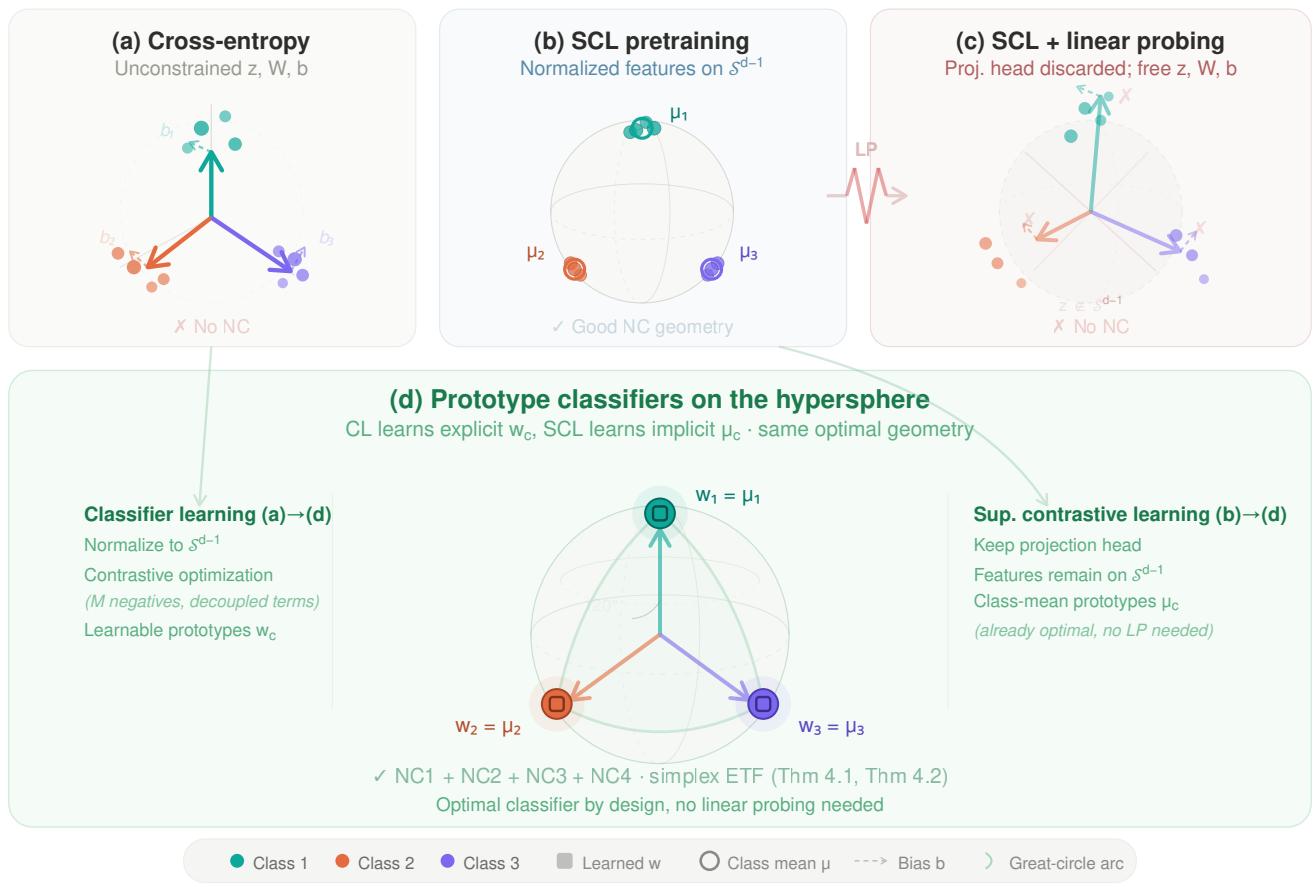
偏理论和监督表征,但对理解 linear probe、原型、均匀性和表征几何有参考价值。
方法:prototype contrast with NTCE / NONL objectives on the hypersphere
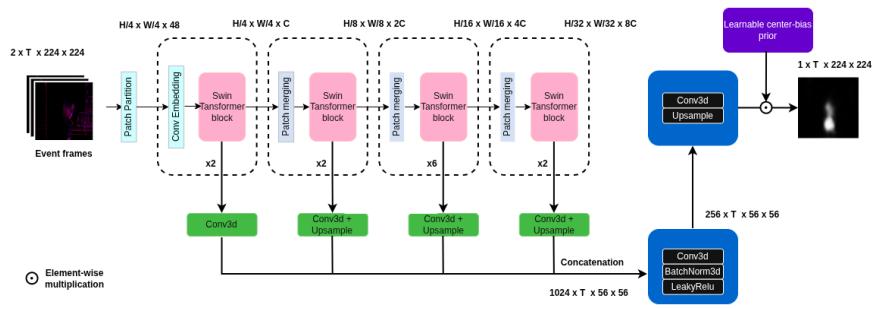
模态较专,适合作为自监督 backbone 迁移到异构视觉模态的扫读案例。
方法:self-supervised event-based Swin Transformer plus lightweight saliency decoder
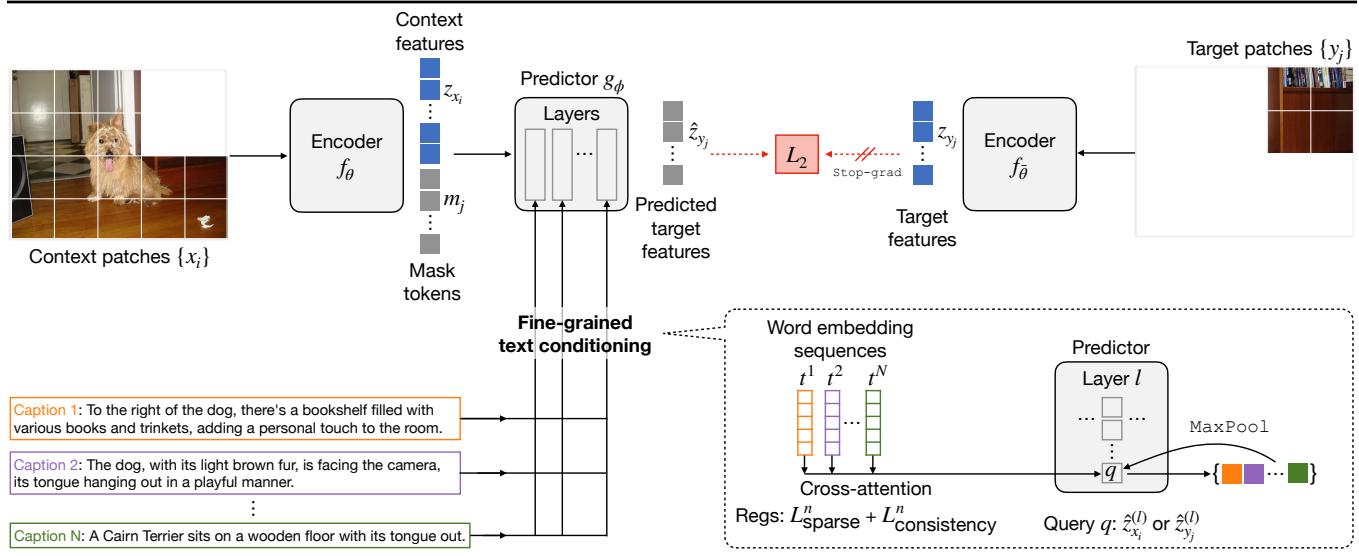
视觉自监督和视觉语言预训练之间的边界被进一步打薄:它仍然预测 feature,不直接重建像素,也不完全依赖对比学习。
方法:caption-conditioned masked feature prediction with sparse cross-attention text conditioner
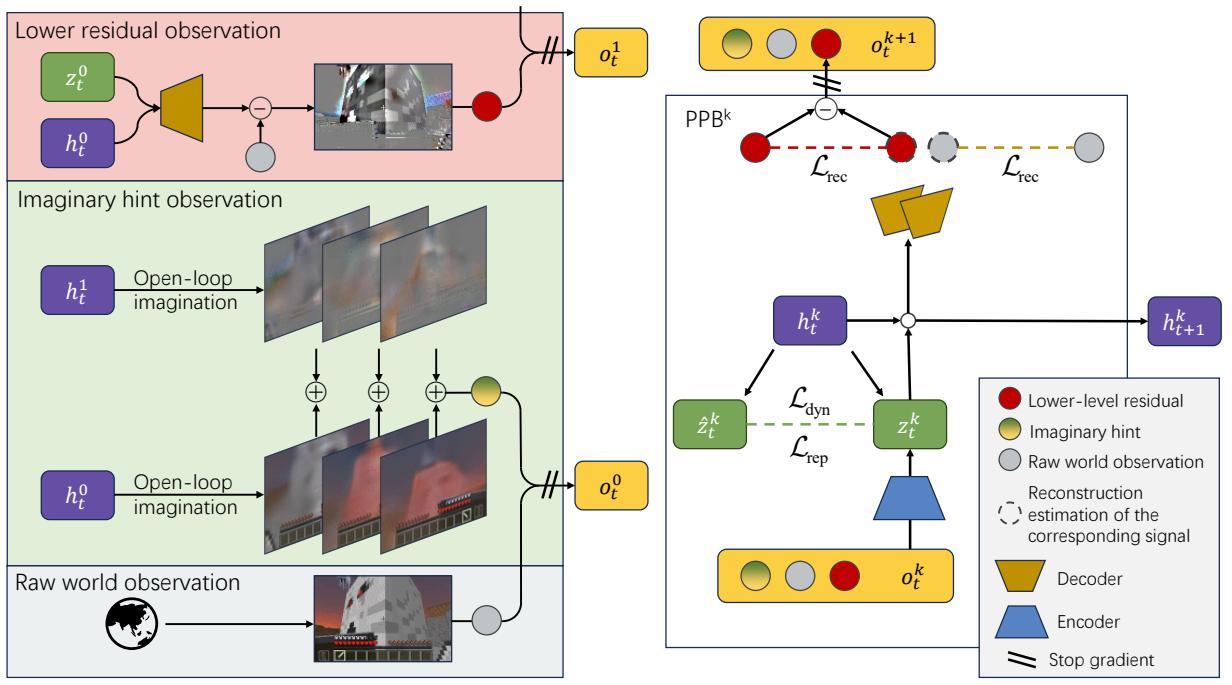
它把视频 SSL 的目标从重建下一帧推向重建“低层没有解释完的部分”。
方法:hierarchical residual world model for self-supervised visual foresight
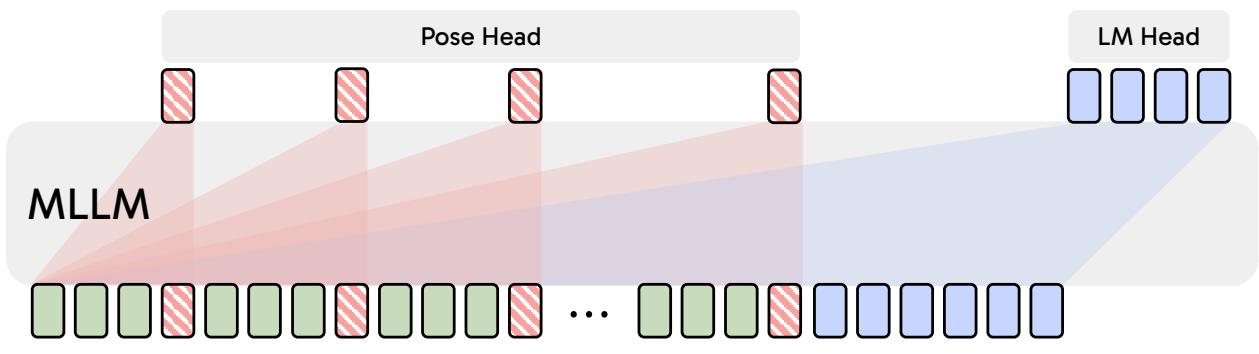
用伪位姿把跨帧 token 固定到共享空间,是视频 VFM/MLLM 很值得跟的结构化监督。
方法:learnable camera tokens + pose regression head for frame-level grounding
高相关;详见方法、贡献和实验边界。
方法:把自监督目标从激活表征扩展到可缩放视觉模型初始化权重模板
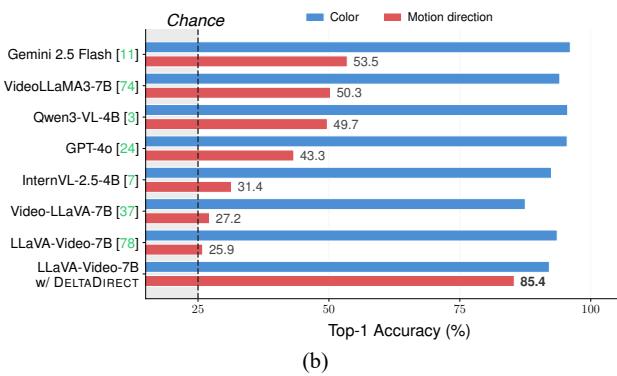
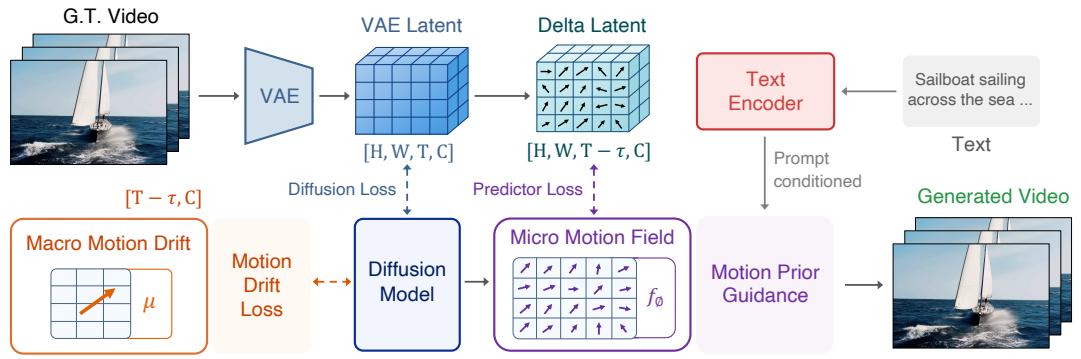
这类诊断比单纯刷视频 QA 更有价值,因为它定位了视觉表征到语言读出的断点。
方法:feature-delta motion vector objective at projector level
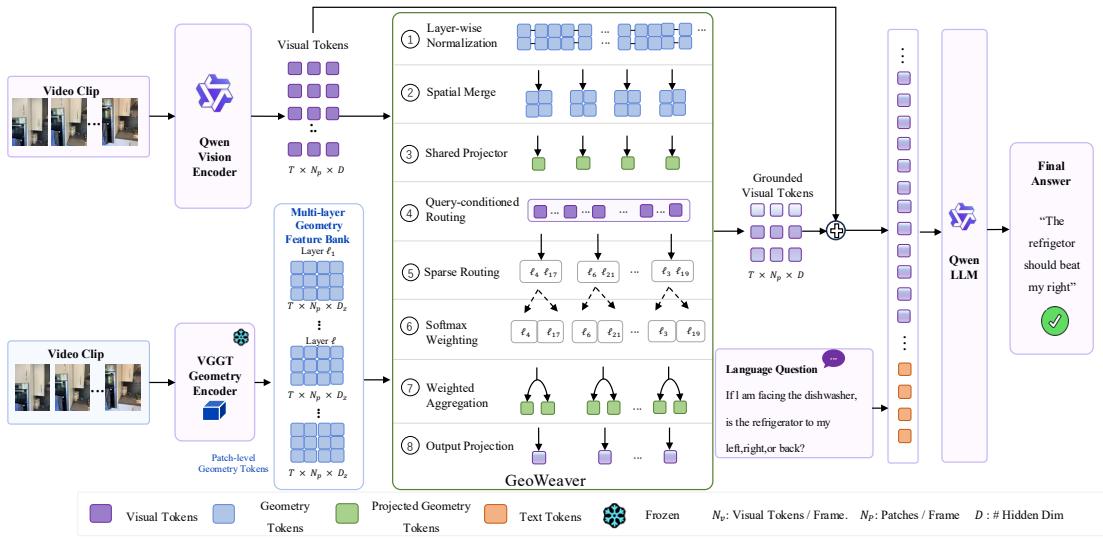
这篇不是 JEPA,而是 VLM 视觉 token grounding:冻结几何编码器的证据被分配给多层视觉 token。
方法:multi-level geometry bank + residual grounding before LLM reasoning
中相关;详见方法、贡献和实验边界。
方法:从几何/协方差角度统一 nuisance-robust representation learning 的损失设计
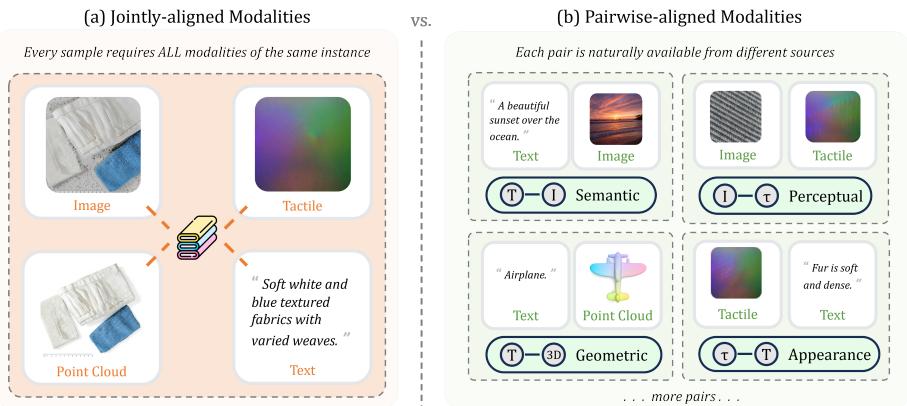
它把多模态表征学习的问题改写成模态图连通性问题,重点不在堆更多模态,而在证明 pairwise supervision 也能学习共享/私有 latent 结构。
方法:self-modal reconstruction + pairwise contrastive latent alignment
高相关;详见方法、贡献和实验边界。
方法:VFM dense feature 自监督密化,适合接在 DINO/CLIP/SigLIP 视觉表征后
中高相关;详见方法、贡献和实验边界。
方法:重建式自监督和 2DGS 表示结合,可作为图像重建预训练线索
中相关;详见方法、贡献和实验边界。
方法:用 SAM/DINO 先验蒸馏到生成模型,偏生成但有 VFM 表征迁移价值
中相关;详见方法、贡献和实验边界。
方法:无标注视频 latent action 表征的理论分析,偏世界模型/视频自监督
高相关;详见方法、贡献和实验边界。
方法:探索用冻结图像 VFM 低成本获得视频时序能力
中高相关;详见方法、贡献和实验边界。
方法:检验 SSL/pretrained encoder 的跨下游 feature-level 脆弱性