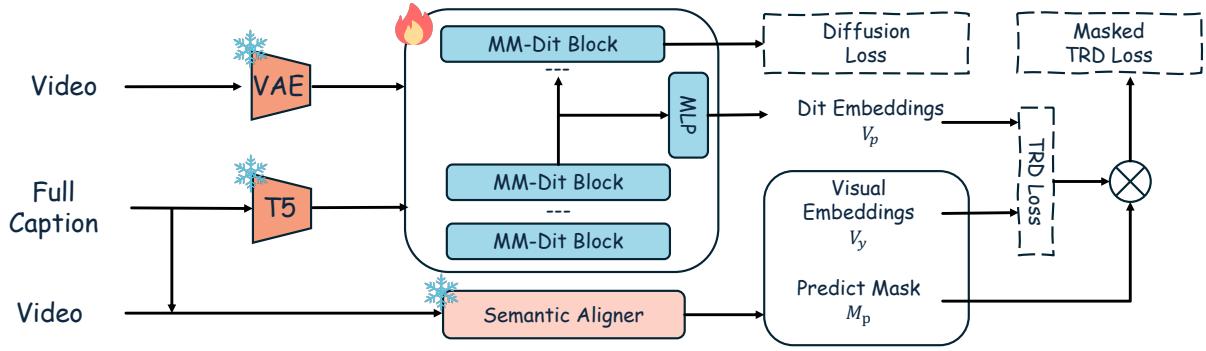
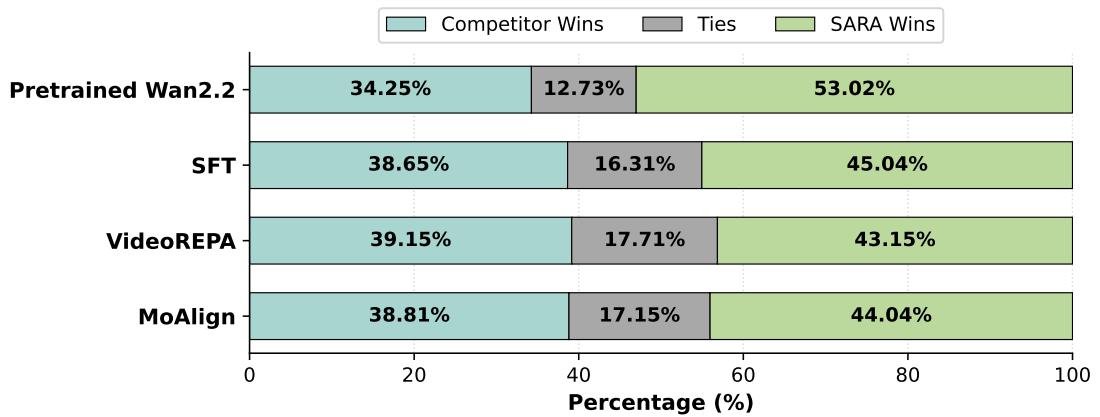
Figureure 2 · Overview of SARAFigure 2 Overview of SARA. Stage I (top): a lightweight aligner on top of frozen V-JEPA, SAM 3.1, and Qwen3- VL-Embedding backbones learns, for any (video, caption) pair, a text-conditioned per-patch saliency $M _ { p } ,$ supervised jointly by per-entity, combined-entity, and background SAM masks (LBCE) and calibrated by a caption-level InfoNCE. Stage II (bottom): the frozen aligner is queried with the full caption, and its saliency is turned into pair weights that route a masked token-relation distillation loss, added to the diffusion loss of a trainable DiT.这张图概括 SARA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 5 · Blind pairwise user studyFigure 5 Blind pairwise user study. Each row reports the percentage of comparisons where annotators prefer SARA, tie, or prefer the baseline. SARA is preferred over every baseline.这张图/表用于判断 SARA 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。