GeoWorld-VLM:它和通用视觉自监督的关系在于:用冻结 camera-conditioned video world model 作为几何 teacher 来蒸馏 VLM 视觉通路,是 world-model-as-teacher 的典型...
中高相关;详见方法、贡献和实验边界。
GeoWorld-VLM: Geometry from World Models for Vision-Language Models arXiv 更新 原文链接
编号2605.16713优先级P2类别arXiv 更新会议arXiv 更新方法用冻结 camera-conditioned video world model 作为几何 teacher 来蒸馏 VLM 视觉通路,是 world-model-as-teacher 的典型案例来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:用冻结 camera-conditioned video world model 作为几何 teacher 来蒸馏 VLM 视觉通路,是 world-model-as-teacher 的典型... 中高相关;详见方法、贡献和实验边界。
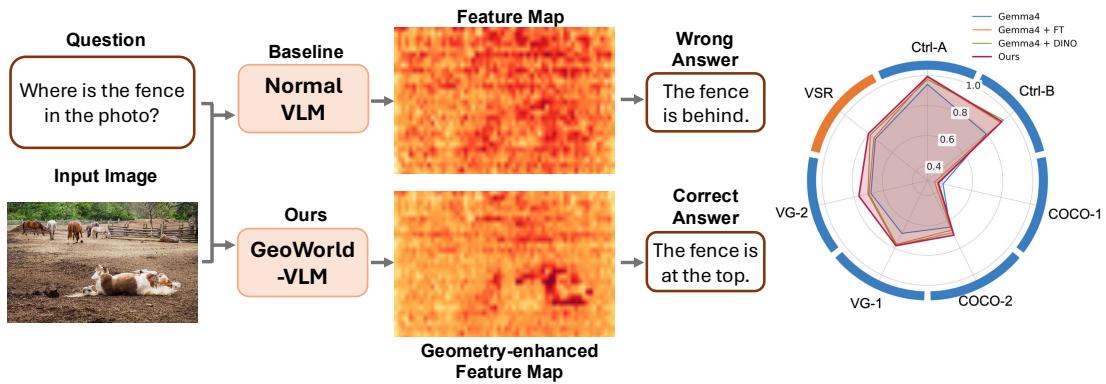
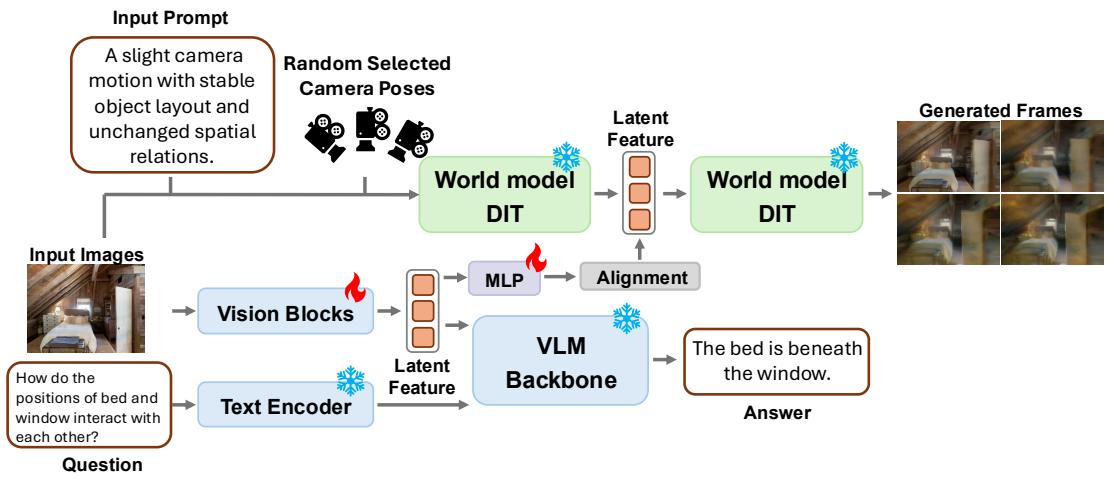
Figureure 1 · : OverviewFigure 1: Overview. Given an input image and a spatial reasoning question, GeoWorld-VLM enhances the spatial understanding of standard vision-language models by injecting world-model priors at the feature-map level. Compared with the original VLM features, GeoWorld-VLM produces more geometry-aware representations, leading to clearer spatial grounding and improved answer accuracy. As shown on the right, our method consistently outperforms strong baselines, including the original Gemma-4, fine-tuned Gemma, and fine-tuned Gemma with DINO features, across diverse spatial reasoning benchmarks such as What’sUp and VSR.这张图概括 GeoWorld-VLM 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : GeoWorld-VLMFigure 2: GeoWorld-VLM. During training, GeoWorld-VLM fine-tunes only the vision blocks including vision encoder and multimodal projector. It aligns the latent features produced by the VLM vision encoder with intermediate world-model representations, where the world model takes the input image, text prompt, and randomly sampled camera poses as input. At inference time, GeoWorld-VLM no longer requires the world model and can perform standard VLM inference directly.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 GeoWorld-VLM 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:用冻结 camera-conditioned video world model 作为几何 teacher 来蒸馏 VLM 视觉通路,是 world-model-as-teacher 的典型案例。
方法拆解
用冻结 camera-conditioned video world model 作为几何 teacher 来蒸馏 VLM 视觉通路,是 world-model-as-teacher 的典型案例