Self-supervised Hierarchical Visual Reasoning with World Model ICML 2026 · CCF A 原文链接
编号2605.17537优先级P1类别World model / video SSL会议ICML 2026 · CCF A方法hierarchical residual world model for self-supervised visual foresight来源arXiv / OpenReview
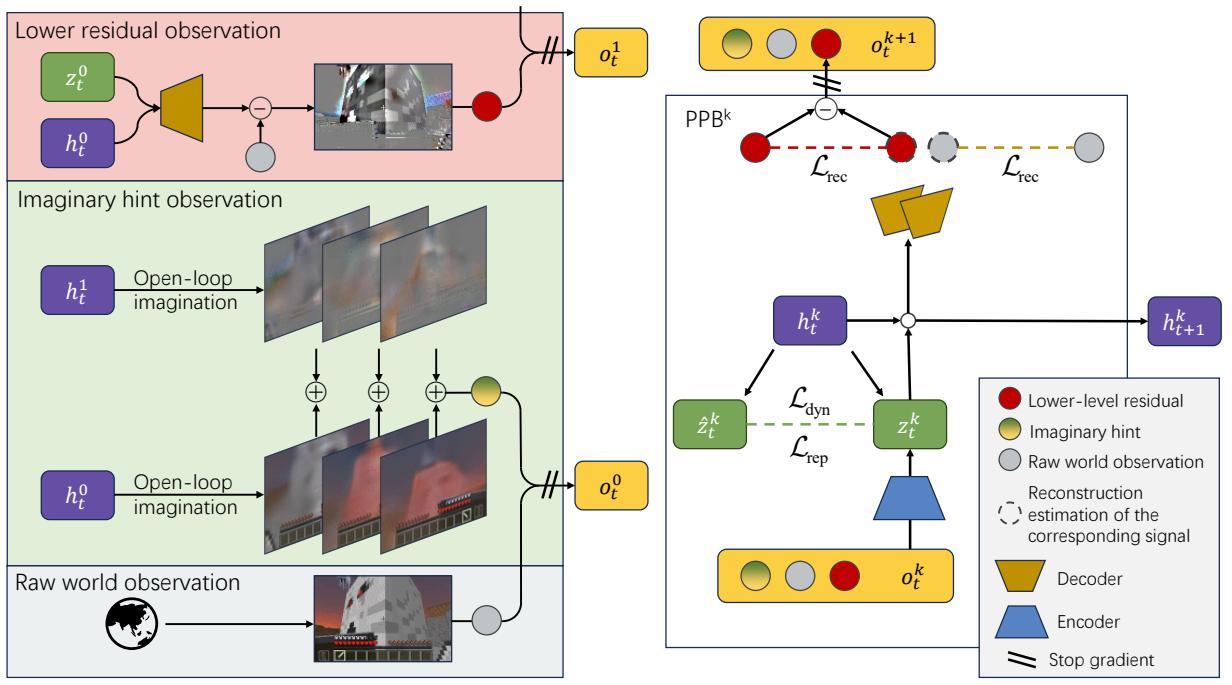
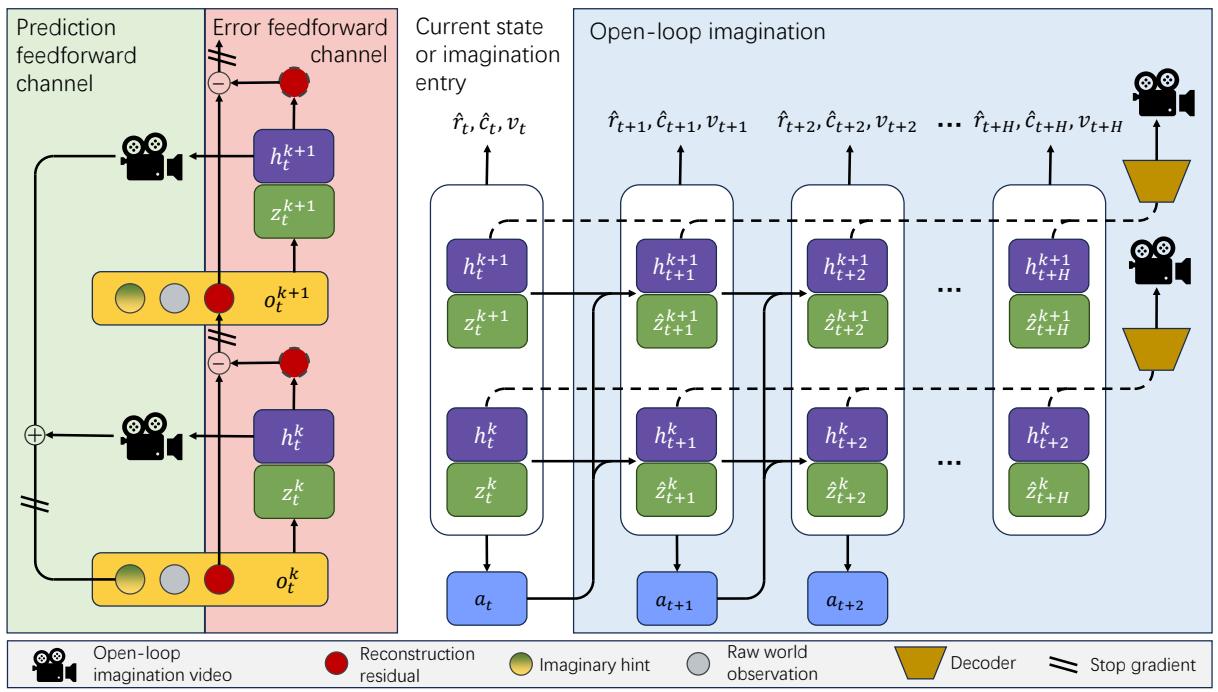
Figureure 1 · Overview of ResDreamer a model base RL algorithm based on hierarchicalFigure 1. Overview of ResDreamer a model base RL algorithm based on hierarchical world model. The left side shows the structure of enhanced visual observations. Adjacent world model layers communicate by residual and predictive signal within the enhanced observation. The right side shows the modules and training process of the k-th layer world model. The Encoder reads enhanced visual observations and gives the posterior $z _ { t . } ^ { k } .$ The dynamic predictor learns to estimate $z _ { t } ^ { k }$ with $\hat { z } _ { t } ^ { k }$ without accessing the observation. The sequence model updates internal state $h _ { t } ^ { k }$ by $z _ { t } ^ { k }$ . The Decoder reconstructs the observation signal which generates reconstruction loss and residual visual signal for upper layer.这张图概括 ResDreamer 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · The information channel between world model layers is bidirectionalFigure 2. The information channel between world model layers is bidirectional. Only reconstruction error and modulated foresight images are transmitted between layers, with no gradients being passed. On one hand, each layer of the PPB generates predictions about the external world and transmits visual planning representations to lower layers. On the other hand, the PPB treats low-level residuals as self-supervised learning signals to obtain a more complete inner representation.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 ResDreamer 的方法或实验,请结合正文精读段落一起看。