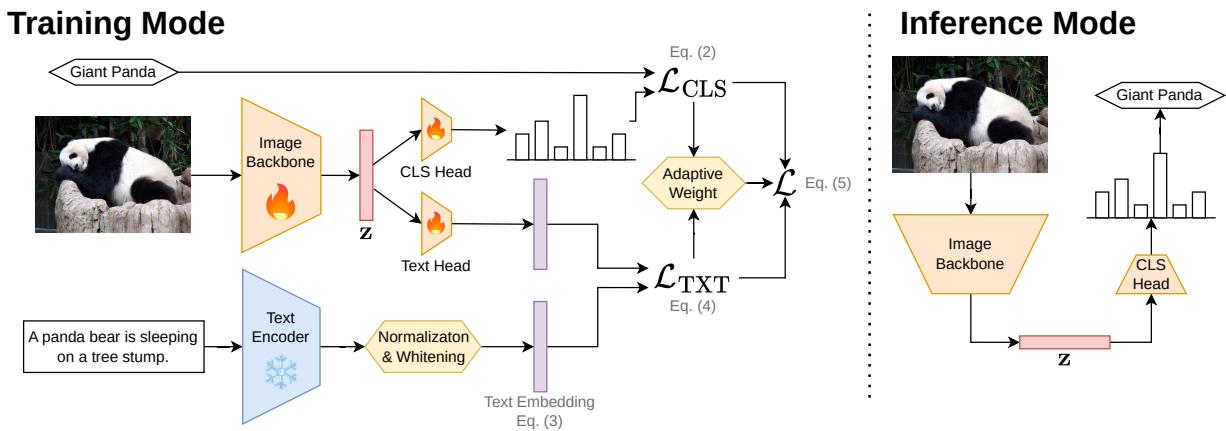
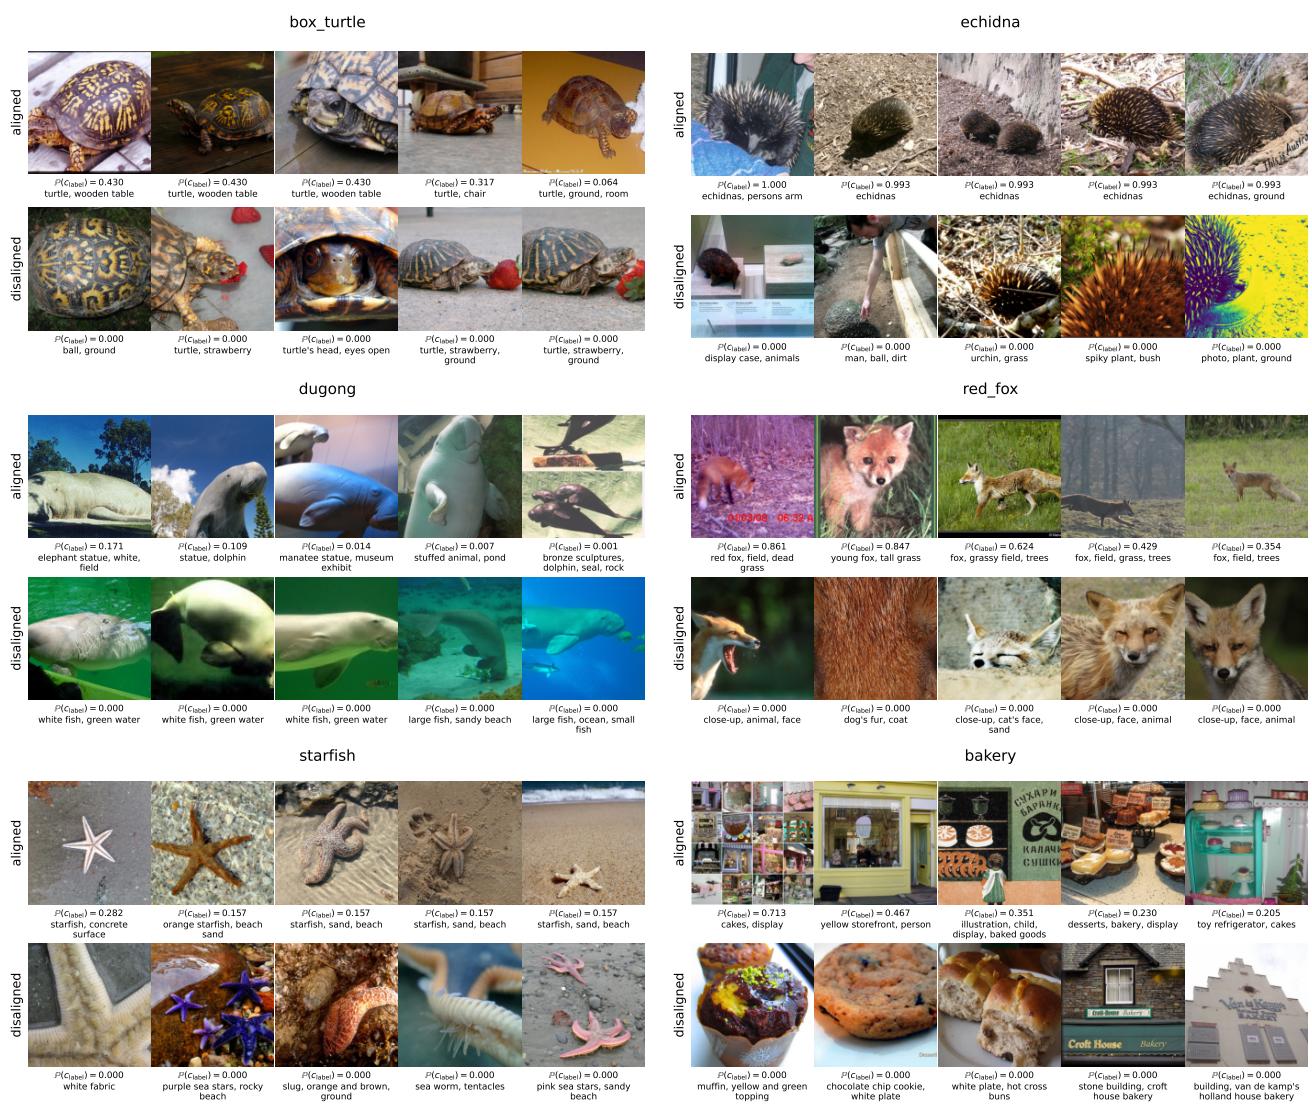
Figureure 1 · : Setup of text-guided image-classification using TextTeacher: During Figure 1: Setup of text-guided image-classification using TextTeacher: During training, we use a frozen text encoder on image captions to inject with semantic knowledge into an image classifier. At inference time, we deploy a standard, unimodal vision model.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 TextTeacher 的方法或实验,请结合正文精读段落一起看。Figureure 10 · : Most aligned and disaligned images for 6 random classes using ViT-B Figure 10: Most aligned and disaligned images for 6 random classes using ViT-B trained with TextTeacher for 300 epochs. An aligned image is one where the text captions will output a large signal for a specific class. A disaligned image is an image of a class where the text caption produces a low signal for that class.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 TextTeacher 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:冻结文本编码器可以作为训练期语义锚点,推理时仍保留纯视觉模型。
方法拆解
frozen text encoder semantic anchors for image representation training