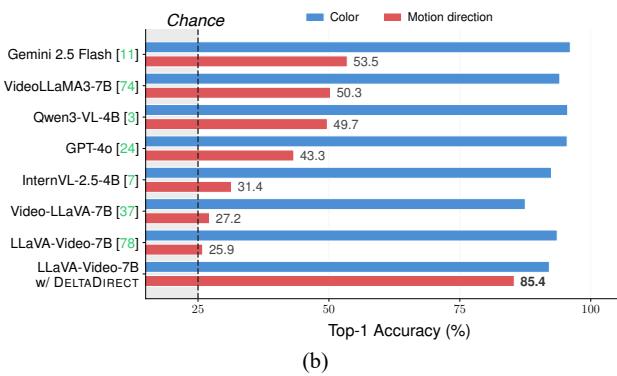
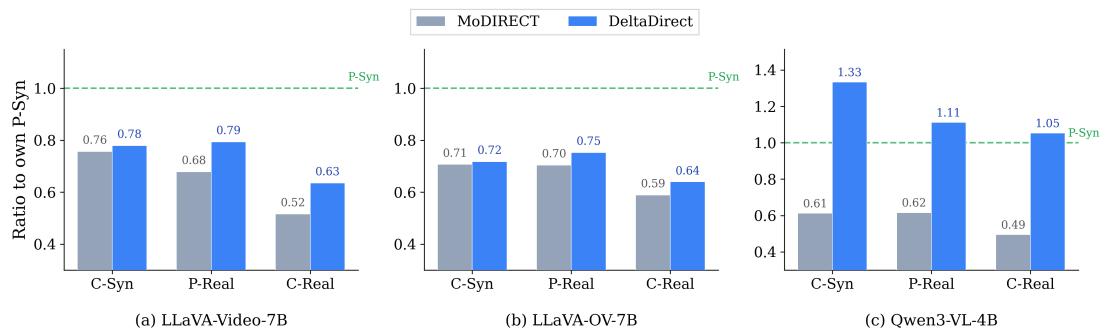
Figureure 1 · : Directional motion blindness in Video-LLMsFigure 1: Directional motion blindness in Video-LLMs. (a) Given a simple synthetic video of a yellow circle moving from left to right, recent Video-LLMs correctly identify the object’s color but answer the wrong motion direction. (b) Across Video-LLMs, appearance recognition is high, yet signed motion direction accuracy remains much lower, often near chance.这张图/表用于判断 DeltaDirect 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 11 · : DeltaDirect restores the OOD motion direction concept vector magnituFigure 11: DeltaDirect restores the OOD motion direction concept vector magnitude across video-LLM backbones. For each backbone, we plot the direction concept vector magnitude on each OOD domain (Cutout-on-Syn, Primitive-on-Real, Cutout-on-Real) as a ratio to the same model’s source-domain Primitive-on-Syn magnitude. The green dashed line marks the Primitive-on-Syn reference at 1.0. The MODIRECT-INST baseline (gray) shows a clear magnitude deficit on every backbone, while DeltaDirect (blue) consistently narrows the gap. Qwen3-VL-4B exhibits the largest recovery, where DeltaDirect pushes every OOD ratio above the Primitive-on-Syn reference.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 DeltaDirect 的方法或实验,请结合正文精读段落一起看。