先说结论。它和通用视觉自监督的关系在于:分析 DINO ViT 的 dense degradation,并用选择性 token mixing 提升密集预测。 中高相关;详见方法、贡献和实验边界。
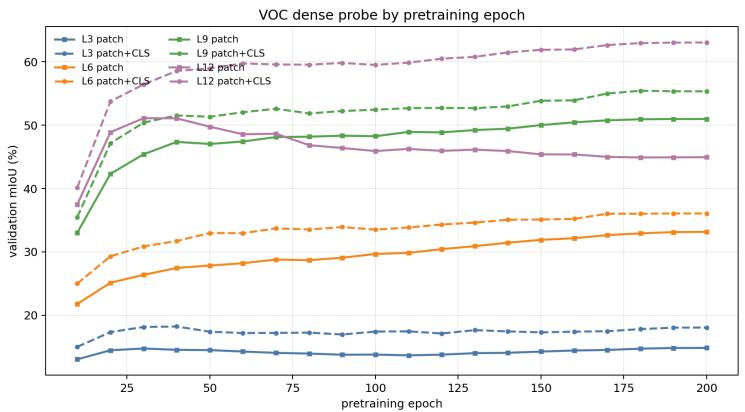
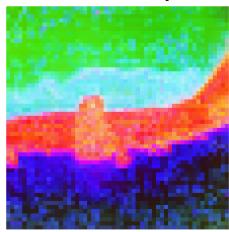
(b) VOC dense-probe mIoU across pretraining epochs and feature layers(b) VOC dense-probe mIoU across pretraining epochs and feature layers. Figure 2: Relationship between CLS spatial grounding and dense prediction quality across training. Left: PiB heatmap showing how well CLS-aligned patches remain localized within foreground regions. Right: VOC dense probing performance across layers and epochs.这张图/表用于判断 Vision Transformers Need Better Token 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Entmax All-Layer Figure 1: Visualization of the impact of our proposed sparse attention, cEntmax All-Layer Figure 1: Visualization of the impact of our proposed sparse attention, compared with other baselines. We display the first PCA components of model outputs in RGB.这张可视化用来解释 Vision Transformers Need Better Token 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。
核心问题
它和通用视觉自监督的关系在于:分析 DINO ViT 的 dense degradation,并用选择性 token mixing 提升密集预测。
方法拆解
分析 DINO ViT 的 dense degradation,并用选择性 token mixing 提升密集预测