编号2605.24807优先级P3类别Visual SSL / representation会议arXiv方法CLIP 语义注入 SAM encoder,偏下游分割但有低标注视觉表征价值来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:CLIP 语义注入 SAM encoder,偏下游分割但有低标注视觉表征价值。 中相关;详见方法、贡献和实验边界。
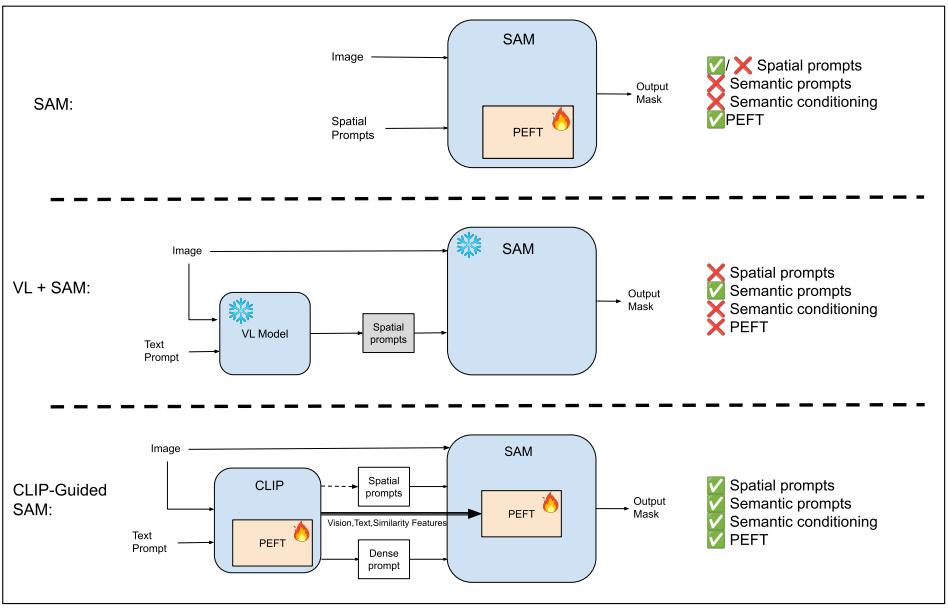
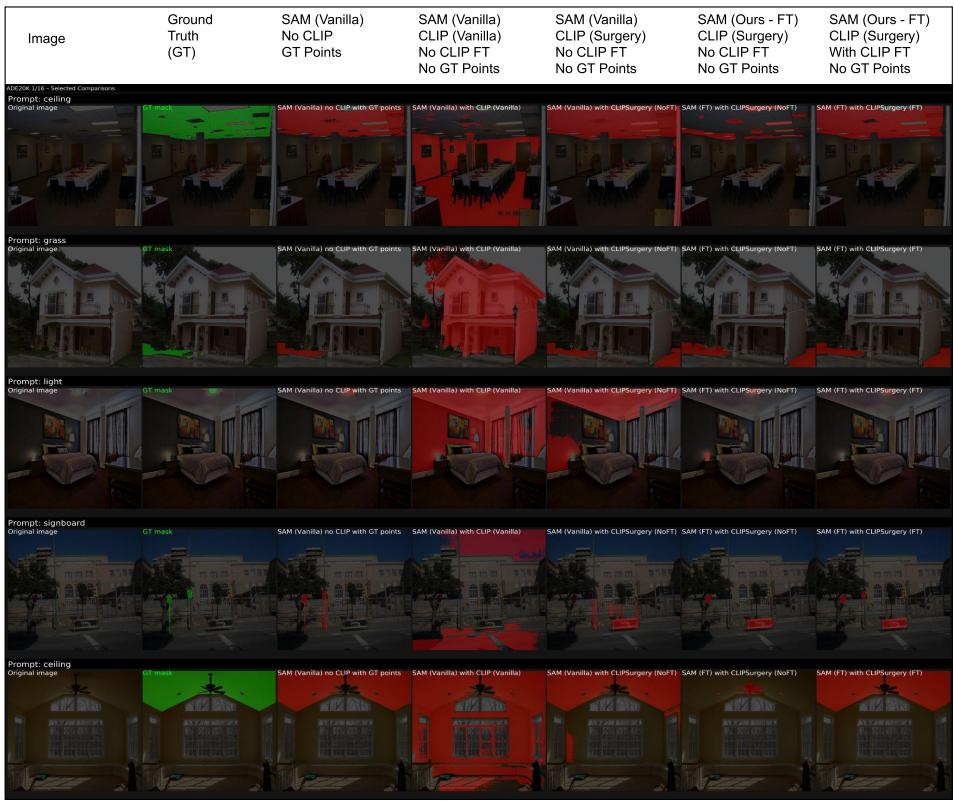
Figureure 1 · : CLIP-Guided SAM OverviewFig. 1: CLIP-Guided SAM Overview. Comparison of (top) SAM with PEFT, (middle) typical VLM+SAM pipelines, and (bottom) our CLIP-Guided SAM. Existing approaches either rely on spatial prompting alone or couple a VLM to SAM externally via prompt generation, leaving SAM’s internal representations semantically uninformed. Our approach introduces internal semantic conditioning by injecting CLIP-derived features directly into SAM’s image encoder through multi-modal adapters, enabling joint SAM–CLIP co-adaptation.这张图概括 CLIP-Guided SAM 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 5 · : Qualitative analysis on ADE20K (1/16 split)Fig. 5: Qualitative analysis on ADE20K (1/16 split). Comparison of vanilla SAM, CLIP-based prompting variants, and our CLIP-Guided SAM before and after fine-tuning.这张图/表用于判断 CLIP-Guided SAM 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:CLIP 语义注入 SAM encoder,偏下游分割但有低标注视觉表征价值。