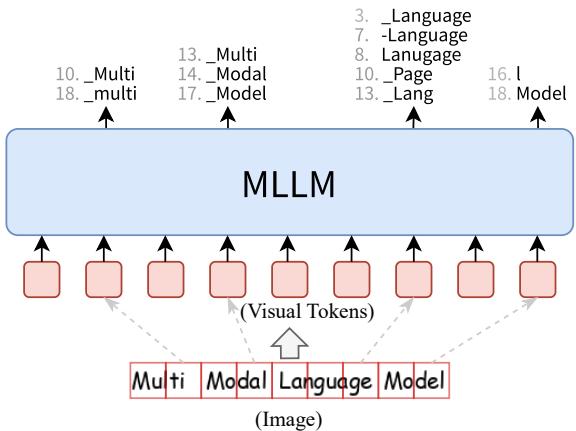
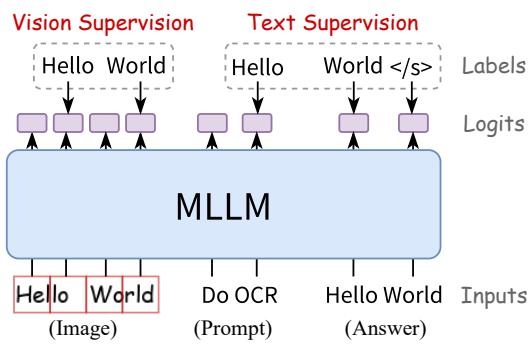
Figureure 1 · : An example of visual logits in Qwen3-VL-2B showing the top-20 tokensFigure 1: An example of visual logits in Qwen3-VL-2B showing the top-20 tokens at the final image patch of each word. Numbers indicate rank; punctuation and meaningless characters are removed. This observation inspires us to supervise visual tokens using the words in the image patches.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 DV-SFT 的方法或实验,请结合正文精读段落一起看。Figureure 2 · : Diagram of DV-SFTFigure 2: Diagram of DV-SFT. The training procedure of DV-SFT is identical to that of standard SFT, where all tokens are trained end-to-end on the next-token prediction task. The difference lies in the fact that a significant portion of visual tokens have valid labels.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 DV-SFT 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:把监督直接打到 visual tokens 上,解决 MLLM 中视觉 token 只被文本 loss 间接优化的问题。
方法拆解
把监督直接打到 visual tokens 上,解决 MLLM 中视觉 token 只被文本 loss 间接优化的问题