通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-05-28 图像表征 · VFM · JEPA · 视频预训练
Visual SSL / representation · 扫读 · 2026-05-28

Pop-Up Distractions Reveal Bag-of-Events Behavior:它和通用视觉自监督的关系在于:VideoLLM temporal grounding 诊断:模型可能把视频当事件袋而非时序结构

中相关;详见方法、贡献和实验边界。

编号2605.27101 优先级扫读 类别Visual SSL / representation 会议arXiv 方法VideoLLM temporal grounding 诊断:模型可能把视频当事件袋而非时序结构 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:VideoLLM temporal grounding 诊断:模型可能把视频当事件袋而非时序结构。 中相关;详见方法、贡献和实验边界。

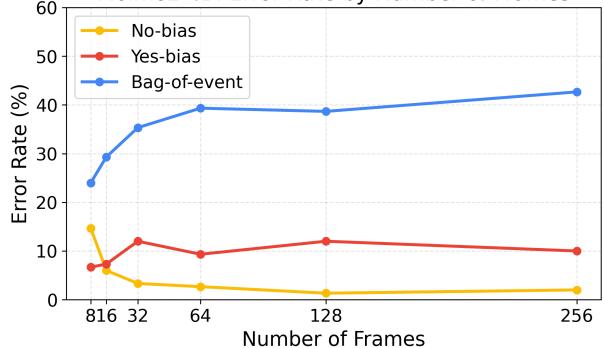
Molmo2 4B: Error Rate by Number of Frames Figure 10: Molmo2-4B: Error rates by number of f
Molmo2 4B: Error Rate by Number of Frames Figure 10: Molmo2-4B: Error rates by number of fMolmo2 4B: Error Rate by Number of Frames Figure 10: Molmo2-4B: Error rates by number of frames.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Pop-Up Distractions Reveal Bag-of-Events Behavior 的方法或实验,请结合正文精读段落一起看。
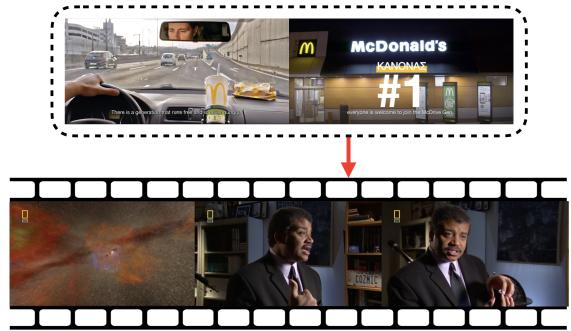
Q: Is Neil deGrasse Tyson having McDonald's in this video? Video LLM: Yes Figure 1: VideoL
Q: Is Neil deGrasse Tyson having McDonald's in this video? Video LLM: Yes Figure 1: VideoLQ: Is Neil deGrasse Tyson having McDonald's in this video? Video LLM: Yes Figure 1: VideoLLMs conflate the injected advertisement (top) with the main video content (bottom), hallucinating that Neil deGrasse Tyson is eating McDonald’s despite no frame showing him eating anything.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Pop-Up Distractions Reveal Bag-of-Events Behavior 的方法或实验,请结合正文精读段落一起看。

核心问题

它和通用视觉自监督的关系在于:VideoLLM temporal grounding 诊断:模型可能把视频当事件袋而非时序结构。

方法拆解

VideoLLM temporal grounding 诊断:模型可能把视频当事件袋而非时序结构

主要贡献

中相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。