通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-05-28 图像表征 · VFM · JEPA · 视频预训练
Visual SSL / representation · P2 · 2026-05-28

How and What to Imagine?:它和通用视觉自监督的关系在于:研究统一多模态模型是否真正使用生成的中间视觉思考图

中相关;详见方法、贡献和实验边界。

编号2605.27310 优先级P2 类别Visual SSL / representation 会议arXiv 方法研究统一多模态模型是否真正使用生成的中间视觉思考图 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:研究统一多模态模型是否真正使用生成的中间视觉思考图。

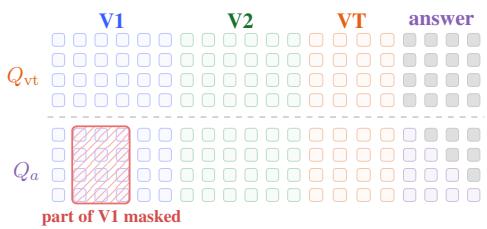
Figureure 2 · : VDrop attention mask
Figureure 2 · : VDrop attention maskFigure 2: VDrop attention mask. Answer queries $Q _ { a }$ cannot attend to the masked region (red hatched), while thinking-image queries $Q _ { \mathrm { v t } }$ retain full access to all.这张可视化用来解释 How and What to Imagine? 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。
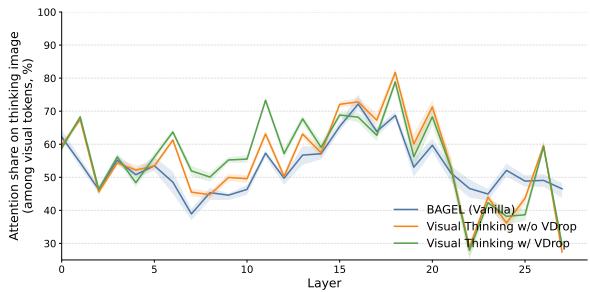
Figureure 6 · : Mean answer-token attention on thinkingimage tokens across decoder l
Figureure 6 · : Mean answer-token attention on thinkingimage tokens across decoder lFigure 6: Mean answer-token attention on thinkingimage tokens across decoder layers (STARE). The VDrop-trained model places more attention on the generated thinking-image than the standard SFT model, especially in early and mid layers, indicating that VDrop shifts the answer pathway toward the thinking-image.这张可视化用来解释 How and What to Imagine? 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。
核心问题

它和通用视觉自监督的关系在于:研究统一多模态模型是否真正使用生成的中间视觉思考图。

方法拆解

研究统一多模态模型是否真正使用生成的中间视觉思考图

主要贡献

中相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。