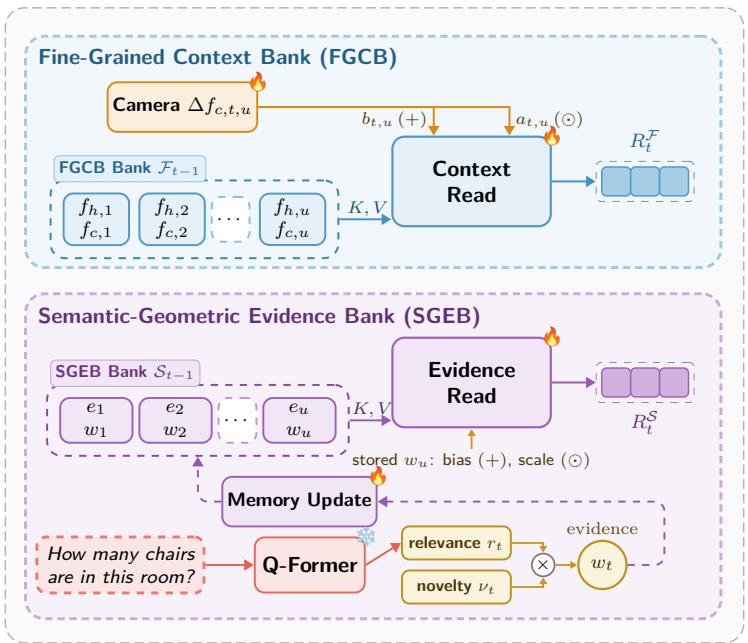
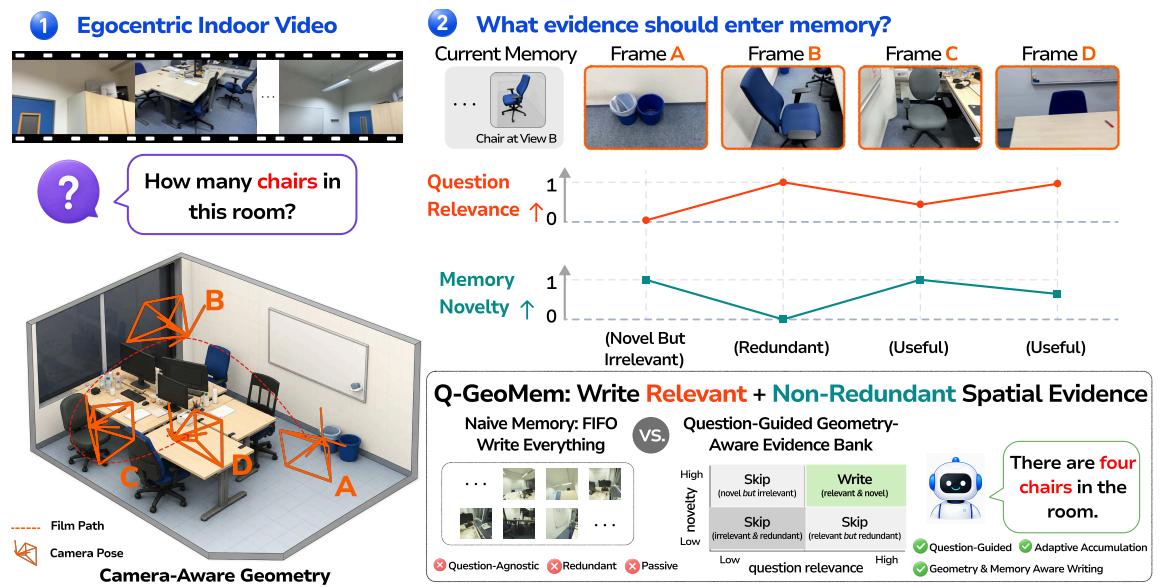
(b) Question-Guided Geometric Memory Figure 2: Overview of the proposed framework(b) Question-Guided Geometric Memory Figure 2: Overview of the proposed framework. Camera-guided geometry fusion first injects spatial cues into frame tokens. The Fine-Grained Context Bank preserves recent detailed visual evidence, while the Semantic-Geometric Evidence Bank stores compact pooled fused features. Question-conditioned write scores are computed by considering both the current question and the existing evidence bank, enabling memory-aware evidence reading and writing.这张图概括 Q-GeoMem 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Motivation of Q-GeoMemFigure 1: Motivation of Q-GeoMem. Egocentric indoor videos reveal spatial layout through partial, camera-dependent views, so long-horizon spatial reasoning depends on retaining the right evidence rather than simply storing more frames. For a question such as “How many chairs are in this room?”, FIFO-style memory may mix useful chair observations with irrelevant or repeated views. Q-GeoMem instead treats memory update as question-guided geometric evidence management: camera-conditioned geometry grounds frame features, question relevance identifies task-useful observations, and novelty discourages redundant long-range evidence.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Q-GeoMem 的方法或实验,请结合正文精读段落一起看。