AdaMerge:它和通用视觉自监督的关系在于:训练-free ViT token merging,把 token 重要性和层级冗余纳入合并决策
中高相关;详见方法、贡献和实验边界。
AdaMerge: Salience-Aware Adaptive Token Merging for Training-Free Acceleration of Vision Transformers arXiv cross-list 原文链接
编号2605.27465优先级P1类别arXiv cross-list会议arXiv cross-list方法训练-free ViT token merging,把 token 重要性和层级冗余纳入合并决策来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:训练-free ViT token merging,把 token 重要性和层级冗余纳入合并决策。 中高相关;详见方法、贡献和实验边界。
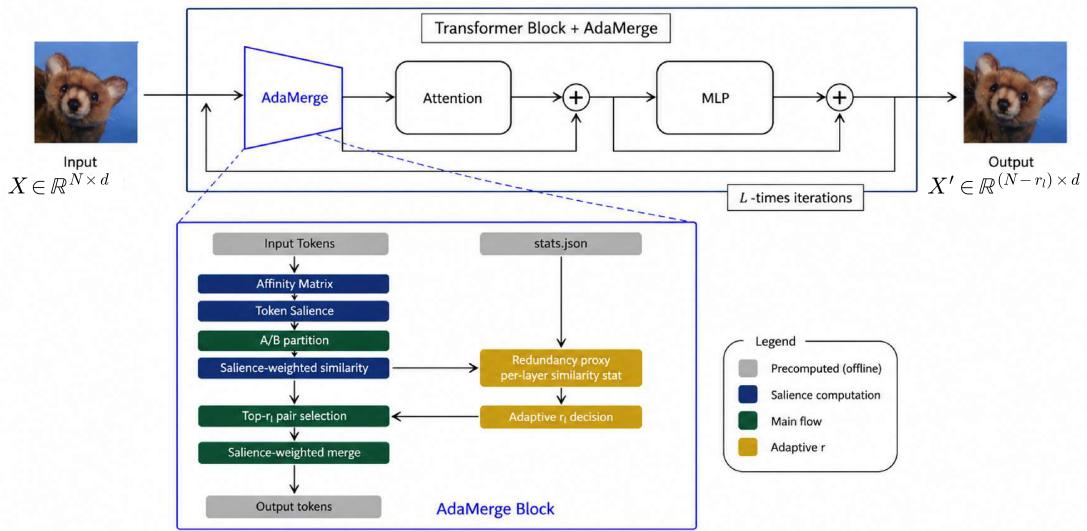
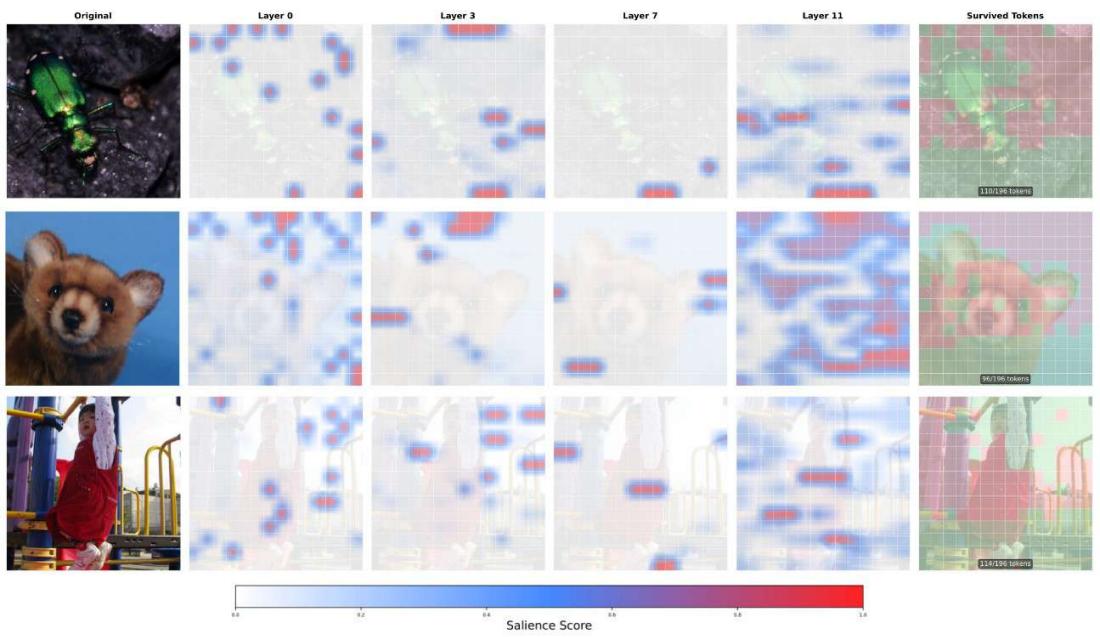
Figureure 2 · : Top: ADAMERGE is integrated before each Transformer block to reduce Figure 2: Top: ADAMERGE is integrated before each Transformer block to reduce the sequence length from N to $N - r _ { l }$ prior to self-attention. Bottom: Internal pipeline. Salience computation and adaptive $r _ { l }$ decision run in parallel, followed by salience-proportional aggregation. Layer-wise statistics $( \mu _ { l } , \sigma _ { l } )$ are precomputed offline and loaded from stats.json.这张图概括 AdaMerge 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Layer-wise salience maps and survived tokens from $\mathrm { A D A MFigure 1: Layer-wise salience maps and survived tokens from $\mathrm { A D A M E R G E } ( r _ { \mathrm { m a x } } { = } 1 8 )$ on three ImageNet-1k images. Warmer colors indicate higher salience (column-wise sum of the rownormalized affinity matrix). Salience consistently localizes to discriminative regions and sharpens with depth, corroborating the token-importance non-uniformity motivating our design. In the rightmost column, green denotes survived tokens and red denotes merged tokens; object-centric patches are preferentially preserved. Crucially, the varying proportion of merged tokens across different images demonstrates how ADAMERGE content-adaptively allocates its merging budget to preserve semantic integrity.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 AdaMerge 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:训练-free ViT token merging,把 token 重要性和层级冗余纳入合并决策。