先说结论。它和通用视觉自监督的关系在于:object-centric evidence routing,把局部 grounding 证据压入可复用 visual working space。 中相关;详见方法、贡献和实验边界。
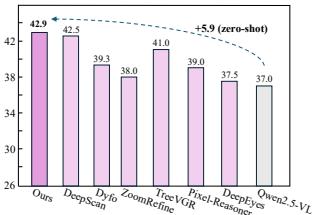
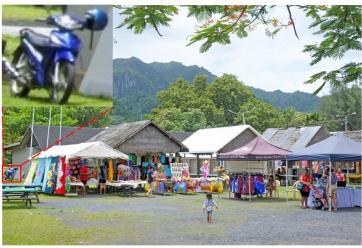
(c) Zero-shot Transfer on TreeBench Figure 4: Backbone compatibility and transferability(c) Zero-shot Transfer on TreeBench Figure 4: Backbone compatibility and transferability. (a): Backbone compatibility. VideoEspresso (Avg.) evaluated via similarity matching and MM-GCoT (A-Acc./G-Acc./Consist.). (b): Zero-shot transfer of ROVER-enhanced Qwen2.5-VL-7B to held-out benchmarks. (c): Comparison with state-of-the-art alternatives on TreeBench [56], with scores taken from DeepScan [33].这张图/表用于判断 ROVER 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 9 · : Transfer example on Mantis after training on VideoEspressoFigure 9: Transfer example on Mantis after training on VideoEspresso. Model-predicted multiimage reasoning that integrates cues from multiple objects and images to support the final answer.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 ROVER 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:object-centric evidence routing,把局部 grounding 证据压入可复用 visual working space。
方法拆解
object-centric evidence routing,把局部 grounding 证据压入可复用 visual working space