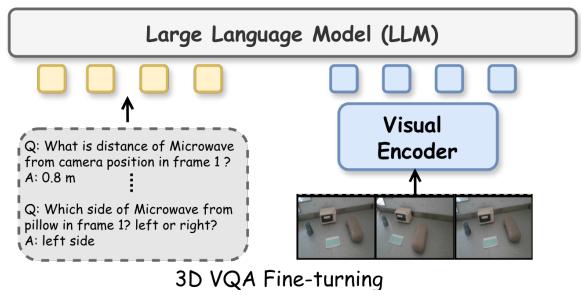
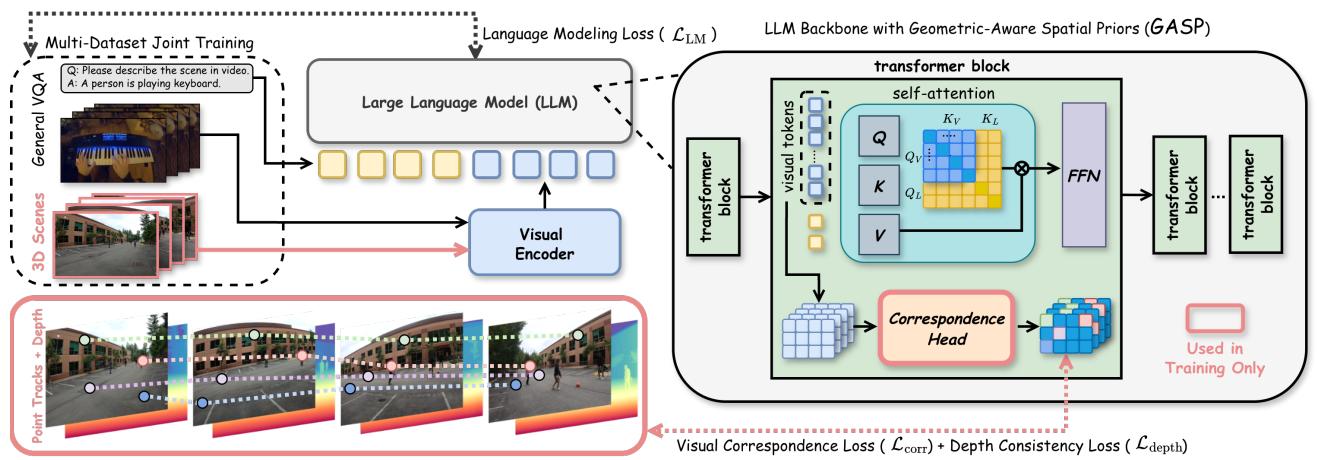
Figureure 1 · Top: Our proposed framework (GASP) learns geometric consistency by injFigure 1 Top: Our proposed framework (GASP) learns geometric consistency by injecting the correspondence head into the LLM, supervised by 3D spatial priors. Bottom: Standard spatial VLMs rely on fine-tuning with 3D VQA datasets, which often leads to memorizing data-specific biases. Note that our GASP requires no 3D prior input and processes as a standard VLM during inference.这张图概括 Beyond 3D VQAs 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · Injecting the Geometric-Aware Spatial Priors (GASP) into VLMsFigure 2 Injecting the Geometric-Aware Spatial Priors (GASP) into VLMs. Standard approaches rely on fine-tuning with 3D VQA datasets, which may encourage memorizing dataset-specific biases. We instead insert a small correspondence head into the intermediate layers of the LLM backbone. During the training phase, this head is supervised by visual correspondence and depth consistency signals derived from ground-truth point tracks and depth maps. At inference, the head is discarded and the model processes inputs (e.g., VQA) as a standard VLM, without any auxiliary 3D input. Note that the 3D scene example shown is from EgoHumans [24] for illustration; our training data is sourced from DL3DV [30].这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Beyond 3D VQAs 的方法或实验,请结合正文精读段落一起看。