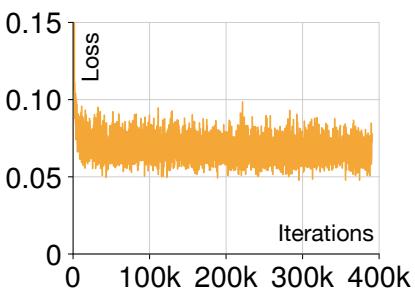
Figureure 10 · : Pretraining loss for the JiT-T2I reference baseline [34] on GPIC-FulFigure 10: Pretraining loss for the JiT-T2I reference baseline [34] on GPIC-Full. We show training loss vs. iterations. The model is trained for one epoch on GPIC-Full (100M text-image pairs).这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 GPIC 的方法或实验,请结合正文精读段落一起看。Figureure 3 · : Our dataset construction pipelineFigure 3: Our dataset construction pipeline. We develop a four-stage pipeline to create GPIC. We source permissive images from Flickr and Wikimedia (Stage 1), filter low-quality and harmful images (Stage 2), deduplicate images using similarity scores derived from SSCD [23] copy detection features (Stage 3), and caption into one of tag, short, medium, or long (Stage 4). Qwen-3-VL-4B-Instruct [19] is used for filtering and captioning.这张图概括 GPIC 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。