YoCausal:它和通用视觉自监督的关系在于:用真实视频反转构造 causal counterfactual benchmark,适合评估视频 world model 是否学到动态因果
中相关;详见方法、贡献和实验边界。
YoCausal: How Far is Video Generation from World Model? A Causality Perspective arXiv 原文链接
编号2605.30346优先级P3类别Visual SSL / representation会议arXiv方法用真实视频反转构造 causal counterfactual benchmark,适合评估视频 world model 是否学到动态因果来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:用真实视频反转构造 causal counterfactual benchmark,适合评估视频 world model 是否学到动态因果。 中相关;详见方法、贡献和实验边界。
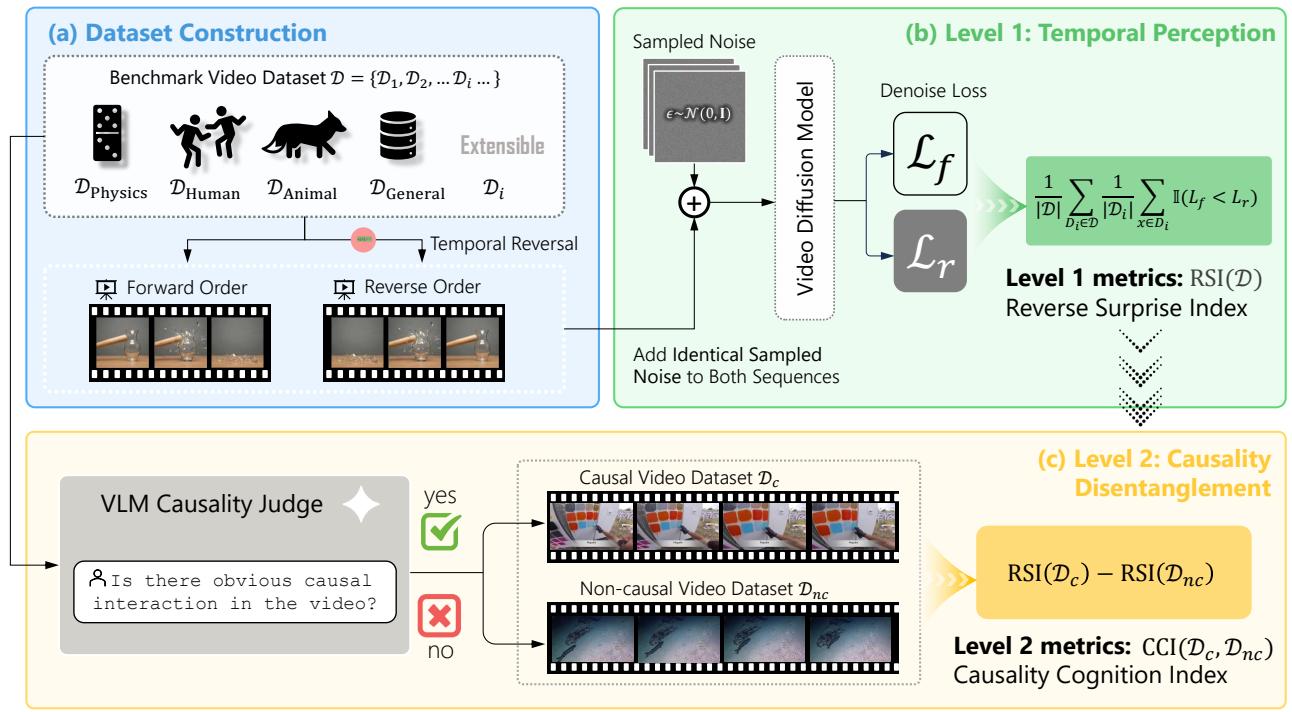
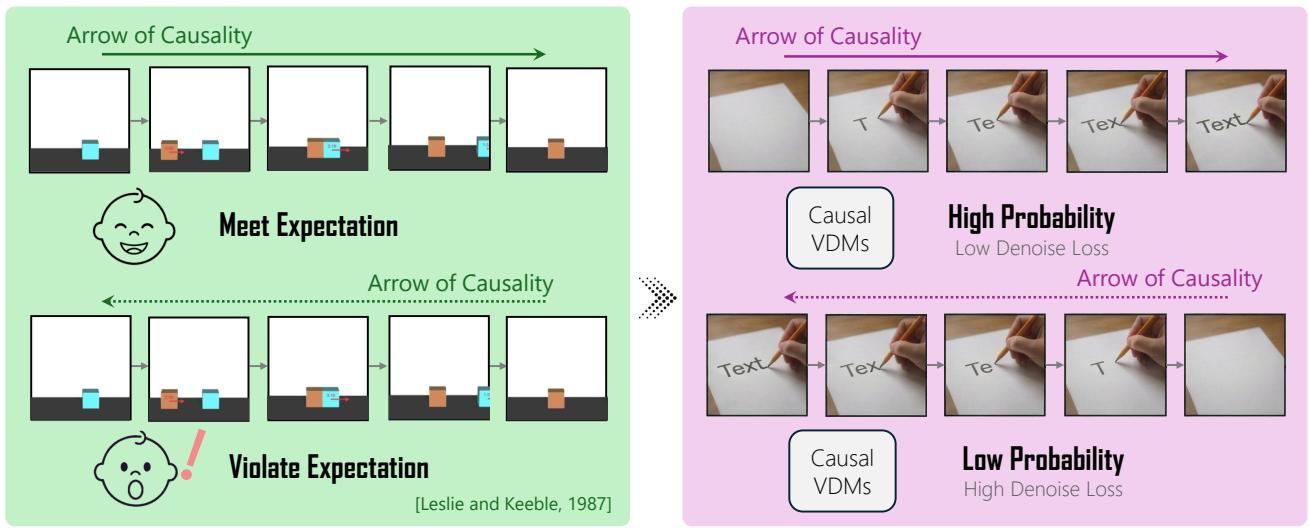
Figureure 3 · Overview of the YoCausal evaluation frameworkFigure 3 Overview of the YoCausal evaluation framework. (a) Dataset Construction: We construct an infinitely extensible benchmark by using real-world videos from different domains. By applying zero-cost temporal reversal, we generate natural counterfactual pairs (forward $x ^ { f }$ and reverse $x ^ { r } )$ . (b) Level 1 Temporal Perception: Identical sampled noise ϵ is added to both sequences and compute their denoising losses. Reverse Surprise Index (RSI), quantifies the model’s perception of the arrow of time by measuring the proportion of instances where the reversed video has a higher loss $( \mathcal { L } _ { r } > \mathcal { L } _ { f } )$ . (c) Level 2 Causality Disentanglement: To disentangle genuine causal cognition from statistical temporal biases, a Vision-Language Model (VLM) divides the dataset into causal $( \mathcal { D } _ { c } )$ and non-causal $( { \mathcal { D } } _ { n c } )$ subsets. The Level-2 metric, Causality Cognition Index (CCI), is computed as the difference in RSI between these subsets, isolating the model’s genuine causal cognition ability.这张图概括 YoCausal 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · Conceptual overview of YoCausal benchmarkFigure 2 Conceptual overview of YoCausal benchmark. We draw inspiration from the Violation of Expectation (VoE) paradigm in cognitive science. (Left) Infants show surprise when seeing videos played in reverse (bottom), violating their intuitive causal cognition [65] (99K). (Right) We transfer this paradigm to generative models: treating the learned data distribution as the model’s cognition, a causally-aware VDM should assign lower probability (higher denoising loss) to counterfactual reversed videos than to forward ones. This elegant analogy allows us to benchmark causal understanding using arbitrarily scalable real-world videos.这张图概括 YoCausal 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:用真实视频反转构造 causal counterfactual benchmark,适合评估视频 world model 是否学到动态因果。
方法拆解
用真实视频反转构造 causal counterfactual benchmark,适合评估视频 world model 是否学到动态因果