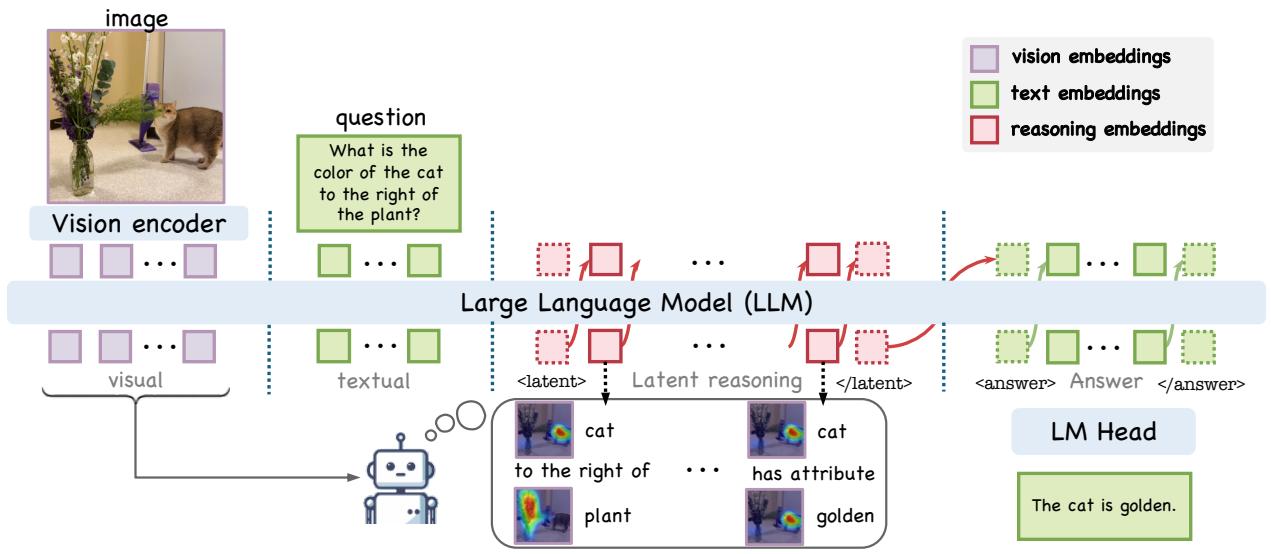
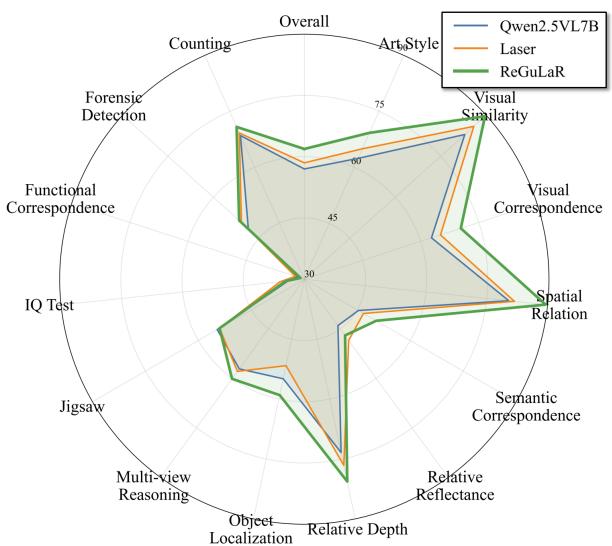
Figureure 2 · : Overview of ReGuLaRFigure 2: Overview of ReGuLaR. ReGuLaR follows a thinking-then-answering process, where latent-space reasoning precedes final answer generation. At each latent reasoning step, the model focuses on one questionrelevant object pair and their relation, or on one object and its attribute. A training-time ReGFormer (Section 3.2) grounds each reasoning state in these critical visual structures, and is not required during inference.这张图概括 ReGuLaR 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 4 · : Performance comparison across 14 diverse tasks of the BLINK benchmarFigure 4: Performance comparison across 14 diverse tasks of the BLINK benchmark.这张图/表用于判断 ReGuLaR 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。