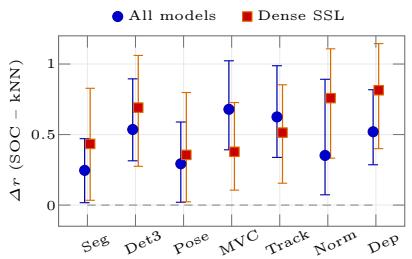
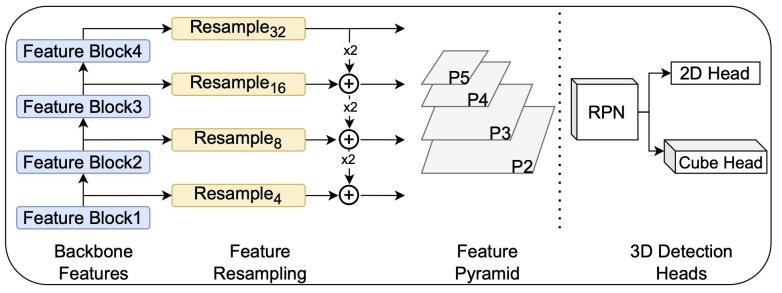
Figureure 4 · : Per-task Pearson r across 37 vision models, with 95% bootstrap CIsFig. 4: Per-task Pearson r across 37 vision models, with 95% bootstrap CIs. Left: SOC correlates with every downstream task more strongly than ImageNet kNN. Right: the SOC advantage $\varDelta r = r _ { \mathrm { S O C } } - r _ { \mathrm { k } }$ NN stays positive on all tasks and is preserved on a 17 subset only including models trained with dense SSL objectives.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 SOCO 的方法或实验,请结合正文精读段落一起看。FigFig. r5: Overview of the detection probe. The probe receives four intermediate feature maps from a pretrained frozen backbone, merges and upsamples them to produce a Detectron2-style feature pyramid $\{ p _ { 2 } , p _ { 3 } , p _ { 4 } , p _ { 5 } \}$ used by the 3D detection head.这张图概括 SOCO 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。