先说结论。它和通用视觉自监督的关系在于:把 VLM 蒸馏梯度拆成 language prior 与 visual grounding,直接处理视觉证据被语言先验淹没的问题。 高相关;详见方法、贡献和实验边界。
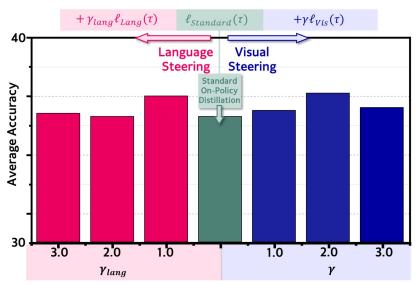
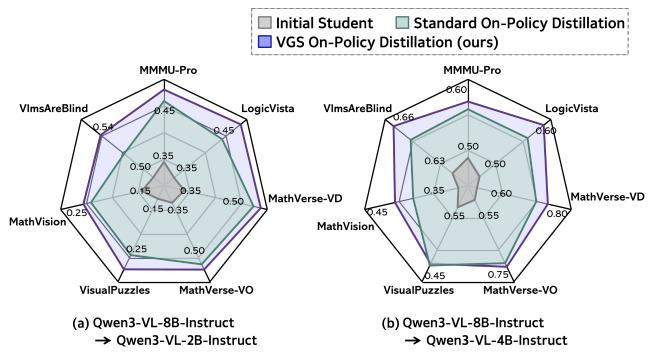
(c) Text-only Benchmark Figure 10(c) Text-only Benchmark Figure 10. Impact of optimization steering across varying levels of visual dependency. Average accuracy comparison between Language Steering, Standard On-Policy Distillation, and Visual Gradient Steering. (a) On High-Visual Dependent benchmarks, prioritizing the visual subspace (VGS) significantly outperforms the baseline, whereas leaning on the language prior actively degrades performance. (b) On Low-Visual Dependent and (c) pure Text-Only benchmarks, performance remains uniform across all methods, confirming that VGS yields gains where visual grounding is the primary bottleneck without compromising the model’s core textual reasoning capabilities.这张图/表用于判断 Decomposed On-Policy Distillation for Vision-Language 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 1 · Visual Gradient Steering (VGS) outperforms standard monolithic distillFigure 1. Visual Gradient Steering (VGS) outperforms standard monolithic distillation. We compare the reasoning performance of student models distilled from a 8B teacher. VGS (purple) consistently surpasses the standard baseline (green) across diverse multimodal benchmarks for both (a) 2B and (b) 4B students, demonstrating superior visual grounding.这张图/表用于判断 Decomposed On-Policy Distillation for Vision-Language 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:把 VLM 蒸馏梯度拆成 language prior 与 visual grounding,直接处理视觉证据被语言先验淹没的问题。
方法拆解
把 VLM 蒸馏梯度拆成 language prior 与 visual grounding,直接处理视觉证据被语言先验淹没的问题