Cosmos 3:它和通用视觉自监督的关系在于:大规模 omnimodal world model 同时处理语言、图像、视频、音频和 action,是通用视频/世界模型预训练的重要系统信号
中高相关;详见方法、贡献和实验边界。
Cosmos 3: Omnimodal World Models for Physical AI arXiv + project/code 原文链接
编号2606.02800优先级P2类别project/code会议arXiv + project/code方法大规模 omnimodal world model 同时处理语言、图像、视频、音频和 action,是通用视频/世界模型预训练的重要系统信号来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:大规模 omnimodal world model 同时处理语言、图像、视频、音频和 action,是通用视频/世界模型预训练的重要系统信号。 中高相关;详见方法、贡献和实验边界。
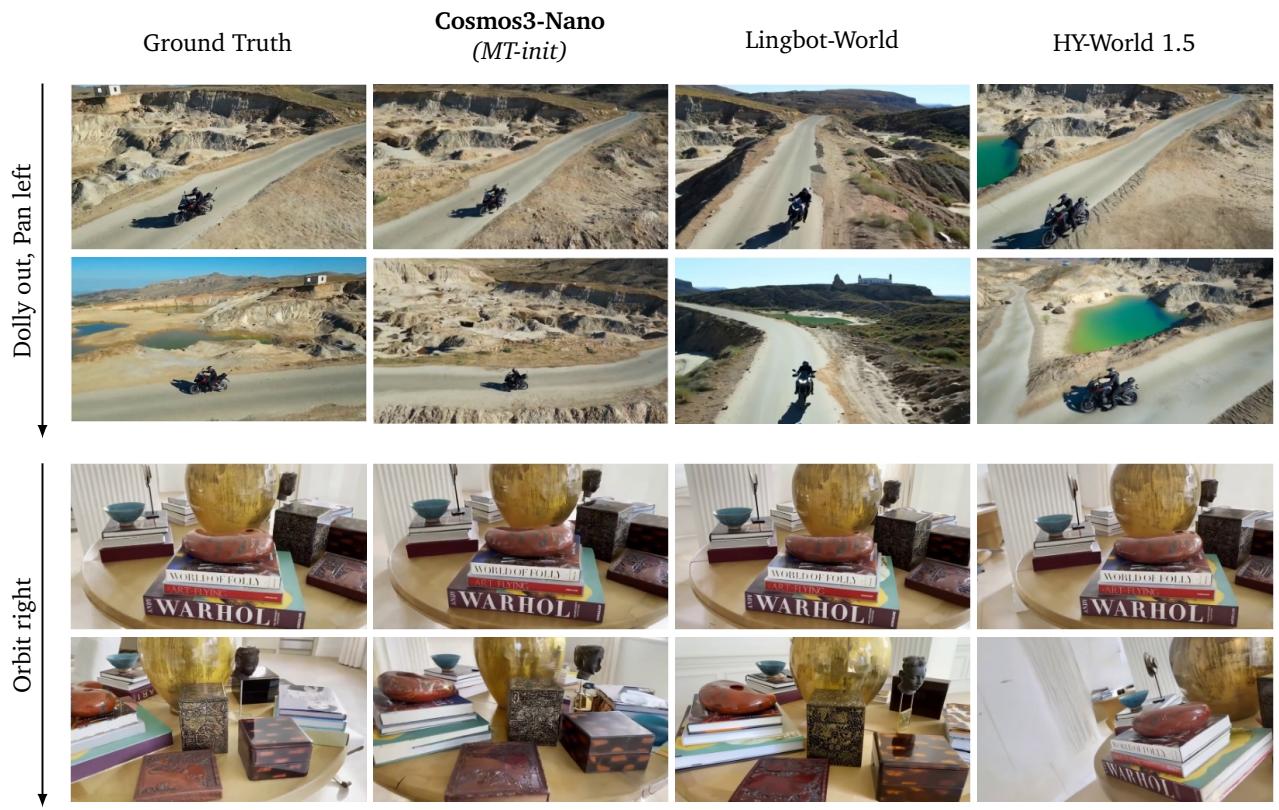
Figureure 1 · : Cosmos 3 serves as a general-purpose backbone for Physical AIFigure 1: Cosmos 3 serves as a general-purpose backbone for Physical AI. By jointly modeling language, image, video, audio, and action for both understanding and generation, Cosmos 3 unifies a wide range of model classes within a single network architecture, including vision-language models, image generation models, audio-visual generation models, policy or world-action models, forward dynamics models, and inverse dynamics models.这张图概括 Cosmos 3 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 23 · : Camera forward dynamics comparisonFigure 23: Camera forward dynamics comparison. Given complex realistic trajectories, Cosmos3-Nano (MT-init) faithfully reproduces the same camera motion in the generated video. For each motion example, the first row shows frames near the start of the sequence and the second row shows frames near the end. The downward arrow indicates temporal progression from start to finish, while the text beside it specifies the commanded camera motion.这张图/表用于判断 Cosmos 3 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:大规模 omnimodal world model 同时处理语言、图像、视频、音频和 action,是通用视频/世界模型预训练的重要系统信号。
方法拆解
大规模 omnimodal world model 同时处理语言、图像、视频、音频和 action,是通用视频/世界模型预训练的重要系统信号