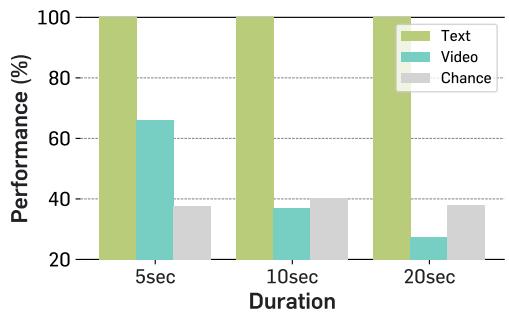
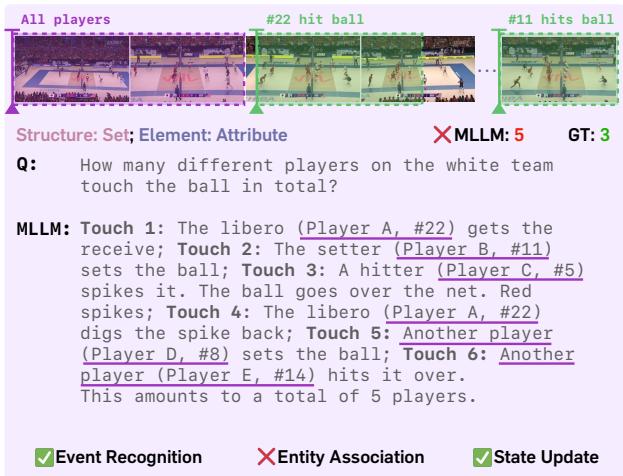
(a) Example task and its text transcription(a) Example task and its text transcription. (b) Performance across video durations. Figure 2 | Analyzing bottlenecks of MLLMs in visual state tracking. (a) An example Blender task (rolling die) with its video frames and text transcription. (b) Performance across video durations on the selected task subset. Recent MLLMs, such as Gemini-3.1 Pro [23], solve the task perfectly with text conditions, but their video performance drops to near chance and degrades further as videos grow longer.这张图/表用于判断 Benchmarking Visual State Tracking in 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 3 · | Failures in event identificationFigure 3 | Failures in event identification. We highlight phrases and frames related to state extraction in purple and failures in visual perception in green. For better illustration, we subsampled video frames related to the failures and simplified the thinking traces.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Benchmarking Visual State Tracking in 的方法或实验,请结合正文精读段落一起看。