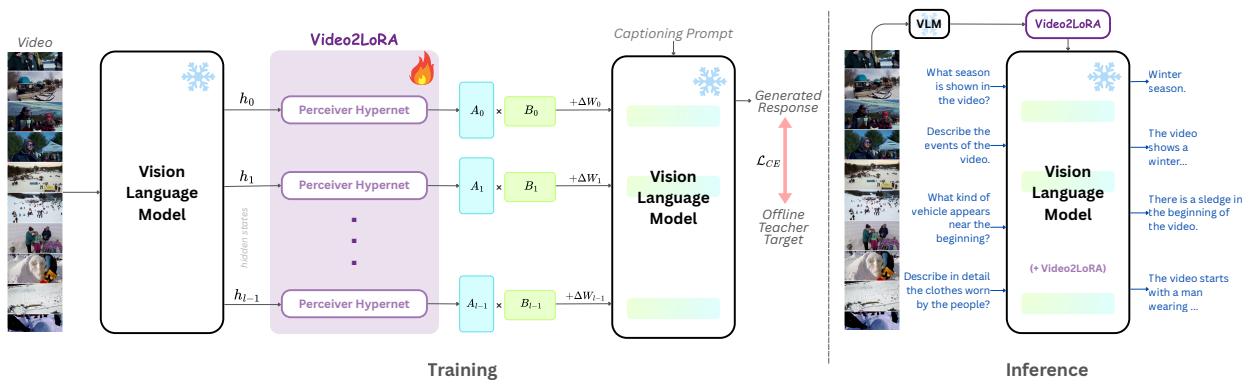
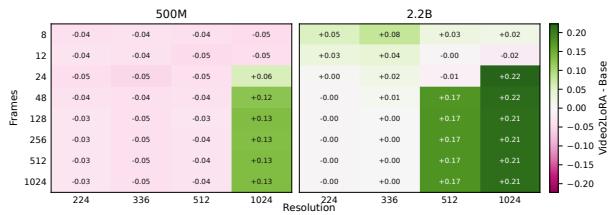
Figureure 1 · : VIDEO2LORA overviewFigure 1: VIDEO2LORA overview. Training (left): A frozen VLM encodes the input video into hidden states. The trainable VIDEO2LORA hypernetwork reads these states and generates LoRA adapter weights in a single forward pass. The adapter-augmented frozen VLM is trained against teacher-generated targets. Inference (right): Given a new video, VIDEO2LORA generates the LoRA adapter once. The frozen VLM, augmented with this adapter, answers arbitrary text queries without visual tokens. Per-query cost is independent of video length.这张图概括 Video2LoRA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Inference efficiency on VidCapBench, comparing the base model and VIFigure 2: Inference efficiency on VidCapBench, comparing the base model and VIDEO2LORA. (a) Change in mean Token-F1 from replacing in-context video tokens with VIDEO2LORA.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Video2LoRA 的方法或实验,请结合正文精读段落一起看。