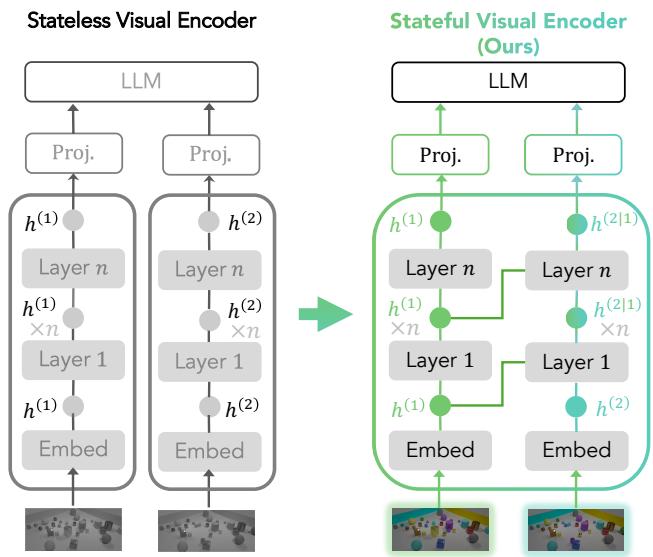
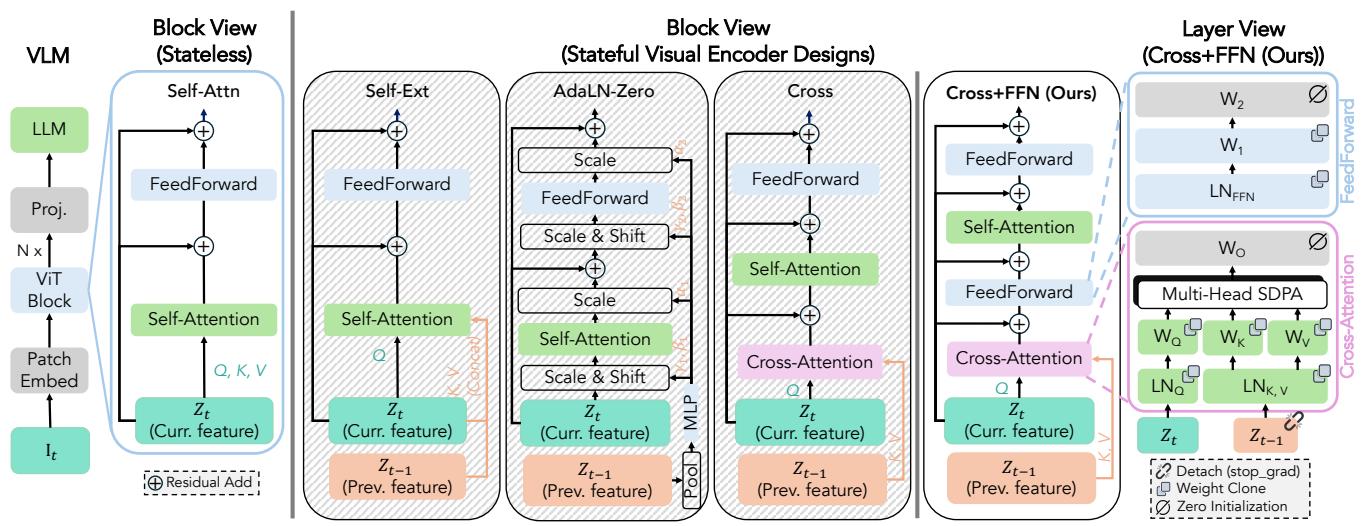
Figureure 1 · Stateful visual encoders condition each image’s visual representation Figure 1. Stateful visual encoders condition each image’s visual representation on features from the previous image within the vision backbone, enabling early cross-image comparison inside the visual encoder. The left-to-right direction ensures that the current image can attend only to past visual features, matching interactions where future observations may not yet be available.这张图/表用于判断 Stateful Visual Encoders for Vision-Language 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 2 · Design study and implementation recipe for SVEFigure 2. Design study and implementation recipe for SVE. We compare several ways to condition current visual tokens $Z _ { t }$ on past tokens $Z _ { t - 1 }$ . The layer view expands the winning Cross-Attn + FFN design and shows its implementation recipe: stop-gradient on the past feature pathway, cloned initialization from the same ViT block, and zero initialization. Activations and positional embeddings in the layer view are omitted for simplicity.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Stateful Visual Encoders for Vision-Language 的方法或实验,请结合正文精读段落一起看。