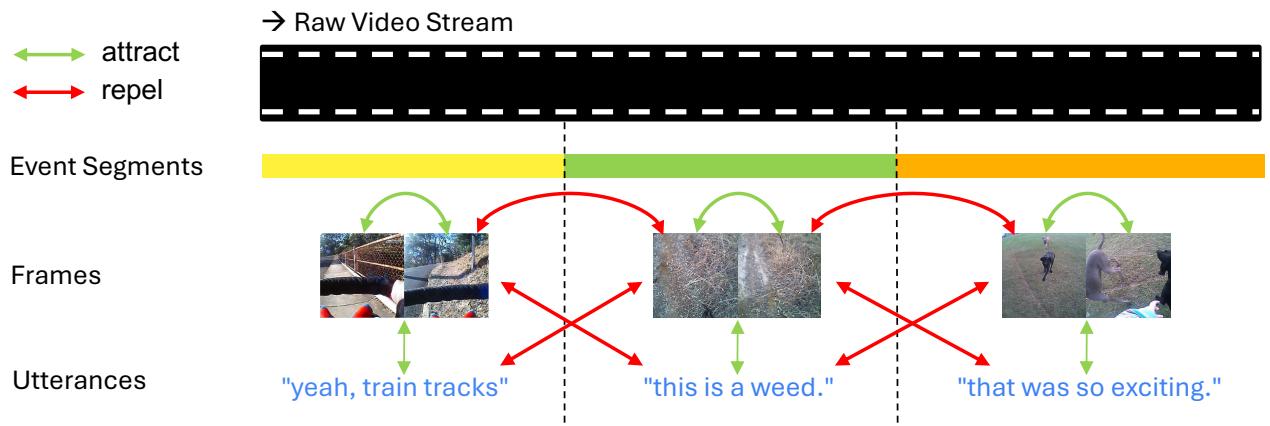
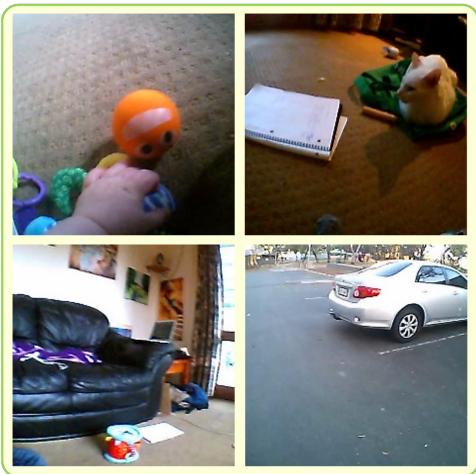
Figureure 1 · : Overview of BabyCLFigure 1: Overview of BabyCL. The incoming SAYCam stream is partitioned into event segments of roughly three minutes using hierarchical visual clustering, with boundaries adjusted to utterance timestamps. Embeddings of frames within the same event segment are brought together while those from different event segments are pushed apart $( { \mathcal { L } } _ { S } ) .$ . Matching pairs of utterances and frames are brought together while mismatching ones are pushed apart $( \mathcal { L } _ { C } )$ .这张图概括 Continual Visual and Verbal Learning 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Example of the 4AFC taskFigure 2: Example of the 4AFC task. Given a target category (“ball”) and three foil categories (“cat”, “couch”, and “car”), the model must select the image corresponding to the target category from four candidate images.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Continual Visual and Verbal Learning 的方法或实验,请结合正文精读段落一起看。