VideoKR:它和通用视觉自监督的关系在于:ICML Spotlight 的视频推理数据与评测工作;不是 SSL 目标,但对视频 foundation model 评估有参考
中相关;详见方法、贡献和实验边界。
VideoKR: Towards Knowledge- and Reasoning-Intensive Video Understanding arXiv + ICML 2026 Spotlight 原文链接
编号2606.05259优先级扫读类别ICML 2026 Spotlight会议arXiv + ICML 2026 Spotlight方法ICML Spotlight 的视频推理数据与评测工作;不是 SSL 目标,但对视频 foundation model 评估有参考来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:ICML Spotlight 的视频推理数据与评测工作;不是 SSL 目标,但对视频 foundation model 评估有参考。 中相关;详见方法、贡献和实验边界。
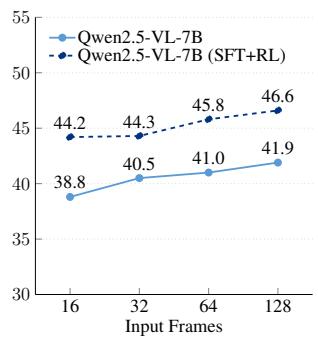
Figureure 6 · A VideoKR-SFT-201K example from the engineering domainFigure 6. A VideoKR-SFT-201K example from the engineering domain. The reasoning process is presented in a concise and abbreviated form to improve readability.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 VideoKR 的方法或实验,请结合正文精读段落一起看。(b) Knowledge-intensive Reasoning Figure 3(b) Knowledge-intensive Reasoning Figure 3. Inference-time frame scaling results on general and knowledge-intensive video reasoning benchmarks. The figure shows category-wise average accuracies for Qwen2.5-VL-7B-Instruct and its VideoKR post-trained variant (SFT+RL) under different input frame budgets. Appendix D.1 provides the full per-benchmark results for post-trained Qwen2.5-VL-7B-Instruct and Qwen3-VL-8B-Instruct models.这张图/表用于判断 VideoKR 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:ICML Spotlight 的视频推理数据与评测工作;不是 SSL 目标,但对视频 foundation model 评估有参考。
方法拆解
ICML Spotlight 的视频推理数据与评测工作;不是 SSL 目标,但对视频 foundation model 评估有参考