The Invisible Hand of Physics:它和通用视觉自监督的关系在于:通过反演视频扩散轨迹发现物理可行性可从 DiT 状态线性解码,提示生成式预训练隐含视觉物理表征
高相关;详见方法、贡献和实验边界。
The Invisible Hand of Physics: When Video Diffusion Models Know More Than They Show arXiv 原文链接
编号2606.05328优先级P1类别Visual SSL / representation会议arXiv方法通过反演视频扩散轨迹发现物理可行性可从 DiT 状态线性解码,提示生成式预训练隐含视觉物理表征来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:通过反演视频扩散轨迹发现物理可行性可从 DiT 状态线性解码,提示生成式预训练隐含视觉物理表征。 高相关;详见方法、贡献和实验边界。
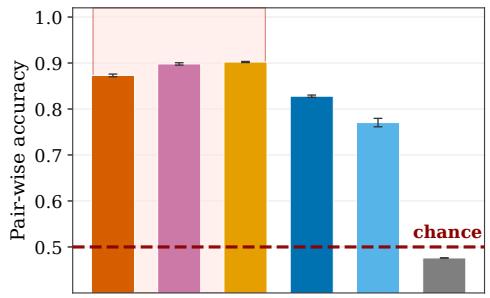
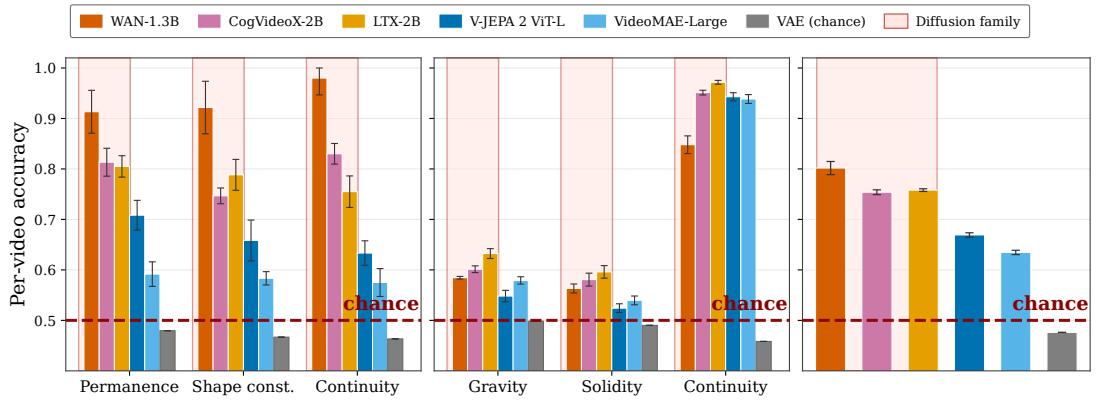
Figureure 3 · : Pairwise accuracy on IntPhys and InfLevelFigure 3: Pairwise accuracy on IntPhys and InfLevel. Following the protocol of Garrido et al. [2025], the probe is shown a plausible/impossible pair and predicts which is impossible. Diffusion models always exceed V-JEPA and VideoMAE-Large, supporting the per-video result of Figure 2.这张图/表用于判断 The Invisible Hand of Physics 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 2 · : Physical plausibility is decodable from the internal states of videoFigure 2: Physical plausibility is decodable from the internal states of video diffusion models. Probe accuracy on (Left) IntPhys and (Middle) InfLevel for WAN, LTX, and CogVideoX, compared against V-JEPA and VideoMAEv2. (Right) Diffusion video models outperform representation encoder on average. Error bars demonstrates standard error of the mean across 5 seeds.这张图/表用于判断 The Invisible Hand of Physics 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:通过反演视频扩散轨迹发现物理可行性可从 DiT 状态线性解码,提示生成式预训练隐含视觉物理表征。