MotionEnhancer:它和通用视觉自监督的关系在于:从 video diffusion model 蒸馏 motion attention prior 给 video VLM,适合跟踪视频表征和生成模型监督的交叉
中高相关;详见方法、贡献和实验边界。
MotionEnhancer: Leveraging Video Diffusion for Motion-Enhanced Vision-Language Models arXiv 新增 + CVPR 2026 原文链接
编号2606.06853优先级P1类别arXiv 新增 + CVPR 2026会议arXiv 新增 + CVPR 2026方法从 video diffusion model 蒸馏 motion attention prior 给 video VLM,适合跟踪视频表征和生成模型监督的交叉来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:从 video diffusion model 蒸馏 motion attention prior 给 video VLM,适合跟踪视频表征和生成模型监督的交叉。 中高相关;详见方法、贡献和实验边界。
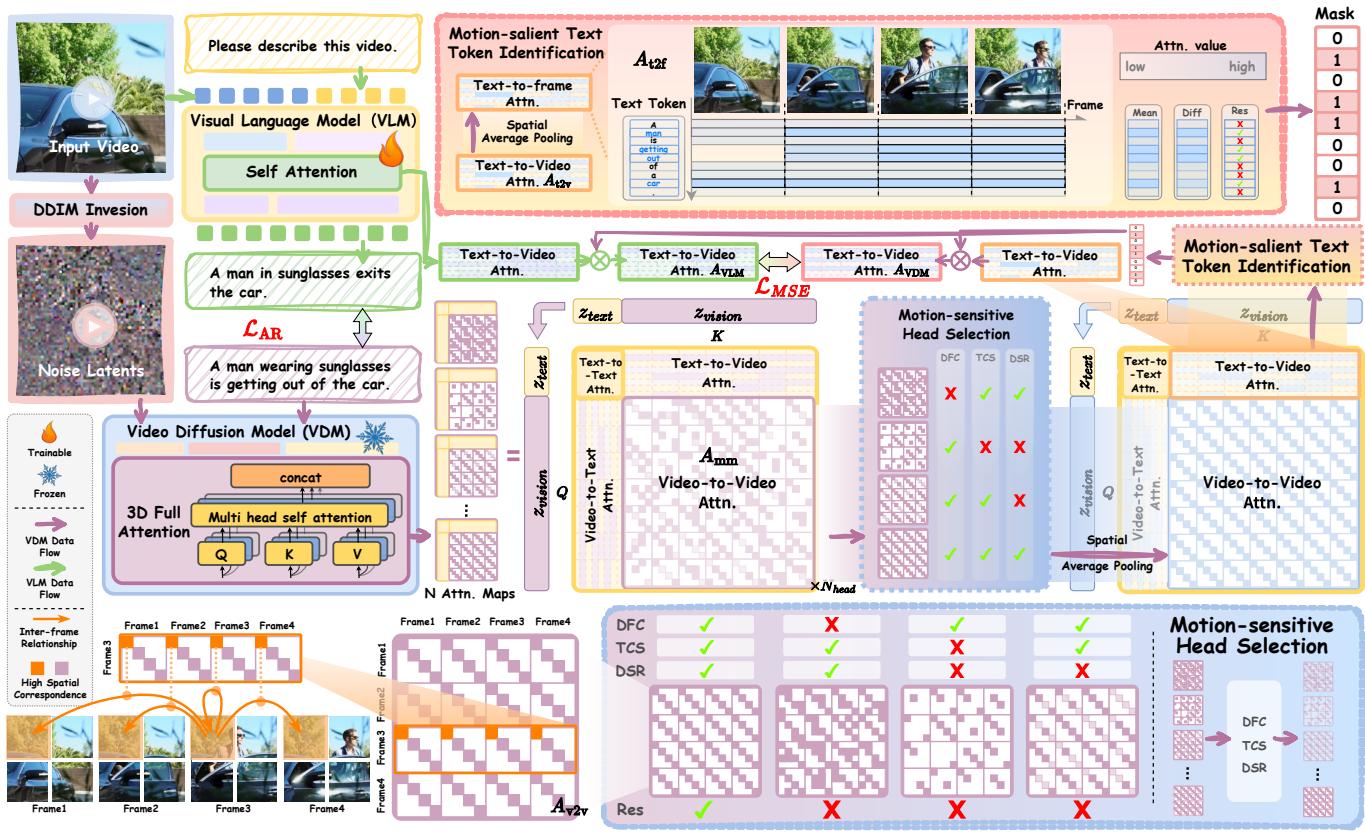
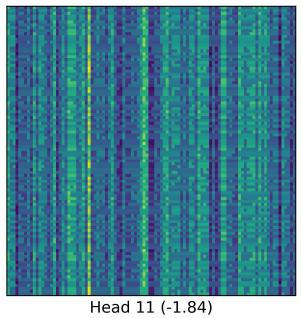
Figureure 2 · Framework of MotionEnhancerFigure 2. Framework of MotionEnhancer. Our method leverages motion priors distilled from a powerful VDM as auxiliary supervision to enhance the motion understanding capability of a VLM through attention alignment. Attention maps extracted from the VDM during DDIM sampling are filtered by the Motion-sensitive Head Selection (MHS) and Motion-salient Text Token Identification (MTTI) modules to identify motion-relevant attentions. The resulting text-to-vision attentions are then used to guide the VLM during supervised fine-tuning.这张图概括 MotionEnhancer 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · Zoom-in view of two specific headsFigure 2. Zoom-in view of two specific heads. We selected the first 100 spatial location tokens for visualization. It is demonstrated that heads with high scores exhibit a diagonal pattern, which is consistent with the main paper.这张可视化用来解释 MotionEnhancer 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。
核心问题
它和通用视觉自监督的关系在于:从 video diffusion model 蒸馏 motion attention prior 给 video VLM,适合跟踪视频表征和生成模型监督的交叉。
方法拆解
从 video diffusion model 蒸馏 motion attention prior 给 video VLM,适合跟踪视频表征和生成模型监督的交叉