先说结论。它和通用视觉自监督的关系在于:用层级 frame tokens 处理视频长程一致性,和视觉 tokenizer/RAE/world model 的 latent 设计高度相关。 中高相关;详见方法、贡献和实验边界。
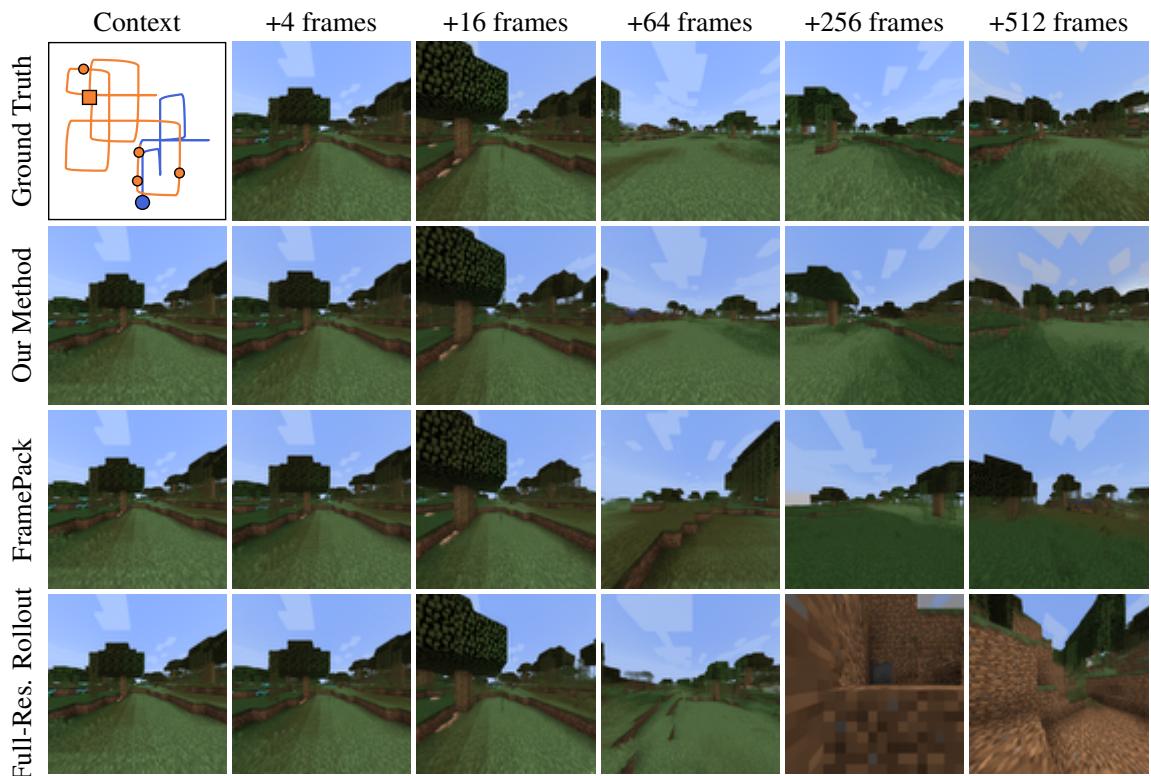
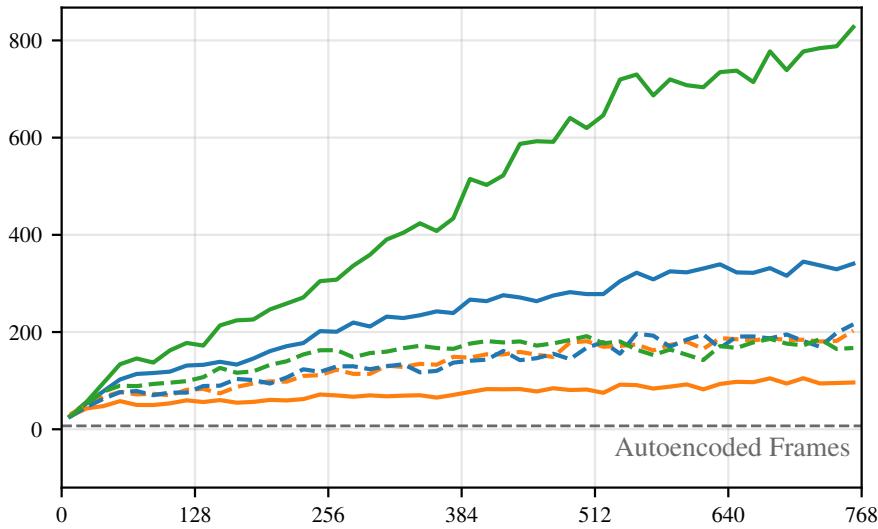
Figureure 3 · : Unlike the baselines, our method reliably recalls the scene’s structFigure 3: Unlike the baselines, our method reliably recalls the scene’s structure, even when many 1frames have elapsed. The top-left panel shows a top-down view of the trajectory the models follow. Blue is context; orange is generated. The points at which frames are shown are marked. We encourage the reader to consult our project website for videos of similar comparisons.这张图/表用于判断 MilliVid 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Quality (FVD ↓) Figure 9: Scaling properties: A comparison of our method and the baselinesQuality (FVD ↓) Figure 9: Scaling properties: A comparison of our method and the baselines at two distinct scales. 1Given 3840 tokens, both our method and FramePack hold 255 frames of context. Meanwhile, given 3584 tokens, the autoregressive high-resolution rollout model holds 7 frames of context. Given 1280 tokens, both our method and FramePack hold 85 frames of context; the high-resolution rollout model holds 2 frames of context. The models with longer sequence length were trained for 192,000 steps, while the ones with shorter sequence length were trained for 256,000 steps. Longer sequence length improves consistency for both our model and FramePack. However, it causes the high-resolution rollout model to become unstable, and so its consistency falls below the consistency of random ground-truth frames. With a lower sequence length, all models have roughly the same per-frame quality. However, increasing sequence length appears to increase exposure bias (as indicated by increasing FVD) for the baselines while reducing it for our model. This suggests that our model may have more favorable scaling properties than the baselines.这张图/表用于判断 MilliVid 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:用层级 frame tokens 处理视频长程一致性,和视觉 tokenizer/RAE/world model 的 latent 设计高度相关。
方法拆解
用层级 frame tokens 处理视频长程一致性,和视觉 tokenizer/RAE/world model 的 latent 设计高度相关