Latent Spatial Memory for Video:它和通用视觉自监督的关系在于:把视频 world model 的跨帧记忆从 RGB/点云搬到 diffusion latent,直接触及可复用视觉 latent 与长期一致性
高相关;详见方法、贡献和实验边界。
Latent Spatial Memory for Video World Models arXiv recent-list补漏 + project 原文链接
编号2606.09828优先级P0类别arXiv recent-list补漏 + project会议arXiv recent-list补漏 + project方法把视频 world model 的跨帧记忆从 RGB/点云搬到 diffusion latent,直接触及可复用视觉 latent 与长期一致性来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:把视频 world model 的跨帧记忆从 RGB/点云搬到 diffusion latent,直接触及可复用视觉 latent 与长期一致性。 高相关;详见方法、贡献和实验边界。
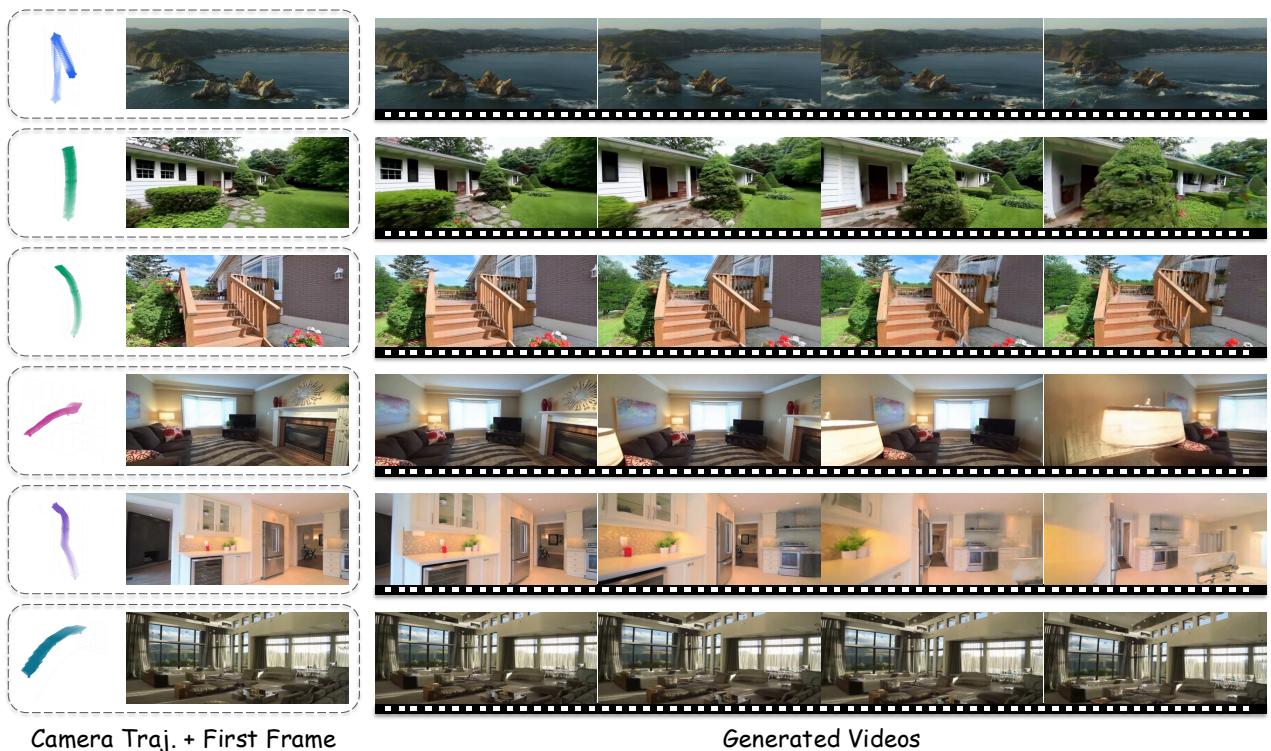
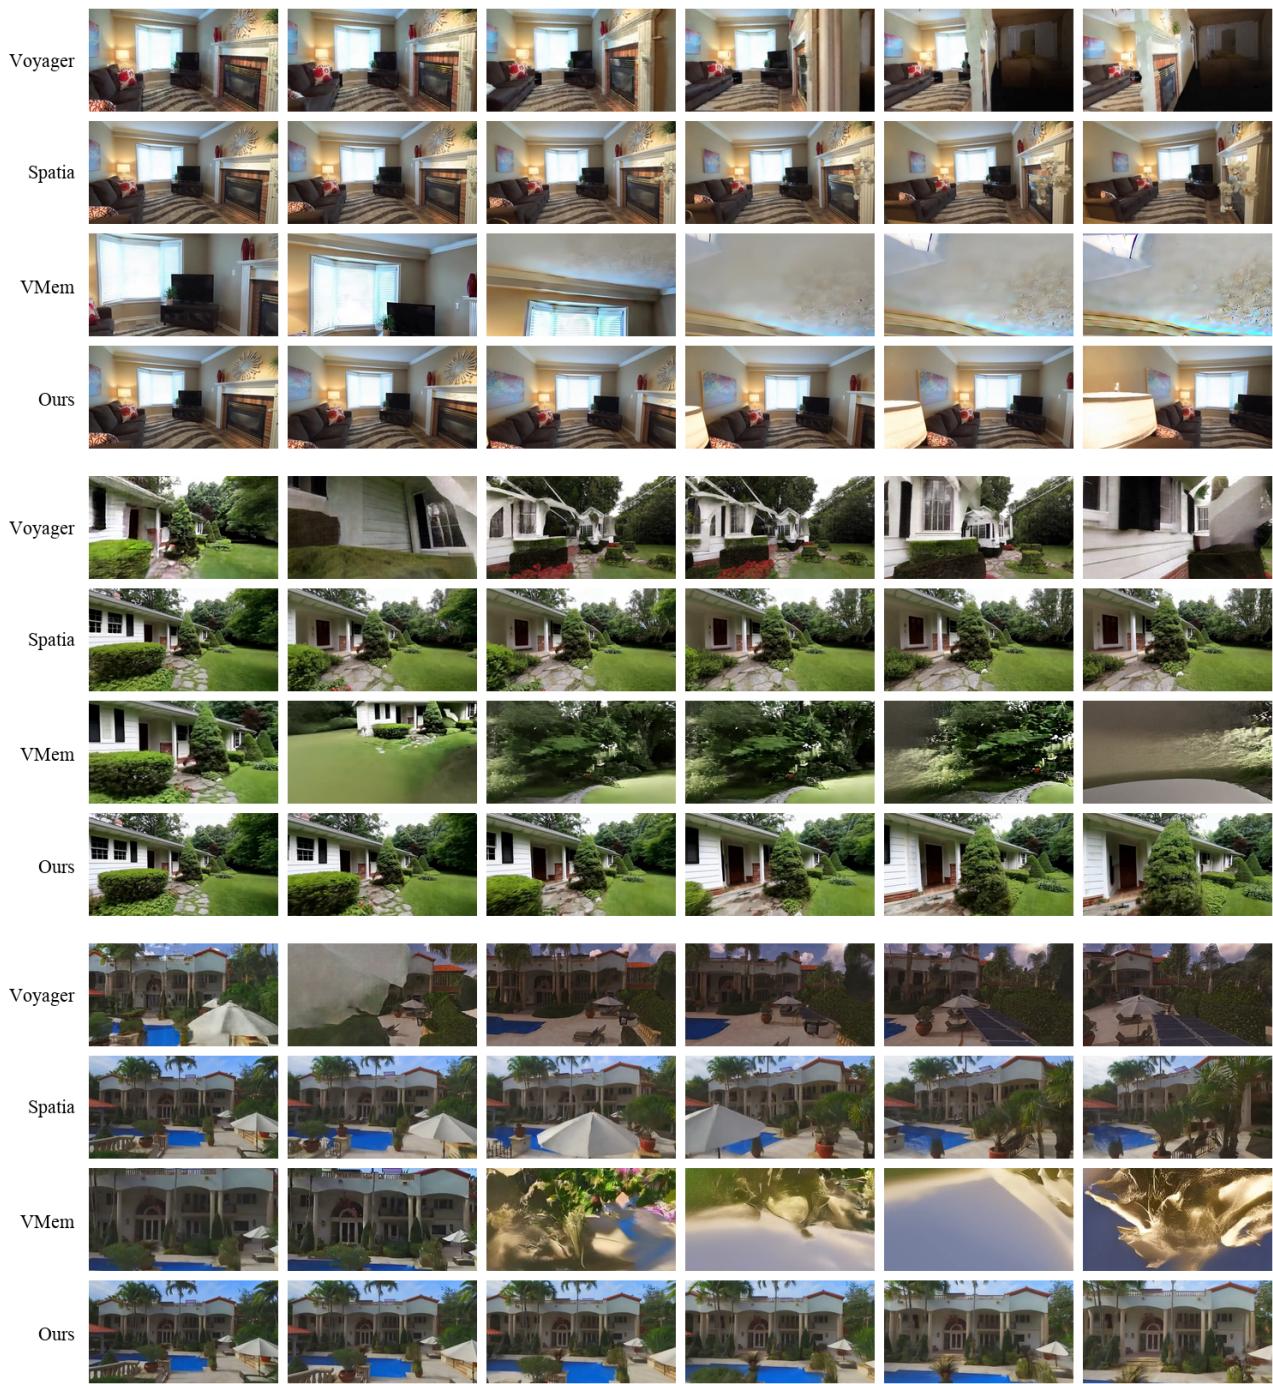
Figureure 1 · Geometrically consistent videos generated by Mirage with latent spatiaFigure 1 Geometrically consistent videos generated by Mirage with latent spatial memory. Given a single input image and a user-specified camera trajectory (left), Mirage preserves spatial consistency by caching 3D information directly in the latent space, rather than as an RGB-colored point cloud. This design enables memory queries through a single latent-resolution projection, avoiding the costly rasterize-and-encode round trip required by prior RGB point-cloud memories. Consequently, Mirage can faithfully return to previously observed regions even after large camera detours, while achieving up to 10.57× faster end-to-end video generation and 55× lower GPU memory usage than RGB-cache baselines.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Latent Spatial Memory for Video 的方法或实验,请结合正文精读段落一起看。Figureure 6 · Video comparison on RealEstate10KFigure 6 Video comparison on RealEstate10K. Each block shows one RealEstate10K trajectory, with rows corresponding to Voyager, Spatia, VMem, and Mirage (Ours), and columns showing uniformly sampled frames over time. Across indoor and outdoor scenes, Mirage preserves sharper structure and more stable appearance under camera motion, while baselines exhibit geometry drift, texture distortion, or accumulated artifacts.这张图/表用于判断 Latent Spatial Memory for Video 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:把视频 world model 的跨帧记忆从 RGB/点云搬到 diffusion latent,直接触及可复用视觉 latent 与长期一致性。
方法拆解
把视频 world model 的跨帧记忆从 RGB/点云搬到 diffusion latent,直接触及可复用视觉 latent 与长期一致性