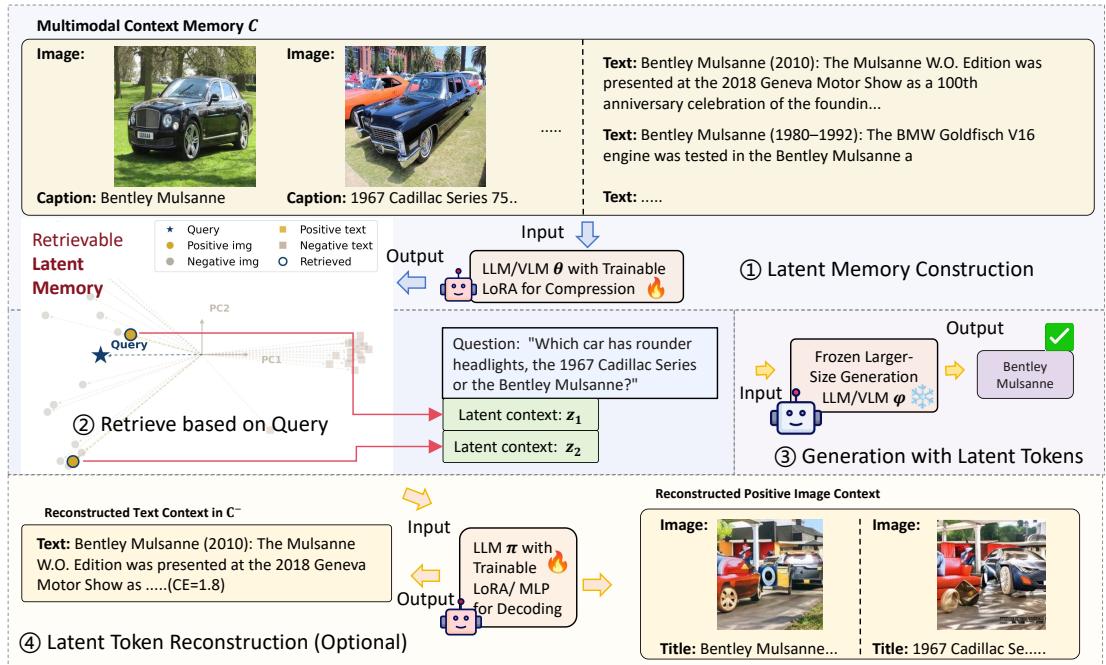
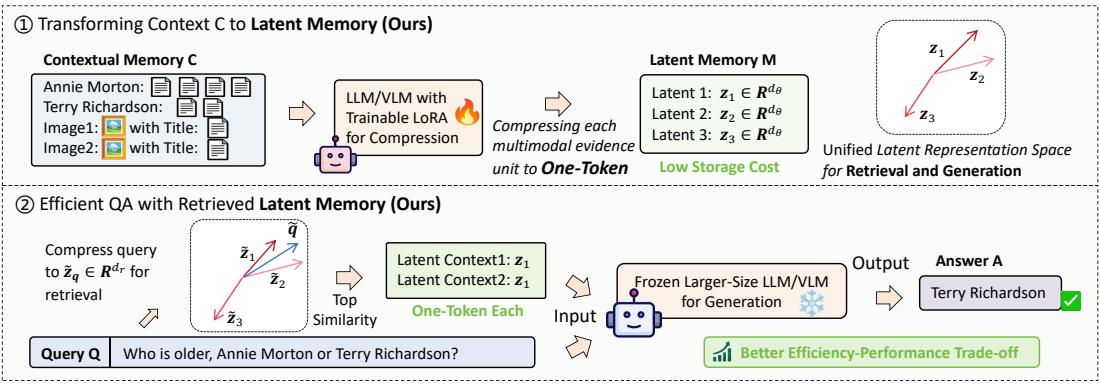
Figureure 11 · : Additional multimodal WebQA case studies with LLaVA-1.5-13BFigure 11: Additional multimodal WebQA case studies with LLaVA-1.5-13B. Each example uses the same Latent Memory retrieval-and-generation pipeline as the main experiments.这张图概括 One Token per Multimodal Evidence 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。(b) Generation with retrievable Latent Memory (Ours) Figure 1: (a) shows the existing pipe(b) Generation with retrievable Latent Memory (Ours) Figure 1: (a) shows the existing pipeline for memory-based generation. To improve storage efficiency and token efficiency, our Latent Memory (b) can compress each multimodal evidence into one latent token, which achieves better retrieval ability and competitive generation performances.这张图概括 One Token per Multimodal Evidence 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。