先说结论。它和通用视觉自监督的关系在于:用四关键帧时序一致性 probe 静态图像生成模型的 visual world modeling 能力。 高相关;详见方法、贡献和实验边界。
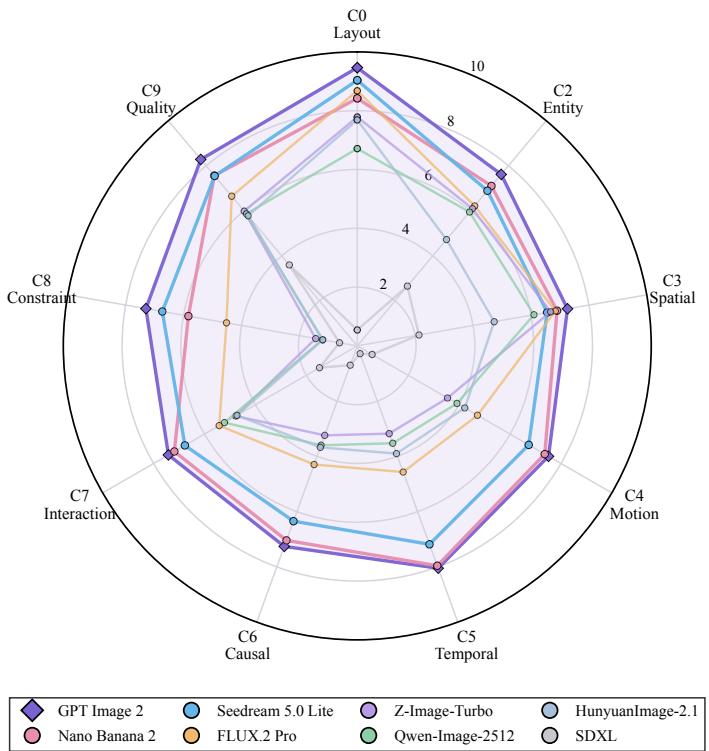
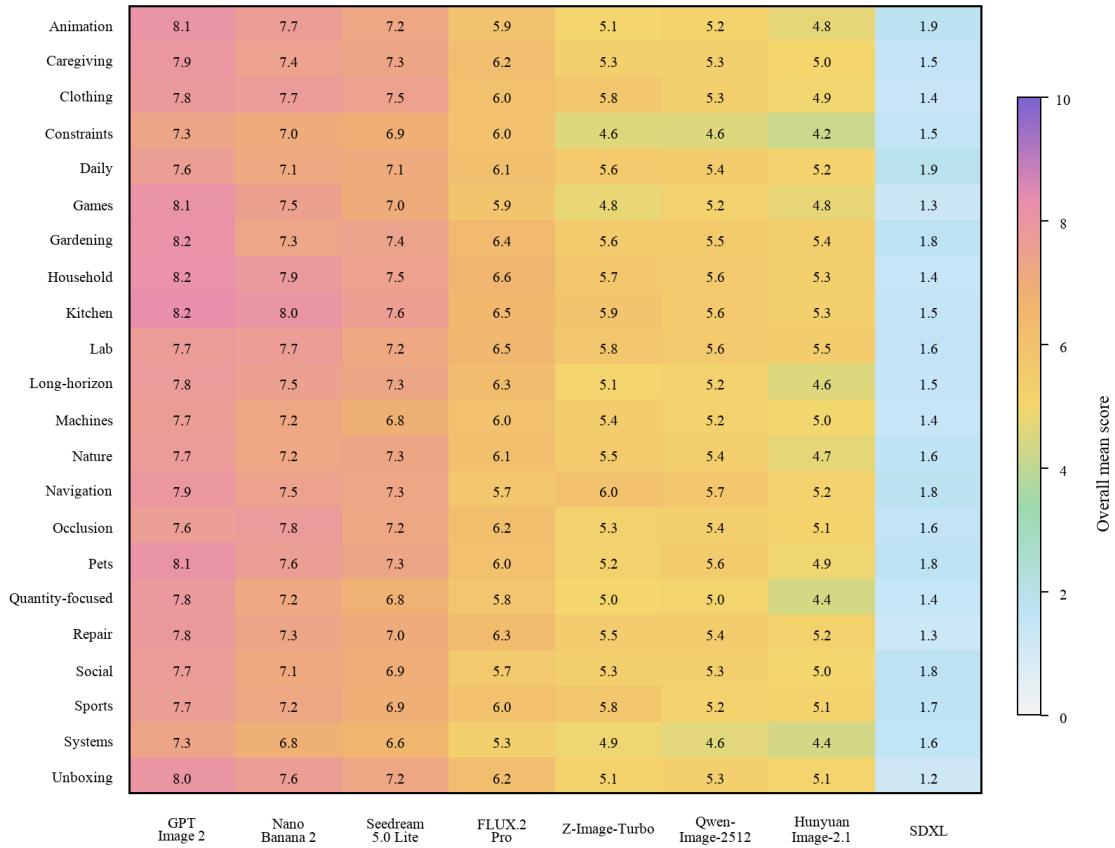
Figureure 3 · | Radar view of prompt-only capability scores across all eight evaluatFigure 3 | Radar view of prompt-only capability scores across all eight evaluated models. The axes correspond to C0 and C2–C9; C1 is omitted because reference grounding is not applicable without a reference image. The faint purple envelope highlights the GPT Image 2 capability profile, while all model contours and markers are retained for comparison.这张图/表用于判断 Can Image Models Imagine Time? ImageTime 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 7 · | Fine-grained category-level prompt-only Overall mean scoresFigure 7 | Fine-grained category-level prompt-only Overall mean scores. Rows cover all 22 ImageTime categories reconstructed from the case filename and case-id prefixes, and columns report the eight evaluated models.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Can Image Models Imagine Time? ImageTime 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:用四关键帧时序一致性 probe 静态图像生成模型的 visual world modeling 能力。
方法拆解
用四关键帧时序一致性 probe 静态图像生成模型的 visual world modeling 能力