Next Forcing:它和通用视觉自监督的关系在于:用多未来 chunk 预测给 causal video world model 更密集的时间监督,和视频自监督/latent prediction 主线高度相关
高相关;详见方法、贡献和实验边界。
Next Forcing: Causal World Modeling with Multi-Chunk Prediction arXiv 新增 原文链接
编号2606.11187优先级P0类别arXiv 新增会议arXiv 新增方法用多未来 chunk 预测给 causal video world model 更密集的时间监督,和视频自监督/latent prediction 主线高度相关来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:用多未来 chunk 预测给 causal video world model 更密集的时间监督,和视频自监督/latent prediction 主线高度相关。 高相关;详见方法、贡献和实验边界。
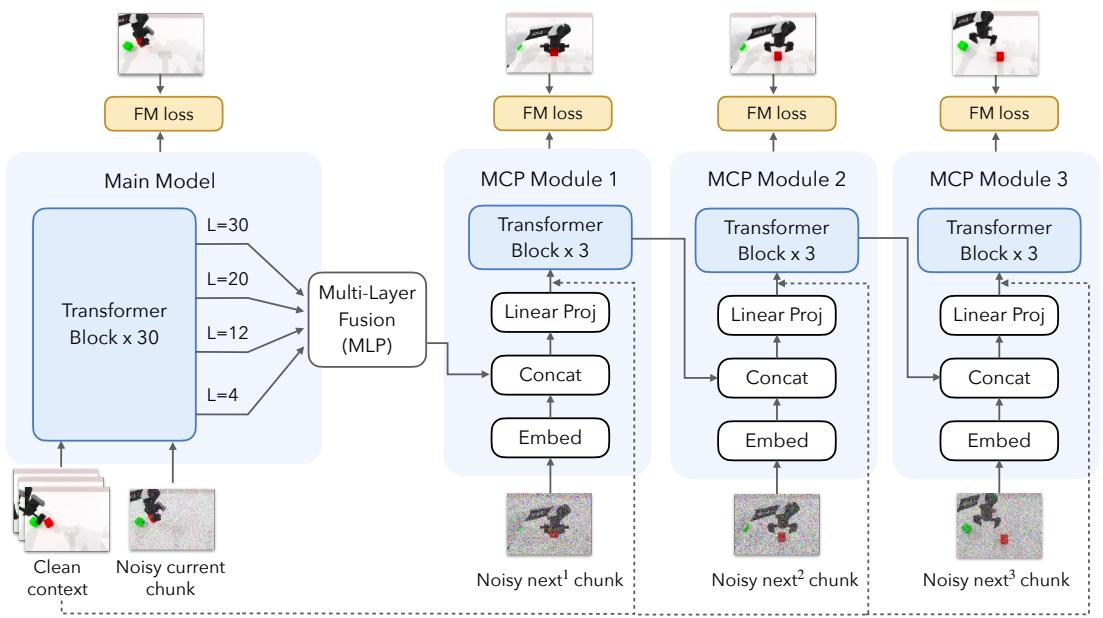
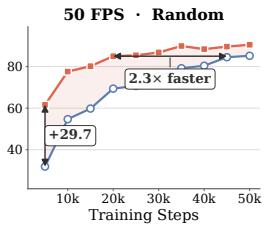
Figureure 2 · : Overview of Next ForcingFigure 2: Overview of Next Forcing. The main model denoises the current chunk, while chained MCP modules predict future chunks (next1, next2, . . .) using features from the main model, providing dense temporal supervision during training and enabling parallel chunk prediction at inference.这张图概括 Next Forcing 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Task success rate (%) on RoboTwin across training stepsFigure 1: Task success rate (%) on RoboTwin across training steps. Next Forcing converges faster and reaches higher final accuracy than LingBot-VA at both 12 and 50 fps. The advantage is most pronounced at 50 fps: at 5k steps Next Forcing already outperforms LingBot-VA by 29.7 points on Random, and matches its 45k-step accuracy at only 20k steps, a 2.3× training speedup.这张图/表用于判断 Next Forcing 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:用多未来 chunk 预测给 causal video world model 更密集的时间监督,和视频自监督/latent prediction 主线高度相关。
方法拆解
用多未来 chunk 预测给 causal video world model 更密集的时间监督,和视频自监督/latent prediction 主线高度相关