先说结论。它和通用视觉自监督的关系在于:把图像和视频 tokenization 放进同一个 ViT tokenizer,并用教师监督塑形 compact latent,是统一视觉 token 表征路线。 高相关;详见方法、贡献和实验边界。
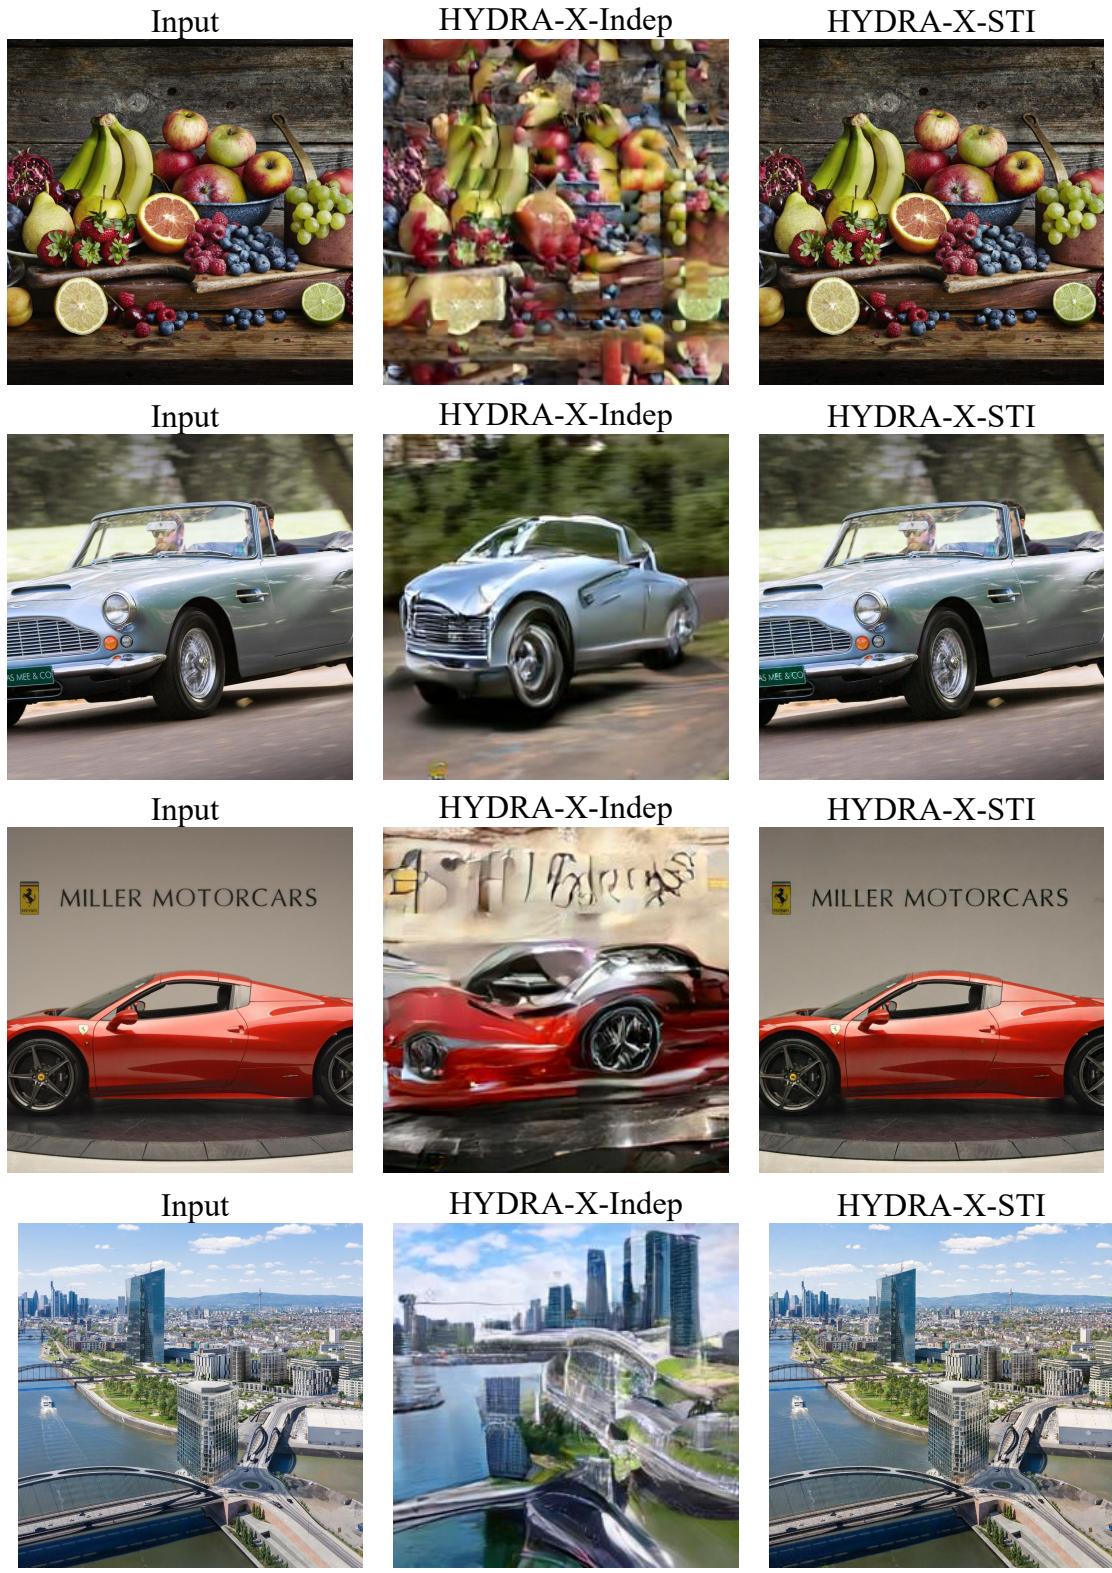
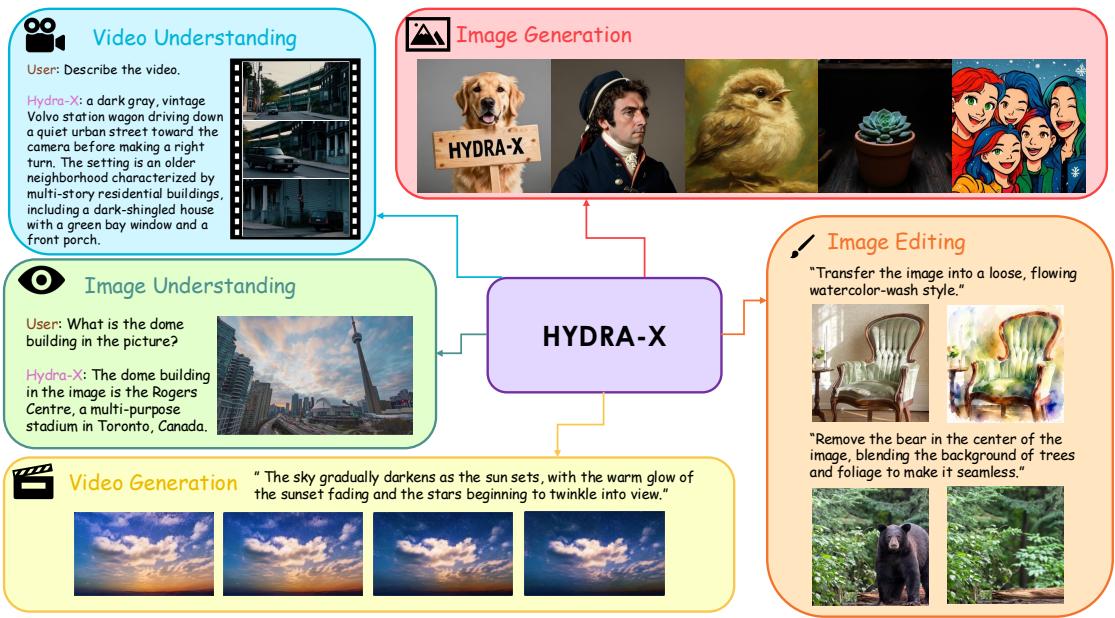
Figureure 5 · : Qualitative effect of tokenizer-stage source–target interactionFigure 5: Qualitative effect of tokenizer-stage source–target interaction. Source-image reconstruction produced by HYDRA-X-Indep (independent Sem-ViT encoding of source and target, the conventional pipeline) versus HYDRA-X-STI (joint encoding through tubelet causal attention, our proposal). The two variants share every other architectural component. HYDRA-X-STI preserves identity-sensitive details (object layout, characters, on-screen text) that HYDRA-X-Indep loses, despite both pipelines using the same LLM and the same number of parameters.这张图概括 HYDRA-X 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : HYDRA-X is a native UMM that unifies image/video understanding, imagFigure 1: HYDRA-X is a native UMM that unifies image/video understanding, image/video generation, and instruction-guided image editing through one holistic tokenizer HYDRA-XTOK.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 HYDRA-X 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:把图像和视频 tokenization 放进同一个 ViT tokenizer,并用教师监督塑形 compact latent,是统一视觉 token 表征路线。
方法拆解
把图像和视频 tokenization 放进同一个 ViT tokenizer,并用教师监督塑形 compact latent,是统一视觉 token 表征路线