通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-06-14 图像表征 · VFM · JEPA · 视频预训练
arXiv 新增 + project · P1 · 2026-06-14

RepWAM:它和通用视觉自监督的关系在于:把 WAM 从重建型视频 tokenizer 转到 representation-centric visual-action tokenizer,虽偏具身,但方法可迁移到视频 world m...

中高相关;详见方法、贡献和实验边界。

编号2606.13674 优先级P1 类别arXiv 新增 + project 会议arXiv 新增 + project 方法把 WAM 从重建型视频 tokenizer 转到 representation-centric visual-action tokenizer,虽偏具身,但方法可迁移到视频 world model 表征 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:把 WAM 从重建型视频 tokenizer 转到 representation-centric visual-action tokenizer,虽偏具身,但方法可迁移到视频 world m... 中高相关;详见方法、贡献和实验边界。
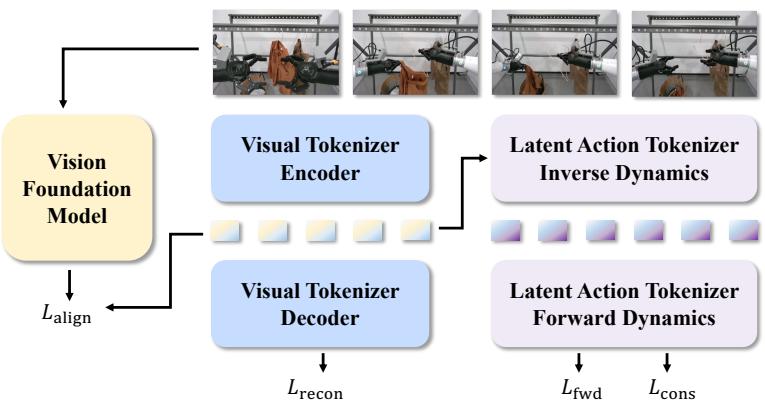
(c) Representation Visual-Action Tokenizer Figure 1 Overview of our representation visual-
(c) Representation Visual-Action Tokenizer Figure 1 Overview of our representation visual-(c) Representation Visual-Action Tokenizer Figure 1 Overview of our representation visual-action tokenizer, which aligns visual latents with a frozen visual foundation model to obtain semantically rich visual tokens, and induces latent actions as transitions within this shared semantic space via coupled inverse and forward dynamics models.这张图概括 RepWAM 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
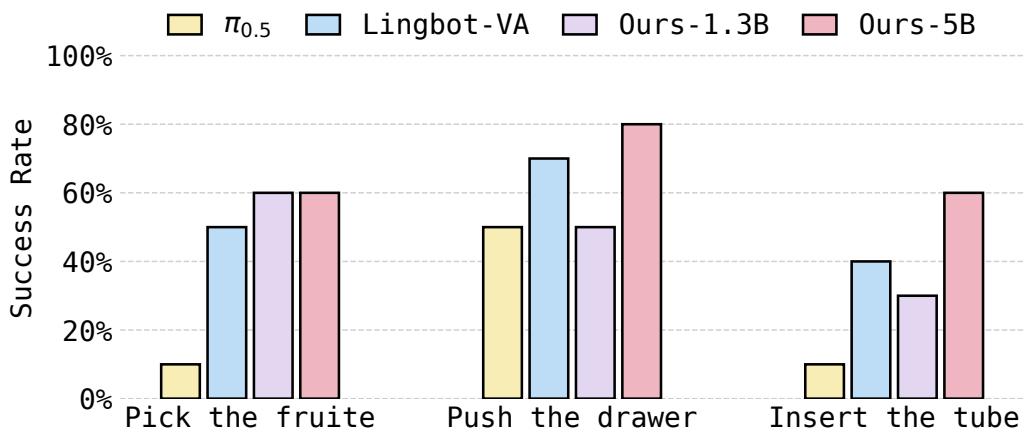
Figureure 2 · Real-world success rate (10 rollouts per task) on three manipulation t
Figureure 2 · Real-world success rate (10 rollouts per task) on three manipulation tFigure 2 Real-world success rate (10 rollouts per task) on three manipulation tasks, comparing ??0 5 [4] and Lingbot-VA [20] against our 1 3B and 5B WAMs.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 RepWAM 的方法或实验,请结合正文精读段落一起看。

核心问题

它和通用视觉自监督的关系在于:把 WAM 从重建型视频 tokenizer 转到 representation-centric visual-action tokenizer,虽偏具身,但方法可迁移到视频 world model 表征。

方法拆解

把 WAM 从重建型视频 tokenizer 转到 representation-centric visual-action tokenizer,虽偏具身,但方法可迁移到视频 world model 表征

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。