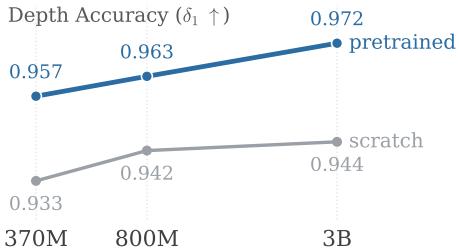
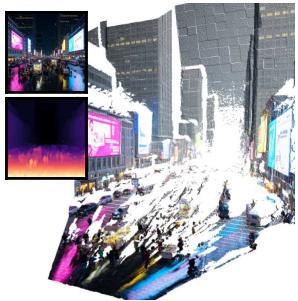
(c) Scales with T2I model size Figure 1: We present Modality Forcing, a post-training reci(c) Scales with T2I model size Figure 1: We present Modality Forcing, a post-training recipe to extract spatial priors from text-toimage (T2I) models. A single DiT models the joint distribution over images and depth, enabling joint and conditional generation in arbitrary combinations. We demonstrate depth predictions improve with increasingly capable T2I pretraining, suggesting T2I is a scalable objective for spatial generation.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Modality Forcing for Scalable Spatial 的方法或实验,请结合正文精读段落一起看。Neon city plaza at nightNeon city plaza at night. Figure 2: Modality Forcing generates rich RGB-Depth from text prompts. Unprojecting the points to 3D, Modality Forcing generates faithful and sharp geometry. The same checkpoint enables monocular depth estimation, and depth-to-image generation competitive with the best specialist models.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Modality Forcing for Scalable Spatial 的方法或实验,请结合正文精读段落一起看。