CausalMotion: Structured Physical Reasoning as Keyframe and Trajectory Guidance for Training-Free Video Generation arXiv 新增 + video generation representation 原文链接
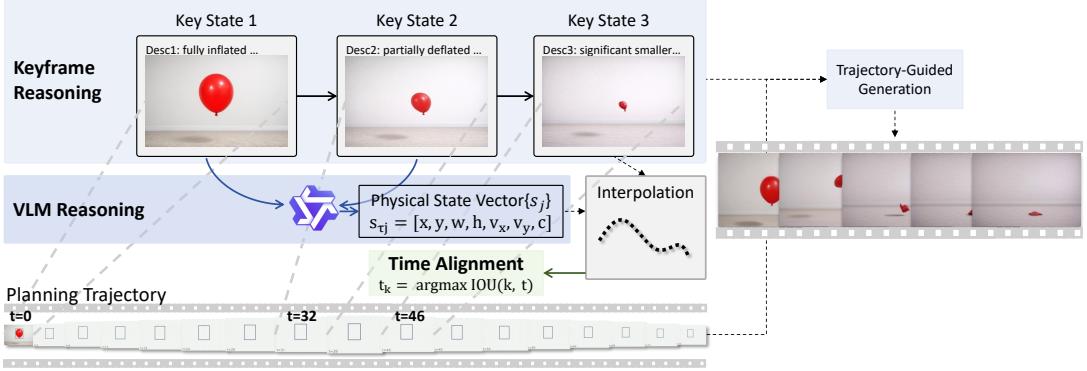
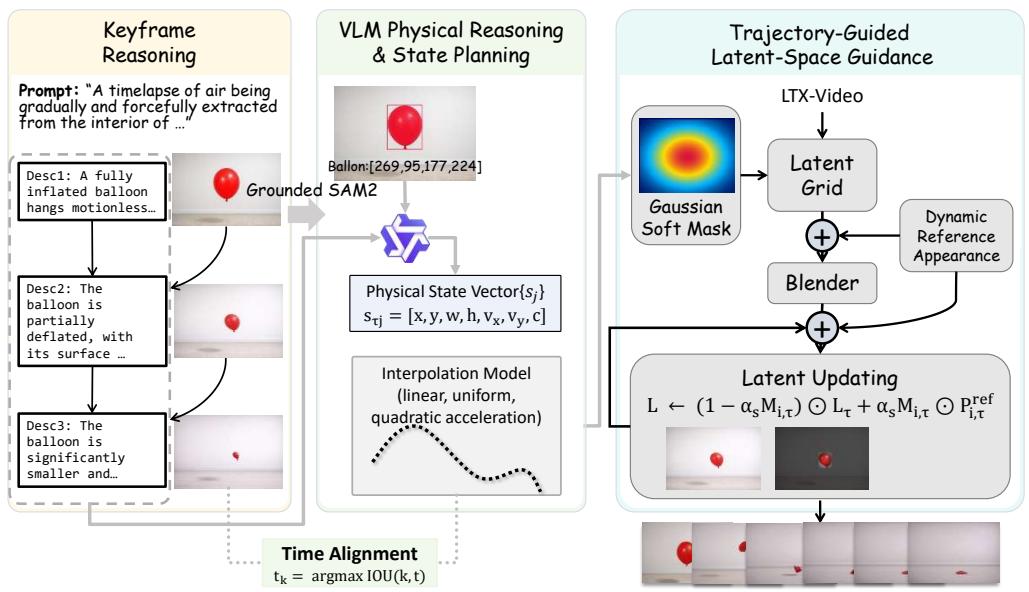
Figureure 1 · : Overview of CausalMotionFigure 1: Overview of CausalMotion. Our training-free framework performs structured physical reasoning to generate keyframes and trajectories, then guides the diffusion model with these intermediate representations.这张图概括 CausalMotion 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : The architecture of our methodFigure 2: The architecture of our method. Given a text prompt, CausalMotion first performs iterative visual reasoning to decompose complex events into causally consistent key states and generates corresponding keyframes that capture critical transitions. It then localizes key objects, predicts sparse physical state vectors, and constructs dense motion trajectories through physicsaware interpolation and temporal alignment. Finally, the generated trajectories are projected into the diffusion latent space, where appearance anchors from keyframes and localized latent updates jointly guide denoising toward physically plausible motion and temporally consistent video generation.这张图概括 CausalMotion 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。