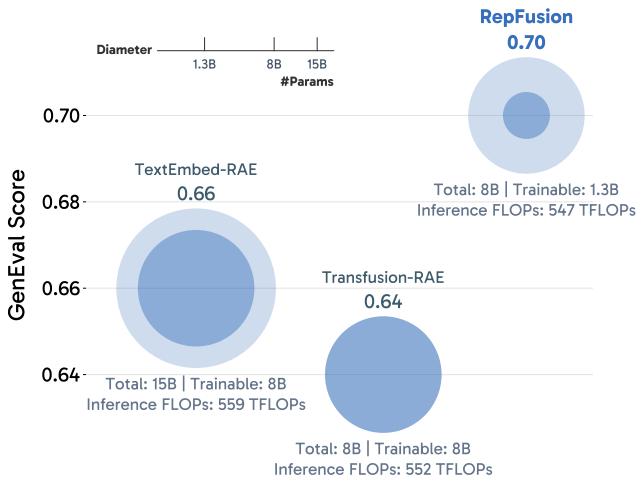
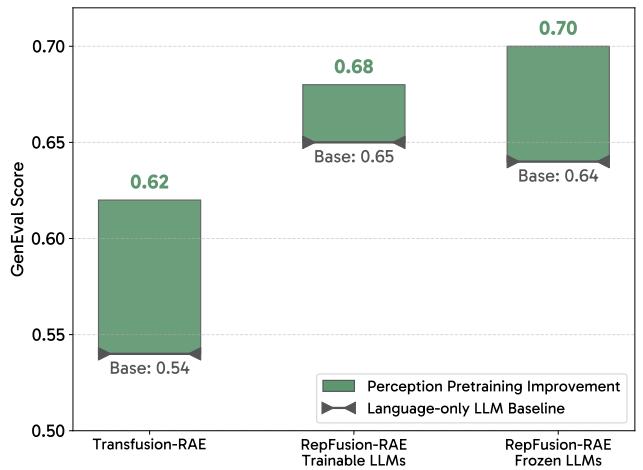
Figureure 2 · GenEval comparison across different conditioning strategies under simiFigure 2. GenEval comparison across different conditioning strategies under similar inference FLOPs. Circle size denotes total parameters, and the inner disk denotes trainable parameters. Each method allocates roughly 8B parameters to modules that either process noisy visual latents or denoise them. RepFusion fine-tunes only a 1.3B DiT and an MLP projector, yet outperforms TextEmbed and Transfusion, both of which train 8B parameters (a larger DiT and an LLM, respectively). This cross-method comparison suggests that MLLMs provide strong priors for denoising visual representations, and that repurposing them to encode noisy representations can be a more effective use of parameters than scaling newly initialized denoisers.这张图/表用于判断 RepFusion 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 4 · High-level comparison between MetaQuery-style (Pan et al., 2025) archiFigure 4 High-level comparison between MetaQuery-style (Pan et al., 2025) architectures (e.g., BLIP-3o (Chen et al., 2025a) and Scale-RAE (Tong et al., 2026)) and RepFusion. During training, both methods backpropagate gradients through the conditional encoder and denoiser, resulting in similar training FLOPs. At inference time, we rerun the MetaQuery conditional encoder with different timestep embeddings to match RepFusion’s inference budget. This increases compute from 113 to 552 TFLOPs, but GenEval does not improve (0.55 to 0.54), because the MLLM still does not observe the evolving noisy representation. In contrast, noisy representation inputs make RepFusion’s condition depend on the denoising state, enabling useful test-time compute scaling through repeated MLLM conditioning and improving GenEval to 0.70. (a) Effect of multimodal perception pretraining in the LLM backbone. Replacing an LLM with a perception-pretrained MLLM improves both Transfusion-RAE and RepFusion under settings with frozen and trainable LLMs.这张图概括 RepFusion 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:把 RAE 视觉表征空间里的 denoising 交给 MLLM 先验,是“语义 latent + 生成预训练”的强信号。
方法拆解
把 RAE 视觉表征空间里的 denoising 交给 MLLM 先验,是“语义 latent + 生成预训练”的强信号