先说结论。它和通用视觉自监督的关系在于:ICML 2026 接收的视觉推理 position paper,强调 VLM 缺少主动视觉探索能力。 中相关;详见方法、贡献和实验边界。
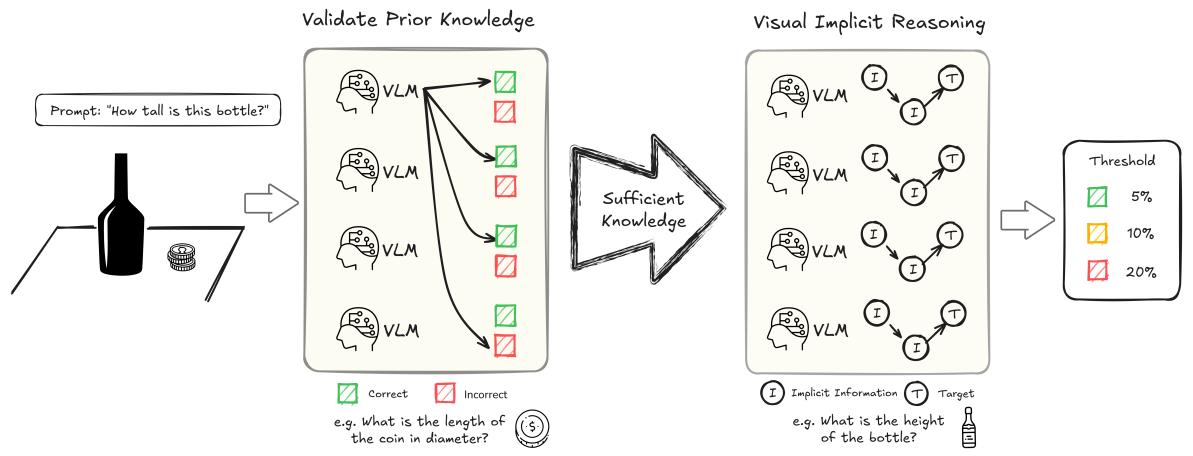
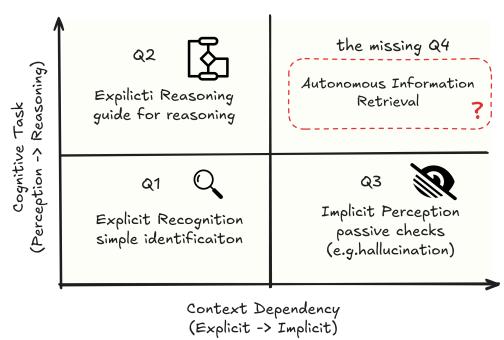
Figureure 2 · Framework for verifying implicit reasoning capabilityFigure 2. Framework for verifying implicit reasoning capability. To rigorously assess implicit reasoning independent of knowledge retrieval, we employ a filtered evaluation pipeline. We first validate prior knowledge across domains to ensure the model possesses the necessary factual basis, eliminating errors caused by knowledge gaps. Verified instances then proceed to Visual Implicit Reasoning, where the model needs to autonomously chain Implicit Information to derive the Target answer. This design ensures that performance metrics strictly reflect the model’s capability to reason with unstated visual cues rather than its memorized knowledge base.这张图概括 Position 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · Agency in visual reasoningFigure 1. Agency in visual reasoning. Left: Comparison of active agency vs. passive capacity in visual reasoning. Unlike humans actively retrieve implicit visual cues to reason about physical properties, current VLMs tend to ignore the implicit information and give wrong answers. Right: Our taxonomy highlights Autonomous Information Retrieval (Q4) as the critical gap. Success here requires visual agency, the ability to actively seek unmentioned visual evidence without explicit prompting which current models lack.这张图/表用于判断 Position 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:ICML 2026 接收的视觉推理 position paper,强调 VLM 缺少主动视觉探索能力。
方法拆解
ICML 2026 接收的视觉推理 position paper,强调 VLM 缺少主动视觉探索能力