通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-06-17 图像表征 · VFM · JEPA · 视频预训练
arXiv 新增 + video embedding benchmark · P2 · 2026-06-17

MVEB:它和通用视觉自监督的关系在于:23-task video embedding benchmark,给视频表征模型提供统一评测面

中高相关;详见方法、贡献和实验边界。

编号2606.14958 优先级P2 类别arXiv 新增 + video embedding benchmark 会议arXiv 新增 + video embedding benchmark 方法23-task video embedding benchmark,给视频表征模型提供统一评测面 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:23-task video embedding benchmark,给视频表征模型提供统一评测面。 中高相关;详见方法、贡献和实验边界。
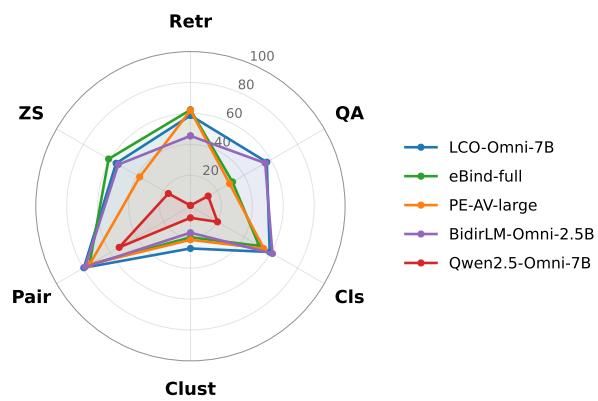
Figureure 2 · : Per-category mean scores for five representative models spanning the
Figureure 2 · : Per-category mean scores for five representative models spanning theFigure 2: Per-category mean scores for five representative models spanning the four paradigms. LCO-Embedding-Omni-7B, eBind-full, PE-AV-large, and BidirLM-Omni-2.5B trace broadly similar but distinct shapes; Qwen2.5-Omni-7B (generative MLLM used as embedder) collapses inward across every category. No single model dominates all six.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 MVEB 的方法或实验,请结合正文精读段落一起看。
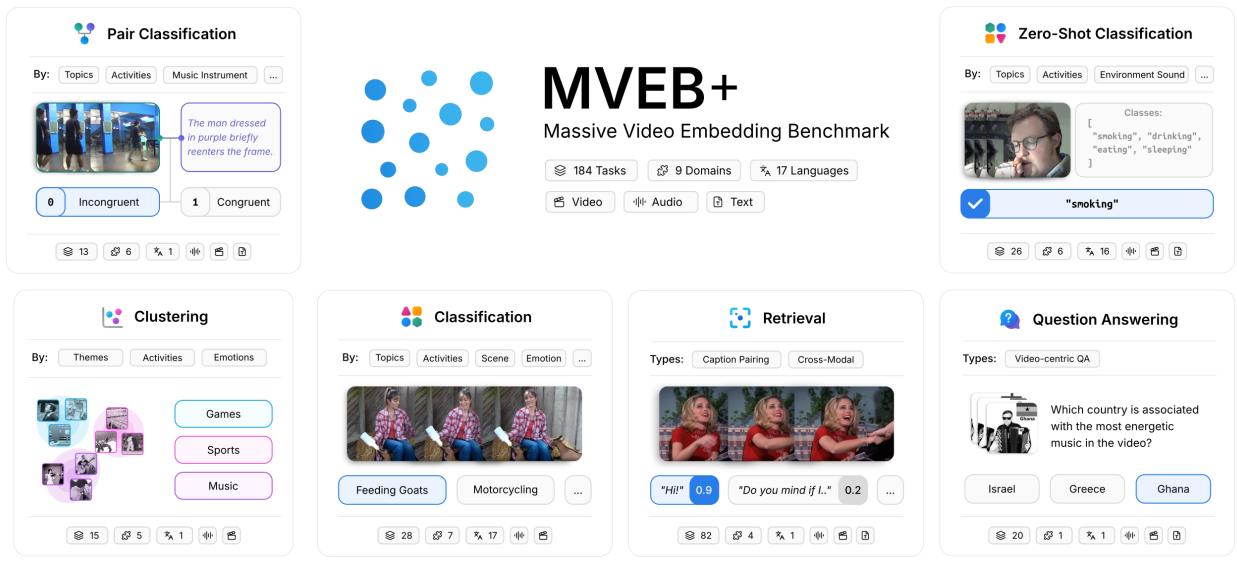
Figureure 1 · : Overview of task types and example subtypes in MVEB+.
Figureure 1 · : Overview of task types and example subtypes in MVEB+.Figure 1: Overview of task types and example subtypes in MVEB+.这张图概括 MVEB 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。

核心问题

它和通用视觉自监督的关系在于:23-task video embedding benchmark,给视频表征模型提供统一评测面。

方法拆解

23-task video embedding benchmark,给视频表征模型提供统一评测面

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。