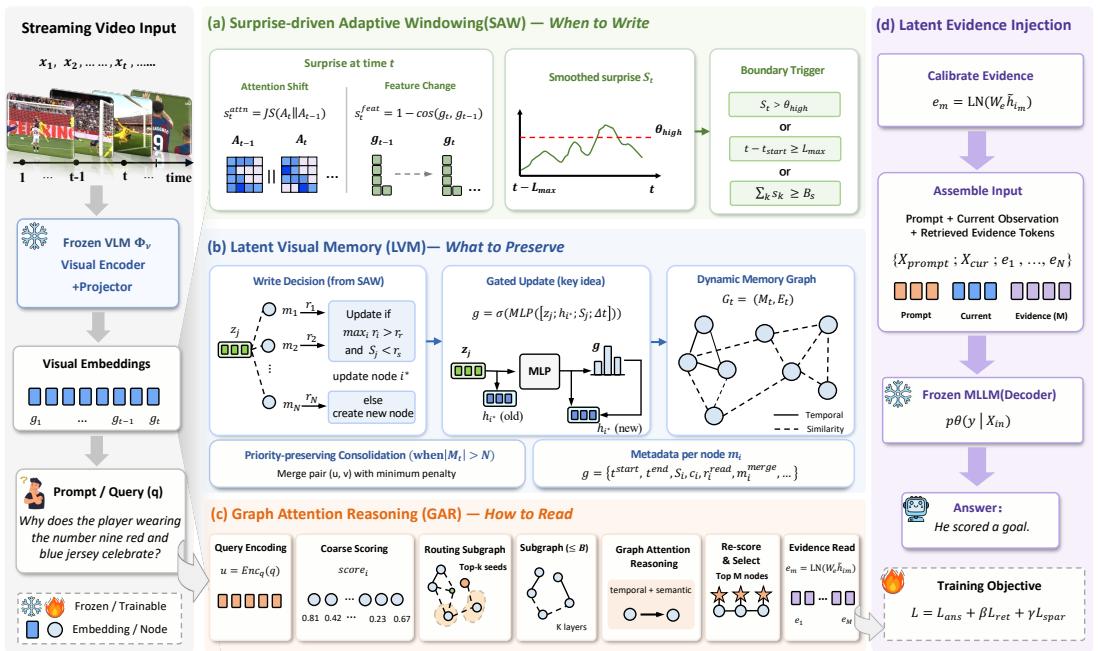
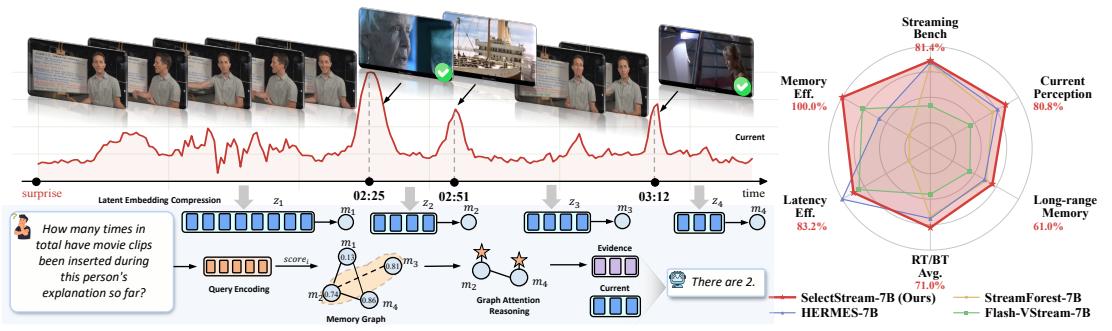
Figureure 2 · : Overview of SelectStreamFigure 2: Overview of SelectStream. The model writes projected VLM visual embeddings into a budgeted latent memory graph, retrieves a query-conditioned evidence subgraph, and injects calibrated latent evidence tokens into a frozen MLLM for answer generation.这张图概括 What Should a Streaming Video 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Motivation of SelectStreamFigure 1: Motivation of SelectStream. Relevant events may appear sparsely over a long stream, while later queries require evidence beyond the recent context. The example shows a counting question where inserted movie clips form sparse surprise peaks. The right panel illustrates the desired trade-off: stronger long-range memory and efficiency without sacrificing current-scene perception.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 What Should a Streaming Video 的方法或实验,请结合正文精读段落一起看。