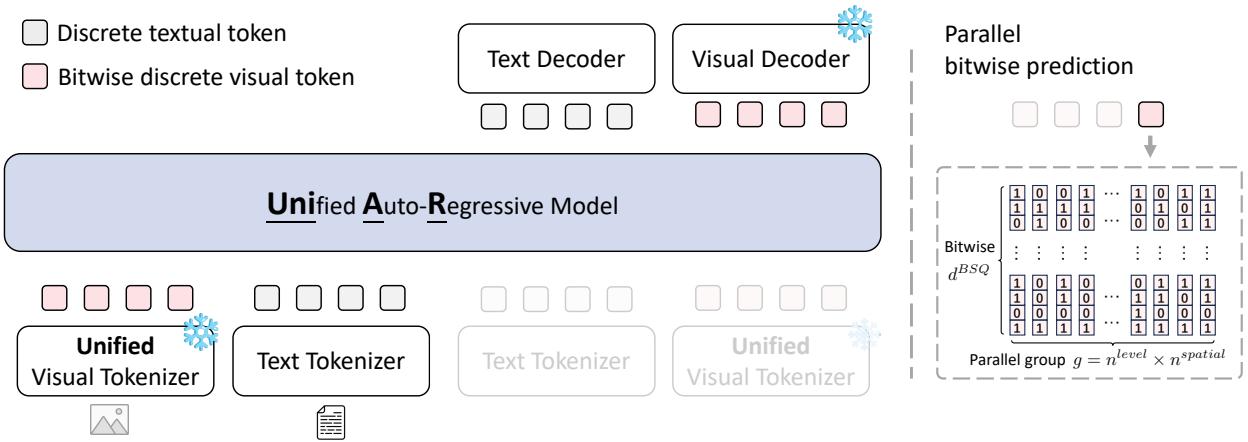
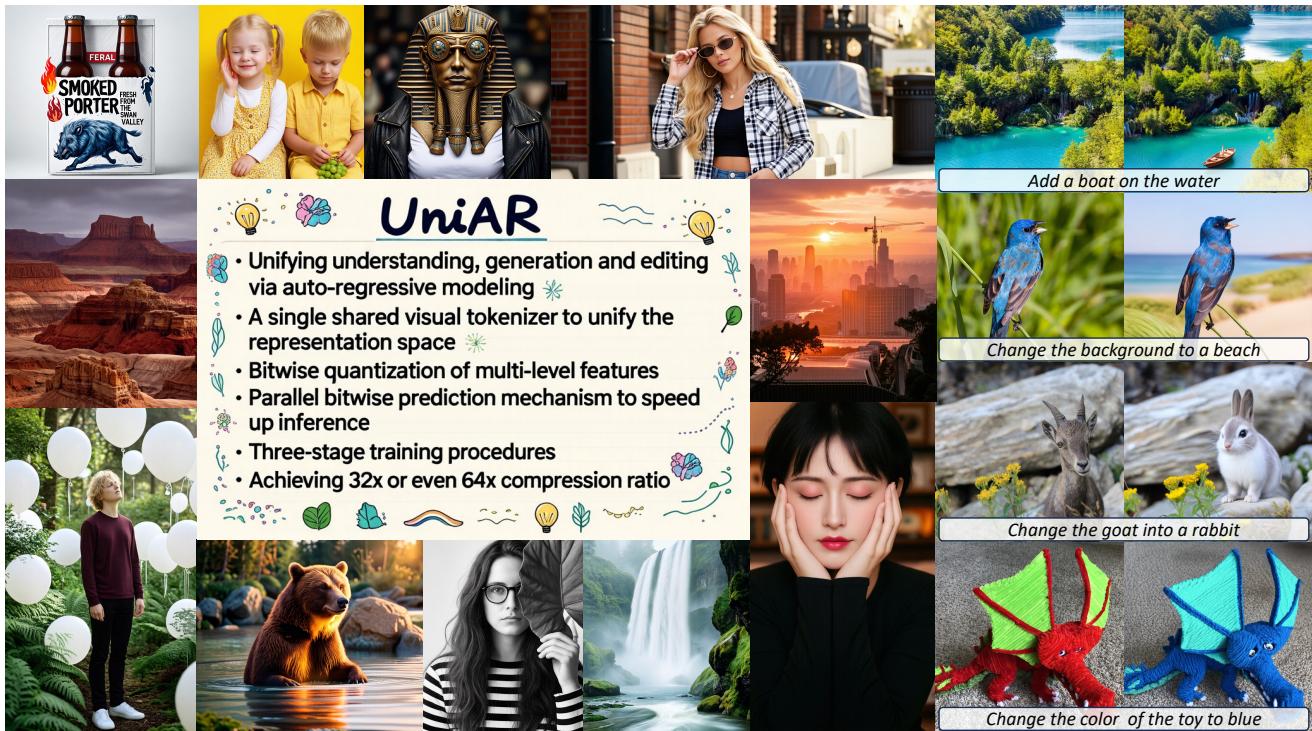
Figureure 2 · UniAR Framework OverviewFigure 2 UniAR Framework Overview. Our architecture integrates a unified visual tokenizer for bitwise quantization of image features into discrete semantic tokens, a unified autoregressive backbone that unifies generation and understanding via next-token prediction, and a DiT-based decoder for high-fidelity image decoding from predicted tokens. For visual generation, the auto-regressive model performs parallel bitwise prediction that predicts the next group of bit indices in parallel as shown in the right part. Notably, both the text and visual decoders are only required during inference and are not utilized during the pretraining stage.这张图概括 Unified Multimodal Autoregressive Modeling with 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · Visual content generated by UniARFigure 1 Visual content generated by UniAR. UniAR produces high-fidelity visual content with demonstrated efficacy in instruction-following and text rendering, alongside versatile image editing capabilities.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Unified Multimodal Autoregressive Modeling with 的方法或实验,请结合正文精读段落一起看。