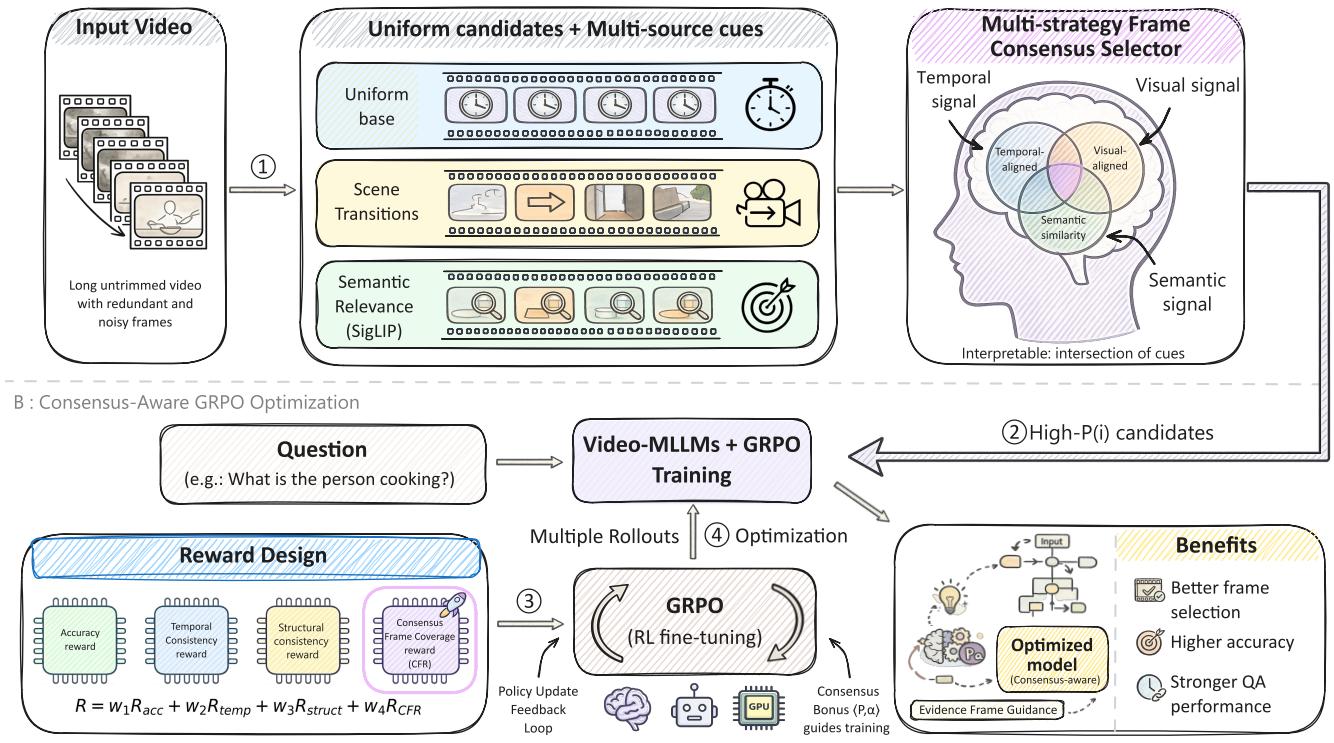
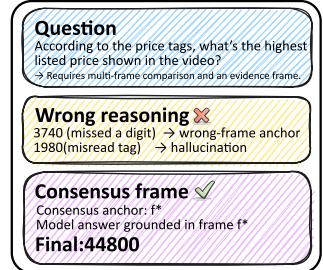
Figureure 2 · : Overview of the CF-GRPO frameworkFigure 2: Overview of the CF-GRPO framework. Panel A constructs a multi-source consensus prior from uniform coverage, scene transitions, and query-conditioned semantic relevance. Panel B incorporates CFR into GRPO, rewarding overlap between the consensus prior and the model-side frame-use distribution while preserving accuracy, temporal, and structural rewards.这张图概括 Reasoning as Intersection 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Motivation of consensus-frame alignmentFigure 1: Motivation of consensus-frame alignment. In long-video QA, single-source sampling or diffuse frame use can anchor the response to visually plausible but incorrect frames. VideoCFR constructs a consensus prior from temporal coverage, scene-transition, and query-relevance cues, and uses this prior as training-time evidence guidance for aligning generation with frames that support the answer.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Reasoning as Intersection 的方法或实验,请结合正文精读段落一起看。