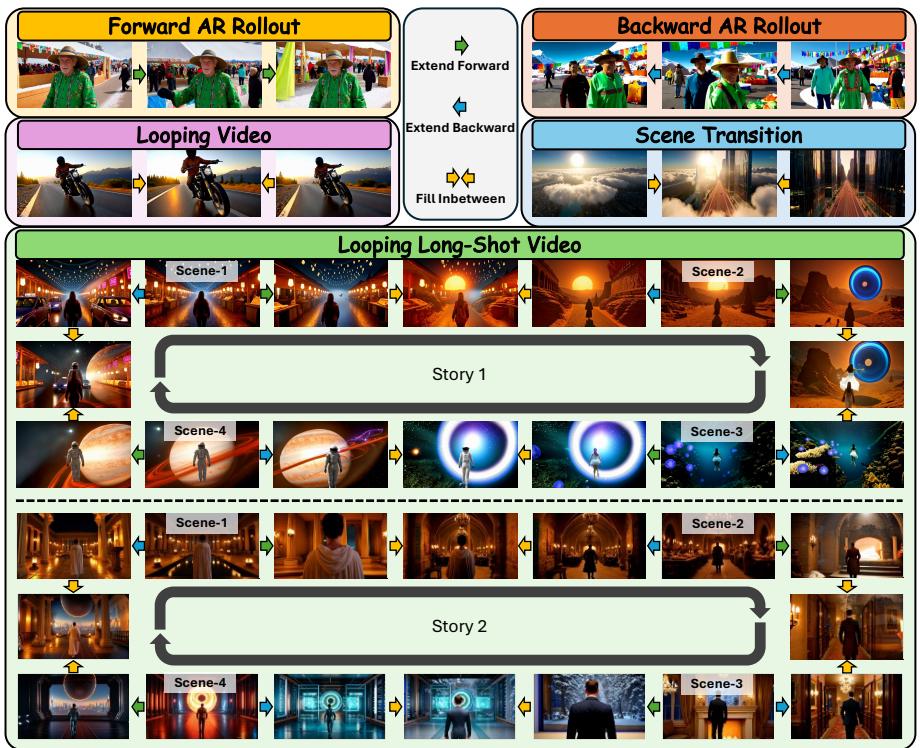
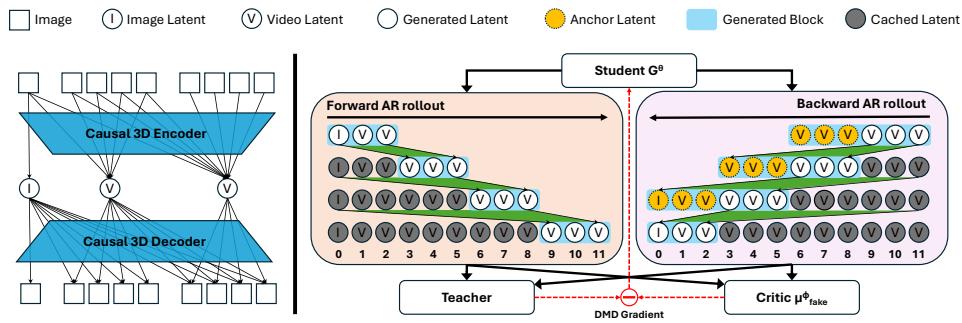
Figureure 1 · : We present UniTemp, a unified distillation framework that delivers aFig. 1: We present UniTemp, a unified distillation framework that delivers a single model capable of flexibly generating video conditioned on past context, future context, or both, and supporting a wide range of generation tasks.这张图概括 UniTemp 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 3 · : Left: Causal design of the frozen 3D VAEFig. 3: Left: Causal design of the frozen 3D VAE. It encodes video into spatialtemporal latents (V) with a leading image latent (I). Each latent is dependent on its past context. Right: Overview of UniTemp. We distill a teacher model into a unified autoregressive student $G ^ { \theta }$ trained on its self-rollout in both forward and backward directions. In backward generation, we introduce blockwise anchor latents (dashed circles) to reduce inter-block flickering. The anchor latents only serve to stabilize generated content by providing approximate missing past context. After being denoised with the current block, they are discarded and not included as outputs.这张图概括 UniTemp 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。