通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-06-19 图像表征 · VFM · JEPA · 视频预训练
arXiv 新增 + LVLM fine-grained diagnosis · P2 · 2026-06-19

Benchmarking Large Vision-Language Models on:它和通用视觉自监督的关系在于:用 feature-level visual discriminability 诊断 LVLM 细粒度图像失败,适合做表征评测读物

中高相关;详见方法、贡献和实验边界。

编号2606.19053 优先级P2 类别arXiv 新增 + LVLM fine-grained diagnosis 会议arXiv 新增 + LVLM fine-grained diagnosis 方法用 feature-level visual discriminability 诊断 LVLM 细粒度图像失败,适合做表征评测读物 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:用 feature-level visual discriminability 诊断 LVLM 细粒度图像失败,适合做表征评测读物。 中高相关;详见方法、贡献和实验边界。

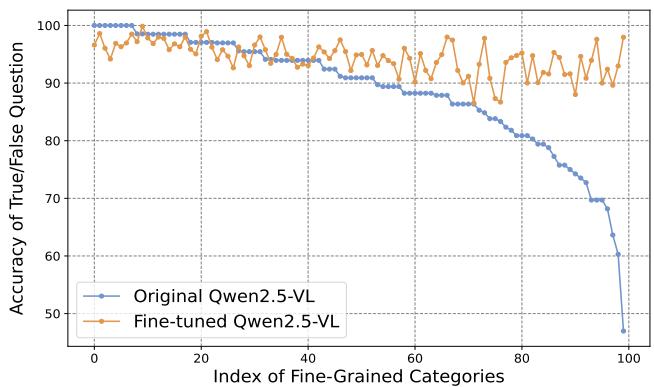
Figureure 20 · Comparison of the original and fine-tuned Qwen2.5- VL [39] models on o
Figureure 20 · Comparison of the original and fine-tuned Qwen2.5- VL [39] models on oFig. 20. Comparison of the original and fine-tuned Qwen2.5- VL [39] models on occurrence-balanced fine-grained aircraft categories. True/false question accuracy for each category is ranked, with blue dots representing the original model and yellow dots the fine-tuned model.这张图/表用于判断 Benchmarking Large Vision-Language Models on 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
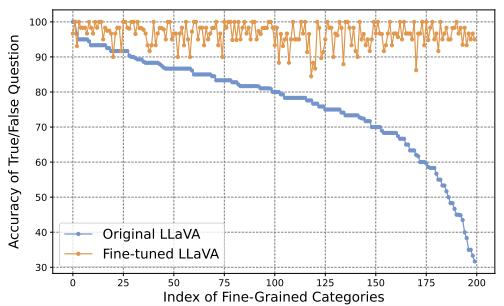
Figureure 7 · Comparison of the original (blue dots) and fine-tuned (yellow dots) LL
Figureure 7 · Comparison of the original (blue dots) and fine-tuned (yellow dots) LLFig. 7. Comparison of the original (blue dots) and fine-tuned (yellow dots) LLaVA models on occurrence-balanced finegrained bird categories. True/false accuracy per category is ranked.这张图/表用于判断 Benchmarking Large Vision-Language Models on 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。

核心问题

它和通用视觉自监督的关系在于:用 feature-level visual discriminability 诊断 LVLM 细粒度图像失败,适合做表征评测读物。

方法拆解

用 feature-level visual discriminability 诊断 LVLM 细粒度图像失败,适合做表征评测读物

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。