先说结论。它和通用视觉自监督的关系在于:把教师 ViT 的中间层当成自适应课程,缓解小模型直接模仿高层 DINOv2/VFM 特征的容量落差。 高相关;详见方法、贡献和实验边界。
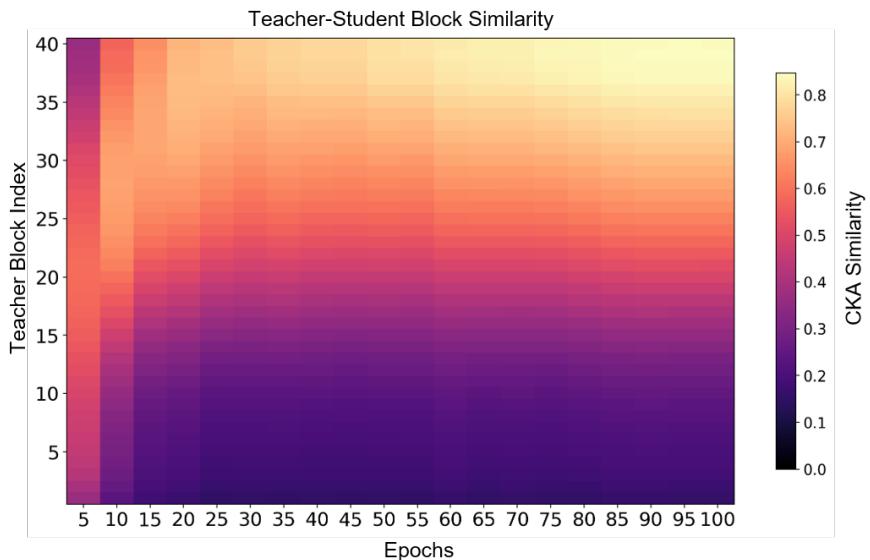
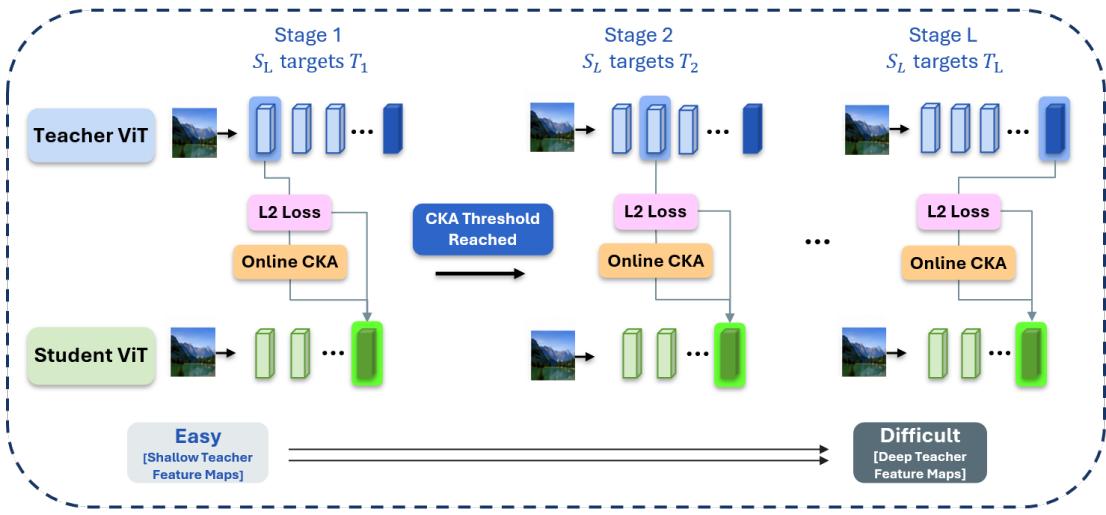
Figureure 2 · : CKA heatmap between the student model’s last feature map and all of Figure 2: CKA heatmap between the student model’s last feature map and all of the teacher’s intermediate feature maps during training. Student checkpoints are saved every 5 epochs, and the CKA score is calculated across a subset of validation dataset.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 LEAP 的方法或实验,请结合正文精读段落一起看。Figureure 1 · : Overview of LEAPFigure 1: Overview of LEAP. Rather than supervising the student against a fixed teacher block from the start, our curriculum advances the supervisory target through the teacher’s feature maps shallow-to-deep based on online CKA alignment, building student representations progressively.这张图概括 LEAP 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:把教师 ViT 的中间层当成自适应课程,缓解小模型直接模仿高层 DINOv2/VFM 特征的容量落差。
方法拆解
把教师 ViT 的中间层当成自适应课程,缓解小模型直接模仿高层 DINOv2/VFM 特征的容量落差