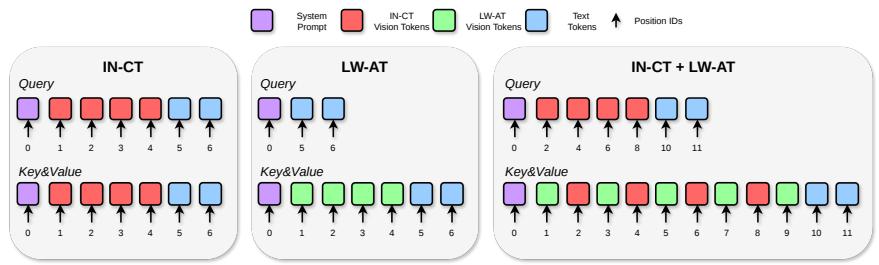
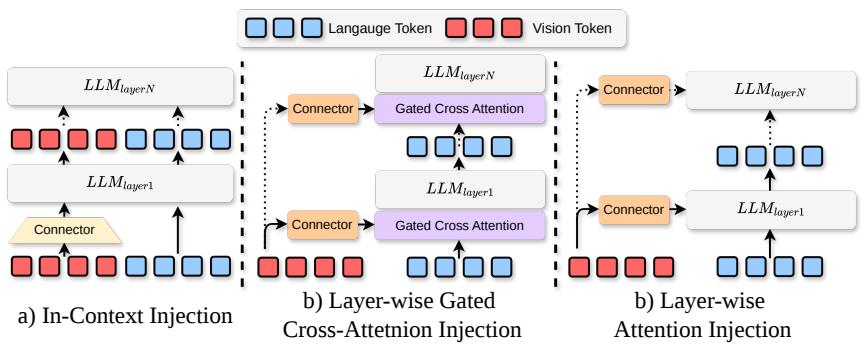
Figureure 9 · : Architecture overview of the hybrid IN-CT + LW-AT model compared to Fig. 9: Architecture overview of the hybrid IN-CT + LW-AT model compared to standalone IN-CT and LW-AT. IN-CT vision tokens are concatenated at the input, while LW-AT vision tokens are injected into the keys and values at every layer. Fig. 10: Token sequence and position ID assignment for IN-CT, LW-AT, and the hybrid IN-CT + LW-AT model. Each paradigm preserves its original position ID scheme independently within the hybrid architecture.这张图概括 The Hidden Evolution of Disguised 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Overview of the three VLM integration paradigms evaluated in this stFig. 1: Overview of the three VLM integration paradigms evaluated in this study. (a) IN-CT concatenates visual tokens with text tokens at the input layer, (b) LW-GC introduces visual features through gated cross-attention blocks, and (c) LW-AT injects visual features directly into the LLM's keys and values.这张图概括 The Hidden Evolution of Disguised 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。