LEViL:它和通用视觉自监督的关系在于:用 VLM 生成语义 pseudo-label space 训练视频 encoder,是低标注视频预训练的可迁移思路
中高相关;详见方法、贡献和实验边界。
LEViL: Label-Efficient Video Learning via Zero-Shot Distillation over VLM-Generated Pseudo-Label Spaces arXiv 新增 · video distillation / pseudo labels 原文链接
编号2606.21358优先级P2类别arXiv 新增 · video distillation / pseudo labels会议arXiv 新增 · video distillation / pseudo labels方法用 VLM 生成语义 pseudo-label space 训练视频 encoder,是低标注视频预训练的可迁移思路来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:用 VLM 生成语义 pseudo-label space 训练视频 encoder,是低标注视频预训练的可迁移思路。 中高相关;详见方法、贡献和实验边界。
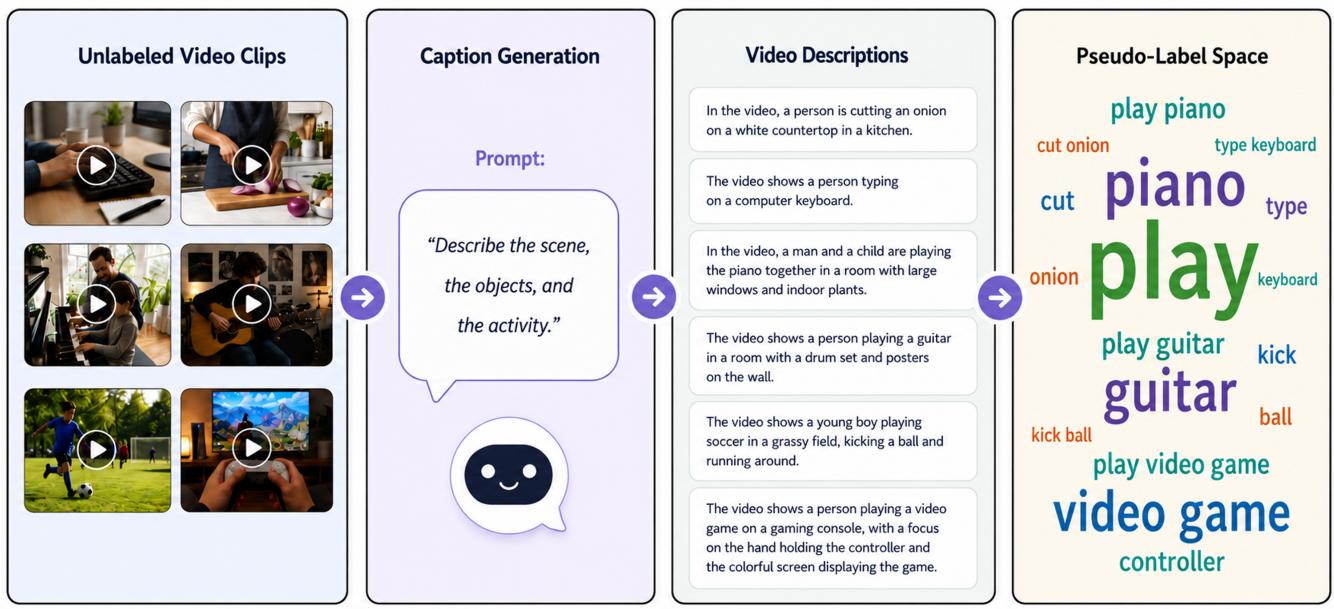
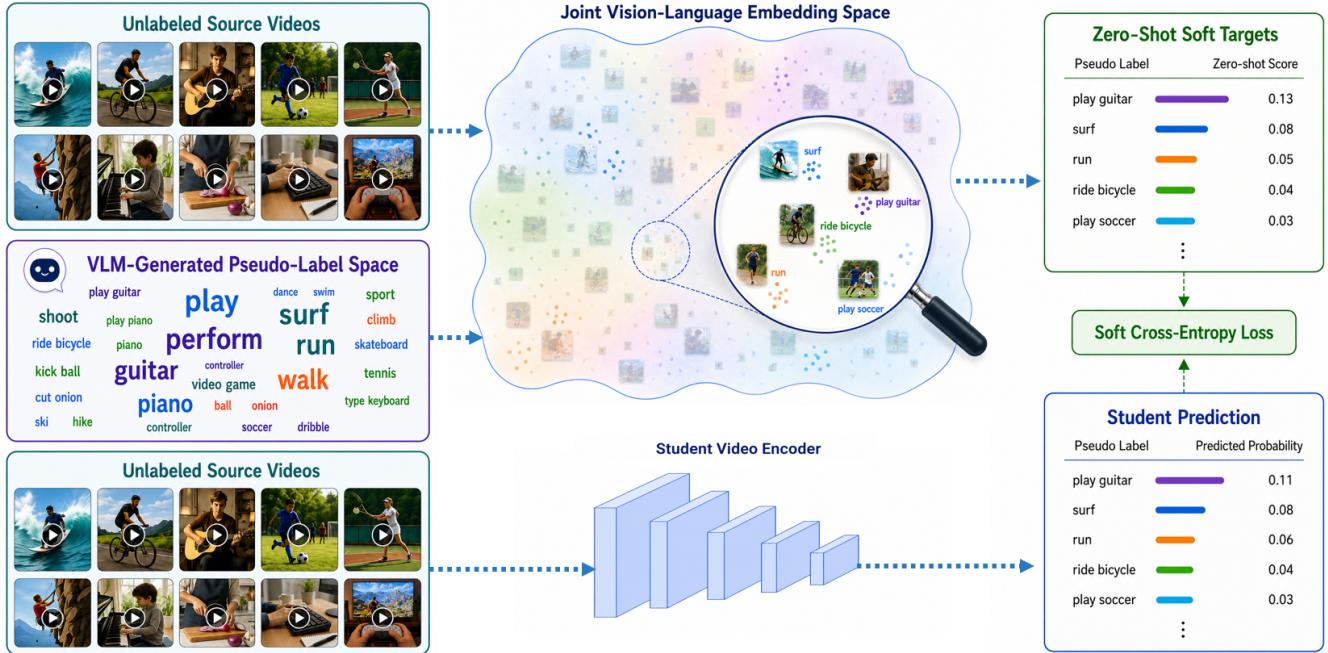
Figureure 2 · Overview of the pseudo-label space construction pipelineFig. 2. Overview of the pseudo-label space construction pipeline. A vision-language model first generates open-vocabulary descriptions of unlabeled video clips. The captions are then processed and filtered to construct a pseudo-label vocabulary comprising actions, objects, and action–object interactions for annotation-free video pretraining.这张图概括 LEViL 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 3 · Overview of zero-shot distillation over the caption-derived pseudo-labFig. 3. Overview of zero-shot distillation over the caption-derived pseudo-label space. A frozen video-language model compares each unlabeled video with the pseudo-labels in a joint video–text embedding space to generate soft semantic target distributions. A student video encoder is then pretrained to reproduce these distributions, enabling annotation-free representation learning.这张图概括 LEViL 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:用 VLM 生成语义 pseudo-label space 训练视频 encoder,是低标注视频预训练的可迁移思路。
方法拆解
用 VLM 生成语义 pseudo-label space 训练视频 encoder,是低标注视频预训练的可迁移思路