Structured Hyperedge Adaptation for Parameter-Efficient:它和通用视觉自监督的关系在于:不是自监督训练目标,但关注 ViT token 关系和高效适配,对 VFM 下游迁移有参考价值
中相关;详见方法、贡献和实验边界。
Structured Hyperedge Adaptation for Parameter-Efficient Fine-Tuning of Vision Transformers arXiv 新增 · ViT adaptation / token structure 原文链接
编号2606.22383优先级P3类别arXiv 新增 · ViT adaptation / token structure会议arXiv 新增 · ViT adaptation / token structure方法不是自监督训练目标,但关注 ViT token 关系和高效适配,对 VFM 下游迁移有参考价值来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:不是自监督训练目标,但关注 ViT token 关系和高效适配,对 VFM 下游迁移有参考价值。 中相关;详见方法、贡献和实验边界。
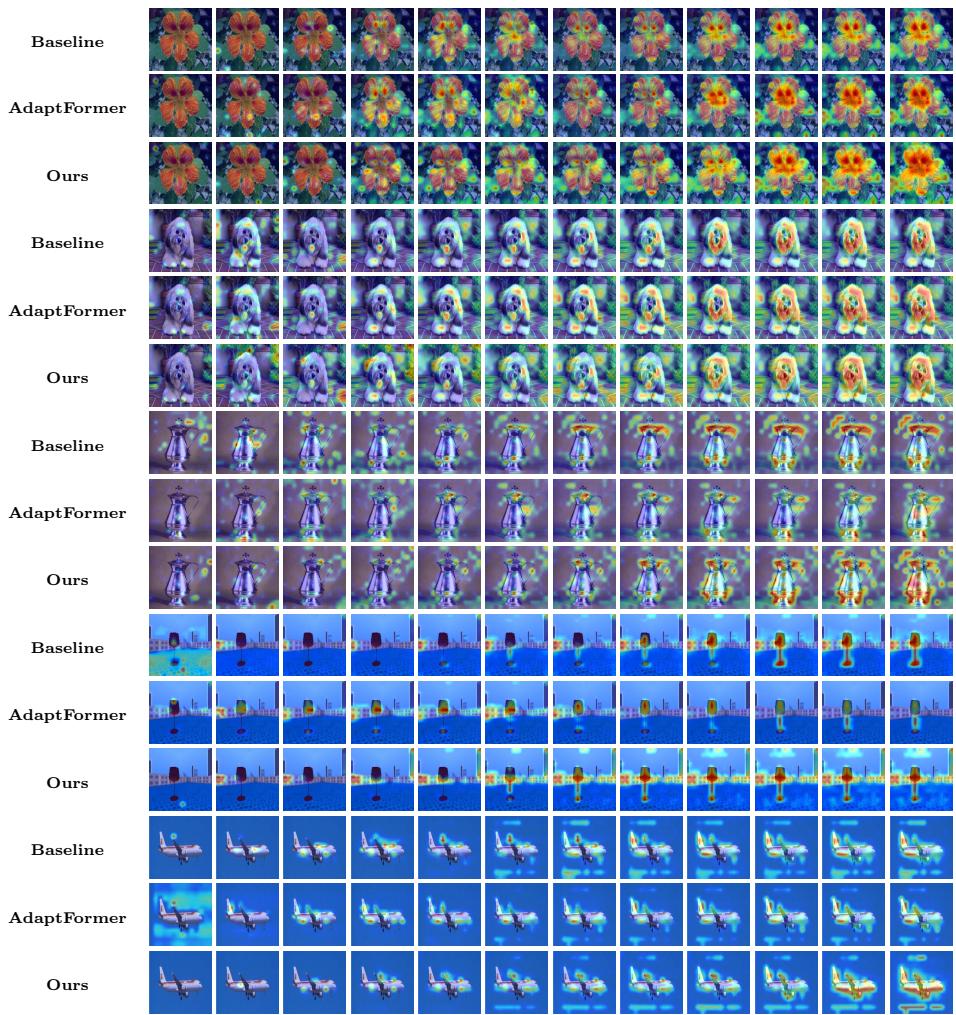
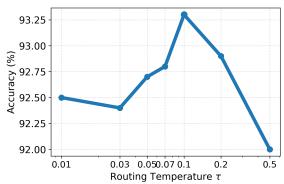
Block 1 Block 2 Block 3 Block 4 Block 5 Block 6 Block 7 Block 8 Block 9 Block 10Block 11BlBlock 1 Block 2 Block 3 Block 4 Block 5 Block 6 Block 7 Block 8 Block 9 Block 10Block 11Block 12 Fig. 10: DAAM [27] visualizations comparing HyperAdapter model with baseline and AdaptFormer models on VTAB-1K across all 12 transformer blocks.这张可视化用来解释 Structured Hyperedge Adaptation for Parameter-Efficient 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。(b) Fig(b) Fig. 3: (a) Efect of the number of hyperedges K on ${ \mathrm { V T A B } } { \cdot } 1 \mathbf { k } .$ , showing that a moderate $K = 8$ balances model capacity and eficiency. (b) Sensitivity to routing temperature τ on Caltech101, where performance peaks at $\tau = 0 . 1 0$ indicating optimal hyperedge assignment at moderate routing sharpness.这张图/表用于判断 Structured Hyperedge Adaptation for Parameter-Efficient 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:不是自监督训练目标,但关注 ViT token 关系和高效适配,对 VFM 下游迁移有参考价值。